Choosing Microsoft DP-750 study material means you choose an effective, smart, and fast way to succeed in your DP-750 exam certification. You will find explanations along with the answers where is necessary in the DP-750 actual test files. With the study by the DP-750 vce torrent, you will have a clear understanding of the DP-750 Valid Dumps. In addition, you can print the DP-750 pdf dumps into papers, thus you can do marks on the papers. Every time, when you review the papers, you will enhance your memory about the marked points. Be confident to attend your DP-750 exam test, you will pass successfully.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data ingestion
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Topic 4: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
>> DP-750 Updated Testkings <<
With the development of the times, the pace of the society is getting faster and faster. If we don't try to improve our value, we're likely to be eliminated by society. Under the circumstances, we must find ways to prove our abilities. For example, getting the DP-750 Certification is a good way. If we had it, the chances of getting a good job would be greatly improved. And our DP-750 exam braindumps are the tool to help you get the DP-750 certification.
NEW QUESTION # 73
Which component enforces table-level permissions in Databricks?
Answer: B
Explanation:
Unity Catalog provides fine-grained access control at table, schema, and column levels. It centralizes governance across workspaces. Cluster policies control compute settings. Spark configuration does not manage security. DBFS permissions are not sufficient for enterprise governance.
NEW QUESTION # 74
You have an Azure Databricks account that contains workspaces enabled for Unity Catalog.
You need to implement audit logging to meet the following requirements:
* Capture audit logs for all the workspaces in the account.
* Retain the audit logs for 90 days.
* Minimize storage and ingestion costs.
The logs will be reviewed only during security investigations and will NOT be queried regularly.
To where should you send the audit logs?
Answer: B
Explanation:
An Azure Storage account provides durable, comparatively low-cost retention for diagnostic and audit logs that are accessed infrequently. A lifecycle or retention policy can preserve the logs for 90 days and then remove them automatically. This matches an investigation-only access pattern without paying the ingestion and indexing charges associated with Log Analytics. Azure Monitor metrics stores numerical monitoring measurements, not the complete audit-event records required here. Azure Event Hubs is a streaming transport intended to forward events to consumers and is not the final long-term retention destination. Log Analytics is appropriate when teams need frequent querying, dashboards, and alerting, but those capabilities introduce unnecessary cost for logs reviewed only during occasional investigations. Storage therefore best satisfies centralized retention and cost requirements.
NEW QUESTION # 75
You have an Azure Databricks workspace that uses Databricks SQL.
You have a table named sales_goals_source that contains the following columns:
* Salesperson
* Item
* 2019
* 2020
* 2021
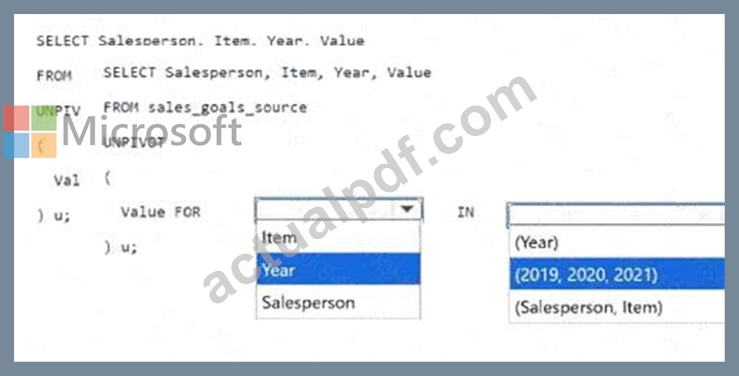
You need to transform the year columns into rows and return the columns Salesperson, Item, Year, and Value.
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
SELECT Salesperson, Item, Year, Value
FROM sales_goals_source
UNPIVOT
(
Value FOR [first dropdown] IN [second dropdown]
);
Answer:
Explanation: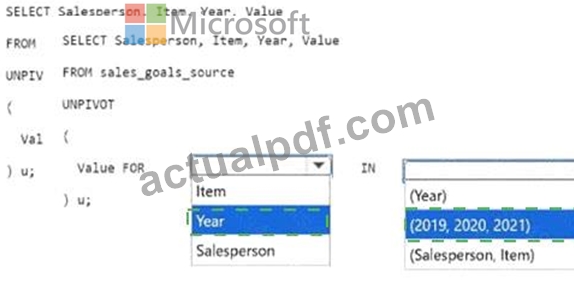
Explanation:
First dropdown: Year
Second dropdown: (2019, 2020, 2021)
The UNPIVOT operator converts the separate 2019, 2020, and 2021 columns into rows. Value becomes the output column containing the values previously stored in those year columns. Year becomes the output name column that identifies the original column from which each value came. Therefore, the expression must use Value FOR Year IN (2019, 2020, 2021). The Salesperson and Item columns are not included in the IN list because they remain identifier columns and are repeated for every resulting year row. A single source row consequently produces three output rows-one for each listed year. Selecting (Year) would reference an output name rather than the source columns that must be rotated.
NEW QUESTION # 76
A data engineer notices slow query performance on a large Delta table in Azure Databricks. The table has frequent updates and deletes. Which action best improves query performance?
Answer: A
Explanation:
OPTIMIZE compacts small files into larger ones, reducing file scan overhead. ZORDER improves data skipping by co-locating related column values. This combination significantly improves query performance on frequently filtered columns. Increasing cluster size does not address file fragmentation. Converting to Parquet removes Delta benefits like ACID transactions.
NEW QUESTION # 77
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: A
Explanation:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
NEW QUESTION # 78
......
All the Microsoft DP-750 questions given in the product are based on actual examination topics. ActualPDF provides three months of free updates if you purchase the DP-750 questions and the content of the examination changes after that. ActualPDF DP-750 PDF Questions: The Implementing Data Engineering Solutions Using Azure Databricks (DP-750) PDF dumps are suitable for smartphones, tablets, and laptops as well. So you can study actual Microsoft DP-750 questions in PDF easily anywhere. ActualPDF updates Implementing Data Engineering Solutions Using Azure Databricks (DP-750) PDF dumps timely as per adjustments in the content of the actual DP-750 exam.
Test DP-750 Cram: https://www.actualpdf.com/DP-750_exam-dumps.html