P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by RealVCE: https://drive.google.com/open?id=1hVWqzI9SFpvY8HjtZnODNUZEiQm_wlBg
Now there are many IT professionals in the world and the competition of IT industry is very fierce. So many IT professionals will choose to participate in the IT certification exam to improve their position in the IT industry. Data-Engineer-Associate Exam is a very important Amazon's certification exam. But if you want to get a Amazon certification, you must pass the exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Security and Governance | 18% | - Apply governance and compliance best practices - Implement data security controls |
| Topic 2: Data Ingestion and Transformation | 34% | - Build and manage data pipelines - Ingest and transform data using AWS services |
| Topic 3: Data Store Management | 26% | - Select appropriate data storage solutions - Optimize storage performance and cost |
| Topic 4: Data Operations and Support | 22% | - Troubleshoot data workflow issues - Monitor and maintain data pipelines |
>> Valid Test Data-Engineer-Associate Experience <<
What are you in trouble?Are you worrying about Amazon Data-Engineer-Associate certification test? It is really difficult to pass Data-Engineer-Associate exam. But, you don't have to be overly concerned. As long as you choose appropriate methods, 100% pass exam is not impossible. What are the appropriate methods? Choosing RealVCE Amazon Data-Engineer-Associate Practice Test is the best way. Test questions and test answers provided by RealVCE and the candidates that have taken Amazon Data-Engineer-Associate exam have been very well received. We assure that the exam dumps will help you to pass Data-Engineer-Associate test at the first attempt.
NEW QUESTION # 12
A company has an Amazon S3-based data lake. The data lake contains datasets that belong to multiple departments. The data lake ingests millions of customer records each day.
A data engineer needs to design an access and storage solution that allows departments to access only the subset of the company's dataset that each department requires. The solution must follow the principle of least privilege.
Which solution will meet these requirements with the LEAST operational effort?
Answer: A
Explanation:
AWS Lake Formation is specifically designed to simplify fine-grained access control for data lakes stored in Amazon S3. By using Lake Formation tag-based access control (LF-TBAC), administrators can define access policies once and apply them dynamically based on tags rather than managing individual IAM policies.
LF-Tags can be assigned to databases, tables, and columns in the AWS Glue Data Catalog. Departments are granted permissions based on tags, ensuring that each department can access only the data it is authorized to view. This approach scales efficiently as datasets and departments grow, which is critical for data lakes ingesting millions of records daily.
Managing IAM policies per department is operationally complex and error-prone. Redshift-based access centralization limits flexibility and introduces unnecessary infrastructure. Syncing data into an RDS database adds cost, latency, and maintenance overhead.
Lake Formation provides centralized governance, auditing, and least-privilege enforcement with minimal administrative effort, making it the optimal solution.
NEW QUESTION # 13
A company needs to set up a data catalog and metadata management for data sources that run in the AWS Cloud. The company will use the data catalog to maintain the metadata of all the objects that are in a set of data stores. The data stores include structured sources such as Amazon RDS and Amazon Redshift. The data stores also include semistructured sources such as JSON files and .xml files that are stored in Amazon S3.
The company needs a solution that will update the data catalog on a regular basis. The solution also must detect changes to the source metadata.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: A
Explanation:
This solution will meet the requirements with the least operational overhead because it uses the AWS Glue Data Catalog as the central metadata repository for data sources that run in the AWS Cloud. The AWS Glue Data Catalog is a fully managed service that provides a unified view of your data assets across AWS and on- premises data sources. It stores the metadata of your data in tables, partitions, and columns, and enables you to access and query your data using various AWS services, such as Amazon Athena, Amazon EMR, and Amazon Redshift Spectrum. You can use AWS Glue crawlers to connect to multiple data stores, such as Amazon RDS, Amazon Redshift, and Amazon S3, and to update the Data Catalog with metadata changes.
AWS Glue crawlers can automatically discover the schema and partition structure of your data, and create or update the corresponding tables in the Data Catalog. You can schedule the crawlers to run periodically to update the metadata catalog, and configure them to detect changes to the source metadata, such as new columns, tables, or partitions12.
The other options are not optimal for the following reasons:
* A. Use Amazon Aurora as the data catalog. Create AWS Lambda functions that will connect to the data catalog. Configure the Lambda functions to gather the metadata information from multiple sources and to update the Aurora data catalog. Schedule the Lambda functions to run periodically. This option is not recommended, as it would require more operational overhead to create and manage an Amazon Aurora database as the data catalog, and to write and maintain AWS Lambda functions to gather and update the metadata information from multiple sources. Moreover, this option would not leverage the benefits of the AWS Glue Data Catalog, such as data cataloging, data transformation, and data governance.
* C. Use Amazon DynamoDB as the data catalog. Create AWS Lambda functions that will connect to the data catalog. Configure the Lambda functions to gather the metadata information from multiple sources and to update the DynamoDB data catalog. Schedule the Lambda functions to run periodically. This option is also not recommended, as it would require more operational overhead to create and manage anAmazon DynamoDB table as the data catalog, and to write and maintain AWS Lambda functions to gather and update the metadata information from multiple sources. Moreover, this option would not leverage the benefits of the AWS Glue Data Catalog, such as data cataloging, data transformation, and data governance.
* D. Use the AWS Glue Data Catalog as the central metadata repository. Extract the schema for Amazon RDS and Amazon Redshift sources, and build the Data Catalog. Use AWS Glue crawlers for data that is in Amazon S3 to infer the schema and to automatically update the Data Catalog. This option is not optimal, as it would require more manual effort to extract the schema for Amazon RDS and Amazon Redshift sources, and to build the Data Catalog. This option would not take advantage of the AWS Glue crawlers' ability to automatically discover the schema and partition structure of your data from various data sources, and to create or update the corresponding tables in the Data Catalog.
:
1: AWS Glue Data Catalog
2: AWS Glue Crawlers
3: Amazon Aurora
4: AWS Lambda
5: Amazon DynamoDB
NEW QUESTION # 14
A company needs to build a data lake in AWS. The company must provide row-level data access and column- level data access to specific teams. The teams will access the data by using Amazon Athena, Amazon Redshift Spectrum, and Apache Hive from Amazon EMR.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: B
Explanation:
Option D is the best solution to meet the requirements with the least operational overhead because AWS Lake Formation is a fully managed service that simplifies the process of building, securing, and managing data lakes. AWS Lake Formation allows you to define granular data access policies at the row and column level for different users and groups. AWS Lake Formation also integrates with Amazon Athena, Amazon Redshift Spectrum, and Apache Hive on Amazon EMR, enabling these services to access the data in the data lake through AWS Lake Formation.
Option A is not a good solution because S3 access policies cannot restrict data access by rows and columns.
S3 access policies are based on the identity and permissions of the requester, the bucket and object ownership, and the object prefix and tags. S3 access policies cannot enforce fine-grained data access control at the row and column level.
Option B is not a good solution because it involves using Apache Ranger and Apache Pig, which are not fully managed services and require additional configuration and maintenance. Apache Ranger is a framework that provides centralized security administration for data stored in Hadoop clusters, such as Amazon EMR.
Apache Ranger can enforce row-level and column-level access policies for Apache Hive tables. However, Apache Ranger is not a native AWS service and requires manual installation and configuration on Amazon EMR clusters. Apache Pig is a platform that allows you to analyze large data sets using a high-level scripting language called Pig Latin. Apache Pig can access data stored in Amazon S3 and process it using Apache Hive. However, Apache Pig is not a native AWS service and requires manual installation and configuration on Amazon EMR clusters.
Option C is not a good solution because Amazon Redshift is not a suitable service for data lake storage.
Amazon Redshift is a fully managed data warehouse service that allows you to run complex analytical queries using standard SQL. Amazon Redshift can enforce row-level and column-level access policies for different users and groups. However, Amazon Redshift is not designed to store and process large volumes of unstructured or semi-structured data, which are typical characteristics of data lakes. Amazon Redshift is also more expensive and less scalable than Amazon S3 for data lake storage.
References:
* AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
* What Is AWS Lake Formation? - AWS Lake Formation
* Using AWS Lake Formation with Amazon Athena - AWS Lake Formation
* Using AWS Lake Formation with Amazon Redshift Spectrum - AWS Lake Formation
* Using AWS Lake Formation with Apache Hive on Amazon EMR - AWS Lake Formation
* Using Bucket Policies and User Policies - Amazon Simple Storage Service
* Apache Ranger
* Apache Pig
* What Is Amazon Redshift? - Amazon Redshift
NEW QUESTION # 15
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?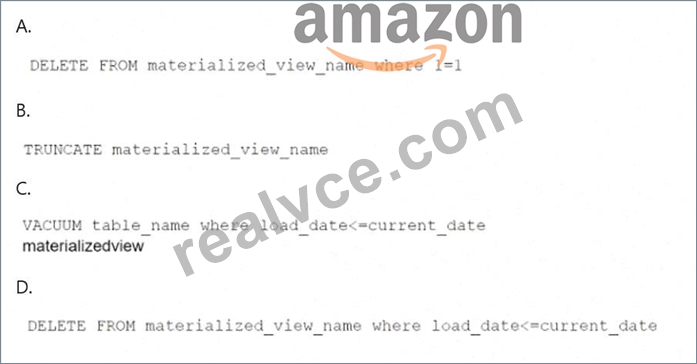
Answer: A
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
* Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
NEW QUESTION # 16
A company plans to use Amazon Kinesis Data Firehose to store data in Amazon S3. The source data consists of 2 MB csv files. The company must convert the .csv files to JSON format. The company must store the files in Apache Parquet format.
Which solution will meet these requirements with the LEAST development effort?
Answer: B
Explanation:
The company wants to use Amazon Kinesis Data Firehose to transform CSV files into JSON format and store the files in Apache Parquet format with the least development effort.
* Option B: Use Kinesis Data Firehose to convert the CSV files to JSON and to store the files in Parquet format.Kinesis Data Firehose supports data format conversion natively, including converting incoming CSV data to JSON format and storing the resulting files in Parquet format in Amazon S3.
This solution requires the least development effort because it uses built-in transformation features of Kinesis Data Firehose.
Other options (A, C, D) involve invoking AWS Lambda functions, which would introduce additional complexity and development effort compared to Kinesis Data Firehose's native format conversion capabilities.
References:
* Amazon Kinesis Data Firehose Documentation
NEW QUESTION # 17
......
Our AWS Certified Data Engineer - Associate (DEA-C01) exam questions provide with the software which has a variety of self-study and self-assessment functions to detect learning results. The statistical reporting function is provided to help students find weak points and deal with them. This function is conductive to pass the AWS Certified Data Engineer - Associate (DEA-C01) exam and improve you pass rate. Our software is equipped with many new functions, such as timed and simulated test functions. After you set up the simulation test timer with our Data-Engineer-Associate Test Guide which can adjust speed and stay alert, you can devote your mind to learn the knowledge. There is no doubt that the function can help you pass the AWS Certified Data Engineer - Associate (DEA-C01) exam.
Certification Data-Engineer-Associate Exam Cost: https://www.realvce.com/Data-Engineer-Associate_free-dumps.html
What's more, part of that RealVCE Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1hVWqzI9SFpvY8HjtZnODNUZEiQm_wlBg