Our Databricks-Certified-Professional-Data-Engineer exam questions are highly praised for their good performance. Customers often value the functionality of the product. After a long period of research and development, our Databricks-Certified-Professional-Data-Engineer learning materials have been greatly optimized. We can promise you that all of our Databricks-Certified-Professional-Data-Engineer practice materials are completely flexible. In addition, we have experts who specialize in research optimization, constantly update and improve our learning materials, and then send them to our customers. We take client's advice on Databricks-Certified-Professional-Data-Engineer training prep seriously and develop it with the advices.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Exam Duration: | 120 minutes |
| Exam Format: | Multiple Choice |
| Real Exam Qty: | 59 |
| Certificate Validity Period: | 2 years |
| Related Certifications: | Databricks Certified Associate Data Engineer |
| Available Languages: | Japanese, Portuguese (Brazil), English, Korean |
| Exam Price: | USD 200 |
| Passing Score: | 70% |
| Recommended Training: | Databricks Data Engineer Professional Training |
| Exam Registration: | Databricks Official Certification Registration |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored or onsite test center |
| Pre Condition: | No mandatory prerequisites; 1+ year hands-on experience and related training highly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-professional |
>> Fresh Databricks-Certified-Professional-Data-Engineer Dumps <<
There are three different versions of our Databricks-Certified-Professional-Data-Engineer practice materials: the PDF, the Software and the APP online. And our Databricks-Certified-Professional-Data-Engineer learning materials can save a lot of time for its high efficiency. You can study online version of Databricks-Certified-Professional-Data-Engineer real test on the subway or on the bus; you can review it when you are lining up for a meal; you can study it before you go sleeping. At the same time, our APP version of Databricks-Certified-Professional-Data-Engineer Study Materials support offline learning, which avoids the situation that there is no way to learn without a network. So why you are still hesitating? Just come and buy it!
Databricks Certified Professional Data Engineer certification is a valuable credential for data engineers who want to demonstrate their skills and proficiency in using Databricks for data engineering tasks. Databricks Certified Professional Data Engineer Exam certification can help data engineers to advance their careers and increase their earning potential. It can also help organizations to identify and hire skilled data engineers who can design and implement data solutions using Databricks.
NEW QUESTION # 45
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint2.0/jobs/create.
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
Answer: E
Explanation:
This is the correct answer because the JSON posted to the Databricks REST API endpoint 2.0/jobs/create defines a new job with a name, an existing cluster id, and a notebook task. However, it does not specify any schedule or trigger for the job execution. Therefore, three new jobs with the same name and configuration will be created in the workspace, but none of them will be executed until they are manually triggered or scheduled.
Verified References: [Databricks Certified Data Engineer Professional], under "Monitoring & Logging" section; [Databricks Documentation], under "Jobs API - Create" section.
NEW QUESTION # 46
The below spark command is looking to create a summary table based customerId and the number of times the customerId is present in the event_log delta table and write a one-time micro-batch to a summary table, fill in the blanks to complete the query.
1.spark._________
2. .format("delta")
3. .table("events_log")
4. .groupBy("customerId")
5. .count()
6. ._______
7. .format("delta")
8. .outputMode("complete")
9. .option("checkpointLocation", "/tmp/delta/eventsByCustomer/_checkpoints/")
10. .trigger(______)
11. .table("target_table")
Answer: C
Explanation:
Explanation
The answer is readStream, writeStream, once = True.
spark.readStream
format("delta")
table("events_log")
groupBy("customerId")
count()
writeStream
format("delta")
outputMode("complete")
option("checkpointLocation", "/tmp/delta/eventsByCustomer/_checkpoints/") trigger(once = True) table("target_table")
NEW QUESTION # 47
The research team has put together a funnel analysis query to monitor the customer traffic on the e-commerce platform, the query takes about 30 mins to run on a small SQL endpoint cluster with max scaling set to 1 cluster. What steps can be taken to improve the performance of the query?
Answer: D
Explanation:
Explanation
The answer is, They can increase the cluster size anywhere from 2X-Small to 4XL(Scale Up) to review the performance and select the size that meets your SLA. If you are trying to improve the performance of a single query at a time having additional memory, additional worker nodes mean that more tasks can run in a cluster which will improve the performance of that query.
The question is looking to test your ability to know how to scale a SQL Endpoint(SQL Warehouse) and you have to look for cue words or need to understand if the queries are running sequentially or concurrently. if the queries are running sequentially then scale up(Size of the cluster from 2X-Small to 4X-Large) if the queries are running concurrently or with more users then scale out(add more clusters).
SQL Endpoint(SQL Warehouse) Overview: (Please read all of the below points and the below diagram to understand )
1.A SQL Warehouse should have at least one cluster
2.A cluster comprises one driver node and one or many worker nodes
3.No of worker nodes in a cluster is determined by the size of the cluster (2X -Small ->1 worker, X-Small ->2 workers.... up to 4X-Large -> 128 workers) this is called Scale Up
4.A single cluster irrespective of cluster size(2X-Smal.. to ...4XLarge) can only run 10 queries at any given time if a user submits 20 queries all at once to a warehouse with 3X-Large cluster size and cluster scaling (min
1, max1) while 10 queries will start running the remaining 10 queries wait in a queue for these 10 to finish.
5.Increasing the Warehouse cluster size can improve the performance of a query, example if a query runs for 1 minute in a 2X-Small warehouse size, it may run in 30 Seconds if we change the warehouse size to X-Small.
this is due to 2X-Small has 1 worker node and X-Small has 2 worker nodes so the query has more tasks and runs faster (note: this is an ideal case example, the scalability of a query performance depends on many factors, it can not always be linear)
6.A warehouse can have more than one cluster this is called Scale Out. If a warehouse is configured with X-Small cluster size with cluster scaling(Min1, Max 2) Databricks spins up an additional cluster if it detects queries are waiting in the queue, If a warehouse is configured to run 2 clusters(Min1, Max 2), and let's say a user submits 20 queries, 10 queriers will start running and holds the remaining in the queue and databricks will automatically start the second cluster and starts redirecting the 10 queries waiting in the queue to the second cluster.
7.A single query will not span more than one cluster, once a query is submitted to a cluster it will remain in that cluster until the query execution finishes irrespective of how many clusters are available to scale.
Please review the below diagram to understand the above concepts: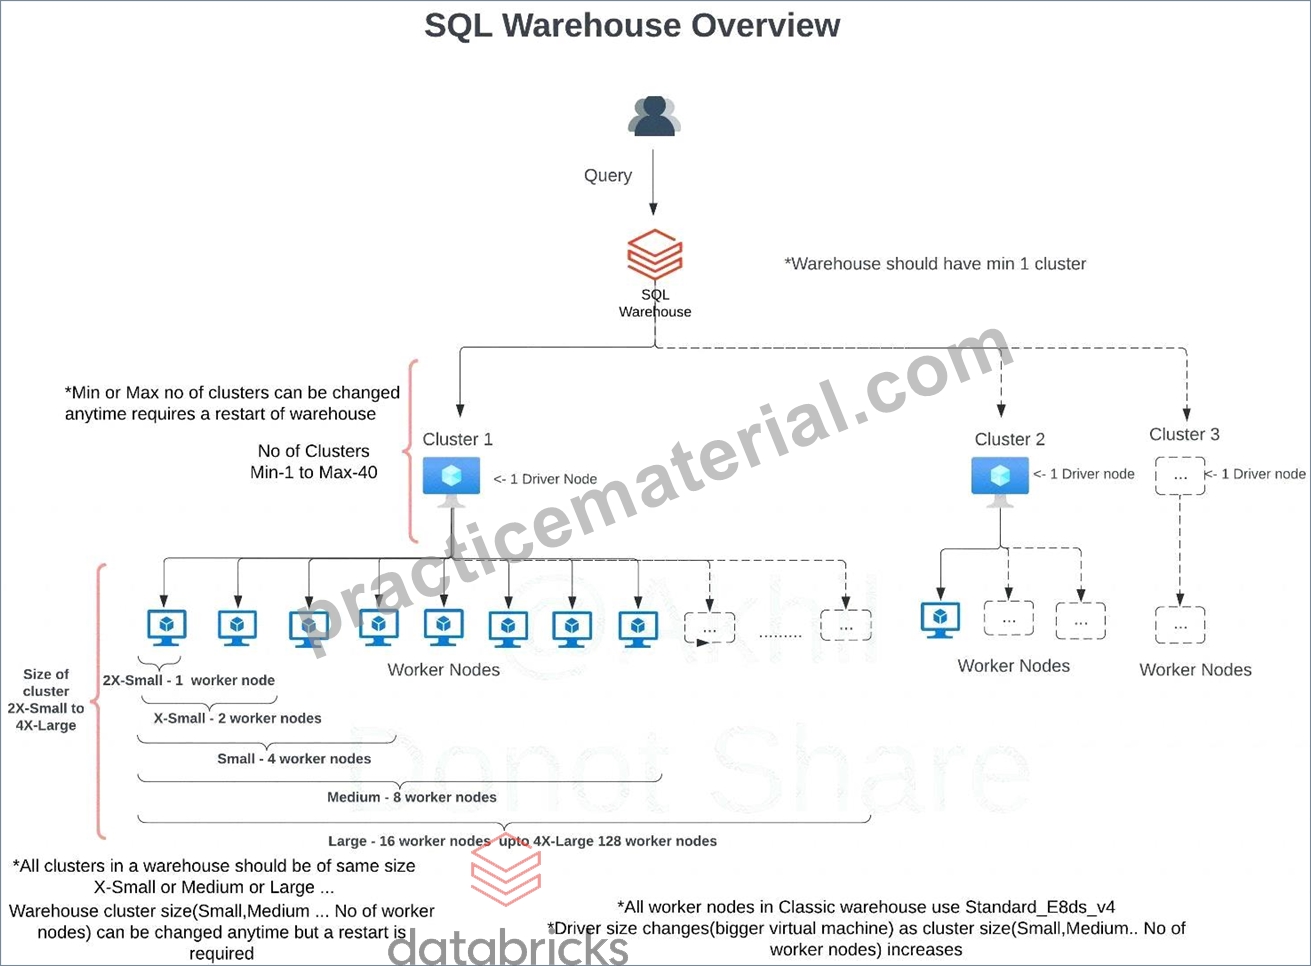
Scale-up-> Increase the size of the SQL endpoint, change cluster size from 2X-Small to up to 4X-Large If you are trying to improve the performance of a single query having additional memory, additional worker nodes and cores will result in more tasks running in the cluster will ultimately improve the performance.
During the warehouse creation or after, you have the ability to change the warehouse size (2X-Small....to
...4XLarge) to improve query performance and the maximize scaling range to add more clusters on a SQL Endpoint(SQL Warehouse) scale-out if you are changing an existing warehouse you may have to restart the warehouse to make the changes effective.
NEW QUESTION # 48
A data engineer is designing a Lakeflow Spark Declarative Pipeline to process streaming order data. The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id is not null and amount is greater than zero. Invalid records should be dropped. Which Lakeflow Spark Declarative Pipelines configuration implements this requirement using Python?
Answer: B
Explanation:
Databricks documents that expectation decorators are applied to datasets using decorators such as @dp.expect
, @dp.expect_or_drop , and related variants. The expect_or_drop behavior drops records that violate the constraint before they are written to the target dataset. That matches the requirement exactly. ( Databricks Documentation ) Option D is the only answer that uses the documented decorator pattern correctly and applies drop semantics for both constraints. Options B and C use expect , which records the violation but does not drop invalid records. Option A is not the documented API pattern for Lakeflow expectations, because expectations are declared as decorators on the table or view definition rather than chained as DataFrame methods. ( Databricks Documentation )
======
NEW QUESTION # 49
How VACCUM and OPTIMIZE commands can be used to manage the DELTA lake?
Answer: B
Explanation:
Explanation
VACCUM:
You can remove files no longer referenced by a Delta table and are older than the retention thresh-old by running the vacuum command on the table. vacuum is not triggered automatically. The de-fault retention threshold for the files is 7 days. To change this behavior, see Configure data reten-tion for time travel.
OPTIMIZE:
Using OPTIMIZE you can compact data files on Delta Lake, this can improve the speed of read queries on the table. Too many small files can significantly degrade the performance of the query.
NEW QUESTION # 50
......
Valid Real Databricks-Certified-Professional-Data-Engineer Exam: https://www.practicematerial.com/Databricks-Certified-Professional-Data-Engineer-exam-materials.html