BONUS!!! Download part of Actual4Cert SPS-C01 dumps for free: https://drive.google.com/open?id=1ePqRKxIIHwjZ-T6li69PT_o6Cjg_1ljF
The SPS-C01 exam study guide includes the latest SPS-C01 PDF test questions and practice test software which can help you to pass the SPS-C01 test smoothly. The test questions cover the practical questions in the test SPS-C01 certification and these possible questions help you explore varied types of questions which may appear in the SPS-C01 test and the approaches you should adapt to answer the questions. Every SPS-C01 exam question is covered in our SPS-C01 learning braindump. You will get the SPS-C01 certification for sure with our SPS-C01 training guide.
| Section | Weight | Objectives |
|---|---|---|
| Performance Optimization and Best Practices | 20% | - Debugging and explain plans - Minimizing data transfer - Vectorized UDFs - Warehouse sizing for Snowpark - Caching strategies - Query pushdown and optimization |
| Snowpark Concepts | 15% | - Snowpark DataFrames and query plans - Snowpark Sessions and connection management - Stored procedures and conditional logic - Transformations vs. Actions - Snowpark architecture and core concepts - Client-side vs. Server-side execution |
| Snowpark API for Python | 30% | - Establishing connections and session management - Working with Semi-structured data - DataFrame creation and manipulation - Reading and writing data - User-Defined Functions (UDFs) and Stored Procedures |
| Data Transformations and DataFrame Operations | 35% | - Using built-in functions - Complex data pipelines - Window functions - Persisting transformed data - Filtering, Aggregating, and Joining DataFrames |
Our clients come from all around the world and our company sends the products to them quickly. The clients only need to choose the version of the product, fill in the correct mails and pay for our SPS-C01 study materials. Then they will receive our mails in 5-10 minutes. Once the clients click on the links they can use our SPS-C01 Study Materials immediately. If the clients can’t receive the mails they can contact our online customer service and they will help them solve the problem. Finally the clients will receive the mails successfully. The purchase procedures are simple and the delivery of our SPS-C01 study materials is fast.
NEW QUESTION # 124
You have a Snowpark Python application that uses a UDF to perform custom data transformations. The UDF relies on a large, read-only lookup table that is stored as a CSV file on a Snowflake stage. Which of the following strategies would be the MOST efficient way to access the lookup table within the UDF?
Answer: A,C
Explanation:
Both options C and E are efficient. Option C leverages Snowflake's internal storage and query capabilities, avoiding repeated file reads. Although reading a file from stage only at once is good, it would impact the first call. Option E avoids hitting the stage every time, and only when the key is not present in cache. Options A and B suffer from performance bottlenecks due to repeated file access. In general, reading data within the Snowflake environment (C) is more performant than reading data from external sources within the UDF, especially when Snowflake's query optimizer can be used. Caching with LRU using the 'cachetoolS library is effective, as cache would contain some values from large data. get_stage_file API from session object is efficient way.
NEW QUESTION # 125
A Snowpark application needs to manage multiple sessions concurrently, each connected to a different Snowflake warehouse for resource isolation. The application receives warehouse names dynamically at runtime. How can the application efficiently create and manage these sessions while ensuring proper resource cleanup?
Answer: D
Explanation:
Option B is the most reliable and recommended way to manage multiple sessions. It ensures resource isolation by creating separate sessions per warehouse. Closing each session properly, especially using a 'finally' block or context manager, prevents resource leaks and ensures sessions are closed even if errors occur. Option A can lead to unpredictable behavior if multiple threads or asynchronous tasks interact with the global session. Options C, D and E are generally incorrect or don't properly manage resource cleanup or isolation.
NEW QUESTION # 126
Consider the following Snowpark Python code snippet intended to operationalize a stored procedure: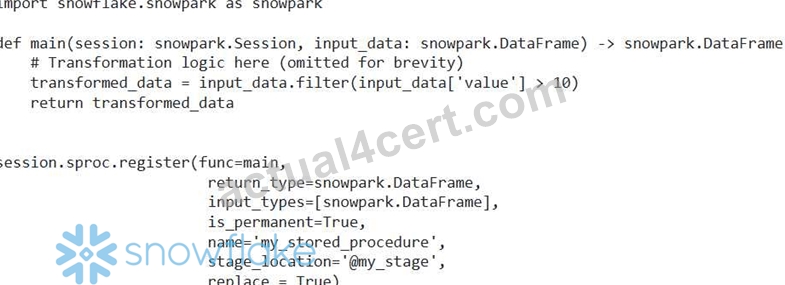
This code results in an error during registration. Which of the following actions would be MOST appropriate to fix the registration issue and ensure the stored procedure can be successfully operationalized?
Answer: B
Explanation:
Option C is the correct solution. The 'session.sproc.registefl method should be called outside of the 'main' function definition. The registration process is a separate step from the function definition itself. The 'sproc.register' will take the function definition and create an object in Snowflake. Since this must be outside of the function it needs to be outside the main function. All other options would not solve the error with the registration.
NEW QUESTION # 127
A Snowpark application needs to process large volumes of sensor data stored in a Snowflake table named , which includes columns , 'timestamp' , and The application must calculate a rolling average of for each over a 5-minute window. The data is not perfectly ordered by 'timestamp' within each 'sensor_id'. What is the MOST efficient and accurate way to implement this rolling average calculation using Snowpark?
Answer: D
Explanation:
Option D is the most efficient and accurate. 'partitionBy('sensor_id')' ensures that the rolling average is calculated separately for each sensor. 'orderBy('timestamp'Y orders the data within each partition by timestamp. 0)' defines the 5- minute window relative to the current row, accurately capturing all readings within that window even if they are slightly out of order. 'avg(Y then efficiently calculates the average within that window. Other options are either less efficient (e.g., UDTF iteration) or less accurate (e.g., incorrect window definitions, filtering).
NEW QUESTION # 128
You've written a Snowpark stored procedure in Python that utilizes a custom Python library named 'my utils.py' containing utility functions for data transformation. This library is not available in Anaconda'. You want to deploy the stored procedure and ensure that the custom library is accessible during execution. Which is the most appropriate way to operationalize your Snowpark stored procedure with the custom library?
Answer: C
Explanation:
Option A is the most appropriate. The 'imports' argument in 'session.sproc.register' is specifically designed for including custom modules and files that are not available through Anaconda. Uploading 'my_utils.py' to a stage and referencing it in the 'imports' argument makes the library available during stored procedure execution. Packaging into a wheel is used for libraries that are available through pypi but may require a specific version. Option C is bad practice, and options D and E are impossible.
NEW QUESTION # 129
......
Before the clients purchase our SPS-C01 study materials, they can have a free trial freely. The clients can log in our company’s website and visit the pages of our products. The pages of our products lists many important information about our SPS-C01 study materials and they include the price, version and updated time of our products, the exam name and code, the total amount of the questions and answers, the merits of our SPS-C01 Study Materials and the discounts. You can have a comprehensive understanding of our SPS-C01 study materials after you see this information. Then you can look at the free demos and try to answer them to see the value of our SPS-C01 study materials and finally decide to buy them or not.
Exam Dumps SPS-C01 Collection: https://www.actual4cert.com/SPS-C01-real-questions.html
BTW, DOWNLOAD part of Actual4Cert SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1ePqRKxIIHwjZ-T6li69PT_o6Cjg_1ljF