現在Nutanix NCP-BC-7.5 認證考試是很多IT人士參加的最想參加的認證考試之一,是IT人才認證的依據之一。通過這個考試是需要豐富的知識和經驗的,而積累豐富的知識和經驗是需要時間的。也許你會選擇一些培訓課程或培訓工具,花一定的錢選擇一個高品質的培訓機構培訓是值得的。VCESoft就是一個可以滿足很多參加Nutanix NCP-BC-7.5 認證考試的IT人士的需求的網站。VCESoft的產品是對Nutanix NCP-BC-7.5 認證考試提供針對性培訓的,能讓你短時間內補充大量的IT方面的專業知識,讓你為Nutanix NCP-BC-7.5 認證考試做好充分的準備。
| Section | Objectives |
|---|---|
| Security and Hardening | - Approval policies configuration - Designing secure BCDR environments - Security best practices for replication - RBAC implementation for disaster recovery |
| Monitoring, Testing and Troubleshooting | - Troubleshooting permission issues and misconfigured DR environments - Diagnosing network, storage and replication failures - Setting up alerts for replication lag - Resolving third-party backup integration problems - Non-disruptive recovery testing - Documenting runbooks for incident response |
| Replication and Failover Architecture | - Network segmentation for BCDR environments - Synchronous replication across sites - Recovery site capacity management - Failover readiness validation - Asynchronous replication planning |
| BCDR Fundamentals and Requirements Interpretation | - Translating business requirements into resilient recovery architectures - Understanding RTO and RPO concepts and business impact analysis - Defining recovery strategies aligned to business requirements and risk tolerance - Availability metrics and SLA definitions - Selecting appropriate replication types (async, near-sync, synchronous, metro) |
| Nutanix Disaster Recovery Solutions | - Configuring and managing replication policies - Metro Availability configuration and management - Recovery workflows using Nutanix native tools - Integration with third-party backup solutions - Failover procedures and execution |
| Data Protection and Snapshots | - Snapshot scheduling and management - Storage configuration for BCDR - Incremental backup implementation - Data restoration at VM and application level - Snapshot retention policies design |
突然發現,很多人對自己未來的所有計劃都有同一個開頭——等我有了錢……但是,IT認證考試不能等。如果你覺得購買 Nutanix 的 NCP-BC-7.5 考試培訓資料利用它來準備考試是一場冒險,那麼整個生命就是一場冒險,走得最遠的人常常就是願意去做願意去冒險的人。而 VCESoft 的 NCP-BC-7.5 考資料根據最新的考試動態變化而更新,會在第一時間更新 NCP-BC-7.5 題庫。
問題 #11
A Protection Domain exists with a VM, but no new snapshots are being created and replication never starts.
Which is the most likely DR setup issue?
答案:B
解題說明:
In a Nutanix legacy Protection Domain (PD) configuration, three primary elements must be in place for data protection to occur: the entities (VMs), the remote site (destination), and the schedule. Even if a VM has been added to a Protection Domain (negating Option A), the cluster will not take any action unless it is explicitly told " when " and " how often " to do so.
If no new snapshots are being created locally and replication is not starting, the most likely issue is that no " Schedule " has been configured for that Protection Domain. The schedule defines the RPO (e.g., hourly, daily) and the retention period for the snapshots. Without an active schedule, the Cerebro service simply has no instruction to initiate the snapshot process. While a missing vStore mapping (Option C) would cause the " replication " to fail, the " local snapshots " would still be created in the PD. Similarly, low bandwidth throttling (Option D) would cause the replication to move slowly or time out, but it would not prevent the initial creation of the local recovery points. Therefore, verifying the presence of a valid, active replication schedule is the mandatory first step for an administrator when a Protection Domain appears to be " idle " despite having VMs assigned to it.
問題 #12
Refer to Exhibit: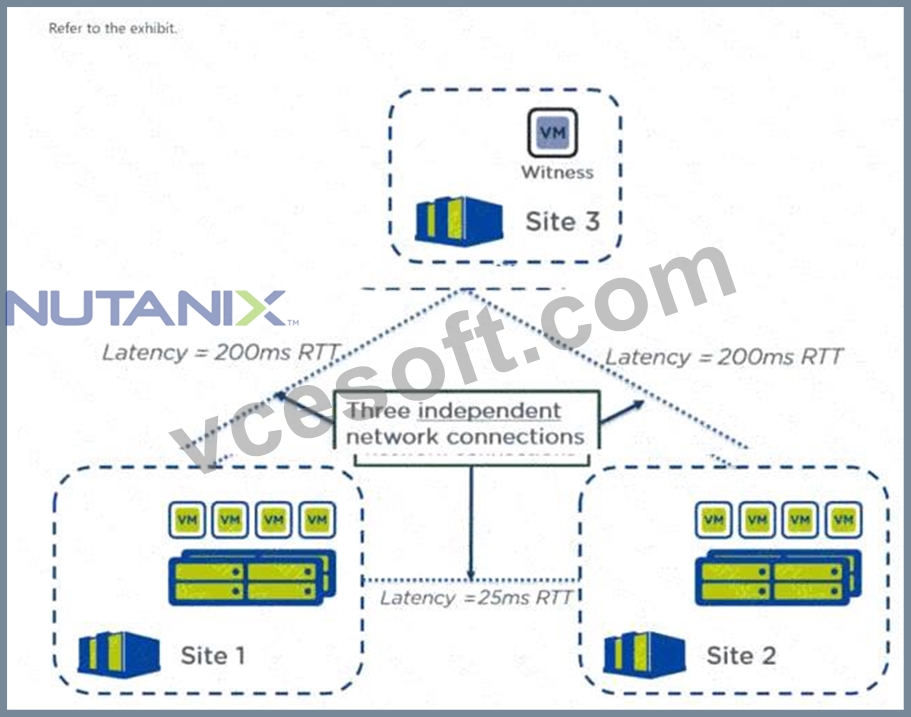
An administrator is configuring Metro Availability in their environment, as shown in the diagram. What issue in the configuration will prevent Metro from working correctly?
答案:B
解題說明:
Nutanix Metro Availability and Synchronous Replication have very strict networking requirements to ensure that real-time data mirroring does not introduce unacceptable application latency. The industry-standard requirement for Nutanix synchronous operations is a maximum Round Trip Time (RTT) latency of 5ms between the two primary clusters (Site 1 and Site 2). According to the diagram provided in the question, the latency between Site 1 and Site 2 is 25ms RTT. This latency is significantly higher than the 5ms threshold and will prevent the Metro Availability configuration from functioning correctly. While the latency to the Witness VM (200ms RTT) is perfectly acceptable (Option D), and having a Witness at a third site (Option A) is a best practice, the " data path " between the storage clusters is the bottleneck here. If an administrator attempts to enable Metro with 25ms of latency, the guest VMs would experience severe performance degradation because every write would be delayed by the 25ms it takes to receive an acknowledgment from the remote site.
Therefore, the high latency between the data-serving sites is the primary configuration issue that must be resolved, typically by moving the clusters closer together or upgrading the inter-site fiber connection.
問題 #13
Which combination of Replication Schedules within the same Recovery Plan will cause the recovery to fail?
答案:C
解題說明:
A Recovery Plan in Nutanix is the orchestration engine that defines the power-on sequence, network mappings, and script execution for disaster recovery. While a single cluster can support various types of replication-Asynchronous, NearSync, and Synchronous-there are strict architectural limits on how these can be mixed within a single automated plan.
The primary conflict arises when mixing Synchronous (0 RPO) schedules with snapshot-based Asynchronous or NearSync schedules. Synchronous replication is an " Active-Standby " or " Active-Active " storage state where the destination site already has the data in a " mounted " but inactive container. In contrast, Asynchronous and NearSync recovery involve " restoring " a VM from a specific recovery point (snapshot), which includes registering the VM and attaching the disks during the failover process. Because the orchestration logic for a Zero-RPO synchronous failover is fundamentally different from a snapshot restoration, Nutanix prevents placing them in the same Recovery Plan. Attempting to do so will cause validation errors and lead to execution failure, as the orchestrator cannot simultaneously manage real-time failover and snapshot-based restoration for the same logical group. To successfully protect an environment with both types of RPO requirements, administrators must create separate Recovery Plans: one dedicated to Synchronous workloads and another for snapshot-based Asynchronous/NearSync workloads, ensuring that each set of VMs follows its appropriate recovery workflow.
問題 #14
An organization has two Nutanix clusters managed by a single Prism Central (PC) instance. They intend to implement Synchronous Replication between the sites. During a failover test, the administrator notices that automatic failover does not occur when the primary site ' s storage becomes unavailable. What is the most likely cause of this behavior based on an analysis of the requirements?
答案:D
解題說明:
In a Nutanix Synchronous Replication or Metro Availability setup, data is mirrored in real-time, but the " intelligence " required to automate a failover resides outside of the two primary clusters. Without a Witness VM (Option C), the secondary cluster cannot distinguish between a total primary site failure and a simple network partition between the two data centers. If the clusters lose communication but there is no Witness to act as an independent tie-breaker, the secondary cluster will stay in a " Standby " state and will not automatically " promote " its storage to " Active " or power on the VMs. This is a safety mechanism to prevent " split-brain " where two clusters might try to serve the same data, leading to corruption. To enable automatic failover, a Witness VM must be deployed at a third, independent site and registered to both clusters. The Witness allows the secondary site to verify that the primary site has indeed failed; once verified, the Witness grants the " lock " to the secondary site, allowing the automated failover process to begin. Thus, the lack of a Witness is the " most likely cause " for why a failover test would fail to trigger automatically during a storage or site outage.
問題 #15
During routine monitoring, an administrator notices that replication from the primary Nutanix cluster to the recovery cluster has stopped. New recovery points are not being created, and the DR dashboard shows replication errors. Investigation reveals:
* The primary and recovery clusters are both online and healthy.
* Network segmentation was recently enabled to isolate replication traffic from other workloads.
* No recent changes were made to firewall rules, protection policies or RPO settings.
Which action should the administrator take first to investigate the replication failure?
答案:D
解題說明:
In a Nutanix environment, replication health is heavily dependent on the available bandwidth and the consistency of the network path between the source and target sites. When replication fails following an infrastructure change like network segmentation, it often indicates that the system is unable to sustain the current data change rate over the new path. While verifying ports (Option C) is a logical infrastructure step, the provided answer emphasizes managing the replication load by increasing the Recovery Point Objective (RPO) interval. Increasing the RPO (e.g., from 1 hour to 4 hours) reduces the frequency of snapshot transfers, which can help determine if the replication engine (Cerebro) can successfully complete a transfer when given a longer window or reduced pressure. If increasing the RPO resolves the failure, the administrator can conclude that the network change introduced a bottleneck or limited throughput that is insufficient for the original " heavy " schedule. This diagnostic step helps differentiate between a total connectivity blackout and a performance-related failure caused by the newly implemented network segmentation. Once the baseline replication is restored at a higher RPO, the administrator can then proceed to optimize the network or firewall settings to support the more aggressive RPO requirements originally set by the business.
問題 #16
......
現在世界上有很多 IT人才,IT行業競爭激烈。所以很多IT人才會選擇參加相關的IT認證考試來提高自己在IT行業中的地位。NCP-BC-7.5 考試就是Nutanix的一個很重要的認證考試,但是很多IT專業人員要想拿到Nutanix 認證證書,他們就必須得通過考試。
NCP-BC-7.5信息資訊: https://www.vcesoft.com/NCP-BC-7.5-pdf.html