Our company is professional brand established for compiling NCA-7.5 exam materials for candidates, and we aim to help you to pass the examination as well as getting the related NCA-7.5 certification in a more efficient and easier way. Owing to the superior quality and reasonable price of our NCA-7.5 Exam Materials, our company has become a top-notch one in the international market. Our NCA-7.5 exam torrents are not only superior in price than other makers in the international field, but also are distinctly superior in many respects.
| Section | Objectives |
|---|---|
| Topic 1: Demonstrate and Understand Platform Health and Monitoring | - Cluster health checks and resiliency status - Alerts, events, and performance monitoring - Support case creation and diagnostic tools |
| Topic 2: Describe Cluster Configuration and Maintenance | - Hardware maintenance procedures - Software updates and Life Cycle Management (LCM) - Valid cluster configuration options |
| Topic 3: Recognize Nutanix Solutions and Tools | - Use cases and features of Nutanix management and operational tools - Nutanix solutions, use cases, and features of Nutanix Cloud Infrastructure (NCI) Technologies |
| Topic 4: Describe Nutanix Platform Administration | - Basic virtual networking configuration - Virtual machine management tasks - Storage operations and licensing management |
>> Valid Nutanix NCA-7.5 Real Test <<
No matter in the day or on the night, you can consult us the relevant information about our NCA-7.5 preparation exam through the way of chatting online or sending emails. I’m sure our 24-hour online service will not disappoint you as we offer our service 24/7 on our NCA-7.5 Study Materials. And we will give you the most considerate suggestions on our NCA-7.5 learning guide with all our sincere and warm heart.
NEW QUESTION # 15
A VM is experiencing delays even though its own CPU usage appears low.
Which metric should be checked to identify scheduling issues?
Answer: D
Explanation:
CPU Ready measures the time during which a virtual CPU is prepared to execute but is waiting for the hypervisor to schedule it on a physical processor. A VM can therefore report low apparent CPU consumption while still responding slowly: its workload is not continuously executing because the assigned vCPUs are waiting for physical CPU time.
Elevated CPU Ready commonly indicates physical CPU contention, excessive vCPU allocation, an unfavorable vCPU-to-core ratio, or competition from other VMs on the host. The administrator should correlate CPU Ready with host CPU utilization, VM sizing, the number of runnable vCPUs, and workload behavior. Assigning additional vCPUs without confirming the cause can worsen scheduling delays because the hypervisor may need to coordinate more virtual processors.
Disk capacity measures available storage space and does not identify processor scheduling latency. Memory usage can reveal pressure, swapping, or insufficient guest memory, but it does not directly represent time spent waiting for CPU scheduling. Snapshot size relates to retained point-in-time storage data and is unrelated to hypervisor CPU dispatch. Nutanix identifies CPU Ready Time as the percentage of CPU wait time, making it the appropriate metric. Reference: Nutanix Intelligent Operations - VM Details and CPU Ready Time .
NHCF alignment: workload performance interpretation.
NEW QUESTION # 16
What would cause storage compression to become automatically disabled?
Answer: C
Explanation:
Nutanix AOS automatically disables compression when metadata usage becomes high. The Prism 7.5 storage documentation explicitly identifies this condition and states that an alert is generated when automatic disablement occurs. Consequently, option D is the verified answer, replacing the supplied answer A.
Compression requires AOS metadata resources to track compressed extents and the associated data layout. If metadata consumption reaches a protective threshold, continuing compression could place additional pressure on the metadata services required for normal storage operation. AOS therefore prioritizes platform stability and metadata availability by disabling compression and notifying the administrator. The corresponding health alert should be investigated to determine why metadata usage has increased and whether workload characteristics or another storage condition requires remediation.
High write activity may increase storage workload and influence when post-process compression can execute, but it is not the documented automatic-disable trigger in this question. High reads similarly do not directly cause compression to be disabled. High physical-capacity consumption generates its own capacity warnings and corrective requirements but is distinct from the metadata threshold governing compression.
NHCF/NCA reference: Storage Concepts-capacity optimization, compression and storage-container administration; NCA Section 2, "Discuss storage operations." Official references: Prism 7.5-Compression , Prism 7.5-Storage Alert Reference .
NEW QUESTION # 17
An administrator needs to decrease the number of CPUs assigned to a VM.
What is the first step?
Answer: C
Explanation:
The VM must be powered off before the administrator can reduce its CPU allocation. CPU hot-plug capabilities permit supported guest operating systems to receive additional virtual CPU resources while running, but they do not provide a supported mechanism for removing active processors from a powered-on VM. Nutanix documentation states that the number of CPUs cannot be decreased while the VM is powered on.
After shutting down the guest cleanly and confirming that the VM is off, the administrator can edit the VM configuration, reduce the required vCPU count or associated CPU topology, save the change, and restart the VM. The proposed configuration must remain valid-for example, the relationship between sockets, vCPUs, and cores must be supported.
Enabling Hot-Add addresses CPU expansion rather than reduction. Nutanix Guest Tools supplies guest integration and operational capabilities but does not override hypervisor restrictions on CPU removal. A snapshot may be useful as an optional change-control precaution, but it does not make CPU reduction possible and is not the required first step.
The technically necessary action is therefore to power off the VM. Reference: AHV - Virtual Machine Memory and CPU Hot-Plug Configurations . NHCF alignment: modifying VM compute resources and understanding hot-plug limitations.
NEW QUESTION # 18
Refer to the exhibit.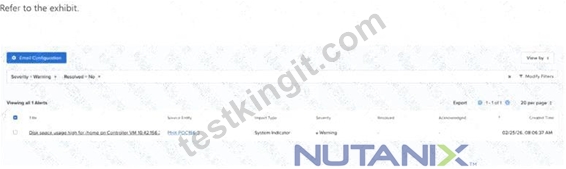
A cluster is showing the alert in the attached image.
What is the recommended method to quickly determine possible causes and corrective actions for this alert?
Answer: B
Explanation:
The alert title is the navigation control used to open the alert details page. That page consolidates the information needed to investigate the condition, including the alert description, severity, creation time, affected entity, possible causes, and recommended corrective actions. Nutanix documentation states that an administrator displays an alert's details by clicking its title.
The Source Entity link leads to information about the affected object-for example, a disk, controller VM, host, or cluster. Entity information may be useful later in the investigation, but it is not the direct route to the alert-specific cause and resolution guidance requested in the question. The selection box merely selects the record for supported bulk or administrative operations. Email Configuration controls alert-notification delivery and does not diagnose the active alert.
Copying the title into a public search engine is also inferior to using the contextual information already maintained in Prism. Search results may apply to different software releases or environmental conditions, whereas the details page is connected to the actual alert instance and entity. Therefore, clicking the alert title is the fastest supported diagnostic path. References: Prism Central - Alerts Summary View and Prism 7.5 - Alert Details . NHCF alignment: interpreting and investigating alerts.
NEW QUESTION # 19
Before physically removing a failing disk from a Nutanix node, what step must be completed in Prism Element?
Answer: A
Explanation:
The disk must first be logically removed from the cluster through Prism Element. The administrator selects the disk, clicks Remove Disk and confirms the action. AOS then migrates any recoverable data away from the device and updates the cluster's storage metadata. The disk must not be physically removed until the process completes and the disk indicator in the hardware diagram turns red.
The red indicator confirms that AOS has finished the supported logical-removal workflow and that the disk is no longer participating as an active storage device. Physically extracting a disk before this state is reached can interrupt data migration, generate additional alerts and reduce cluster resiliency.
The cluster destroy command would destroy the cluster configuration and is entirely inappropriate for component replacement. Shutting down the CVM would unnecessarily remove storage-controller services from the node and can interfere with the evacuation process. Rebooting the AHV host neither removes the disk from AOS metadata nor confirms that data migration has completed.
NHCF/NCA reference: Hardware maintenance, disk replacement and storage-resiliency procedures; NCA Section 3, "Identify hardware maintenance tasks." Official references: Prism 7.5-Removing a Disk , Prism
7.5-Hardware Table View .
NEW QUESTION # 20
......
The Nutanix Certified Associate (NCA) 7.5 Exam (NCA-7.5) exam dumps are real and updated NCA-7.5 exam questions that are verified by subject matter experts. They work closely and check all Nutanix Certified Associate (NCA) 7.5 Exam (NCA-7.5) exam dumps one by one. They maintain and ensure the top standard of Nutanix Certified Associate (NCA) 7.5 Exam (NCA-7.5) exam questions all the time.
NCA-7.5 Latest Test Labs: https://www.testkingit.com/Nutanix/latest-NCA-7.5-exam-dumps.html