Databricks的Certified-Data-Engineer-Professional考試是IT行業之中既流行也非常重要的一個考試,我們準備了最優質的學習指南和最佳的線上服務,特意為IT專業人士提供捷徑,Testpdf Databricks的Certified-Data-Engineer-Professional考題涵蓋了所有你需要知道的考試內容和答案,如果你通過我們Testpdf的考題模擬,你就知道這才是你千方百計想得到的東西,並且認為這樣才真的是為考試做準備的
| Section | Weight | Objectives |
|---|---|---|
| Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
| Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
| CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Manage dependencies, libraries, and UDFs |
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
>> Certified-Data-Engineer-Professional考試心得 <<
如果你還在為了通過 Databricks Certified-Data-Engineer-Professional 花大量的寶貴時間和精力拼命地惡補知識,同時也不知道怎麼選擇一個更有效的捷徑來通過Databricks Certified-Data-Engineer-Professional認證考試。現在Testpdf為你提供一個有效的通過Databricks Certified-Data-Engineer-Professional認證考試的方法,會讓你感覺起到事半功倍的效果。
問題 #91
A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor.
When evaluating the Ganglia Metrics for this cluster, which indicator would signal a bottleneck caused by code executing on the driver?
答案:A
解題說明:
This is the correct answer because it indicates a bottleneck caused by code executing on the driver. A bottleneck is a situation where the performance or capacity of a system is limited by a single component or resource. A bottleneck can cause slow execution, high latency, or low throughput. A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor. When evaluating the Ganglia Metrics for this cluster, one can look for indicators that show how the cluster resources are being utilized, such as CPU, memory, disk, or network. If the overall cluster CPU utilization is around 25%, it means that only one out of the four nodes (driver + 3 executors) is using its full CPU capacity, while the other three nodes are idle or underutilized. This suggests that the code executing on the driver is taking too long or consuming too much CPU resources, preventing the executors from receiving tasks or data to process. This can happen when the code has driver-side operations that are not parallelized or distributed, such as collecting large amounts of data to the driver, performing complex calculations on the driver, or using non-Spark libraries on the driver.
問題 #92
A data engineer is using Lakeflow Declarative Pipelines Expectations feature to track the data quality of their incoming sensor data. Periodically, sensors send bad readings that are out of range, and they are currently flagging those rows with a warning and writing them to the silver table along with the good data. They've been given a new requirement ?the bad rows need to be quarantined in a separate quarantine table and no longer included in the silver table.
This is the existing code for their silver table:
@dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
What code will satisfy the requirements?
答案:D
解題說明:
Lakeflow Declarative Pipelines (DLT) supports data quality enforcement using @dlt.expect,
@dlt.expect_or_drop, and @dlt.expect_all.
@dlt.expect applies a rule and records whether rows pass or fail the condition but does not drop failing rows. Instead, failing rows can be written to a quarantine table.
@dlt.expect_or_drop enforces that only rows passing the condition flow downstream, dropping bad records automatically.
In this case, the requirement is:
Good rows (reading < 120) go to the silver table.
Bad rows (reading >= 120) go to a quarantine table.
Bad rows should not be included in silver.
The correct implementation is Option A, where:
The silver table uses @dlt.expect to validate reading < 120. These rows flow normally.
The quarantine table applies an expectation for reading >= 120, ensuring bad records are captured separately.
Other options are incorrect:
Option B/D: These either use expect_or_drop incorrectly or apply wrong conditions, leading to dropped rows without quarantining properly.
Option C: Uses expect_or_drop for both tables, which would discard bad rows instead of persisting them into a quarantine table.
Thus, Option A meets the business requirement to split good and bad data streams while ensuring both are captured for auditing and processing.
問題 #93
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
答案:B
解題說明:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration.
Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
問題 #94
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.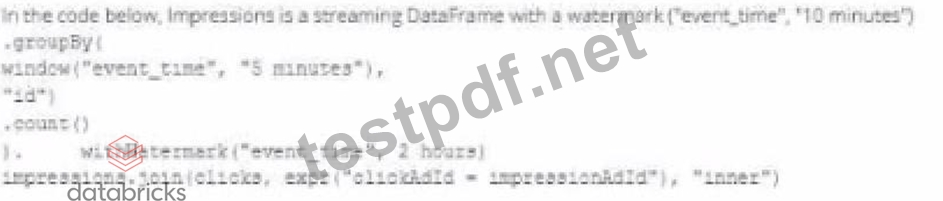
Which solution would improve the performance?




答案:C
解題說明:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
問題 #95
When monitoring a complex workload, being able to see the query plan is critical to understanding what the workload is doing. Where can the visualization of the query plan be found?
答案:D
解題說明:
The Spark UI provides detailed visibility into how queries are executed. The SQL/DataFrame tab displays the logical and physical query plans, allowing engineers to visualize execution details and understand how the workload is processed across stages and operators.
問題 #96
......
我們提供的產品是可以100%把你推上成功,那麼IT行業的巔峰離你又近了一步。如果你還沒有通過考試的信心,在這裏向你推薦一個最優秀的參考資料。在上面你可以免費下載我們提供的關於 Databricks Certified-Data-Engineer-Professional 題庫的部分考題及答案測驗我們的可靠性。只需要短時間的學習就可以通過考試的最新的 Certified-Data-Engineer-Professional 考古題出現了。選擇最新的 Certified-Data-Engineer-Professional 考題會將對你有很大幫助,你需要考前用考試模擬題隨機做練習,重複做上幾次。
Certified-Data-Engineer-Professional熱門證照: https://www.testpdf.net/Certified-Data-Engineer-Professional.html