Certified-Data-Engineer-Professional Valid Test Voucher | Certified-Data-Engineer-Professional Vce Test Simulator

Our Certified-Data-Engineer-Professional exam questions are valuable and useful and if you buy our product will provide first-rate service to you to make you satisfied. We provide not only the free download and try out of the Certified-Data-Engineer-Professional study guide but also the immediate refund if you fail in the test. To see whether our Certified-Data-Engineer-Professional Study Materials are worthy to buy you can have a look at the introduction of our product on the website and free download the demos to check the questions and answers.
| Section | Weight | Objectives |
|---|
| Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines
- Apply AUTO CDC APIs and exactly-once semantics
|
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations
- Enforce data quality and quarantine bad data
|
| Security and Governance | ~10% | - Implement row-level security, column masking, and compliance
- Manage Unity Catalog permissions and ACLs
|
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures
- Use Spark UI, Query Profiler, and system tables
|
| CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines
- Deploy with Declarative Automation Bundles, CLI, and REST API
|
| Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering
- Apply dimensional modeling techniques
|
| Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage
- Leverage system tables and observability tools
|
| Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs
- Implement scalable Python/SQL code and project structures
- Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
|
>> Certified-Data-Engineer-Professional Valid Test Voucher <<
Databricks - Certified-Data-Engineer-Professional Authoritative Valid Test Voucher
This certification gives us more opportunities. Compared with your colleagues around you, with the help of our Certified-Data-Engineer-Professional preparation questions, you will also be able to have more efficient work performance. Our Certified-Data-Engineer-Professional study materials can bring you so many benefits because they have the following features. I hope you can use a cup of coffee to learn about our Certified-Data-Engineer-Professional training engine. Perhaps this is the beginning of your change.
Databricks Certified Data Engineer Professional Sample Questions (Q10-Q15):
NEW QUESTION # 10
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
- B. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
- C. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
- D. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
- E. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
Answer: B
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types.
NEW QUESTION # 11
A data engineer is implementing a job to download multiple PDF files from a third-party provided REST API endpoint by specifying different report types. The REST API is time-consuming and encounters intermittent errors, so the engineer wants to track each download activity to know when it fails and to retry partially, while providing scalable throughput. The engineer needs to download ten report types, and the list can be changed over time. How should the data engineer achieve this?
- A. Use a Delta Lake table to track each report download status as 10 rows, and use it as a source table to execute the download function as a Pandas UDF.
- B. Define ten Notebook tasks to clearly track which report download failed.
- C. Use a foreach task with a list of report types as its inputs.
- D. Define a list variable within a Notebook to loop through the report types to download them, and print the download results. Execute it as a Notebook tasks.
Answer: C
Explanation:
A foreach task allows the job to dynamically iterate over a configurable list of report types, execute downloads in parallel, and track the success or failure of each item independently. This enables scalable throughput, partial retries for failed downloads, and easy updates when the list of report types changes, without hardcoding tasks or introducing unnecessary complexity.
NEW QUESTION # 12
A data engineer is designing an append-only pipeline that needs to handle both batch and streaming data in Delta Lake. The team wants to ensure that the streaming component can efficiently track which data has already been processed. Which configuration should be set to enable this?
- A. partitionBy
- B. checkpointLocation
- C. mergeSchema
- D. overwriteSchema
Answer: B
Explanation:
When working with Delta Lake streaming ingestion, checkpointing is critical for maintaining fault tolerance and ensuring exactly-once data processing semantics.
The checkpointLocation parameter defines the directory where Spark Structured Streaming stores progress information, offsets, and metadata. This allows the engine to resume processing from the last committed offset without reprocessing previously ingested data.
Without checkpointing, each stream restart would reprocess all data, leading to duplicates.
Parameters like partitionBy or schema options (mergeSchema / overwriteSchema) affect table structure, not data lineage tracking. Therefore, the correct and required configuration for efficient streaming state management is checkpointLocation.
NEW QUESTION # 13
A data engineer deploys a multi-task Databricks job that orchestrates three notebooks. One task intermittently fails with Exit Code 1 but succeeds on retry. The engineer needs to collect detailed logs for the failing attempts, including stdout/stderr and cluster lifecycle context, and share them with the platform team. What steps the data engineer needs to follow using built-in tools?
- A. From the job run details page, export the job's logs or configure log delivery; then retrieve the compute driver logs and event logs from the compute details page to correlate stdout/stderr with cluster events.
- B. Export the notebook run results to HTML; this bundle includes complete stdout, stderr, and cluster event history across all tasks.
- C. Download worker logs directly from the Spark UI and ignore driver logs, as worker logs contain stdout/stderr for all tasks and cluster events.
- D. Use the notebook interactive debugger to re-run the entire multi-task job, and capture step- through traces for the failing task.
Answer: A
Explanation:
The recommended way to troubleshoot and collect detailed job logs is through the Job Run Details page in Databricks. From there, engineers can export run logs or configure automatic log delivery to a storage destination. The driver and event logs available under compute details provide stdout, stderr, and cluster lifecycle context required for root-cause analysis.
NEW QUESTION # 14
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic:
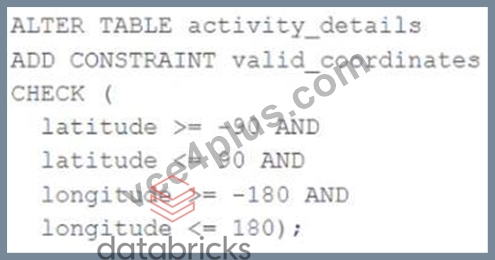
A batch job is attempting to insert new records to the table, including a record where latitude =
45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
- A. The write will insert all records except those that violate the table constraints; the violating records will be recorded to a quarantine table.
- B. The write will insert all records except those that violate the table constraints; the violating records will be reported in a warning log.
- C. The write will include all records in the target table; any violations will be indicated in the boolean column named valid_coordinates.
- D. The write will fail completely because of the constraint violation and no records will be inserted into the target table.
- E. The write will fail when the violating record is reached; any records previously processed will be recorded to the target table.
Answer: D
Explanation:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated.
NEW QUESTION # 15
......
The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) web-based practice test is compatible with these browsers: Chrome, Safari, Internet Explorer, MS Edge, Firefox, and Opera. This Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice exam does not require any software installation as it is web-based. It has similar specifications to the Databricks Certified-Data-Engineer-Professional desktop-based practice exam software, but it requires an internet connection.
Certified-Data-Engineer-Professional Vce Test Simulator: https://www.vce4plus.com/Databricks/Certified-Data-Engineer-Professional-valid-vce-dumps.html
- Free PDF 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional –Efficient Valid Test Voucher 👦 Open website ➽ www.dumpsmaterials.com 🢪 and search for ➽ Certified-Data-Engineer-Professional 🢪 for free download 👶Technical Certified-Data-Engineer-Professional Training
- Certified-Data-Engineer-Professional Braindumps Torrent 😈 Certified-Data-Engineer-Professional Test Pass4sure 🖼 Certified-Data-Engineer-Professional Braindumps Torrent 🍆 Open website ➠ www.pdfvce.com 🠰 and search for [ Certified-Data-Engineer-Professional ] for free download 🐑Certified-Data-Engineer-Professional Latest Exam Vce
- Databricks Certified-Data-Engineer-Professional Web-Based Practice Program 🪔 Search for “ Certified-Data-Engineer-Professional ” on ✔ www.exam4labs.com ️✔️ immediately to obtain a free download 🚶Certified-Data-Engineer-Professional Latest Test Pdf
- By Achieving the Databricks Certified-Data-Engineer-Professional You will Get the Job ↩ Search for ➥ Certified-Data-Engineer-Professional 🡄 and easily obtain a free download on ⇛ www.pdfvce.com ⇚ 🖕Certified-Data-Engineer-Professional Valid Test Bootcamp
- Free PDF 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional –Efficient Valid Test Voucher 💜 Open ➽ www.easy4engine.com 🢪 and search for 「 Certified-Data-Engineer-Professional 」 to download exam materials for free 🐩Certified-Data-Engineer-Professional Braindumps Torrent
- Pass Guaranteed 2026 High Hit-Rate Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Valid Test Voucher 😷 Open ✔ www.pdfvce.com ️✔️ and search for 《 Certified-Data-Engineer-Professional 》 to download exam materials for free 📔Certified-Data-Engineer-Professional Lab Questions
- Exam Certified-Data-Engineer-Professional Learning 🟥 Trustworthy Certified-Data-Engineer-Professional Dumps 🩲 Technical Certified-Data-Engineer-Professional Training 🤍 Go to website ⮆ www.prepawaypdf.com ⮄ open and search for 【 Certified-Data-Engineer-Professional 】 to download for free 📯Certified-Data-Engineer-Professional Reliable Cram Materials
- Pass Certified-Data-Engineer-Professional Exam with Marvelous Certified-Data-Engineer-Professional Valid Test Voucher by Pdfvce 🚻 Enter 【 www.pdfvce.com 】 and search for 「 Certified-Data-Engineer-Professional 」 to download for free ⏬Certified-Data-Engineer-Professional Valid Test Bootcamp
- Certified-Data-Engineer-Professional Questions - Pass On First Try [2026] 😋 The page for free download of ▶ Certified-Data-Engineer-Professional ◀ on ➡ www.torrentvce.com ️⬅️ will open immediately ⬆Certified-Data-Engineer-Professional Latest Exam Vce
- Certified-Data-Engineer-Professional Reliable Cram Materials 🥱 Exam Certified-Data-Engineer-Professional Learning 🤟 Trustworthy Certified-Data-Engineer-Professional Dumps 🍂 Search for ▶ Certified-Data-Engineer-Professional ◀ and easily obtain a free download on ➡ www.pdfvce.com ️⬅️ 😗Certified-Data-Engineer-Professional Reliable Cram Materials
- Databricks Certified-Data-Engineer-Professional Web-Based Practice Program 👖 Go to website ➠ www.testkingpass.com 🠰 open and search for ➽ Certified-Data-Engineer-Professional 🢪 to download for free 🍨Certified-Data-Engineer-Professional Reliable Cram Materials
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.longisland.com, fakescam.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes