BONUS!!! Download part of BraindumpStudy DP-100 dumps for free: https://drive.google.com/open?id=1YegriBJdRUk_moMFGVgBPwLl2RLH82pG
We try our best to provide the most efficient and intuitive learning methods to the learners and help them learn efficiently. Our DP-100 study materials provide the instances, simulation and diagrams to the clients so as to they can understand them intuitively. Based on the consideration that there are some hard-to-understand contents we insert the instances to our DP-100 Study Materials to concretely demonstrate the knowledge points and the diagrams to let the clients understand the inner relationship and structure of the knowledge points.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and prepare a machine learning solution | 20-25% | - Manage data assets
|
| Topic 2: Optimize language models for AI applications | 25-30% | - Evaluate and improve models
|
| Topic 3: Explore data and run experiments | 20-25% | - Run experiments
|
| Topic 4: Train and deploy models | 25-30% | - Train models
|
You can try the Microsoft DP-100 exam dumps demo before purchasing. If you like our Designing and Implementing a Data Science Solution on Azure (DP-100) exam questions features, you can get the full version after payment. BraindumpStudy DP-100 Dumps give surety to confidently pass the Designing and Implementing a Data Science Solution on Azure (DP-100) exam on the first attempt.
NEW QUESTION # 314
You create an Azure Machine Learning workspace. You use the Azure Machine Learning SDK for Python.
You must create a dataset from remote paths. The dataset must be reusable within the workspace.
You need to create the dataset.
How should you complete the following code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.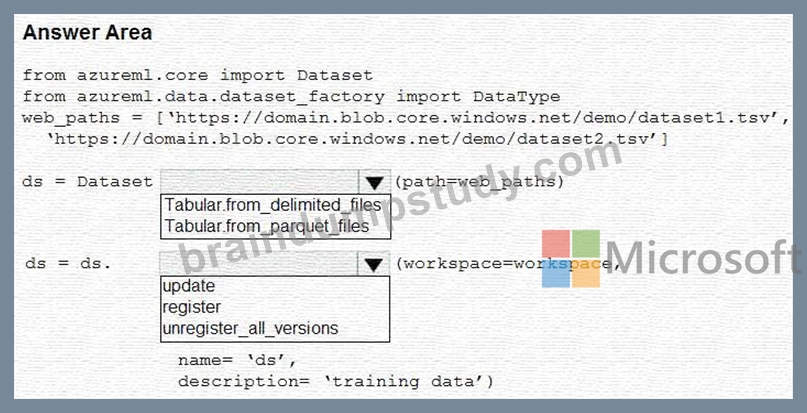
Answer:
Explanation: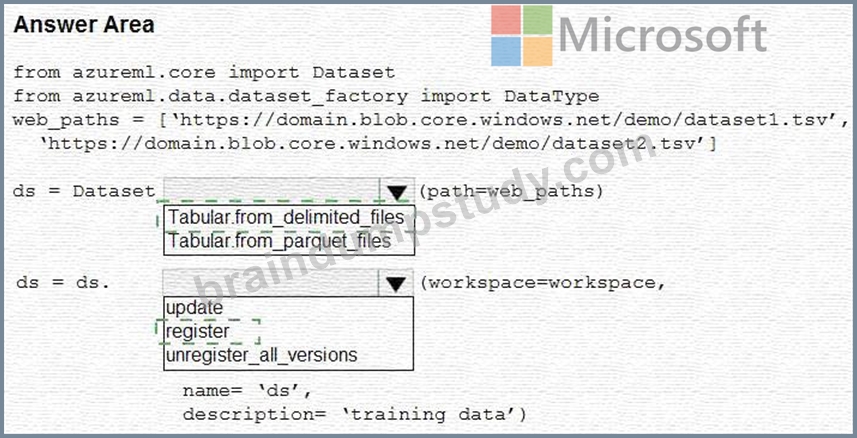
Explanation: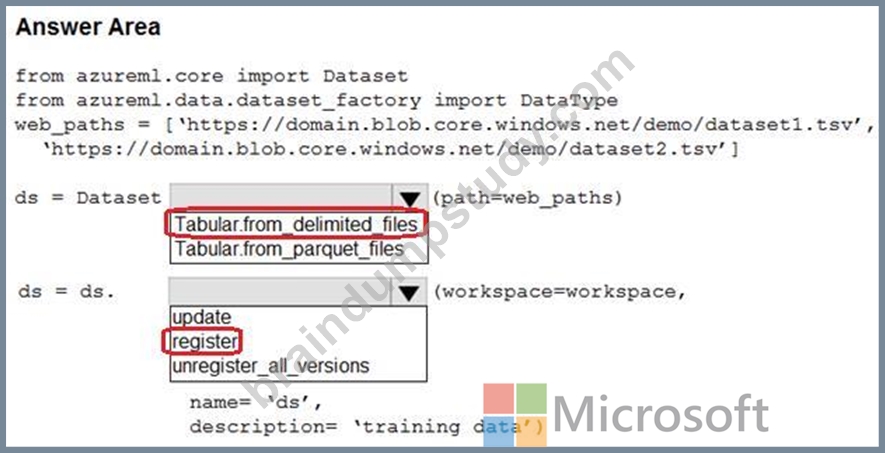
NEW QUESTION # 315
You are developing a machine learning model by using Azure Machine Learning. You are using multiple text files in tabular format for model dat a. You have the following requirements:
* You must use AutoML jobs to train the model.
* You must use data from specified columns.
* The data concept must support lazy evaluation.
You need to load data into a Pandas dataframe.
Which data concept should you use?
Answer: A
NEW QUESTION # 316
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using Azure Machine Learning to run an experiment that trains a classification model.
You want to use Hyperdrive to find parameters that optimize the AUC metric for the model. You configure a HyperDriveConfig for the experiment by running the following code: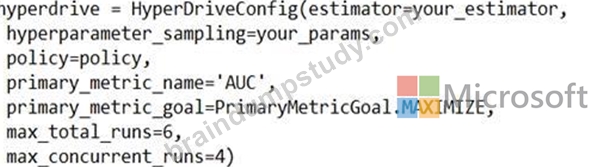
You plan to use this configuration to run a script that trains a random forest model and then tests it with validation data. The label values for the validation data are stored in a variable named y_test variable, and the predicted probabilities from the model are stored in a variable named y_predicted.
You need to add logging to the script to allow Hyperdrive to optimize hyperparameters for the AUC metric.
Solution: Run the following code: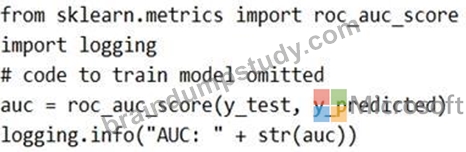
Does the solution meet the goal?
Answer: A
Explanation:
Python printing/logging example:
logging.info(message)
Destination: Driver logs, Azure Machine Learning designer
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-debug-pipelines
NEW QUESTION # 317
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create an Azure Machine Learning service datastore in a workspace. The datastore contains the following files:
* /data/2018/Q1 .csv
* /data/2018/Q2.csv
* /data/2018/Q3.csv
* /data/2018/Q4.csv
* /data/2019/Q1.csv
All files store data in the following format:
id,f1,f2,l
1,1,2,0
2,1,1,1
3.2.1.0
You run the following code: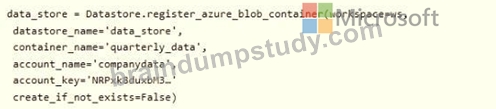
You need to create a dataset named training_data and load the data from all files into a single data frame by using the following code:
Solution: Run the following code: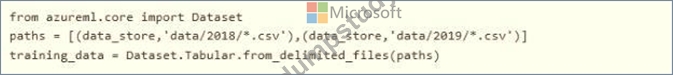
Does the solution meet the goal?
Answer: A
Explanation:
Use two file paths.
Use Dataset.Tabular_from_delimeted as the data isn ' t cleansed.
Note:
A TabularDataset represents data in a tabular format by parsing the provided file or list of files. This provides you with the ability to materialize the data into a pandas or Spark DataFrame so you can work with familiar data preparation and training libraries without having to leave your notebook. You can create a TabularDataset object from .csv, .tsv, .parquet, .jsonl files, and from SQL query results.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-create-register-datasets
NEW QUESTION # 318
You are preparing to build a deep learning convolutional neural network model for image classification. You create a script to train the model using CUDA devices. You must submit an experiment that runs this script in the Azure Machine Learning workspace. The following compute resources are available:
* a Microsoft Surface device on which Microsoft Office has been installed. Corporate IT policies prevent the installation of additional software
* a Compute Instance named ds-workstation in the workspace with 2 CPUs and 8 GB of memory
* an Azure Machine Learning compute target named cpu-cluster with eight CPU-based nodes
* an Azure Machine Learning compute target named gpu-cluster with four CPU and GPU-based nodes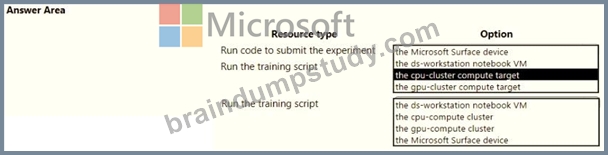
Answer:
Explanation: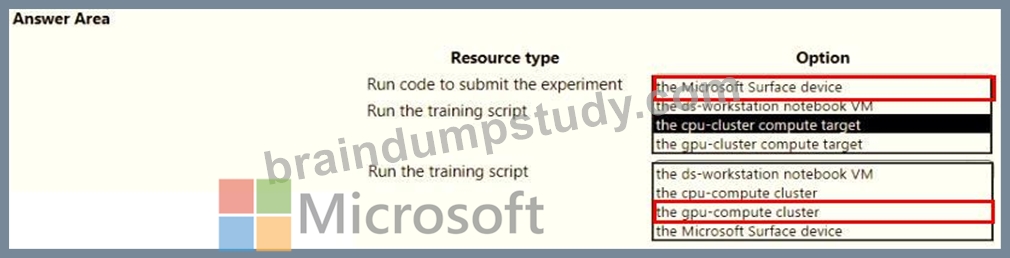
NEW QUESTION # 319
......
One of the main unique qualities of BraindumpStudy Designing and Implementing a Data Science Solution on Azure Exam Questions is its ease of use. Our practice exam simulators are user and beginner friendly. You can use Designing and Implementing a Data Science Solution on Azure (DP-100) PDF dumps and Web-based software without installation. Microsoft DP-100 PDF Questions work on all the devices like smartphones, Macs, tablets, Windows, etc. We know that it is hard to stay and study for the Designing and Implementing a Data Science Solution on Azure (DP-100) exam dumps in one place for a long time.
Latest DP-100 Dumps: https://www.braindumpstudy.com/DP-100_braindumps.html
P.S. Free & New DP-100 dumps are available on Google Drive shared by BraindumpStudy: https://drive.google.com/open?id=1YegriBJdRUk_moMFGVgBPwLl2RLH82pG