By contrasting with other products in the industry, our CCAR-P test guide really has a higher pass rate, which has been verified by many users. As long as you use our CCAR-P exam training I believe you can pass the exam. If you fail to pass the exam, we will give a full refund. CCAR-P learning guide hopes to progress together with you and work together for their own future. The high passing rate of CCAR-P exam training also requires your efforts. If you choose CCAR-P test guide, I believe we can together contribute to this high pass rate.
| Section | Weight | Objectives |
|---|---|---|
| Claude Models, Prompting & Context Engineering | 13% | - Design system prompts, templates, and guardrails - Mitigate prompt injection, leaks, and jailbreak risks - Apply context engineering and context management techniques - Select appropriate Claude models based on trade-offs |
| Evaluation, Testing & Optimization | 16% | - Implement iterative improvement pipelines - Test accuracy, reliability, latency, and cost - Define evaluation metrics and success criteria - Optimize performance, prompting, and model selection |
| Integration | 19% | - Integrate with data pipelines and RAG systems - Implement Model Context Protocol (MCP) integrations - Design authentication, authorization, and observability - Integrate Claude with enterprise systems, APIs, and tools |
| Stakeholder Communication & Lifecycle Management | 14% | - Manage stakeholder feedback and expectation alignment - Document architectures and support full lifecycle phases - Communicate architectural decisions and trade-offs - Conduct structured discovery and requirement gathering |
| Solution Design & Architecture | 17% | - Design multi-agent systems and orchestration strategies - Align solutions to business value pillars - Translate business problems into Claude-based AI solutions - Select architectural patterns: workflow, agentic, augmented LLM - Design end-to-end architectures and feedback loops |
| Developer Productivity & Operational Enablement | 7% | - Configure Claude tools and environments for teams - Support debugging, monitoring, and operational resolution - Improve developer workflows with AI-assisted tooling |
| Governance, Safety & Risk Management | 14% | - Implement guardrails and safety controls - Manage data privacy and security compliance - Address ethical AI considerations and bias mitigation - Ensure regulatory compliance (GDPR, HIPAA, etc.) |
>> CCAR-P Certification Training <<
With our CCAR-P exam questions, the most important and the most effective reward is that you can pass the exam and get the CCAR-P certification. And it is also what all of the candidates care about. At the same time, you can also get some more practical skills. Your work efficiency will increase and your life will be more capable. Our CCAR-P Guide questions are such a very versatile product to change your life and make you become better.
NEW QUESTION # 48
The compliance team at a firm has approved a Claude Skill that generates client-facing investment summaries. The Skill includes the firm's required disclaimers and prohibited-language list. A product manager has asked whether additional guardrails are needed at the application layer or whether the Skill alone is sufficient.
Which two guardrail responsibilities should remain at the application layer rather than the Skill? (Select two.) Each correct answer presents part of the solution.
Answer: C,D
Explanation:
Authorization and compliance logging must remain enforceable application-layer controls. Option B requires the application to authenticate the requester, resolve the user's role and entitlements, and deny the operation when the user lacks authority. A Skill can instruct Claude how to behave, but it is not a reliable security boundary and cannot replace identity-based access control enforced by the surrounding system.
Option A similarly belongs at the application layer. The application must create an authoritative audit event containing the requester, timestamp, Skill and model version, relevant input or content identifiers, generated output, review status, and retention classification. Audit evidence cannot depend on whether the model remembers or chooses to invoke a logging instruction.
Options C, D, and E describe reusable generation behavior that appropriately belongs within the approved Skill: house style, the standardized disclaimer, and the prohibited-language policy. The application may still validate their presence after generation, but the Skill remains the primary reusable content package.
The correct architecture separates behavioral guidance from deterministic enforcement. Skills supply domain instructions and templates; the application enforces identity, authorization, audit retention, data access, output validation, and consequential-action controls.
Study Guide references/topics: Skills versus application controls; authentication; authorization; compliance logging; deterministic guardrails; policy enforcement boundaries.
NEW QUESTION # 49
You are evaluating retrieval-strategy claims used by a peer team.
For each claim, select yes if the statement is generally accurate. Otherwise, select no.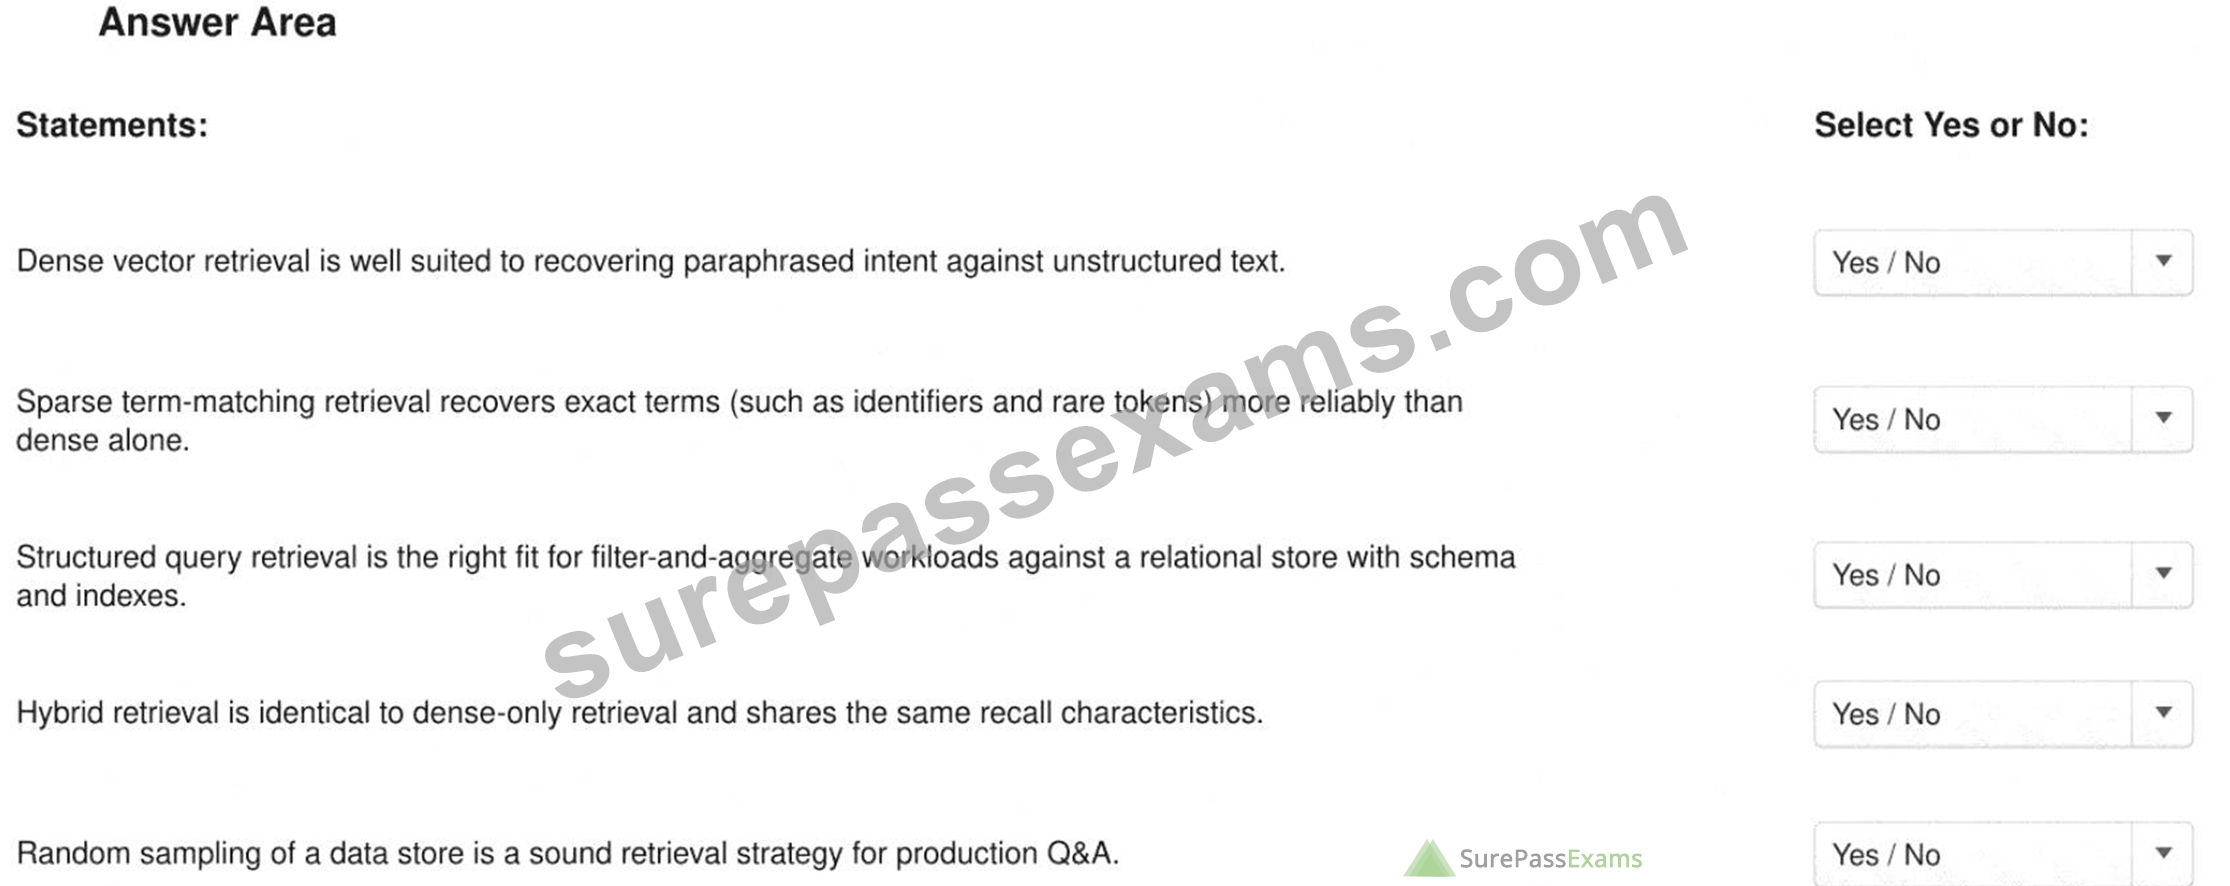
Answer:
Explanation: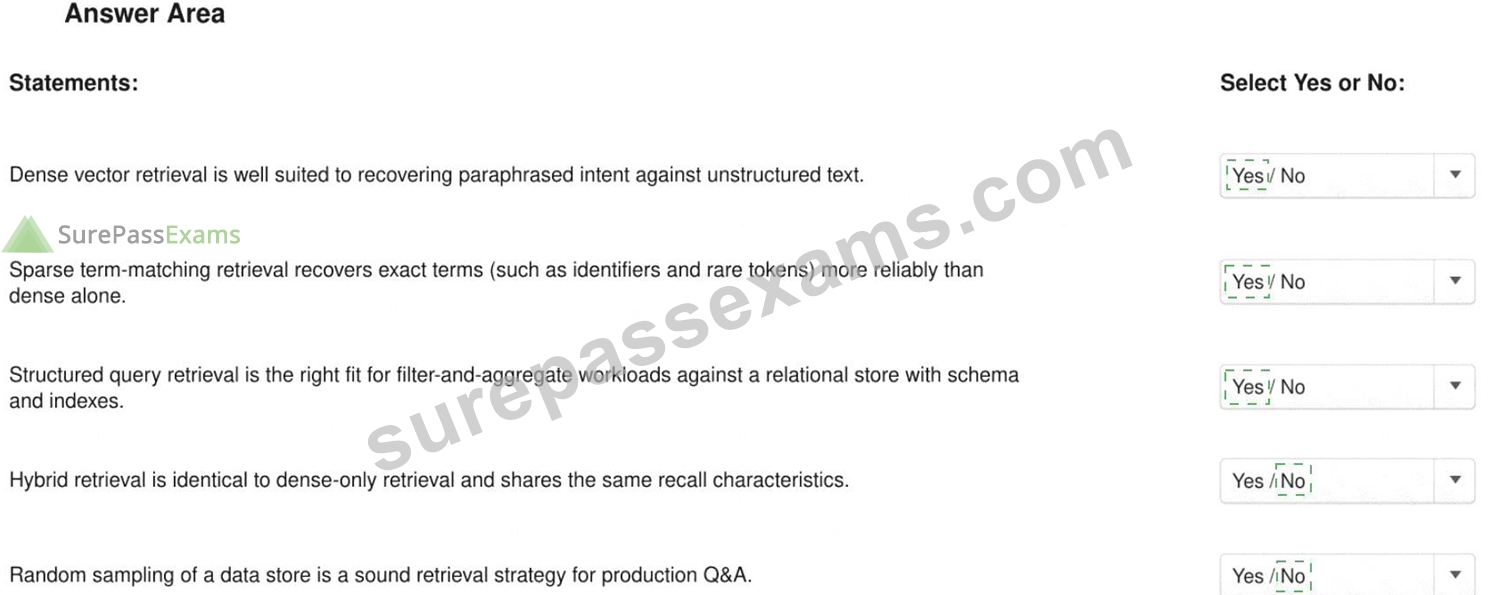
Explanation:
Yes, Yes, Yes, No, No
Dense vector retrieval represents semantic similarity, making it suitable for matching paraphrases and conceptually related language even when the query and source do not share identical words. Sparse lexical retrieval, including BM25-style matching, retains strong sensitivity to exact tokens and is therefore valuable for identifiers, product codes, technical names, and uncommon terminology.
Structured query retrieval is appropriate when the required operation depends on explicit fields, predicates, joins, counts, grouping, or aggregation over a relational schema. In that situation, generating or invoking a constrained database query is more precise than approximating the operation through semantic similarity.
Hybrid retrieval is not identical to dense retrieval. It combines semantic and lexical candidate sets, typically followed by rank fusion or reranking. Anthropic's contextual-retrieval guidance explains that semantic search captures meaning and paraphrases, while BM25 captures exact terminology; combining them improves coverage. Contextual Retrieval, Contextual Retrieval Cookbook Random sampling is not a relevance strategy. It provides no systematic relationship between the query and selected evidence, producing unstable coverage and preventable hallucination risk. Production Q & A requires deterministic or evaluated relevance mechanisms, access filters, suitable indexes, and measurable retrieval metrics such as recall at k.
Study Guide references/topics: Dense retrieval; sparse retrieval; structured queries; hybrid search; rank fusion; retrieval evaluation; production RAG design.
NEW QUESTION # 50
You are running a discovery session with a business sponsor who asks for "an AI system to fix our customer escalations." Which approach best yields actionable requirements?
Answer: C
Explanation:
The sponsor's statement expresses a desired outcome but does not define an implementable requirement.
Option B converts the vague request into concrete information about users, workflow triggers, expected resolutions, decision boundaries, and non-functional constraints. These findings can then be translated into measurable success criteria, evaluation cases, integration requirements, and escalation rules. Anthropic's evaluation guidance states that an LLM application should begin with specific, measurable, achievable, and relevant success criteria. Option A prematurely treats an aspiration as a complete specification. Option C incorrectly transfers discovery responsibility entirely to the sponsor, while Option D imports assumptions from an unrelated context. Effective Claude architecture requires traceability from the business problem through requirements, evaluation measures, design decisions, and production acceptance criteria. Anthropic:
Define success criteria and build evaluations
NEW QUESTION # 51
You are selecting a model for a new production workload and must complete the upstream steps before testing candidate models empirically.
Which two steps must be completed BEFORE running a representative sample on a candidate model? (Select two.) Each correct answer presents part of the solution.
Answer: A,D
Explanation:
Empirical model testing requires a defined decision frame. Option D must occur first because the quality threshold, acceptable latency, expected request volume, and associated cost envelope determine what constitutes a successful result. Without these criteria, a representative-sample test can produce measurements but cannot support a defensible selection.
Option C is the next upstream step. Known model capabilities and the workload profile are used to identify a plausible candidate rather than testing models arbitrarily. Anthropic's model-selection guidance recommends evaluating capability, speed, cost, and effort requirements before narrowing the candidate set. Choosing the Right Model Option A occurs after empirical testing because the architect cannot know which lightest model consistently meets the quality bar until sample results have been evaluated. Option B belongs to ongoing lifecycle management after a new version becomes available. Option E is a deployment-governance activity that follows successful model selection, security review, and readiness validation.
The correct sequence is: define workload criteria, shortlist candidate models, run a representative evaluation, compare quality and operational metrics, select the least costly model that reliably satisfies all gates, and periodically retest the decision.
Study Guide references/topics: Requirements-driven model selection; representative sampling; quality thresholds; latency and volume requirements; capability-cost trade-offs; model lifecycle reassessment.
NEW QUESTION # 52
You are building an ethics-review checklist for deployments supported by artificial intelligence.
Which two checks belong on the list? (Select two.)
Each correct answer presents a complete solution.
Answer: C,D
Explanation:
An ethics review must examine unsupported generalizations, stereotyping, disparate treatment, and other conclusions about people that are not justified by the evidence. It must also preserve identifiable human accountability for consequential decisions; responsibility cannot be transferred to a probabilistic system.
Licensing is a legal and commercial-control question, while latency and throughput are operational requirements. Both remain important, but neither is the central ethical test presented here. Restricting review to low-confidence or threshold-triggering outputs is also inadequate because models can express harmful or biased conclusions with high confidence. Ethical review should cover representative populations, protected and intersectional groups, high-impact outcomes, override mechanisms, transparency, and channels for challenge or appeal.
Study Guide references/topics: Bias and unsupported generalization; human accountability; consequential decisions; ethical oversight.
NEW QUESTION # 53
......
Obtaining the CCAR-P certificate will make your colleagues and supervisors stand out for you, because it represents your professional skills. At the same time, it will also give you more opportunities for promotion and job-hopping. The CCAR-P latest exam dumps have different classifications for different qualification examinations, which can enable students to choose their own learning mode for themselves according to the actual needs of users. On buses or subways, you can use fractional time to test your learning outcomes with CCAR-P Test Torrent, which will greatly increase your pro forma efficiency.
Latest CCAR-P Test Camp: https://www.surepassexams.com/CCAR-P-exam-bootcamp.html