Databricks Certified-Data-Engineer-Professional Reliable Exam Online & Test Certified-Data-Engineer-Professional Questions Fee

Our Certified-Data-Engineer-Professional test torrent is of high quality, mainly reflected in the pass rate. Our Certified-Data-Engineer-Professional test torrent is carefully compiled by industry experts based on the examination questions and industry trends in the past few years. More importantly, we will promptly update our Certified-Data-Engineer-Professional exam materials based on the changes of the times and then send it to you timely. 99% of people who use our learning materials have passed the exam and successfully passed their certificates, which undoubtedly show that the passing rate of our Certified-Data-Engineer-Professional Test Torrent is 99%.
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Topic 2: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 3: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Topic 4: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 5: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 6: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 4. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 5. Create pipeline components using control flow operators such as if/else and foreach
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
|
| Topic 7: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Topic 8: Data Modeling | - Design and optimize data models
- 1. Design dimensional models for analytical workloads with efficient querying and aggregation
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Topic 9: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Topic 10: Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Query Profile and Spark UI to monitor workloads
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
>> Databricks Certified-Data-Engineer-Professional Reliable Exam Online <<
Marvelous Certified-Data-Engineer-Professional Reliable Exam Online Covers the Entire Syllabus of Certified-Data-Engineer-Professional
As we all know it is not easy to obtain the Certified-Data-Engineer-Professional certification, and especially for those who cannot make full use of their sporadic time. But you are lucky, we can provide you with well-rounded services on Certified-Data-Engineer-Professional practice braindumps to help you improve ability. You would be very pleased and thankful if you can spare your time to have a look about features of our Certified-Data-Engineer-Professional Study Materials. With the pass rate high as 98% to 100%, you can totally rely on our Certified-Data-Engineer-Professional exam questions.
Databricks Certified Data Engineer Professional Sample Questions (Q234-Q239):
NEW QUESTION # 234
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
- A. Schema inference and evolution on Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- B. Tungsten encoding used by Databricks is optimized for storing string data: newly-added native support for querying JSON strings means that string types are always most efficient.
- C. By default Delta Lake collects statistics on the first 32 columns in a table; these statistics are leveraged for data skipping when executing selective queries.
- D. Because Delta Lake uses Parquet for data storage, Dremel encoding information for nesting can be directly referenced by the Delta transaction log.
Answer: C
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
NEW QUESTION # 235
A streaming video analytics team ingests billions of events daily into a Unity Catalog-managed Delta table video_events. Analysts run ad-hoc point-lookup queries on columns like user_id, campaign_id, and region. The team manually runs OPTIMIZE video_events ZORDER BY (user_id, campaign_id, region), but still sees poor performance on recent data and dislikes the operational overhead. The team wants a hands-off way to keep hot columns co-located as query patterns evolve. Which Delta capability should the team leverage on video_events?
- A. Utilize Liquid Clustering (CLUSTER BY AUTO) and Predictive Optimization.
- B. Enable Delta caching.
- C. Enable auto-compaction (optimizeWrite and autoCompact).
- D. Schedule OPTIMIZE/ZORDER to run after each job to improve recent file performance.
Answer: A
Explanation:
According to Databricks Delta Lake optimization documentation, Liquid Clustering is a next- generation file organization capability that automatically manages file co-location without requiring explicit partitioning or manual Z-ORDERing. When combined with Predictive Optimization, Databricks automatically maintains clustering across frequently filtered or queried columns, adapting dynamically as query workloads evolve.
This approach eliminates the need for manual maintenance (such as periodic OPTIMIZE or Z- ORDER commands) while improving query performance on large tables--particularly for high- ingest streaming workloads.
Delta caching (B) only improves performance for cached queries and does not address file layout issues, and (D) handles file size optimization but not clustering. Thus, C is the most efficient, modern, and low-maintenance solution recommended by Databricks.
NEW QUESTION # 236
A view is registered with the following code:
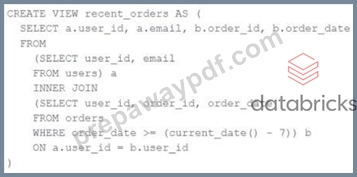
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. All logic will execute when the view is defined and store the result of joining tables to the DBFS; this stored data will be returned when the view is queried.
- B. Results will be computed and cached when the view is defined; these cached results will incrementally update as new records are inserted into source tables.
- C. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- D. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
Answer: C
NEW QUESTION # 237
A table in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
- A. Convert the batch job to a Structured Streaming job using the complete output mode; configure a Structured Streaming job to read from the customer_churn_params table and incrementally predict against the churn model.
- B. Modify the overwrite logic to include a field populated by calling
spark.sql.functions.current_timestamp() as data are being written; use this field to identify records written on a particular date. - C. Apply the churn model to all rows in the customer_churn_params table, but implement logic to perform an upsert into the predictions table that ignores rows where predictions have not changed.
- D. Replace the current overwrite logic with a merge statement to modify only those records that have changed; write logic to make predictions on the changed records identified by the change data feed.
- E. Calculate the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers before making new predictions; only make predictions on those customers not in the previous predictions.
Answer: D
Explanation:
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed.
This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
NEW QUESTION # 238
A data engineer is implementing Unity Catalog governance for a multi-team environment. Data scientists need interactive clusters for basic data exploration tasks, while automated ETL jobs require dedicated processing. How should the data engineer configure cluster isolation policies to enforce least privilege and ensure Unity Catalog compliance?
- A. Create compute policies with STANDARD access mode for interactive workloads and DEDICATED access mode for automated jobs.
- B. Configure all clusters with NO ISOLATION_SHARED access mode since Unity Catalog works with any cluster configuration.
- C. Allow all users to create any cluster type and rely on manual configuration to enable Unity Catalog access modes.
- D. Use only DEDICATED access mode for both interactive workloads and automated jobs to maximize security isolation.
Answer: A
Explanation:
Unity Catalog enforces governance and data isolation through cluster access modes and compute policies. According to Databricks documentation, "Interactive clusters that multiple users share should use Standard access mode, while automated jobs and production pipelines should use Dedicated access mode for stricter isolation." Standard access mode allows multiple users to share the same compute resources but still respects Unity Catalog permissions. Dedicated access mode isolates the job run's execution environment, ensuring that data access is limited to the job's identity. Configuring these modes within compute policies enforces least privilege and ensures all compute complies with Unity Catalog security standards. Options A and C are incorrect because using only Dedicated clusters reduces resource efficiency, while "No isolation" clusters are not Unity Catalog compliant.
NEW QUESTION # 239
......
After we develop a new version, we will promptly notify you. At Certified-Data-Engineer-Professional, you have access to the best resources in the industry. We guarantee that you absolutely don't need to spend extra money to buy other products. Certified-Data-Engineer-Professional practice materials will definitely make you feel value for money. If you are really in doubt, you can use our trial version of our Certified-Data-Engineer-Professional Exam Questions first. We believe that you will definitely make a decision immediately after use!
Test Certified-Data-Engineer-Professional Questions Fee: https://www.prepawaypdf.com/Databricks/Certified-Data-Engineer-Professional-practice-exam-dumps.html
- Free PDF 2026 Pass-Sure Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Reliable Exam Online 🈺 Search for ➤ Certified-Data-Engineer-Professional ⮘ and easily obtain a free download on ▛ www.practicevce.com ▟ 🍡Updated Certified-Data-Engineer-Professional CBT
- Certified-Data-Engineer-Professional Exam Study Solutions 🐺 New Certified-Data-Engineer-Professional Study Materials 🌱 New Study Certified-Data-Engineer-Professional Questions 💋 ✔ www.pdfvce.com ️✔️ is best website to obtain ➽ Certified-Data-Engineer-Professional 🢪 for free download 🍇Certified-Data-Engineer-Professional Reliable Exam Pattern
- Reliable Certified-Data-Engineer-Professional Study Materials 😝 Valid Braindumps Certified-Data-Engineer-Professional Book 🧝 Valid Braindumps Certified-Data-Engineer-Professional Book 📬 Search for 【 Certified-Data-Engineer-Professional 】 and download it for free on ▷ www.prepawaypdf.com ◁ website 🧑New Certified-Data-Engineer-Professional Practice Materials
- 2026 Realistic Databricks Certified-Data-Engineer-Professional Reliable Exam Online Pass Guaranteed 🥩 Search for “ Certified-Data-Engineer-Professional ” and download it for free on ➠ www.pdfvce.com 🠰 website 🌵Certified-Data-Engineer-Professional Exam Study Solutions
- 2026 Realistic Databricks Certified-Data-Engineer-Professional Reliable Exam Online Pass Guaranteed 🤟 Easily obtain free download of 《 Certified-Data-Engineer-Professional 》 by searching on ( www.prepawaypdf.com ) 🌘Latest Certified-Data-Engineer-Professional Test Cram
- How to Prepare for Certified-Data-Engineer-Professional Certification Exam? 🤔 The page for free download of { Certified-Data-Engineer-Professional } on ➠ www.pdfvce.com 🠰 will open immediately 🔒Certified-Data-Engineer-Professional Latest Exam Pass4sure
- Certified-Data-Engineer-Professional Reliable Exam Pattern 🛂 Certified-Data-Engineer-Professional Online Tests 🈵 Valid Braindumps Certified-Data-Engineer-Professional Book 📫 Copy URL 【 www.vce4dumps.com 】 open and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download for free 👶Certified-Data-Engineer-Professional Accurate Answers
- Free PDF Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional –Efficient Reliable Exam Online 🧤 Open ➡ www.pdfvce.com ️⬅️ enter ▛ Certified-Data-Engineer-Professional ▟ and obtain a free download 🕗New Certified-Data-Engineer-Professional Practice Materials
- Free PDF Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional –Efficient Reliable Exam Online 🤪 Search for ➽ Certified-Data-Engineer-Professional 🢪 and download exam materials for free through ➠ www.pdfdumps.com 🠰 🐂Certified-Data-Engineer-Professional Latest Exam Pass4sure
- Certified-Data-Engineer-Professional Exams Training 😙 New Certified-Data-Engineer-Professional Test Pdf 🚚 Updated Certified-Data-Engineer-Professional CBT 📏 Easily obtain free download of ➥ Certified-Data-Engineer-Professional 🡄 by searching on ⮆ www.pdfvce.com ⮄ 🚋Certified-Data-Engineer-Professional Reliable Exam Pattern
- Best Way to Prepare For Databricks Certified-Data-Engineer-Professional Certification Exam 🦰 Open website “ www.vceengine.com ” and search for ⇛ Certified-Data-Engineer-Professional ⇚ for free download 🧼Certified-Data-Engineer-Professional Reliable Exam Pattern
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes