100% Pass Quiz Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional–The Best Valid Study Guide
P.S. Free & New Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by TestPassed: https://drive.google.com/open?id=155SJrofaKPJKFscoimy3zfkwhvvzcqo2
Our PDF version of Databricks-Machine-Learning-Professional training materials is legible to read and remember, and support printing request. Software version of Databricks-Machine-Learning-Professional practice materials supports simulation test system, and give times of setup has no restriction. Remember this version support Windows system users only. App online version of Databricks-Machine-Learning-Professional Exam Questions is suitable to all kinds of equipment or digital devices and supportive to offline exercise on the condition that you practice it without mobile data.
| Topic | Details |
|---|
| Topic 1 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 2 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 3 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Topic 4 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 5 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 6 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 7 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 8 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 9 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 10 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
>> Databricks-Machine-Learning-Professional Valid Study Guide <<
Covers 100% Composite Exams Databricks-Machine-Learning-Professional Critical Information
Our company’s Databricks-Machine-Learning-Professional exam questions are reliable packed with the best available information. It is always relevant to the real Databricks-Machine-Learning-Professional exam as it is regularly updated by the best and the most professional experts. As long as you study with our Databricks-Machine-Learning-Professional learning braindumps, you will be surprised by the most accurate exam questions and answers that will show up exactly in the real exam. So what are you waiting for? Just put them to the cart and buy!
Databricks Certified Machine Learning Professional Sample Questions (Q22-Q27):
NEW QUESTION # 22
A Machine Learning Engineer has a large dataset with a customer_region column and wants to train separate models for each region, then generate predictions. They need to parallelize this group-specific model training process using Databricks and the Pandas Function API. Which approach will implement this solution?
- A. Use mapInPandas() to apply the training function across all partitions without grouping.
- B. Use groupBy("customer_region") and apply a training function with applyInPandas().
- C. Use foreachBatch() to sequentially process each region's data.
- D. Use collect() to gather all data and process regions using standard pandas groupby.
Answer: B
Explanation:
The Pandas Function API supports parallel, group-specific processing by using groupBy on the grouping column and applyInPandas to execute a custom training function independently for each group. This enables separate models to be trained per region in parallel across the cluster, with each function invocation receiving only the data for its group.
NEW QUESTION # 23
A Machine Learning Engineer needs a continuous deployment pipeline for their models hosted on Databricks Model Serving. The deployment automation should execute after a model is trained and registered using MLflow. The goal of the automation is to deploy the latest version of the model from the MLflow Model Registry only if the model can meet the company's strict latency requirements (P95 < 300ms) while serving production traffic. How can the engineer validate that new models meet their latency requirements when served in production?
- A. Serve the latest model on Databricks Model Serving and use a load testing client to generate requests at the production request rate. Use the load testing client to calculate P95 latency and verify it is less than 300ms.
- B. Use the MLflow Get Run API to retrieve the model metrics from MLflow Tracking and verify that the inference_latency metric is less than 300ms.
- C. A/B test the latest model with Databricks Model Serving so that the latest model receives 5% of production traffic and the current model receives the rest. Use inference tables to calculate P95 latency and verify it is less than 300ms.
- D. Use the MLflow Get Run API to retrieve the model metrics from MLflow Tracking and verify that the model_latency metric is less than 300ms.
Answer: C
Explanation:
Validating latency requirements must be done under real production serving conditions. Routing a small percentage of live production traffic to the new model using Databricks Model Serving allows accurate measurement of end-to-end serving latency. Inference tables capture request latency metrics, enabling calculation of the P95 latency and ensuring it meets the strict production threshold before full rollout.
NEW QUESTION # 24
A machine learning engineer and data scientist are working together to convert a batch deployment to an always-on streaming deployment. The machine learning engineer has expressed that rigorous data tests must be put in place as a part of their conversion to account for potential changes in data formats.
Which of the following describes why these types of data type tests and checks are particularly important for streaming deployments?
- A. Because the streaming deployment is always on, there is no practitioner to debug poor model performance
- B. Because the streaming deployment is always on, there is a need to confirm that the deployment can autoscale
- C. None of these statements
- D. Because the streaming deployment is always on, all types of data must be handled without producing an error
- E. All of these statements
Answer: B
NEW QUESTION # 25
A Machine Learning Engineer has previously built a feature table for model training and inference using a batch mode approach:
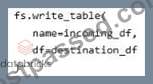
They have been informed that they now require these features to be available in "real-time", with latency on the order of a minute. Their manager has informed them there is now a Kafka stream from which they can stream live data, and they need to have this ingested and available for low- latency feature lookups.
Which change to their existing code will achieve this?
- A. Change the incoming_df to be a dataframe based on a readStream() from the Kafka source and publish the table as an online table with the streaming option set to True.
- B. Create a custom pyfunc MLflow model which processes results of the Kafka stream for on demand feature calculation.
- C. Run a triggered workflow to ingest the Kafka data to a dataframe that they can use with their existing write_table() command.
- D. Change the incoming_df to be a dataframe based on a readStream() from the kafka source, the write_table() method will provide a low-latency lookup on this data.
Answer: A
Explanation:
To achieve real-time availability with minute-level latency, the feature data must be continuously ingested from Kafka and published to an online table. Using a streaming DataFrame created with readStream from the Kafka source and enabling the online table with streaming allows incremental updates to be synchronized to the online store, supporting low-latency feature lookups for real-time inference.
NEW QUESTION # 26
A machine learning engineer has detected that concept drift is occurring in a production machine learning application. Which result is the impact of concept drift?
- A. The model's efficacy will increase
- B. The model's latency will increase
- C. The model's efficacy will decrease
- D. The model's latency will decrease
Answer: C
Explanation:
Concept drift occurs when the relationship between input features and the target variable changes over time. This leads to a decrease in the model's efficacy, as the model is no longer accurately capturing the underlying data patterns it was trained on.
NEW QUESTION # 27
......
The price for Databricks-Machine-Learning-Professional study materials is quite reasonable, no matter you are a student at school or an employee in the company, you can afford it. Just think that you just need to spend some money, you can get the certificate. What’s more, Databricks-Machine-Learning-Professional exam materials are compiled by skilled professionals, and they cover the most knowledge points and will help you pass the exam successfully. We have online and offline chat service stuff, they have the professional knowledge about Databricks-Machine-Learning-Professional Exam Dumps, and you can have a chat with them if you have any questions.
Databricks-Machine-Learning-Professional Certification Exam Infor: https://www.testpassed.com/Databricks-Machine-Learning-Professional-still-valid-exam.html
- Prepare well and Pass the Databricks Databricks-Machine-Learning-Professional Exam on the first attempt ⛪ Search for ➽ Databricks-Machine-Learning-Professional 🢪 and download it for free immediately on ➽ www.easy4engine.com 🢪 🏄Free Databricks-Machine-Learning-Professional Sample
- Databricks Databricks-Machine-Learning-Professional Valid Study Guide: Databricks Certified Machine Learning Professional - Pdfvce Free Download for you any time 🛕 Search for 《 Databricks-Machine-Learning-Professional 》 and download it for free on ▶ www.pdfvce.com ◀ website 📄Free Databricks-Machine-Learning-Professional Sample
- Free Databricks-Machine-Learning-Professional Sample 📝 Free Databricks-Machine-Learning-Professional Sample 🐍 Latest Databricks-Machine-Learning-Professional Exam Preparation 🌴 Search on “ www.examcollectionpass.com ” for ▷ Databricks-Machine-Learning-Professional ◁ to obtain exam materials for free download 🏫Databricks-Machine-Learning-Professional Valid Test Voucher
- Databricks Databricks-Machine-Learning-Professional Exam Questions Are Designed By Experts 🤒 Enter ➥ www.pdfvce.com 🡄 and search for 《 Databricks-Machine-Learning-Professional 》 to download for free 🏆Databricks-Machine-Learning-Professional Authorized Certification
- Databricks Databricks-Machine-Learning-Professional Exam Questions Are Designed By Experts 🚾 Easily obtain { Databricks-Machine-Learning-Professional } for free download through ☀ www.examcollectionpass.com ️☀️ 🕔Databricks-Machine-Learning-Professional Certification
- Databricks-Machine-Learning-Professional Exam Papers ▛ Databricks-Machine-Learning-Professional Exam Papers 👧 Accurate Databricks-Machine-Learning-Professional Answers 🧺 Search for ▶ Databricks-Machine-Learning-Professional ◀ and download it for free on ▶ www.pdfvce.com ◀ website ⏩Exam Databricks-Machine-Learning-Professional Price
- Databricks-Machine-Learning-Professional Practice Materials: Databricks Certified Machine Learning Professional - Databricks-Machine-Learning-Professional Test Preparation - www.vceengine.com 😇 Go to website ✔ www.vceengine.com ️✔️ open and search for ✔ Databricks-Machine-Learning-Professional ️✔️ to download for free 🦕Databricks-Machine-Learning-Professional Pass Test Guide
- Actual Databricks Databricks-Machine-Learning-Professional Exam Questions – Key To Success 😽 Simply search for ➽ Databricks-Machine-Learning-Professional 🢪 for free download on ➤ www.pdfvce.com ⮘ 🍁Databricks-Machine-Learning-Professional Valid Test Voucher
- Top Databricks-Machine-Learning-Professional Valid Study Guide | Valid Databricks Databricks-Machine-Learning-Professional Certification Exam Infor: Databricks Certified Machine Learning Professional 📯 Search for “ Databricks-Machine-Learning-Professional ” and obtain a free download on ▛ www.examcollectionpass.com ▟ 🧛Exam Databricks-Machine-Learning-Professional Price
- Databricks Databricks-Machine-Learning-Professional Valid Study Guide: Databricks Certified Machine Learning Professional - Pdfvce Free Download for you any time 🦐 Open ▶ www.pdfvce.com ◀ and search for ⮆ Databricks-Machine-Learning-Professional ⮄ to download exam materials for free ⚾Databricks-Machine-Learning-Professional Authorized Certification
- Actual Databricks Databricks-Machine-Learning-Professional Exam Questions – Key To Success 🗣 Search for ➽ Databricks-Machine-Learning-Professional 🢪 on { www.testkingpass.com } immediately to obtain a free download 👡Exam Databricks-Machine-Learning-Professional Voucher
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, semasocial.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 Databricks Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by TestPassed: https://drive.google.com/open?id=155SJrofaKPJKFscoimy3zfkwhvvzcqo2