P.S. Free & New Mule-Arch-201 dumps are available on Google Drive shared by PracticeDump: https://drive.google.com/open?id=1otpoam4_w_mubeJ0GqaTO-ZS8oEjPf4q
Passing an exam isn’t an easy thing for some candidates, if youchoose the Mule-Arch-201 training materials of us, we will make the exam easier for you. Mule-Arch-201 training materials include knowledge points, you can remember them through practicing. Mule-Arch-201 questions and answers will list the right answer for you, what you need to do is to practice them. In addition, there are experienced specialists checking the Mule-Arch-201 Exam Dumps, they will ensure the timely update for the latest version.
| Section | Weight | Objectives |
|---|---|---|
| Meeting API Quality Goals | 8% | - API Performance Optimization - Resilience & Reliability Patterns - Unit & Integration Testing |
| Understanding the MuleSoft Platform & Application Networks | 11% | - Application Network Fundamentals - MuleSoft Anypoint Platform Core Concepts - C4E (Center for Enablement) Definition |
| Architecting and Deploying API Implementations | 11% | - Mule Runtime Architecture - High Availability (HA) Design - Disaster Recovery (DR) Strategies |
| Designing and Sharing APIs | 11% | - API-Led Connectivity Approach - Anypoint Exchange for Sharing Assets - API Design Best Practices |
| Deploying API Implementations to CloudHub | 11% | - Deployment Strategies - CloudHub 2.0 & Runtime Fabric - CloudHub Architecture |
| Establishing Organizational and Platform Foundations | 17% | - IT Delivery & C4E Operating Model - Platform Foundation Setup - Governance and Compliance Framework |
| Managing APIs | 12% | - API Security (Policies, SLAs) - API Versioning - API Lifecycle Management |
| Monitoring and Analyzing Application Networks | 8% | - Alerting & Auditing - Anypoint Monitoring Tools - Analytics & Business Insights |
| Applying Integration Patterns | 11% | - Batch Processing - Integration Scenarios & Patterns - Event-Driven Architecture (EDA) |
>> Mule-Arch-201 Latest Braindumps Sheet <<
As old saying goes, god will help those who help themselves. So you must keep inspiring yourself no matter what happens. At present, our Mule-Arch-201 exam materials are able to motivate you a lot. Our products will help you overcome your laziness. And you will become what you want to be with the help of our Mule-Arch-201 learning questions. You can realize and reach your dream. Also, you will have a pleasant learning of our Mule-Arch-201 study quiz.
NEW QUESTION # 115
A Rate Limiting policy is applied to an API implementation to protect the back-end system. Recently, there have been surges in demand that cause some API client POST requests to the API implementation to be rejected with policy-related errors, causing delays and complications to the API clients.
How should the API policies that are applied to the API implementation be changed to reduce the frequency of errors returned to API clients, while still protecting the back-end system?
Answer: A
Explanation:
When managing high traffic to an API, especially with POST requests, it is crucial to ensure the API's policies both protect the back-end systems and provide a smooth client experience. Here's the approach to reducing errors:
Rate Limiting Policy: This policy enforces a limit on the number of requests within a defined time period. However, rate limiting alone may cause clients to hit limits during demand surges, leading to errors.
Adding an SLA-based Spike Control Policy:
Spike Control is designed to handle sudden increases in traffic by smoothing out bursts of requests, which is particularly useful during high-demand periods.
By configuring SLA-based Spike Control, you can define thresholds for specific client tiers. For instance, premium clients might have higher limits or more flexibility in traffic bursts than standard clients.
Why Option D is Correct:
Keeping the Rate Limiting policy continues to provide baseline protection for the back-end.
Adding the SLA-based Spike Control policy allows for differentiated control, where requests are queued or delayed during bursts rather than outright rejected. This approach significantly reduces error responses to clients while still controlling overall traffic.
of Incorrect Options:
Option A (adding Client ID Enforcement) would not reduce errors related to traffic surges.
Option B (HTTP Caching) is not applicable as caching is generally ineffective for non-idempotent requests like POST.
Option C (only Spike Control without Rate Limiting) may leave the back-end system vulnerable to sustained high traffic levels, reducing protection.
Reference
For more information on configuring Rate Limiting and SLA-based Spike Control policies, refer to MuleSoft documentation on API Policies and Rate Limiting.
NEW QUESTION # 116
A REST API is being designed to implement a Mule application.
What standard interface definition language can be used to define REST APIs?
Answer: C
NEW QUESTION # 117
Due to a limitation in the backend system, a system API can only handle up to 500 requests per second. What is the best type of API policy to apply to the system API to avoid overloading the backend system?
Answer: B
Explanation:
Correct Answe r: Spike control
*****************************************
>> First things first, HTTP Caching policy is for purposes different than avoiding the backend system from overloading. So this is OUT.
>> Rate Limiting and Throttling/ Spike Control policies are designed to limit API access, but have different intentions.
>> Rate limiting protects an API by applying a hard limit on its access.
>> Throttling/ Spike Control shapes API access by smoothing spikes in traffic.
That is why, Spike Control is the right option.
NEW QUESTION # 118
A retail company with thousands of stores has an API to receive data about purchases and insert it into a single database. Each individual store sends a batch of purchase data to the API about every 30 minutes. The API implementation uses a database bulk insert command to submit all the purchase data to a database using a custom JDBC driver provided by a data analytics solution provider. The API implementation is deployed to a single CloudHub worker. The JDBC driver processes the data into a set of several temporary disk files on the CloudHub worker, and then the data is sent to an analytics engine using a proprietary protocol. This process usually takes less than a few minutes. Sometimes a request fails. In this case, the logs show a message from the JDBC driver indicating an out-of-file-space message. When the request is resubmitted, it is successful. What is the best way to try to resolve this throughput issue?
Answer: C
Explanation:
Correct Answe r: Increase the size of the CloudHub worker(s)
*****************************************
The key details that we can take out from the given scenario are:
>> API implementation uses a database bulk insert command to submit all the purchase data to a database
>> JDBC driver processes the data into a set of several temporary disk files on the CloudHub worker
>> Sometimes a request fails and the logs show a message indicating an out-of-file-space message Based on above details:
>> Both auto-scaling options does NOT help because we cannot set auto-scaling rules based on error messages. Auto-scaling rules are kicked-off based on CPU/Memory usages and not due to some given error or disk space issues.
>> Increasing the number of CloudHub workers also does NOT help here because the reason for the failure is not due to performance aspects w.r.t CPU or Memory. It is due to disk-space.
>> Moreover, the API is doing bulk insert to submit the received batch data. Which means, all data is handled by ONE worker only at a time. So, the disk space issue should be tackled on "per worker" basis. Having multiple workers does not help as the batch may still fail on any worker when disk is out of space on that particular worker.
Therefore, the right way to deal this issue and resolve this is to increase the vCore size of the worker so that a new worker with more disk space will be provisioned.
NEW QUESTION # 119
Which APIs can be used with DataGraph to create a unified schema?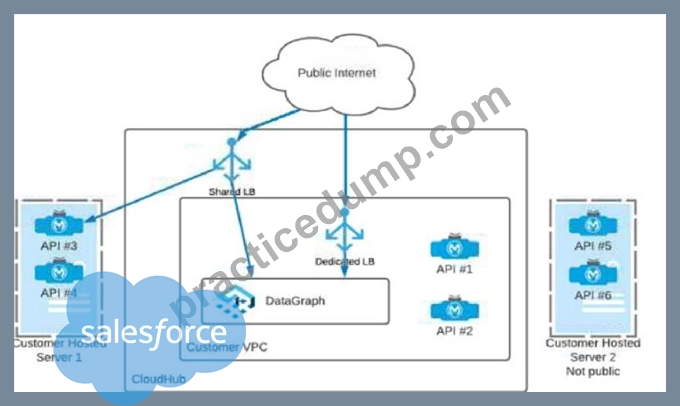
Answer: B
Explanation:
To create a unified schema in MuleSoft's DataGraph, APIs must be exposed in a way that allows DataGraph to pull and consolidate data from these APIs into a single schema accessible to consumers. DataGraph provides a federated approach, combining multiple APIs to form a single, unified API endpoint.
In this setup:
APIs 1, 2, 3, and 4 are suitable candidates for DataGraph because they are hosted within the Customer VPC on CloudHub and are accessible either through a Shared Load Balancer (LB) or a Dedicated Load Balancer (DLB). Both of these load balancers provide public access, which is a necessary condition for DataGraph as it must access the APIs to aggregate data.
APIs 5 and 6 are hosted on Customer Hosted Server 2, which is explicitly marked as "Not public". Since DataGraph requires API access through a publicly reachable endpoint to aggregate them into a unified schema, APIs 5 and 6 cannot be used with DataGraph in this configuration.
APIs 3 and 4 on Customer Hosted Server 1 appear accessible through a Shared LB, implying public accessibility that meets DataGraph's requirements.
By combining APIs 1, 2, 3, and 4 within DataGraph, you can create a unified schema that enables clients to query data seamlessly from all these APIs as if it were from a single source.
This setup allows for efficient data retrieval and can simplify API consumption by reducing the need to call multiple APIs individually, thus optimizing performance and developer experience.
Reference
For more detailed information on setting up and managing unified schemas in DataGraph, refer to the DataWeave documentation and MuleSoft DataGraph resources which provide in-depth guidelines on schema aggregation and API federation.
NEW QUESTION # 120
......
According to the survey, the candidates most want to take Salesforce Mule-Arch-201 test in the current IT certification exams. Of course, the Salesforce Mule-Arch-201 certification is a very important exam which has been certified. In addition, the exam qualification can prove that you have high skills. However, like all the exams, Salesforce Mule-Arch-201 test is also very difficult. To pass the exam is difficult but PracticeDump can help you to get Salesforce Mule-Arch-201 certification.
Upgrade Mule-Arch-201 Dumps: https://www.practicedump.com/Mule-Arch-201_actualtests.html
P.S. Free 2026 Salesforce Mule-Arch-201 dumps are available on Google Drive shared by PracticeDump: https://drive.google.com/open?id=1otpoam4_w_mubeJ0GqaTO-ZS8oEjPf4q