BTW, DOWNLOAD part of PDFDumps SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1rnJcnY0B-nd2eOAtlZY8VJMaQTyk0nys
A variety of PDFDumps’ Snowflake dumps are very helpful for the preparation to get assistance in this regard. It is designed exactly according to the exams curriculum. The use of test preparation exam questions helps them to practice thoroughly. Rely on material of the Free SPS-C01 Braindumps online (easily available) sample tests, and resource material available on our website. These free web sources are significant for SPS-C01 certification syllabus. Our website provides the sufficient material regarding SPS-C01 exam preparation.
| Section | Weight | Objectives |
|---|---|---|
| Snowpark API for Python | 30% | - Reading and writing data - Working with Semi-structured data - Establishing connections and session management - DataFrame creation and manipulation - User-Defined Functions (UDFs) and Stored Procedures |
| Data Transformations and DataFrame Operations | 35% | - Using built-in functions - Window functions - Persisting transformed data - Complex data pipelines - Filtering, Aggregating, and Joining DataFrames |
| Snowpark Concepts | 15% | - Transformations vs. Actions - Client-side vs. Server-side execution - Snowpark architecture and core concepts - Snowpark DataFrames and query plans - Stored procedures and conditional logic - Snowpark Sessions and connection management |
| Performance Optimization and Best Practices | 20% | - Caching strategies - Vectorized UDFs - Debugging and explain plans - Minimizing data transfer - Warehouse sizing for Snowpark - Query pushdown and optimization |
>> Valid Exam SPS-C01 Preparation <<
We can provide absolutely high quality guarantee for our SPS-C01 practice materials, for all of our SPS-C01 learning materials are finalized after being approved by industry experts. Without doubt, you will get what you expect to achieve, no matter your satisfied scores or according SPS-C01certification file. As long as you choose our SPS-C01 exam questions, you will get the most awarded.
NEW QUESTION # 157
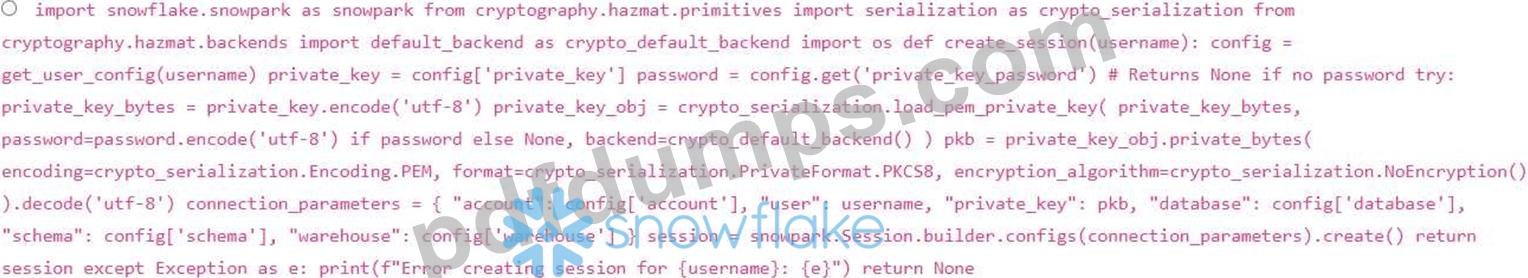
You are tasked with automating the creation of Snowpark sessions using key pair authentication for multiple users. You have a function that retrieves connection parameters (account, user, private key, etc.) for each user from a secure configuration file. The private keys are stored in PEM format. However, some users' private keys are password-protected. Which of the following approaches ensures the secure and correct establishment of Snowpark sessions for all users, including those with password-protected private keys? Assume get_user config(username)' retrieves the user's configuration, including the private key and password (if any).

Answer: C
Explanation:
Option C is the most secure and correct approach. It handles both password-protected and non-password-protected private keys gracefully using the 'cryptography' library, without storing passwords in memory or requiring users to compromise their security. It attempts to load the private key with the password (if provided), and if no password is provided, it defaults to 'None'. Options A and D have security vulnerabilities associated with storing or prompting for passwords. Option B forces users to weaken security. Option E doesn't consider password protected private keys.
NEW QUESTION # 158
You are developing a Snowpark application that needs to read data from a set of CSV files stored in a Snowflake stage named ' my_stage'. The files have a header row and are comma-delimited. You want to use the Snowpark API to create a DataFrame from these files, automatically inferring the schema. Which of the following code snippets correctly achieves this?


Answer: E
Explanation:
Option D is the correct way to read CSV files from a stage in Snowpark with header and schema inference using .format("csv").option(...y. Option A is close, but it doesn't use the correct syntax for specifying the stage location; it expects a file path relative to the current working directory.Option B incorrectly uses .csv()' with directly.Option C correctly passes options, but must use the load method in conjunction with format option. Option E has incorrect path specification in addition to incorrect function chain. Option D uses .load()" after setting the format and options is most appropriate.
NEW QUESTION # 159
You are working with a Snowpark DataFrame named containing information about products, including 'CATEGORY , 'SUBCATEGORY , and 'PRICE'. You want to determine the maximum price for each subcategory within each category. Furthermore, you need to filter the results to only include categories that have more than 5 subcategories. Which of the following Snowpark Python code snippets accomplishes this task? (Select all that apply)





Answer: B,D
Explanation:
The correct options are D and E. They both address the requirement and count distinct subcategories within each category. Option D: Correctly calculates the maximum price for each subcategory within each category. Then separately calculates the count of DISTINCT subcategories for each category. Filters the categories to include only those with more than 5 subcategories. Joins the two resulting DataFrames to provide the final output. This is a standard and explicit way to accomplish the task. Using countDistinct to ensure each subcategory is only counted once. Option E: Aggregates Max Price and CountDistinct of subcategory into same dataframe, this addresses all requirements in a more concise manner. Option A: Does not give the right result since 'count' will not give the countDistinct. Also using 'COUNT(SUBCATEGORYV in category_countS dataframe results in count of all rows in the group instead of the number of groups (number of Subcategories). Option B: Window functions is irrelevant here, and requires more coding while can be handled efficiently by aggregating and countDistinct combination Option C: Option C doesn't aggregate maximum price for each subcategory within each category as the question mentions.
NEW QUESTION # 160
A data engineering team wants to create a Snowpark stored procedure that takes a VARIANT column from a Snowflake table, parses a specific JSON element within each row, and returns a new DataFrame with the extracted data as a STRING column. The JSON structure is consistent across all rows. What is the MOST efficient and type-safe way to implement this, considering the need for performance and maintainability?
Answer: D
Explanation:
The most efficient and type-safe approach is Option E. Using 'get' function on the VARIANT column to extract the JSON element, use the 'as_varchar' function to cast the VARIANT value to a String value, and register the stored procedure with explicit 'return_type' and schema definition for enhanced type safety. Snowpark's 'get' function provides optimized JSON parsing capabilities. Explicit casting using 'as_varchar' ensures that the extracted data is properly converted to a string. Registering the stored procedure with and a schema definition enforces data type safety at the interface level, preventing potential runtime errors and improving maintainability. Options A and D are less efficient or may lead to runtime errors. Option B is less explicit and more error prone.
NEW QUESTION # 161
You are developing a Snowpark Python application that needs to process large datasets. You want to optimize performance by leveraging user-defined functions (UDFs) to perform complex calculations in parallel across the Snowflake data warehouse. Which of the following statements regarding Snowpark UDFs are TRUE?
Answer: D,E
Explanation:
Snowpark UDFs can be either scalar or vectorized, offering different performance tradeoffs. Vectorized UDFs are generally more efficient for large datasets as they process batches of rows. Snowpark UDFs do distribute the data and computation across multiple nodes automatically; however, the distribution strategy, while not directly controlled, is influenced by how the UDF is applied to the data and the inherent distribution of the underlying data itself. Python is the primary UDF language. Option A is false because UDFs are designed for parallel processing. Option C is not always true; custom channels might be necessary for specific dependencies. Option E is partially correct in the older releases but Python is used primarily now.
NEW QUESTION # 162
......
Our SPS-C01 study guide has three formats which can meet your different needs: PDF, software and online. If you choose the PDF version, you can download our study material and print it for studying everywhere. With our software version of SPS-C01 exam material, you can practice in an environment just like the real examination. And you will certainly be satisfied with our online version of our SPS-C01 training quiz. It is more convenient for you to study and practice anytime, anywhere.
Valid Braindumps SPS-C01 Ebook: https://www.pdfdumps.com/SPS-C01-valid-exam.html
BONUS!!! Download part of PDFDumps SPS-C01 dumps for free: https://drive.google.com/open?id=1rnJcnY0B-nd2eOAtlZY8VJMaQTyk0nys