What's more, part of that FreeDumps DP-800 dumps now are free: https://drive.google.com/open?id=1dg3t9OcdNfu2SmbWIUj1VznWy7cAndx9
As the tech industry continues to evolve and adapt to new technologies, professionals who hold the Developing AI-Enabled Database Solutions (DP-800) certification are better equipped to navigate these changes and stay ahead of the curve, increasing their value to employers and clients. In today's fast-paced and ever-changing Microsoft sector, having the Microsoft DP-800 Certification has become a necessary requirement for individuals looking to advance their careers and stay competitive in the job market.
| Section | Objectives |
|---|---|
| Integrate AI capabilities with database systems | - Implement AI-assisted data processing - Use Azure AI services with database workloads |
| Monitor, troubleshoot, and maintain solutions | - Monitoring database health and performance - Troubleshooting data pipeline issues |
| Develop and manage database solutions | - Ensure security and compliance of data solutions - Optimize performance and scalability |
| Design and implement data solutions | - Implement data storage and data processing solutions - Design database solutions using Azure data services |
>> Latest DP-800 Learning Materials <<
For any candidate, choosing the DP-800 question torrent material is the key to passing the exam. Our study materials can fully meet all your needs: Avoid wasting your time and improve your learning efficiency. Spending little hours per day within one week, you can pass the exam easily. You will don't take any risks and losses if you purchase and learn our DP-800 Latest Exam Dumps, do you?
NEW QUESTION # 82
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders, dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.orders.
Solution; Identify the partition scheme (or the oldest month, and then run the following Transact-SQL statement.
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME (partition_scheme_name);
Does this meet the goal?
Answer: B
Explanation:
This also does not meet the goal. DROP PARTITION SCHEME removes the partition scheme object from the database; it is not the command used to remove just the rows for the oldest month from a partitioned table.
Microsoft's DROP PARTITION SCHEME documentation is explicit that the statement removes the partition scheme itself.
For removing only the oldest month's rows with minimal impact, Microsoft points to partition-level maintenance operations such as truncating a single partition on a partitioned table. That targets only the needed data subset and is more efficient for retention workloads.
NEW QUESTION # 83
You are developing an Azure SQL database solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
You need to ensure that GitHub Copilot Chat can call the hosted GitHub MCP Server tools by using OAuth.
The MCP server configuration must be scoped to the repository.
What should you do in Visual Studio Code?
Answer: C
NEW QUESTION # 84
You have a Microsoft SQL Server 2025 database that contains a table named products. products contains two columns named description and embedding. embedding is generated from description.
You have an application named App1. App1 has a feature that uses the following query.
VECTOR_DISTANCE('cosine', @query_vector, embedding)
Users report that the feature is slow during peak usage times.
You discover that during peak usage times, the semantic search latency increases and CPU utilization spikes.
You need to reduce latency and CPU utilization related to the App1 feature.
What should you do?
Answer: D
Explanation:
The correct answer is C because the current query uses VECTOR_DISTANCE( ' cosine ' , @query_vector, embedding) , which performs an exact vector distance calculation . Microsoft explicitly documents that VECTOR_DISTANCE does not use a vector index , even when one exists. Exact k-nearest-neighbor searches can require scanning large numbers of vectors and calculating distances row by row, which explains the observed CPU spikes and increased semantic-search latency during peak load.
A vector index on products.embedding is specifically designed to accelerate nearest-neighbor search, and VECTOR_SEARCH is the Transact-SQL function that can use that approximate nearest-neighbor index when the index metric matches the query metric. Using METRIC = ' cosine ' preserves the same similarity metric currently used by App1 while reducing the amount of computation required.
The other choices are incorrect:
* A normalizes vectors but does not replace the expensive exact search with indexed ANN retrieval.
* B replaces semantic vector search with lexical full-text search and changes the feature's behavior.
* D a standard nonclustered B-tree index cannot accelerate vector-distance operations.
* E converting embeddings to VARBINARY(8000) removes native vector semantics and does not solve the performance problem.
Therefore, the exam-aligned solution is create a vector index and use VECTOR_SEARCH with cosine distance .
NEW QUESTION # 85
You have an Azure SQL database that contains a table named knowledgebase, knowledgebase stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_pnofiles and benefits_enrollnent that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.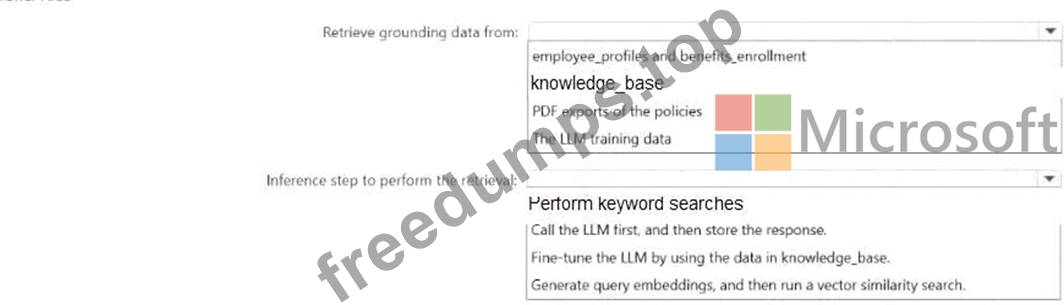
Answer:
Explanation: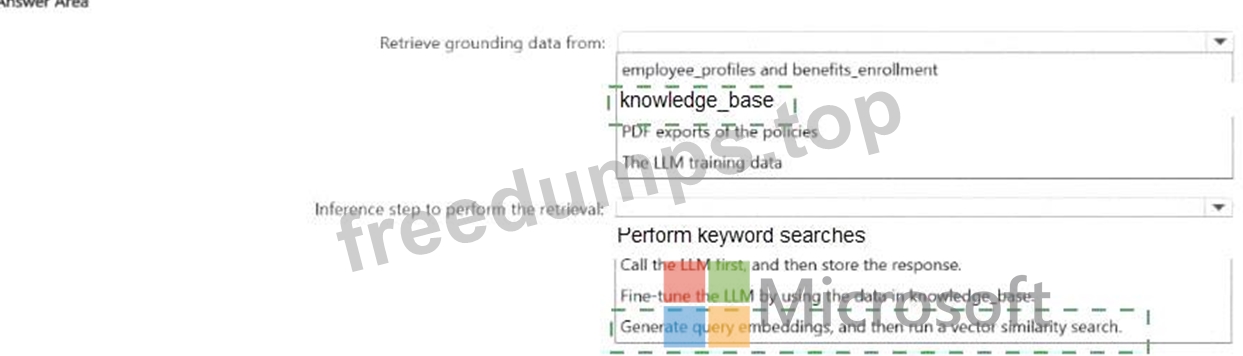
Explanation: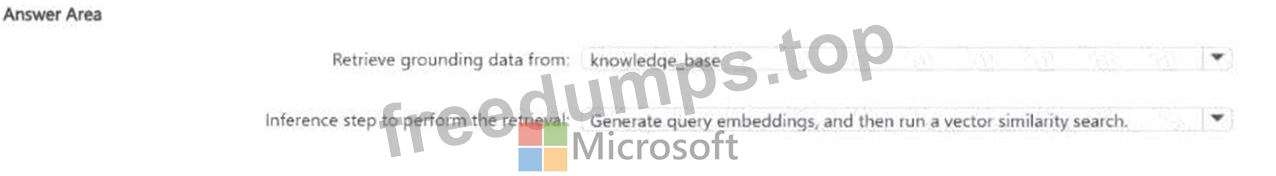
The correct recommendation is to retrieve grounding data from knowledge_base and, at inference time, generate query embeddings and run a vector similarity search .
The chatbot currently answers some general HR questions but fails when policies change and when users ask about internal policy documents by title or category . That is exactly the kind of problem RAG is meant to solve: ground the LLM in the organization's proprietary content instead of relying on the model's training data or unrelated transactional tables. Microsoft's RAG guidance states that RAG extends LLMs by grounding responses in your own content and that, for agentic retrieval, knowledge bases unify knowledge sources for retrieval.
So the grounding data should come from knowledge_base , because that table stores the HR policy documents and already includes fields like title, content, category, and embedding. Those are the fields directly tied to the missing and outdated policy answers. By contrast:
* employee_profiles and benefits_enrollment are operational HR tables, not the authoritative store for policy-document grounding.
* PDF exports of the policies would be inferior to querying the indexed/structured knowledge base already prepared for retrieval.
* The LLM training data is specifically the wrong source when the issue is outdated internal content.
For the retrieval step, Microsoft's guidance says to use embeddings for vector queries and notes that vector similarity search matches concepts, not exact terms . This is especially important because users ask about policy documents by title or category and also phrase questions in ways that might not exactly match document wording. Generating a query embedding and then running a vector similarity search is the appropriate retrieval step in a RAG pipeline.
NEW QUESTION # 86
Drag and Drop Question
You have an Azure SQL database that stores sales data and contains tables named Sales and Products. Sales contains three columns named SalesDate, ProductKey, and TotalSale, Sales is 10 TB and is loaded nightly by using a batch process. Most reporting queries scan large portions of Sales, filter on SalesDate or ProductKey, and use SUM() to aggregate TotalSale.
Products is relatively small and is used primarily for point lookups and joins to Sales.
You need to recommend which indexes to create to optimize the reporting queries. The solution must minimize storage requirements.
Which type of index should you recommend for each table? To answer, drag the appropriate index types to the correct tables. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.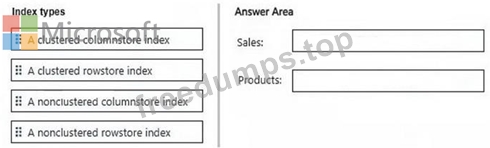
Answer:
Explanation: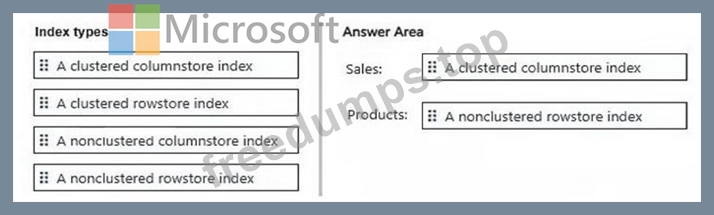
NEW QUESTION # 87
......
FreeDumps Microsoft DP-800 practice exam is the most thorough, most accurate and latest practice test. You will find that it is the only materials which can make you have confidence to overcome difficulties in the first. Microsoft DP-800 exam certification are recognized in any country in the world and all countries will be treate it equally. Microsoft DP-800 Certification not only helps to improve your knowledge and skills, but also helps your career have more possibility.
DP-800 Reliable Test Dumps: https://www.freedumps.top/DP-800-real-exam.html
P.S. Free & New DP-800 dumps are available on Google Drive shared by FreeDumps: https://drive.google.com/open?id=1dg3t9OcdNfu2SmbWIUj1VznWy7cAndx9