Exam Databricks-Certified-Professional-Data-Engineer Experience & Brain Databricks-Certified-Professional-Data-Engineer Exam

You have the option to change the topic and set the time according to the actual Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam. The Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice questions give you a feeling of a real exam which boost confidence. Practice under real Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam situations is an excellent way to learn more about the complexity of the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam dumps. You can learn from your Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice test mistakes and overcome them before the actual Databricks-Certified-Professional-Data-Engineer exam.
Databricks Databricks-Certified-Professional-Data-Engineer Exam Overview:
>> Exam Databricks-Certified-Professional-Data-Engineer Experience <<
Brain Databricks-Certified-Professional-Data-Engineer Exam | Free Databricks-Certified-Professional-Data-Engineer Test Questions
We believe that the best brands are those that go beyond expectations. They don't just do the job – they go deeper and become the fabric of our lives. Therefore, as the famous brand, even though we have been very successful we have never satisfied with the status quo, and always be willing to constantly update the contents of our Databricks-Certified-Professional-Data-Engineer exam torrent. Most important of all, as long as we have compiled a new version of the Databricks-Certified-Professional-Data-Engineer Guide Torrent, we will send the latest version of our Databricks-Certified-Professional-Data-Engineer training materials to our customers for free during the whole year after purchasing. We will continue to bring you integrated Databricks-Certified-Professional-Data-Engineer guide torrent to the demanding of the ever-renewing exam, which will be of great significance for you to keep pace with the times.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) exam is a certification program designed to validate the skills and expertise of data engineers in developing and managing big data pipelines using Databricks. Databricks-Certified-Professional-Data-Engineer Exam is ideal for data engineers, ETL developers, and data architects who work with Databricks and want to showcase their skills and proficiency.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q90-Q95):
NEW QUESTION # 90
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays:
Which limitation will the team face while diagnosing this problem?
- A. Updating the table schema will invalidate the Delta transaction log metadata.
- B. Spark cannot capture the topic partition fields from the kafka source.
- C. Updating the table schema requires a default value provided for each file added.
- D. New fields not be computed for historic records.
Answer: D
Explanation:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
Reference:
Databricks documentation on Delta Lake schema management: https://docs.databricks.com/delta/delta-batch.html#schema-management
NEW QUESTION # 91
You are working to set up two notebooks to run on a schedule, the second notebook is dependent on the first notebook but both notebooks need different types of compute to run in an optimal fashion, what is the best way to set up these notebooks as jobs?
- A. Each task can use different cluster, add these two notebooks as two tasks in a single job with linear dependency and modify the cluster as needed for each of the tasks
- B. Use a very large cluster to run both the tasks in a single job
- C. Use DELTA LIVE PIPELINES instead of notebook tasks
- D. A Job can only use single cluster, setup job for each notebook and use job dependency to link both jobs together
- E. Use a single job to setup both notebooks as individual tasks, but use the cluster API to setup the second cluster before the start of second task
Answer: A
Explanation:
Explanation
Tasks in Jobs support different clusters for each task in the same job.
NEW QUESTION # 92
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone.
A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
- A. Running vacuum automatically invalidates any shallow clones of a table; deep clone should always be used when a cloned table will be repeatedly queried.
- B. Because Type 1 changes overwrite existing records, Delta Lake cannot guarantee data consistency for cloned tables.
- C. The data files compacted by vacuum are not tracked by the cloned metadata; running refresh on the cloned table will pull in recent changes.
- D. The metadata created by the clone operation is referencing data files that were purged as invalid by the vacuum command
Answer: D
Explanation:
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.References:
Databricks documentation on Delta Lake, particularly the sections on cloning tables (shallow and deep cloning) and data retention with the vacuum command (https://docs.databricks.com/delta/index.html).
NEW QUESTION # 93
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
- B. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- C. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- D. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
- E. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
Answer: C
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html
NEW QUESTION # 94
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table:
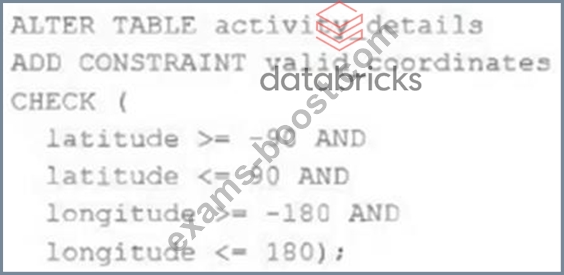
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
- A. The activity details table already exists; CHECK constraints can only be added during initial table creation.
- B. Because another team uses this table to support a frequently running application, two-phase locking is preventing the operation from committing.
- C. The current table schema does not contain the field valid coordinates; schema evolution will need to be enabled before altering the table to add a constraint.
- D. The activity details table already contains records that violate the constraints; all existing data must pass CHECK constraints in order to add them to an existing table.
- E. The activity details table already contains records; CHECK constraints can only be added prior to inserting values into a table.
Answer: D
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and 180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation , under "Add a CHECK constraint to an existing table" section.
https://docs.databricks.com/en/sql/language-manual/sql-ref-syntax-ddl-alter-table.html#add-constraint
NEW QUESTION # 95
......
Brain Databricks-Certified-Professional-Data-Engineer Exam: https://www.exams-boost.com/Databricks-Certified-Professional-Data-Engineer-valid-materials.html
- 2026 Exam Databricks-Certified-Professional-Data-Engineer Experience | Reliable Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam 100% Pass ⛰ Search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ and easily obtain a free download on ⇛ www.pdfdumps.com ⇚ 🥵Databricks-Certified-Professional-Data-Engineer Latest Test Sample
- Reliable Databricks Databricks-Certified-Professional-Data-Engineer Online Practice Test Engine 🐁 The page for free download of ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ on ⇛ www.pdfvce.com ⇚ will open immediately ✊Databricks-Certified-Professional-Data-Engineer Authentic Exam Questions
- Pass-Sure Exam Databricks-Certified-Professional-Data-Engineer Experience - Leading Offer in Qualification Exams - 100% Pass-Rate Brain Databricks-Certified-Professional-Data-Engineer Exam 🧶 Search on { www.practicevce.com } for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to obtain exam materials for free download 🩲Databricks-Certified-Professional-Data-Engineer Current Exam Content
- Reliable Databricks-Certified-Professional-Data-Engineer Test Online 💬 Databricks-Certified-Professional-Data-Engineer Training Online 🪁 Latest Databricks-Certified-Professional-Data-Engineer Real Test 🔝 Easily obtain free download of 「 Databricks-Certified-Professional-Data-Engineer 」 by searching on 「 www.pdfvce.com 」 🥍Free Databricks-Certified-Professional-Data-Engineer Download
- Free Databricks-Certified-Professional-Data-Engineer Download 🛫 Databricks-Certified-Professional-Data-Engineer Exam 🛹 Databricks-Certified-Professional-Data-Engineer Test Discount Voucher 🥯 Simply search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ for free download on 「 www.practicevce.com 」 ✍Databricks-Certified-Professional-Data-Engineer Latest Test Sample
- Databricks-Certified-Professional-Data-Engineer Test Discount Voucher ☣ Databricks-Certified-Professional-Data-Engineer Latest Test Sample 🕡 Databricks-Certified-Professional-Data-Engineer Test Discount Voucher ⏭ Download ➤ Databricks-Certified-Professional-Data-Engineer ⮘ for free by simply searching on ✔ www.pdfvce.com ️✔️ 🔦Databricks-Certified-Professional-Data-Engineer Latest Test Sample
- Reliable Databricks-Certified-Professional-Data-Engineer Test Online 😡 Reliable Databricks-Certified-Professional-Data-Engineer Test Online ✳ Reliable Databricks-Certified-Professional-Data-Engineer Test Online 🍛 Search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 and obtain a free download on ⮆ www.exam4labs.com ⮄ 📧Valid Databricks-Certified-Professional-Data-Engineer Test Cost
- Exam Databricks-Certified-Professional-Data-Engineer Experience Pass Certify | Reliable Brain Databricks-Certified-Professional-Data-Engineer Exam: Databricks Certified Professional Data Engineer Exam 🎊 Open ➥ www.pdfvce.com 🡄 and search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ to download exam materials for free 🤒Pass Databricks-Certified-Professional-Data-Engineer Test Guide
- Databricks-Certified-Professional-Data-Engineer Exam Questions And Answers 🙀 Valid Exam Databricks-Certified-Professional-Data-Engineer Vce Free ⚒ Databricks-Certified-Professional-Data-Engineer Latest Test Sample 🏁 Open ➥ www.troytecdumps.com 🡄 enter ➽ Databricks-Certified-Professional-Data-Engineer 🢪 and obtain a free download 🍻Reliable Databricks-Certified-Professional-Data-Engineer Test Online
- Reliable Databricks Databricks-Certified-Professional-Data-Engineer Online Practice Test Engine 🔂 Copy URL ➡ www.pdfvce.com ️⬅️ open and search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ to download for free 🕤Latest Databricks-Certified-Professional-Data-Engineer Real Test
- Instant Databricks-Certified-Professional-Data-Engineer Discount 📿 Databricks-Certified-Professional-Data-Engineer Authentic Exam Questions 🙁 Databricks-Certified-Professional-Data-Engineer Latest Dumps 🦏 Search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 and download exam materials for free through [ www.troytecdumps.com ] ➡Databricks-Certified-Professional-Data-Engineer Latest Test Sample
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes