DOWNLOAD the newest ExamPrepAway DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1eds1RNQxduZq3-nM-YBkJi1f7YnQEtbU
The study material is available in three easy-to-access formats. The first one is PDF format which is printable and portable. You can access it anywhere with your smart devices like smartphones, tablets, and laptops. In addition, you can even print PDF questions in order to study anywhere and pass Implementing Analytics Solutions Using Microsoft Fabric (DP-600) certification exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Latest DP-600 Guide Files <<
The actual Microsoft DP-600 exam questions are in PDF format for the one who wants to study offline. The actual Microsoft DP-600 exam questions are in simple PDF form. The PDF format is suitable both for smartphones as well as tablets. You can print documents and study anywhere. The plus point is that the PDF version is updated regularly to improve its DP-600 Exam Questions and reflect changes in the syllabus of the exam.
NEW QUESTION # 99
You have a Fabric tenant that contains a warehouse.
A user discovers that a report that usually takes two minutes to render has been running for 45 minutes and has still not rendered.
You need to identify what is preventing the report query from completing.
Which dynamic management view (DMV) should you use?
Answer: B
Explanation:
The correct DMV to identify what is preventing the report query from completing is sys.dm_pdw_exec_requests (D). This DMV is specific to Microsoft Analytics Platform System (previously known as SQL Data Warehouse), which is the environment assumed to be used here. It provides information about all queries and load commands currently running or that have recently run. References = You can find more about DMVs in the Microsoft documentation for Analytics Platform System.
NEW QUESTION # 100
You have Fabric tenant that contains four workspaces named Development, Test, QA, and Production. All the workspaces are in Premium Per User (PPU) license mode.
You plan to use a release pipeline to support the development lifecycle from Development to Production.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.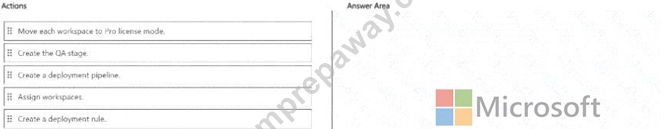
Answer:
Explanation: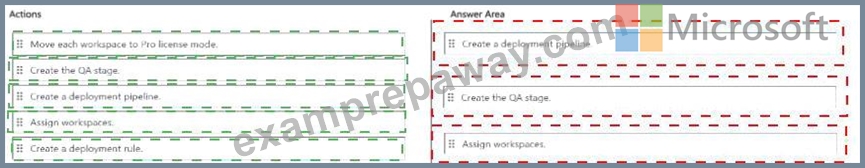
Explanation:
Scenario Recap
Fabric tenant with workspaces: Development, Test, QA, Production.
All workspaces are already in Premium Per User (PPU) mode (which is required for deployment pipelines).
Task: Set up a release pipeline to move through Dev # Test # QA # Production.
Step 1: Create a deployment pipeline
The first step is always to create a new deployment pipeline in the Fabric/Power BI service. This establishes the structure for Dev # Test # Prod (and optionally QA).
Step 2: Create the QA stage
By default, pipelines have 3 stages (Dev, Test, Prod).
Since we need a QA stage in addition, we must explicitly add it as a stage to the pipeline.
Step 3: Assign workspaces
Once the pipeline structure is ready (with QA included), we assign each workspace to the corresponding stage:
Development # Development
Test # Test
QA # QA
Production # Production
Why Not the Other Actions?
Move each workspace to Pro license mode # Incorrect, because deployment pipelines require Premium capacity or PPU, and the workspaces already are in PPU mode.
Create a deployment rule # Deployment rules (e.g., parameter or data source rules) are optional for environment-specific changes, but not part of the initial required setup sequence.
References
Deployment pipelines overview
Assigning workspaces to deployment pipelines
NEW QUESTION # 101
You have a Fabric warehouse named Warehouse1 that contains a table named dbo.Product. dbo.Product contains the following columns.
You need to use a T-SQL query to add a column named PriceRange to dbo.Product. The column must categorize each product based on UnitPrice. The solution must meet the following requirements:
* If UnitPrice is 0, PriceRange is " Not for resale " .
* If UnitPrice is less than 50, PriceRange is " Under $50 " .
* If UnitPrice is between 50 and 250, PriceRange is " Under $250 " .
* In all other instances, PriceRange is " $250+ " .
How should you complete the query? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.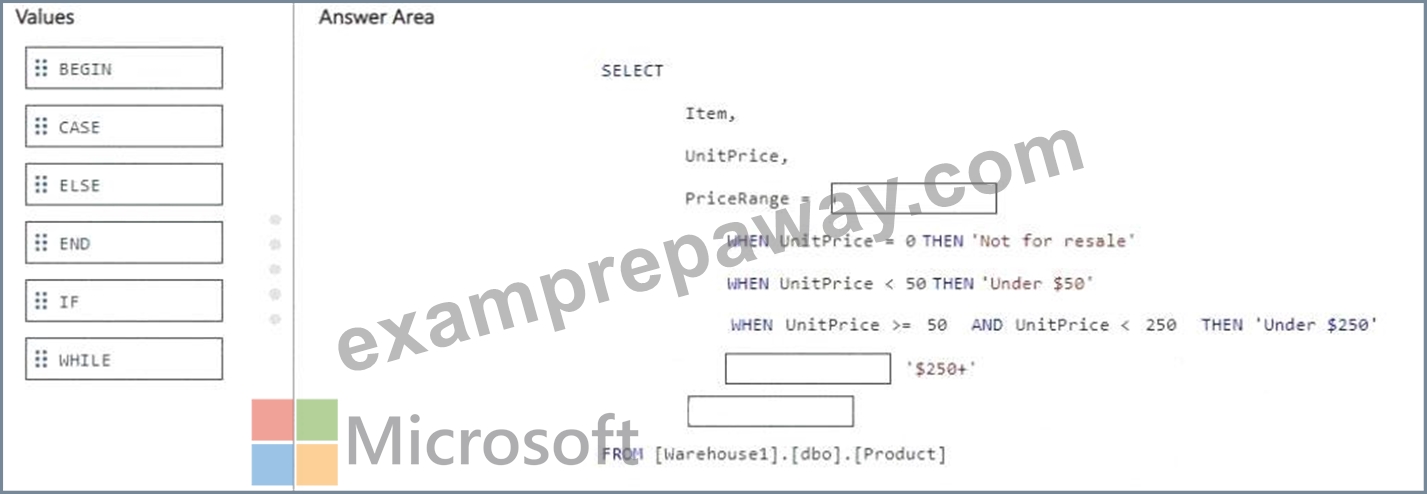
Answer:
Explanation:
Explanation:
Comprehensive Detailed Explanation
We need to create a computed column PriceRange based on the UnitPrice column in the dbo.Product table.
Step 1: Requirements
If UnitPrice = 0 # " Not for resale "
If UnitPrice < 50 # " Under $50 "
If UnitPrice > = 50 AND UnitPrice < 250 # " Under $250 "
Otherwise # " $250+ "
This matches a CASE expression in T-SQL.
Step 2: CASE Expression Structure
The syntax is:
CASE
WHEN condition THEN result
WHEN condition THEN result
ELSE result
END
Step 3: Apply to Problem
SELECT
Item,
UnitPrice,
PriceRange = CASE
WHEN UnitPrice = 0 THEN ' Not for resale '
WHEN UnitPrice < 50 THEN ' Under $50 '
WHEN UnitPrice > = 50 AND UnitPrice < 250 THEN ' Under $250 '
ELSE ' $250+ '
END
FROM [Warehouse1].[dbo] .[Product];
Step 4: Why This is Correct
CASE starts the conditional evaluation.
ELSE handles the default branch ($250+).
END closes the expression.
Meets all requirements exactly.
References
CASE expression in T-SQL
Computed columns in T-SQL
NEW QUESTION # 102
What should you recommend using to ingest the customer data into the data store in the AnatyticsPOC workspace?
Answer: D
Explanation:
For ingesting customer data into the data store in the AnalyticsPOC workspace, a dataflow (D) should be recommended. Dataflows are designed within the Power BI service to ingest, cleanse, transform, and load data into the Power BI environment. They allow for the low-code ingestion and transformation of data as needed by Litware's technical requirements. Reference = You can learn more about dataflows and their use in Power BI environments in Microsoft's Power BI documentation.
Topic 1, Litware. Inc.
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.
The Product data contains a single table and the following columns.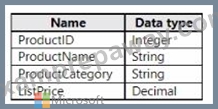
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
NEW QUESTION # 103
You need to migrate the Research division data for Productline2. The solution must meet the data preparation requirements. How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation: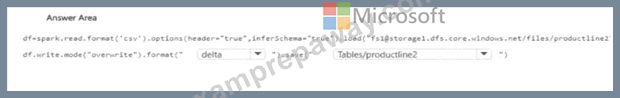
Comprehensive Detailed Explanation
From the case study:
Research division data for Productline2 is currently in CSV format in storage2.
Requirement: "All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer." In Fabric lakehouses, managed tables are stored in Delta format inside the Tables folder.
Step 1: Reading the source
df = spark.read. format ( " csv " ) \
options(header= " true " , inferSchema= " true " ) \
load( " abfss://storage1.dfs.core.windows.net/files/productline2 " )
This correctly ingests the CSV source from ADLS Gen2.
Step 2: Writing to Lakehouse as a managed table
You must write the data in Delta format to ensure it is queryable and managed within the lakehouse.
The correct path is under Tables/ , because this is where Fabric automatically manages Lakehouse managed tables .
The target table should be named productline2 , so the correct path is:
df.write.mode( " overwrite " ). format ( " delta " ).save( " Tables/productline2 " ) Why not other options?
CSV or Parquet formats would not create a managed Lakehouse table; they would just create files.
Writing to productline2 directly (without Tables/ ) would store unmanaged files in the Lakehouse Files area, not managed tables.
Writing to Tables/research/productline2 adds an unnecessary subdirectory and is not the standard structure for managed tables.
Correct Final Code
df.write.mode( " overwrite " ). format ( " delta " ).save( " Tables/productline2 " ) References Managed tables in Microsoft Fabric Lakehouse Delta Lake support in Fabric Spark write to Lakehouse
NEW QUESTION # 104
......
This is a good way to purchase valid exam preparation materials for your coming DP-600 test. Good choice will make you get double results with half efforts. Good exam preparation will point you a clear direction and help you prepare efficiently. Our DP-600 exam preparation can not only give a right direction but also cover most of the real test questions so that you can know the content of exam in advance. You can master the questions and answers of Microsoft DP-600 Exam Preparation, even adjust your exam mood actively.
New Study DP-600 Questions: https://www.examprepaway.com/Microsoft/braindumps.DP-600.ete.file.html
BONUS!!! Download part of ExamPrepAway DP-600 dumps for free: https://drive.google.com/open?id=1eds1RNQxduZq3-nM-YBkJi1f7YnQEtbU