BONUS!!! Download part of Exam4PDF Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1E0uy4q6a0J_1vERp3BYH-rAzAqGbOPAz
As we all know, passing the exam is a wish for all candidates. Data-Engineer-Associate exam torrent can help you pass the exam and obtain the certificate successfully. With skilled experts to edit and verify, Data-Engineer-Associate study materials can meet the needs for exam. In addition, you can get downloading link and password within ten minutes after payment, and you can start your practicing right now. We have online and offline chat service stuff, they possess professional knowledge for Data-Engineer-Associate Training Materials, if you have any questions, just contact us.
| Section | Weight | Objectives |
|---|---|---|
| Data Store Management | 26% | - Manage data lifecycle
|
| Data Ingestion and Transformation | 34% | - Orchestrate data pipelines
|
| Data Security and Governance | 18% | - Manage data privacy and compliance
|
| Data Operations and Support | 22% | - Manage and troubleshoot data processes
|
>> Latest Data-Engineer-Associate Exam Format <<
Exam4PDF is a website for Amazon Certification Data-Engineer-Associate Exam to provide a short-term effective training. Amazon Data-Engineer-Associate is a certification exam which is able to change your life. IT professionals who gain Amazon Data-Engineer-Associate authentication certificate must have a higher salary than the ones who do not have the certificate and their position rising space is also very big, who will have a widely career development prospects in the IT industry in.
NEW QUESTION # 86
A company uses AWS Step Functions to orchestrate a data pipeline. The pipeline consists of Amazon EMR jobs that ingest data from data sources and store the data in an Amazon S3 bucket. The pipeline also includes EMR jobs that load the data to Amazon Redshift.
The company's cloud infrastructure team manually built a Step Functions state machine. The cloud infrastructure team launched an EMR cluster into a VPC to support the EMR jobs. However, the deployed Step Functions state machine is not able to run the EMR jobs.
Which combination of steps should the company take to identify the reason the Step Functions state machine is not able to run the EMR jobs? (Choose two.)
Answer: B,E
Explanation:
To identify the reason why the Step Functions state machine is not able to run the EMR jobs, the company should take the following steps:
Verify that the Step Functions state machine code has all IAM permissions that are necessary to create and run the EMR jobs. The state machine code should have an IAM role that allows it to invoke the EMR APIs, such as RunJobFlow, AddJobFlowSteps, and DescribeStep. The state machine code should also have IAM permissions to access the Amazon S3 buckets that the EMR jobs use as input and output locations. The company can use Access Analyzer for S3 to check the access policies and permissions of the S3 buckets12. Therefore, option B is correct.
Query the flow logs for the VPC. The flow logs can provide information about the network traffic to and from the EMR cluster that is launched in the VPC. The company can use the flow logs to determine whether the traffic that originates from the EMR cluster can successfully reach the data providers, such as Amazon RDS, Amazon Redshift, or other external sources. The company can also determine whether any security group that might be attached to the EMR cluster allows connections to the data source servers on the informed ports. The company can use Amazon VPC Flow Logs or Amazon CloudWatch Logs Insights to query the flow logs3 . Therefore, option D is correct.
Option A is incorrect because it suggests using AWS CloudFormation to automate the Step Functions state machine deployment. While this is a good practice to ensure consistency and repeatability of the deployment, it does not help to identify the reasonwhy the state machine is not able to run the EMR jobs. Moreover, creating a step to pause the state machine during the EMR jobs that fail and wait for a human user to send approval through an email message is not a reliable way to troubleshoot the issue. The company should use the Step Functions console or API to monitor the execution history and status of the state machine, and use Amazon CloudWatch to view the logs and metrics of the EMR jobs .
Option C is incorrect because it suggests changing the AWS Step Functions state machine code to use Amazon EMR on EKS. Amazon EMR on EKS is a service that allows you to run EMR jobs on Amazon Elastic Kubernetes Service (Amazon EKS) clusters. While this service has some benefits, such as lower cost and faster execution time, it does not support all the features and integrations that EMR on EC2 does, such as EMR Notebooks, EMR Studio, and EMRFS. Therefore, changing the state machine code to use EMR on EKS may not be compatible with the existing data pipeline and may introduce new issues.
Option E is incorrect because it suggests checking the retry scenarios that the company configured for the EMR jobs. While this is a good practice to handle transient failures and errors, it does not help to identify the root cause of why the state machine is not able to run the EMR jobs. Moreover, increasing the number of seconds in the interval between each EMR task may not improve the success rate of the jobs, and may increase the execution time and cost of the state machine. Configuring an Amazon SNS topic to store the error messages may help to notify the company of any failures, but it does not provide enough information to troubleshoot the issue.
References:
1: Manage an Amazon EMR Job - AWS Step Functions
2: Access Analyzer for S3 - Amazon Simple Storage Service
3: Working with Amazon EMR and VPC Flow Logs - Amazon EMR
[4]: Analyzing VPC Flow Logs with Amazon CloudWatch Logs Insights - Amazon Virtual Private Cloud
[5]: Monitor AWS Step Functions - AWS Step Functions
[6]: Monitor Amazon EMR clusters - Amazon EMR
[7]: Amazon EMR on Amazon EKS - Amazon EMR
NEW QUESTION # 87
A company receives .csv files that contain physical address data. The data is in columns that have the following names: Door_No, Street_Name, City, and Zip_Code. The company wants to create a single column to store these values in the following format: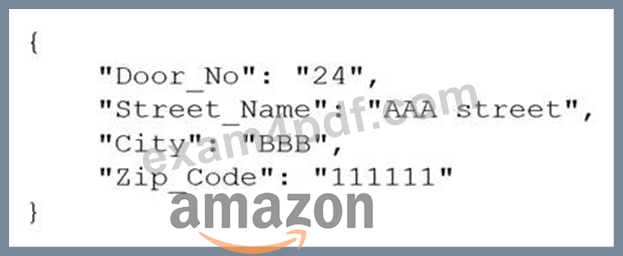
Which solution will meet this requirement with the LEAST coding effort?
Answer: D
Explanation:
The NEST TO MAP transformation allows you to combine multiple columns into a single column that contains a JSON object with key-value pairs. This is the easiest way to achieve the desired format for the physical address data, as you can simply select the columns to nest and specify the keys for each column. The NEST TO ARRAY transformation creates a single column that contains an array of values, which is not the same as the JSON object format. The PIVOT transformation reshapes the data by creating new columns from unique values in a selected column, which is not applicable for this use case. Writing a Lambda function in Python requires more coding effort than using AWS Glue DataBrew, which provides a visual and interactive interface for data transformations. References:
7 most common data preparation transformations in AWS Glue DataBrew (Section: Nesting and unnesting columns) NEST TO MAP - AWS Glue DataBrew (Section: Syntax)
NEW QUESTION # 88
A company stores its processed data in an S3 bucket. The company has a strict data access policy. The company uses IAM roles to grant teams within the company different levels of access to the S3 bucket.
The company wants to receive notifications when a user violates the data access policy. Each notification must include the username of the user who violated the policy.
Which solution will meet these requirements?
Answer: D
Explanation:
The requirement is to detect violations of data access policies and receive notifications with the username of the violator. AWS CloudTrail can provideobject-level tracking for S3to capture detailed API actions on specific S3 objects, including the user who performed the action.
* AWS CloudTrail:
* CloudTrail can monitorAPI callsmade to an S3 bucket, including object-level API actions such as GetObject, PutObject, and DeleteObject. This will help detect access violations based on the API calls made by different users.
* CloudTrail logs include details such as theuser identity, which is essential for meeting the requirement of including the username in notifications.
* The CloudTrail logs can be forwarded toAmazon CloudWatchto trigger alarms based on certain access patterns (e.g., violations of specific policies).
Reference:Monitoring Amazon S3 Activity Using AWS CloudTrail
Amazon CloudWatch:
By forwarding CloudTrail logs to CloudWatch, you can set upalarmsthat are triggered when a specific condition is met, such as unauthorized access or policy violations. The alarm can include detailed information from the CloudTrail log, including the username.
Alternatives Considered:
A (AWS Config rules): While AWS Config can track resource configurations and compliance, it does not provide real-time, detailed tracking of object-level events like CloudTrail does.
B (CloudWatch metrics): CloudWatch does not gather object-level metrics for S3 directly. For this use case, CloudTrail provides better granularity.
D (S3 server access logs): S3 server access logs can monitor access, but they do not provide the real-time monitoring and alerting features that CloudTrail with CloudWatch alarms offer. They also do not include API- level granularity like CloudTrail.
References:
AWS CloudTrail Integration with S3
Amazon CloudWatch Alarms
NEW QUESTION # 89
A retail company is using an Amazon Redshift cluster to support real-time inventory management. The company has deployed an ML model on a real-time endpoint in Amazon SageMaker.
The company wants to make real-time inventory recommendations. The company also wants to make predictions about future inventory needs.
Which solutions will meet these requirements? (Select TWO.)
Answer: D,E
Explanation:
The company needs to use machine learning models for real-time inventory recommendations and future inventory predictions while leveraging both Amazon Redshift and Amazon SageMaker.
Option A: Use Amazon Redshift ML to generate inventory recommendations.
Amazon Redshift ML allows you to build, train, and deploy machine learning models directly from Redshift using SQL statements. It integrates with SageMaker to train models and run inference. This feature is useful for generating inventory recommendations directly from the data stored in Redshift.
Option B: Use SQL to invoke a remote SageMaker endpoint for prediction.
You can use SQL in Redshift to call a SageMaker endpoint for real-time inference. By invoking a SageMaker endpoint from within Redshift, the company can get real-time predictions on inventory, allowing for integration between the data warehouse and the machine learning model hosted in SageMaker.
Option C (offline model training) and Option D (creating dashboards with SageMaker Autopilot) are not relevant to the real-time prediction and recommendation requirements.
Option E (archiving inventory reports in Redshift) is not related to making predictions or recommendations.
Reference:
Amazon Redshift ML Documentation
Invoking SageMaker Endpoints from SQL
NEW QUESTION # 90
A banking company uses an application to collect large volumes of transactional dat a. The company uses Amazon Kinesis Data Streams for real-time analytics. The company's application uses the PutRecord action to send data to Kinesis Data Streams.
A data engineer has observed network outages during certain times of day. The data engineer wants to configure exactly-once delivery for the entire processing pipeline.
Which solution will meet this requirement?
Answer: B
Explanation:
For exactly-once delivery and processing in Amazon Kinesis Data Streams, the best approach is to design the application so that it handles idempotency. By embedding a unique ID in each record, the application can identify and remove duplicate records during processing.
Exactly-Once Processing:
Kinesis Data Streams does not natively support exactly-once processing. Therefore, idempotency should be designed into the application, ensuring that each record has a unique identifier so that the same event is processed only once, even if it is ingested multiple times.
This pattern is widely used for achieving exactly-once semantics in distributed systems.
Reference:
Alternatives Considered:
B (Checkpoint configuration): While updating the checkpoint configuration can help with some aspects of duplicate processing, it is not a full solution for exactly-once delivery.
C (Design data source): Ensuring events are not ingested multiple times is ideal, but network outages can make this difficult, and it doesn't guarantee exactly-once delivery.
D (Using EMR): While using EMR with Flink or Spark could work, it introduces unnecessary complexity compared to handling idempotency at the application level.
Amazon Kinesis Best Practices for Exactly-Once Processing
Achieving Idempotency with Amazon Kinesis
NEW QUESTION # 91
......
Many people worry about buying electronic products on Internet, like our Data-Engineer-Associate preparation quiz, we must emphasize that our Data-Engineer-Associate simulating materials are absolutely safe without viruses, if there is any doubt about this after the pre-sale, we provide remote online guidance installation of our Data-Engineer-Associate Exam Practice. It is worth noticing that some people who do not use professional anti-virus software will mistakenly report the virus.
Review Data-Engineer-Associate Guide: https://www.exam4pdf.com/Data-Engineer-Associate-dumps-torrent.html
What's more, part of that Exam4PDF Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1E0uy4q6a0J_1vERp3BYH-rAzAqGbOPAz