
BTW, DOWNLOAD part of DumpsQuestion MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1bZBeu-78NSZG5ZVygmDQrmC8S1Xtwk3P
Our AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam questions are being offered in three easy-to-use and compatible formats. These AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam dumps formats offer a user-friendly interface and are compatible with all devices, operating systems, and browsers. The DumpsQuestion AWS Certified Machine Learning Engineer - Associate (MLA-C01) PDF questions file contains real and valid Amazon MLA-C01 exam questions that assist you in MLA-C01 exam dumps preparation and boost the candidate's confidence to pass the challenging AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam easily.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Amazon MLA-C01 Reliable Dumps Book <<
The DumpsQuestion are one of the high-in-demand and top-rated platforms that has been offering real, valid, and updated AWS Certified Machine Learning Engineer - Associate (MLA-C01) practice test questions for many years. Over this long time period countless candidates have got success in their dream AWS Certified Machine Learning Engineer - Associate (MLA-C01) certification exam. They all got help from AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam questions and easily crack the final Amazon MLA-C01 exam.
NEW QUESTION # 210
Case Study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
The training dataset includes categorical data and numerical data. The ML engineer must prepare the training dataset to maximize the accuracy of the model.
Which action will meet this requirement with the LEAST operational overhead?
Answer: B
NEW QUESTION # 211
A recommendation model uses ML and calls an Amazon SageMaker AI endpoint to get recommendations. An ML engineer must ensure that the model stays available during an expected increase in user traffic.
Which solution will meet these requirements?
Answer: D
Explanation:
Option A is correct because Amazon SageMaker AI supports automatic scaling for hosted models , and AWS documentation states that auto scaling dynamically adjusts the number of instances provisioned for a model in response to workload changes. When traffic increases, auto scaling brings more instances online; when traffic decreases, it removes unneeded capacity. This directly matches the requirement to keep the recommendation endpoint available during an expected increase in user traffic.
AWS also documents that SageMaker integrates with Application Auto Scaling , and you can scale SageMaker endpoint variants by using target tracking , step scaling , and scheduled scaling policies. That means the service is purpose-built for this scenario: maintaining availability and capacity as inference demand changes over time. Since the model is already being served from a SageMaker endpoint, the most direct and AWS-recommended solution is to configure endpoint auto scaling rather than redesigning the deployment.
The other options do not address the requirement as effectively. Creating a new endpoint does not automatically handle fluctuating traffic and adds unnecessary operational complexity. SageMaker Neo optimizes models for inference performance on supported hardware, but it does not provide elastic capacity management. Attaching an Auto Scaling group to a SageMaker endpoint is incorrect because SageMaker endpoints do not use EC2 Auto Scaling groups directly; scaling is handled through SageMaker's integration with Application Auto Scaling. Therefore, to maintain availability during traffic spikes, the best AWS- documented answer is A: configure auto scaling on the SageMaker AI endpoint .
NEW QUESTION # 212
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
* Embedding
* Retrieval Augmented Generation (RAG)
* Temperature
* Token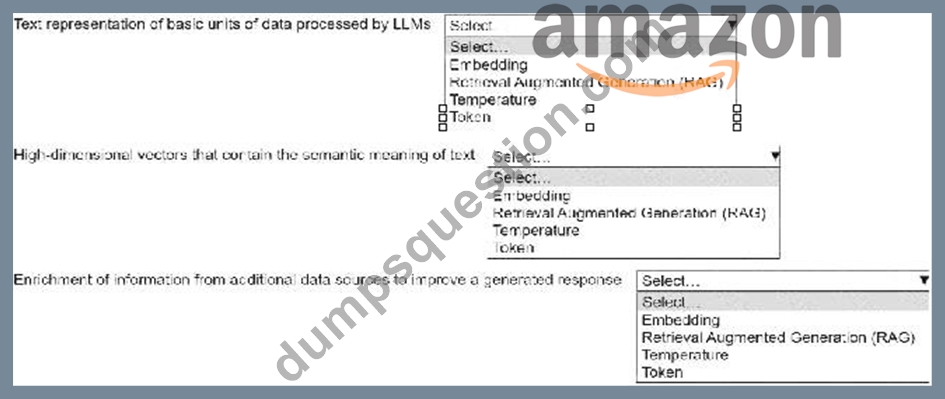
Answer:
Explanation: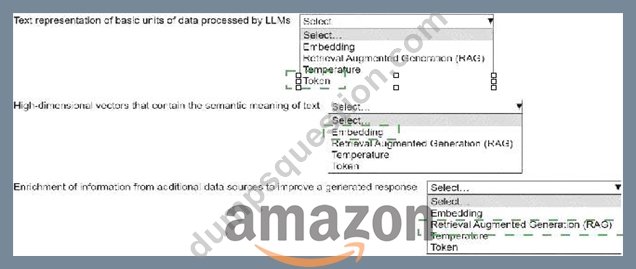
Explanation: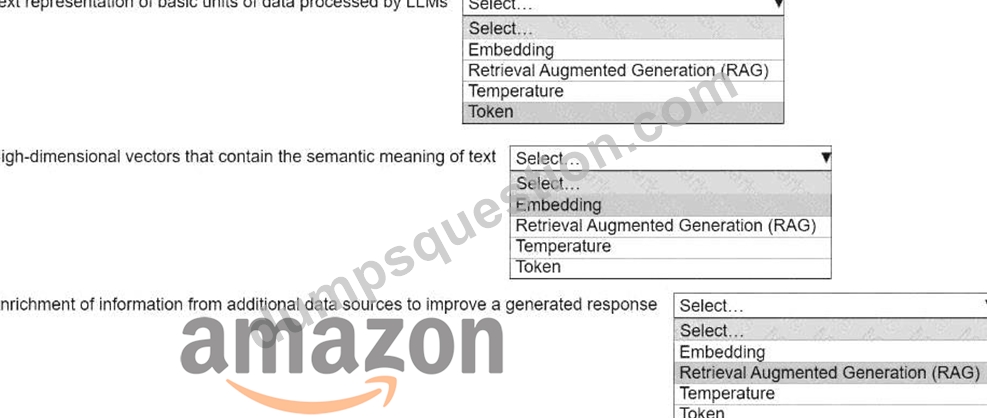
Text representation of basic units of data processed by LLMs: Token
High-dimensional vectors that contain the semantic meaning of text: Embedding Enrichment of information from additional data sources to improve a generated response: Retrieval Augmented Generation (RAG) Comprehensive Detailed Explanation Token:
Description: A token represents the smallest unit of text (e.g., a word or part of a word) that an LLM processes. For example, " running " might be split into two tokens: " run " and " ing. " Why? Tokens are the fundamental building blocks for LLM input and output processing, ensuring that the model can understand and generate text efficiently.
Embedding:
Description: High-dimensional vectors that encode the semantic meaning of text. These vectors are representations of words, sentences, or even paragraphs in a way that reflects their relationships and meaning.
Why? Embeddings are essential for enabling similarity search, clustering, or any task requiring semantic understanding. They allow the model to " understand " text contextually.
Retrieval Augmented Generation (RAG):
Description: A technique where information is enriched or retrieved from external data sources (e.g., knowledge bases or document stores) to improve the accuracy and relevance of a model ' s generated responses.
Why? RAG enhances the generative capabilities of LLMs by grounding their responses in factual and up-to- date information, reducing hallucinations in generated text.
By matching these terms to their respective descriptions, the ML engineer can effectively leverage these concepts to build robust and contextually aware generative AI applications on Amazon Bedrock.
NEW QUESTION # 213
A company uses a training job on Amazon SageMaker Al to train a neural network. The job first trains a model and then evaluates the model ' s performance ag test dataset. The company uses the results from the evaluation phase to decide if the trained model will go to production.
The training phase takes too long. The company needs solutions that can shorten training time without decreasing the model ' s final performance.
Select the correct solutions from the following list to meet the requirements for each description. Select each solution one time or not at all. (Select THREE.)
. Change the epoch count.
. Choose an Amazon EC2 Spot Fleet.
Change the batch size.
. Use early stopping on the training job.
Use the SageMaker Al distributed data parallelism (SMDDP) library.
. Stop the training job.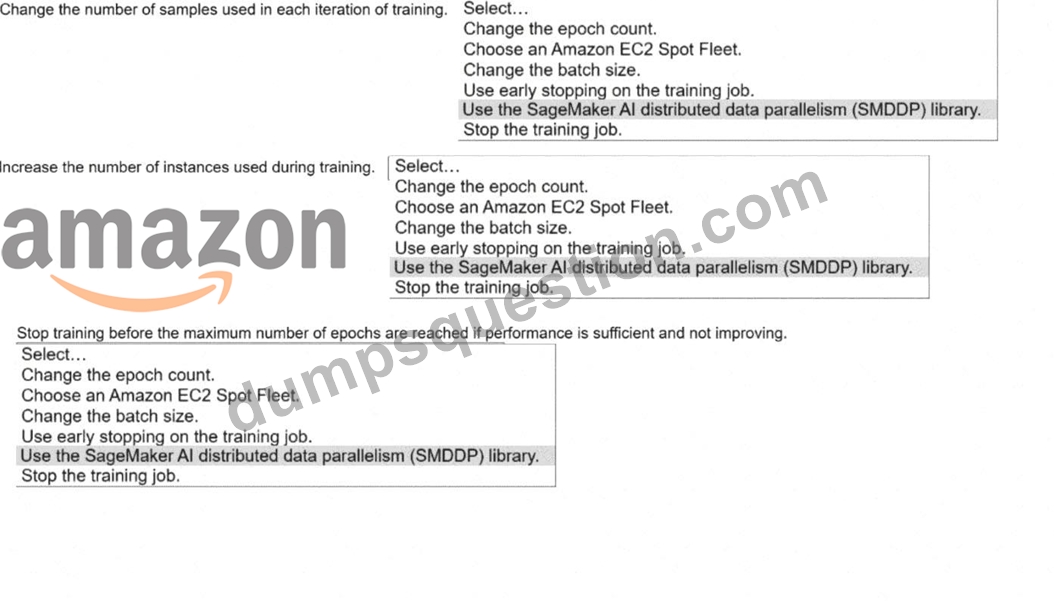
Answer:
Explanation: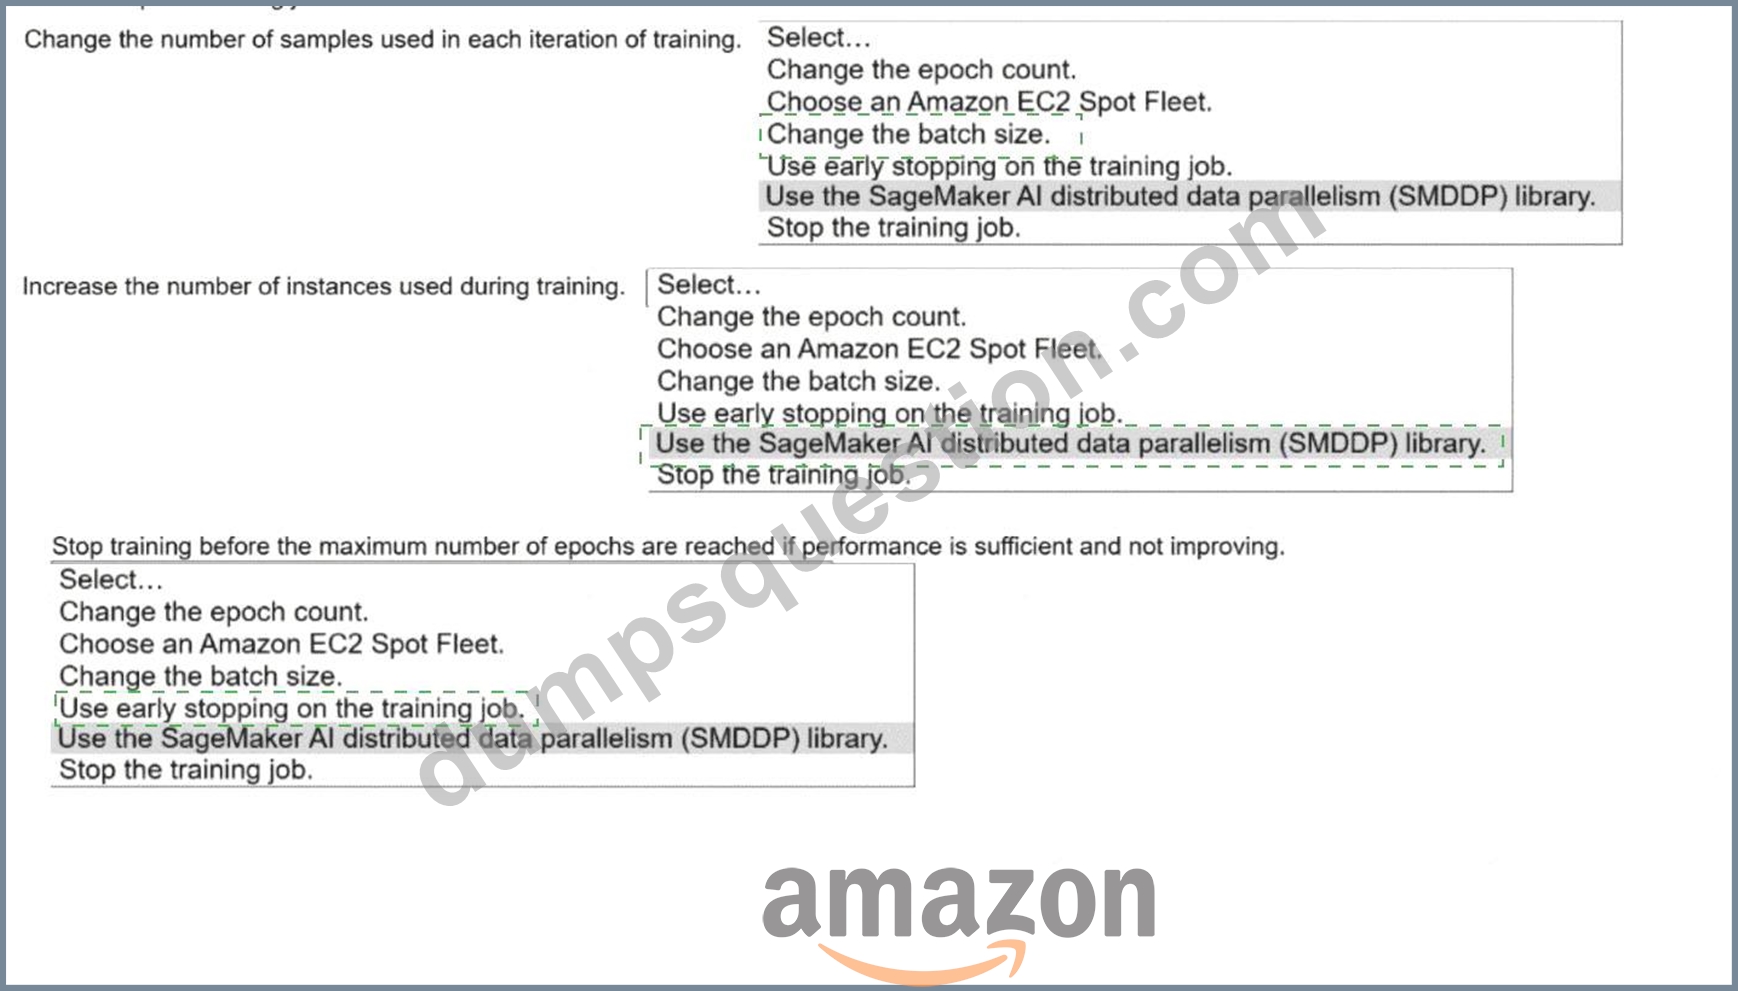
Explanation:
Change the number of samples used in each iteration of training
Correct selection:
Change the batch size
Why:
Increasing the batch size reduces the number of iterations per epoch, which can significantly shorten training time while maintaining model quality when tuned appropriately. AWS explicitly recommends batch size tuning as a primary performance optimization.
Increase the number of instances used during training
Correct selection:
Use the SageMaker AI distributed data parallelism (SMDDP) library
Why:
SMDDP is designed to efficiently distribute training data across multiple GPU instances with optimized gradient synchronization. This accelerates training without affecting model convergence or accuracy, unlike naive scaling approaches.
Stop training before the maximum number of epochs are reached if performance is sufficient and not improving Correct selection:
Use early stopping on the training job
Why:
Early stopping automatically terminates training when validation metrics stop improving. AWS recommends this to reduce wasted compute time while preserving optimal model performance.
NEW QUESTION # 214
A company uses Amazon SageMakerAI to support ML workflows such as model training and deployment.
Select the correct registry from the following list to meet the requirements for each use case with the LEAST operational overhead. Each registry should be selected one or more times. (Select FOUR.)
* Amazon Elastic Container Registry (Amazon ECR)
* SageMaker Model Registry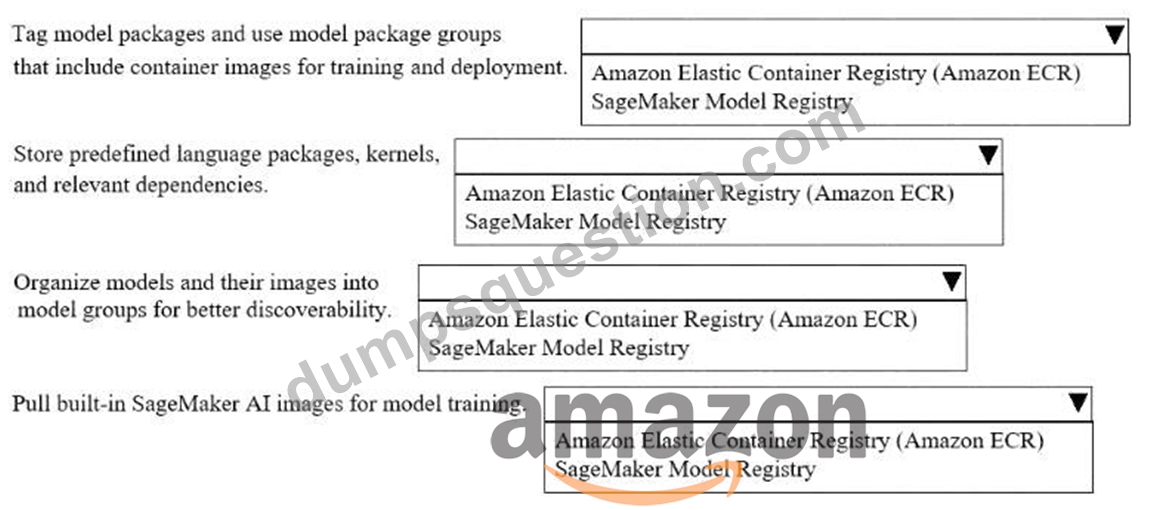
Answer:
Explanation: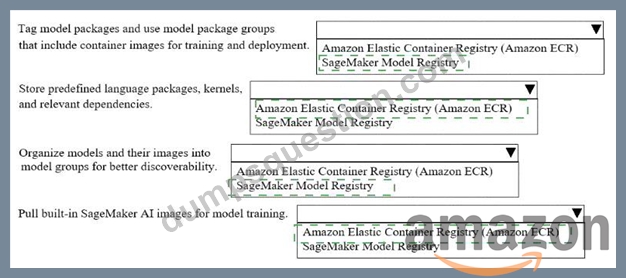
Explanation:
* Tag model packages and use model package groups that include container images for training and deployment # SageMaker Model Registry
* Store predefined language packages, kernels, and relevant dependencies # Amazon Elastic Container Registry (Amazon ECR)
* Organize models and their images into model groups for better discoverability # SageMaker Model Registry
* Pull built-in SageMaker AI images for model training # Amazon Elastic Container Registry (Amazon ECR) The correct hotspot mapping is based on the different purposes of SageMaker Model Registry and Amazon ECR .
For model packages , model package groups , and model discoverability, the correct choice is SageMaker Model Registry . AWS documentation states that a model package group is a collection of versioned model packages, and each version can contain the model artifacts, metadata, and container information used for deployment. AWS also documents that registered models can be organized into groups to support governance, discoverability, and lifecycle management. That is why both " tag model packages and use model package groups " and " organize models and their images into model groups " map to SageMaker Model Registry
.
For storing software environments and pulling training images, the correct choice is Amazon ECR . AWS documentation says SageMaker uses Docker container images , and these images contain the software stack such as frameworks, language packages, kernels, and dependencies. AWS also states that SageMaker provides prebuilt Docker images for training and inference, and these are referenced through Amazon ECR image URIs . Therefore, both " store predefined language packages, kernels, and relevant dependencies " and " pull built-in SageMaker AI images for model training " map to Amazon ECR .
NEW QUESTION # 215
......
To find the perfect MLA-C01 practice materials for the exam, you search and re-search without reaching the final decision and compare advantages and disadvantages with materials in the market. With systemic and methodological content within our MLA-C01 practice materials, they have helped more than 98 percent of exam candidates who chose our MLA-C01 guide exam before getting the final certificates successfully.
MLA-C01 Reliable Exam Vce: https://www.dumpsquestion.com/MLA-C01-exam-dumps-collection.html
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by DumpsQuestion: https://drive.google.com/open?id=1bZBeu-78NSZG5ZVygmDQrmC8S1Xtwk3P