Valid Databricks-Certified-Data-Engineer-Professional Practice Materials | Databricks-Certified-Data-Engineer-Professional Exam Simulator

The clients at home and abroad strive to buy our Databricks-Certified-Data-Engineer-Professional study materials because they think our products are the best study materials which are designed for preparing the test Databricks certification. They trust our Databricks-Certified-Data-Engineer-Professional study materials deeply not only because the high quality and passing rate of our Databricks-Certified-Data-Engineer-Professional study materials but also because our considerate service system. They treat our Databricks-Certified-Data-Engineer-Professional Study Materials as the magic weapon to get the Databricks certificate and the meritorious statesman to increase their wages and be promoted. You may be not quite familiar with our Databricks-Certified-Data-Engineer-Professional study materials and we provide the detailed explanation of our Databricks-Certified-Data-Engineer-Professional study materials as follow for you have an understanding before you decide to buy.
| Section | Objectives |
|---|
| Data Modeling and Transformation | - Performance optimization techniques
- Dimensional modeling concepts
- Spark SQL transformations
|
| Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics)
- Workspace and cluster architecture
- Medallion architecture (Bronze, Silver, Gold)
|
| Production Pipelines and Orchestration | - Error handling and recovery strategies
- Job scheduling and monitoring
- Databricks Workflows
|
| Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader
- ETL pipeline design patterns
- Structured Streaming fundamentals
|
| Delta Lake and Data Management | - Delta Lake transactions and ACID properties
- Schema evolution and enforcement
- Time travel and versioning
|
>> Valid Databricks-Certified-Data-Engineer-Professional Practice Materials <<
ExamDiscuss: The Ideal Solution for Databricks Databricks-Certified-Data-Engineer-Professional Exam Preparation
If you are determined to purchase our Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional valid exam collection materials for your companies, if you pursue long-term cooperation with site, we will have some relate policy. Firstly we provide one-year service warranty for every buyer who purchased Databricks Databricks-Certified-Data-Engineer-Professional valid exam collection materials.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q124-Q129):
NEW QUESTION # 124
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
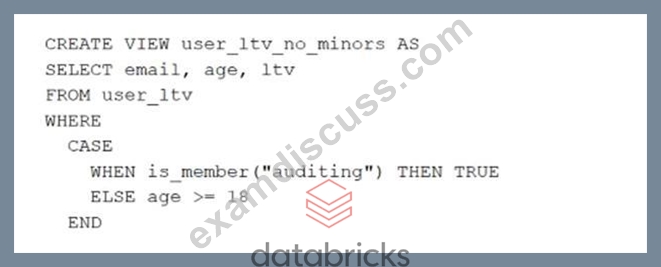
An analyst who is not a member of the auditing group executes the following query:
SELECT * FROM user_ltv_no_minors
Which statement describes the results returned by this query?
- A. All age values less than 18 will be returned as null values all other columns will be returned with the values in user_ltv.
- B. All columns will be displayed normally for those records that have an age greater than 18; records not meeting this condition will be omitted.
- C. All columns will be displayed normally for those records that have an age greater than 17; records not meeting this condition will be omitted.
- D. All records from all columns will be displayed with the values in user_ltv.
- E. All values for the age column will be returned as null values, all other columns will be returned with the values in user_ltv.
Answer: B
Explanation:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 125
When monitoring a complex workload, being able to see the query plan is critical to understanding what the workload is doing. Where can the visualization of the query plan be found?
- A. In the Query Profiler, under the Stages tab
- B. In the Query Profiler, under Query Source
- C. In the Spart UI, under the Jobs tab
- D. In the Spark UI, under the SQL/DataFrame tab
Answer: D
Explanation:
The Spark UI provides detailed visibility into how queries are executed. The SQL/DataFrame tab displays the logical and physical query plans, allowing engineers to visualize execution details and understand how the workload is processed across stages and operators.
NEW QUESTION # 126
To reduce storage and compute costs, the data engineering team has been tasked with curating a series of aggregate tables leveraged by business intelligence dashboards, customer-facing applications, production machine learning models, and ad hoc analytical queries.
The data engineering team has been made aware of new requirements from a customer-facing application, which is the only downstream workload they manage entirely. As a result, an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added.
Which of the solutions addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed?
- A. Replace the current table definition with a logical view defined with the query logic currently writing the aggregate table; create a new table to power the customer-facing application.
- B. Create a new table with the required schema and new fields and use Delta Lake's deep clone functionality to sync up changes committed to one table to the corresponding table.
- C. Configure a new table with all the requisite fields and new names and use this as the source for the customer-facing application; create a view that maintains the original data schema and table name by aliasing select fields from the new table.
- D. Add a table comment warning all users that the table schema and field names will be changing on a given date; overwrite the table in place to the specifications of the customer-facing application.
- E. Send all users notice that the schema for the table will be changing; include in the communication the logic necessary to revert the new table schema to match historic queries.
Answer: C
Explanation:
This is the correct answer because it addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed. The situation is that an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added, due to new requirements from a customer-facing application. By configuring a new table with all the requisite fields and new names and using this as the source for the customer-facing application, the data engineering team can meet the new requirements without affecting other teams that rely on the existing table schema and name. By creating a view that maintains the original data schema and Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from table name by aliasing select fields from the new table, the data engineering team can also avoid duplicating data or creating additional tables that need to be managed.
NEW QUESTION # 127
The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.
Which statement describes what the number alongside this field represents?
- A. The job_id is returned in this field.
- B. The globally unique ID of the newly triggered run.
- C. The total number of jobs that have been run in the workspace.
- D. The job_id and number of times the job has been are concatenated and returned.
- E. The number of times the job definition has been run in the workspace.
Answer: B
Explanation:
When triggering a job run using the Databricks CLI, the run_id field in the response represents a globally unique identifier for that particular run of the job. This run_id is distinct from the job_id.
While the job_id identifies the job definition and is constant across all runs of that job, the run_id is unique to each execution and is used to track and query the status of that specific job run within the Databricks environment. This distinction allows users to manage and reference individual executions of a job directly.
NEW QUESTION # 128
A Delta Lake table representing metadata about content from user has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE Based on the above schema, which column is a good candidate for partitioning the Delta Table?
- A. Post_id
- B. Post_time
- C. User_id
- D. latitude
- E. Date
Answer: E
Explanation:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, the date column is a good candidate for partitioning for several reasons:
Time-Based Queries: If queries frequently filter or group by date, partitioning by the date column can significantly improve performance by limiting the amount of data scanned. Granularity: The date column likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
Data Skew: Other columns like post_id or user_id might lead to uneven partition sizes (data skew), which can negatively impact performance.
Partitioning by post_time could also be considered, but typically date is preferred due to its more manageable granularity.
NEW QUESTION # 129
......
There are many merits of our product on many aspects and we can guarantee the quality of our Databricks-Certified-Data-Engineer-Professional practice engine. Firstly, our experienced expert team compile them elaborately based on the real exam and our Databricks-Certified-Data-Engineer-Professional study materials can reflect the popular trend in the industry and the latest change in the theory and the practice. Secondly, both the language and the content of our Databricks-Certified-Data-Engineer-Professional Study Materials are simple,easy to be understood and suitable for any learners.
Databricks-Certified-Data-Engineer-Professional Exam Simulator: https://www.examdiscuss.com/Databricks/exam/Databricks-Certified-Data-Engineer-Professional/
- Pass-Sure Databricks Valid Databricks-Certified-Data-Engineer-Professional Practice Materials Offer You The Best Exam Simulator | Databricks Certified Data Engineer Professional Exam 🍣 Open ➤ www.testkingpass.com ⮘ enter ▷ Databricks-Certified-Data-Engineer-Professional ◁ and obtain a free download 🕎New Databricks-Certified-Data-Engineer-Professional Test Pass4sure
- Free PDF Databricks - Databricks-Certified-Data-Engineer-Professional - High Pass-Rate Valid Databricks Certified Data Engineer Professional Exam Practice Materials 🎠 Search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ and download it for free on 《 www.pdfvce.com 》 website 🧩Databricks-Certified-Data-Engineer-Professional Latest Mock Test
- Databricks-Certified-Data-Engineer-Professional Reliable Test Answers 🏁 Exam Databricks-Certified-Data-Engineer-Professional Material 🤓 Latest Databricks-Certified-Data-Engineer-Professional Test Voucher 🦼 Immediately open ➠ www.pass4test.com 🠰 and search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ to obtain a free download 🐺Databricks-Certified-Data-Engineer-Professional Reliable Test Answers
- Valid Databricks-Certified-Data-Engineer-Professional Exam Topics 🌘 Databricks-Certified-Data-Engineer-Professional Questions Pdf 🆎 Databricks-Certified-Data-Engineer-Professional Reliable Test Answers 👳 Search for 【 Databricks-Certified-Data-Engineer-Professional 】 and obtain a free download on ➠ www.pdfvce.com 🠰 🤼New Databricks-Certified-Data-Engineer-Professional Test Pass4sure
- Latest Databricks-Certified-Data-Engineer-Professional Test Preparation 🛑 Reliable Databricks-Certified-Data-Engineer-Professional Dumps Free 🍌 Databricks-Certified-Data-Engineer-Professional Reliable Exam Sims 😢 Copy URL 《 www.prep4sures.top 》 open and search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 to download for free 🟪Valid Databricks-Certified-Data-Engineer-Professional Exam Topics
- Hot Valid Databricks-Certified-Data-Engineer-Professional Practice Materials | Valid Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam 100% Pass 😊 Easily obtain free download of 「 Databricks-Certified-Data-Engineer-Professional 」 by searching on ➤ www.pdfvce.com ⮘ ↗Key Databricks-Certified-Data-Engineer-Professional Concepts
- Valid Exam Databricks-Certified-Data-Engineer-Professional Vce Free 📫 Reliable Databricks-Certified-Data-Engineer-Professional Dumps Free 💮 Latest Databricks-Certified-Data-Engineer-Professional Test Preparation 🎴 Easily obtain free download of ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ by searching on “ www.examcollectionpass.com ” 🔍Reliable Databricks-Certified-Data-Engineer-Professional Dumps Free
- Exam Databricks-Certified-Data-Engineer-Professional Material 🥪 Exam Databricks-Certified-Data-Engineer-Professional Material 🤖 Databricks-Certified-Data-Engineer-Professional Reliable Exam Sims 👽 Open ➥ www.pdfvce.com 🡄 enter ➽ Databricks-Certified-Data-Engineer-Professional 🢪 and obtain a free download 🕳Databricks-Certified-Data-Engineer-Professional Reliable Test Experience
- Valid Exam Databricks-Certified-Data-Engineer-Professional Vce Free 🅰 Valid Exam Databricks-Certified-Data-Engineer-Professional Vce Free 👩 Key Databricks-Certified-Data-Engineer-Professional Concepts ⛪ Search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ and download it for free on ⮆ www.pdfdumps.com ⮄ website 🚒Databricks-Certified-Data-Engineer-Professional Reliable Exam Sims
- Databricks-Certified-Data-Engineer-Professional Latest Mock Test 🍶 Databricks-Certified-Data-Engineer-Professional Reliable Exam Sims 🤽 Valid Braindumps Databricks-Certified-Data-Engineer-Professional Ebook 🛬 Search on 「 www.pdfvce.com 」 for ( Databricks-Certified-Data-Engineer-Professional ) to obtain exam materials for free download 🎱New Databricks-Certified-Data-Engineer-Professional Test Pass4sure
- Exam Databricks-Certified-Data-Engineer-Professional Registration 🤝 New Databricks-Certified-Data-Engineer-Professional Test Pass4sure 🔂 Key Databricks-Certified-Data-Engineer-Professional Concepts 🕟 Open website ➥ www.troytecdumps.com 🡄 and search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ for free download 🦄Databricks-Certified-Data-Engineer-Professional Questions Pdf
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, learn.csisafety.com.au, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes