P.S. Kostenlose 2026 Amazon AIF-C01 Prüfungsfragen sind auf Google Drive freigegeben von ZertSoft verfügbar: https://drive.google.com/open?id=1ux1jfWMEBvhe5C5fqqBrlEFk6Yi9h401
Der Vorhang der Lebensbühne wird jederzeit geöffnet werden. Die Hauptsache ist, ob Sie spielen wollen oder einfach weglaufen. Diejenigen, die die Chancen ergreifen können, können Erfolg erlangen. Deshalb müssen Sie ZertSoft wählen. Sie können jederzeit Ihre Fertigkeiten zeigen. Die Prüfungsmaterialien zur Amazon AIF-C01 Zertifizierungsprüfung von ZertSoft ist die effziente Methode, die AIF-C01 Prüfung zu bestehen. Mit AIF-C01 Zertifikat können Sie Ihren Traum verwirklichen und Erfolg erlangen.
| Section | Weight | Objectives |
|---|---|---|
| AI Application Development | 30% | - Evaluate and optimize AI applications
|
| AWS AI Services Overview | 26% | - Describe Amazon Bedrock capabilities
|
| Responsible AI | 20% | - Understand governance and compliance requirements
|
| AI/ML Fundamentals | 24% | - Identify foundational terminology and definitions
|
Ihnen bei dem Bestehen der Amazon AIF-C01 Prüfung erfolgreich zu helfen bedeutet die beste Anerkennung unseres Fleißes. Um diesen Wunsch zu verwirklichen verbessern wir die Prüfungsunterlagen der Amazon AIF-C01 immer wieder. Sie können sie beruhigt benutzen. Wenn Sie Fragen über unsere Produkte oder Service haben, können Sie mit uns einfach online kontaktieren oder uns mailen. Nachdem Sie die Amazon AIF-C01 Prüfungsunterlagen gekauft haben, geben wir Ihnen die neueste Informationen über die Aktualisierung per E-Mail.
34. Frage
A company is building a solution to generate images for protective eyewear. The solution must have high accuracy and must minimize the risk of incorrect annotations.
Which solution will meet these requirements?
Antwort: D
Begründung:
Amazon SageMaker Ground Truth Plus is a managed data labeling service that includes human-in-the-loop (HITL) validation. This solution ensures high accuracy by involving human reviewers to validate the annotations and reduce the risk of incorrect annotations.
* Amazon SageMaker Ground Truth Plus:
* It allows for the creation of high-quality training datasets with human oversight, which minimizes errors in labeling and increases accuracy.
* Human-in-the-loop workflows help verify the correctness of annotations, ensuring that generated images for protective eyewear meet high-quality standards.
* Why Option A is Correct:
* High Accuracy: Human-in-the-loop validation provides the ability to catch and correct errors in annotations, ensuring high-quality data.
* Minimized Risk of Incorrect Annotations: Human review adds a layer of quality assurance, which is especially important in use cases like generating precise images for protective eyewear.
* Why Other Options are Incorrect:
* B. Amazon Bedrock: Does not offer a knowledge base for data augmentation; it focuses on running foundation models.
* C. Amazon Rekognition: Provides image recognition and analysis, not a solution for minimizing annotation errors.
* D. Amazon QuickSight: A data visualization tool, not relevant to image annotation or generation tasks.
Thus, A is the correct answer for generating high-accuracy images with minimized annotation risks.
35. Frage
A company wants to implement a large language model (LLM)-based chatbot to provide customer service agents with real-time contextual responses to customers' inquiries. The company will use the company's policies as the knowledge base.
Antwort: D
Begründung:
* Retraining or pre-training is costly and unnecessary for just using company policies.
* Fine-tuning adapts models but is inefficient for frequently changing company documents.
* Retrieval-Augmented Generation (RAG) is the best approach - it retrieves relevant policy documents from a knowledge base and feeds them into the model context in real time, ensuring accurate and up-to-date responses.
# Reference:
AWS Documentation - RAG with Amazon Bedrock
36. Frage
Which option describes embeddings in the context of AI?
Antwort: A
Begründung:
Embeddings in AI refer to numerical representations of data (e.g., text, images) in a lower-dimensional space, capturing semantic or contextual relationships. They are widely used in NLP and other AI tasks to represent complex data in a format that models can process efficiently.
Exact Extract from AWS AI Documents:
From the AWS AI Practitioner Learning Path:
"Embeddings are numerical representations of data in a reduced dimensionality space. In natural language processing, for example, word or sentence embeddings capture semantic relationships, enabling models to process text efficiently for tasks like classification or similarity search." (Source: AWS AI Practitioner Learning Path, Module on AI Concepts) Detailed Explanation:
* Option A: A method for compressing large datasetsWhile embeddings reduce dimensionality, their primary purpose is not data compression but rather to represent data in a way that preserves meaningful relationships. This option is incorrect.
* Option B: An encryption method for securing sensitive dataEmbeddings are not related to encryption or data security. They are used for data representation, making this option incorrect.
* Option C: A method for visualizing high-dimensional dataWhile embeddings can sometimes be used in visualization (e.g., t-SNE), their primary role is data representation for model processing, not visualization. This option is misleading.
* Option D: A numerical method for data representation in a reduced dimensionality spaceThis is the correct answer. Embeddings transform complex data into lower-dimensional numerical vectors, preserving semantic or contextual information for use in AI models.
References:
AWS AI Practitioner Learning Path: Module on AI Concepts
Amazon Comprehend Developer Guide: Embeddings for Text Analysis (https://docs.aws.amazon.com
/comprehend/latest/dg/embeddings.html)
AWS Documentation: What are Embeddings? (https://aws.amazon.com/what-is/embeddings/)
37. Frage
A company wants to develop ML applications to improve business operations and efficiency.
Select the correct ML paradigm from the following list for each use case. Each ML paradigm should be selected one or more times. (Select FOUR.)
* Supervised learning
* Unsupervised learning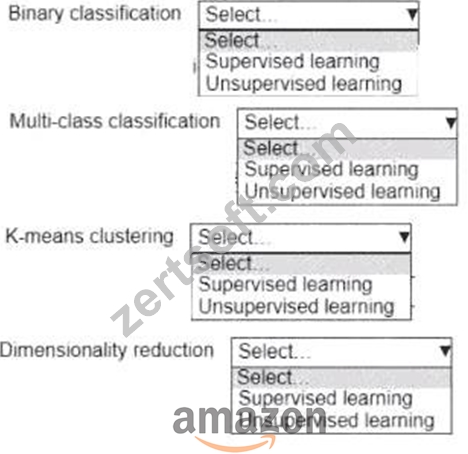
Antwort:
Begründung: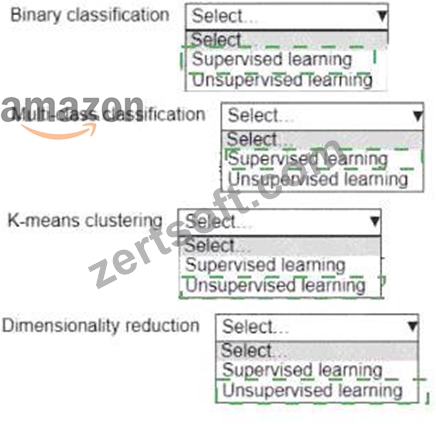
Explanation:
The company is developing ML applications for various use cases, and the task is to select the correct ML paradigm (supervised or unsupervised learning) for each. Supervised learning involves training a model on labeled data to make predictions, while unsupervised learning identifies patterns or structures in unlabeled data. Each use case aligns with one of these paradigms based on its requirements.
Exact Extract from AWS AI Documents:
From the AWS AI Practitioner Learning Path:
"Supervised learning uses labeled data to train models for tasks like classification (e.g., binary or multi-class classification), where the model predicts a category. Unsupervised learning works with unlabeled data for tasks like clustering (e.g., K-means clustering) or dimensionality reduction, identifying patternsor reducing data complexity without predefined labels." (Source: AWS AI Practitioner Learning Path, Module on Machine Learning Strategies) Detailed Explanation:
Binary classification: Supervised learningBinary classification involves predicting one of two classes (e.g., yes
/no, spam/not spam) using labeled data, making it a supervised learning task. The model learns from examples where the correct class is provided.
Multi-class classification: Supervised learningMulti-class classification extends binary classification to predict one of multiple classes (e.g., categorizing items into several groups). Like binary classification, it requires labeled data, so it falls under supervised learning.
K-means clustering: Unsupervised learningK-means clustering groups data into clusters based on similarity, without requiring labeled data. This is a classic unsupervised learning task, as the algorithm identifies patterns in the data on its own.
Dimensionality reduction: Unsupervised learningDimensionality reduction (e.g., using techniques like PCA) reduces the number of features in a dataset while preserving important information. It does not require labeled data, making it an unsupervised learning task.
Hotspot Selection Analysis:
The hotspot lists four use cases, each with a dropdown containing "Select...," "Supervised learning," and
"Unsupervised learning." The correct selections are:
Binary classification: Supervised learning
Multi-class classification: Supervised learning
K-means clustering: Unsupervised learning
Dimensionality reduction: Unsupervised learning
Each paradigm (supervised and unsupervised learning) is used twice, as the question allows for paradigms to be selected one or more times.
References:
AWS AI Practitioner Learning Path: Module on Machine Learning Strategies Amazon SageMaker Developer Guide: Supervised and Unsupervised Learning (https://docs.aws.amazon.com
/sagemaker/latest/dg/algos.html)
AWS Documentation: Introduction to Machine Learning Paradigms (https://aws.amazon.com/machine- learning/)
38. Frage
Select the correct AI term from the following list for each statement. Each AI term should be selected one time. (Select THREE.)
* AI
* Deep learning
* ML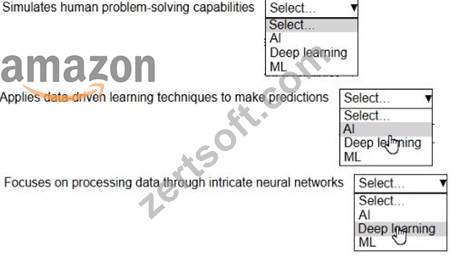
Antwort:
Begründung: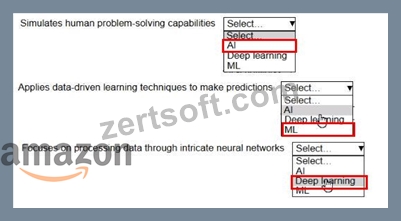
39. Frage
......
Aufgrund der großen Übereinstimmung mit den echten Prüfungsfragen- und Antworten können wir Ihnen 100%-Pass-Garantie versprechen. Wir aktualisieren jeden Tag nach den Informationen von Prüfungsabsolventen oder Mitarbeiter von Testcentern. unsere Prüfungsfragen und Antworten zu Amazon AIF-C01 (AWS Certified AI Practitioner). Wir extrahieren jeden Tag die Informationen der tatsächlichen Prüfungen und integrieren in unsere Produkte integrieren.
AIF-C01 Lernressourcen: https://www.zertsoft.com/AIF-C01-pruefungsfragen.html
Laden Sie die neuesten ZertSoft AIF-C01 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1ux1jfWMEBvhe5C5fqqBrlEFk6Yi9h401