BONUS!!! Download part of Actual4Exams Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1pSSXhMxWdixtl6I4r6kgjk1EZ9CI6iht
In the PDF version, real Professional-Machine-Learning-Engineer exam questions are available. These Google Professional-Machine-Learning-Engineer real questions are printable and portable. You can take this PDF document anywhere and study for the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam without time restrictions. Actual4Exams regularly make changes in the Professional-Machine-Learning-Engineer PDF format when required. Professional-Machine-Learning-Engineer questions in this format are relevant to the actual test.
| Section | Objectives |
|---|---|
| Scaling prototypes into ML models | - Training at scale (Distributed training, TPUs) - Hyperparameter tuning - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) |
| Architecting low-code ML solutions | - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) - Implementing BigQuery ML for basic models - AutoML capabilities and implementation |
| Automating and orchestrating ML pipelines | - CI/CD for ML systems - Vertex AI Pipelines (Kubeflow Pipelines) - Triggering and scheduling pipelines |
| Serving and scaling models | - Online prediction (Vertex AI Prediction) - Batch prediction - Hardware accelerators (GPU/TPU) in serving - Model optimization (Quantization, Distillation) |
| Monitoring ML solutions | - Performance monitoring and drift detection - Model retraining strategies - Logging and alerting (Cloud Monitoring) |
| Collaborating within and across teams to manage data and models | - Data management and governance - Version control and reproducibility (e.g., DVC, MLOps) - Collaboration between Data Scientists, Data Engineers, and ML Engineers |
>> Professional-Machine-Learning-Engineer Certificate Exam <<
The Actual4Exams is committed from the first day to help students ace the Google Professional-Machine-Learning-Engineer exam at any cost. These formats are Google Professional-Machine-Learning-Engineer PDF questions file, desktop practice test software, and web-based practice test software. All these three Actual4Exams Professional-Machine-Learning-Engineer Exam Questions formats are designed to help applicants ace the Google Professional-Machine-Learning-Engineer exam preparation and enable the candidates to crack the final Google Professional-Machine-Learning-Engineer exam easily.
NEW QUESTION # 187
You are deploying a new version of a model to a production Vertex Al endpoint that is serving traffic You plan to direct all user traffic to the new model You need to deploy the model with minimal disruption to your application What should you do?
Answer: A
Explanation:
The best option for deploying a new version of a model to a production Vertex AI endpoint that is serving traffic, directing all user traffic to the new model, and deploying the model with minimal disruption to your application, is to create a new model, set the parentModel parameter to the model ID of the currently deployed model, upload the model to Vertex AI Model Registry, deploy the new model to the existing endpoint, and set the new model to 100% of the traffic. This option allows you to leverage the power and simplicity of Vertex AI to update your model version and serve online predictions with low latency. Vertex AI is a unified platform for building and deploying machine learning solutions on Google Cloud. Vertex AI can deploy a trained model to an online prediction endpoint, which can provide low-latency predictions for individual instances. A model is a resource that represents a machine learning model that you can use for prediction. A model can have one or more versions, which are different implementations of the same model. A model version can have different parameters, code, or data than another version of the same model. A model version can help you experiment and iterate on your model, and improve the model performance and accuracy. A parentModel parameter is a parameter that specifies the model ID of the model that the new model version is based on. A parentModel parameter can help you inherit the settings and metadata of the existing model, and avoid duplicating the model configuration. Vertex AI Model Registry is a service that can store and manage your machine learning models on Google Cloud. Vertex AI Model Registry can help you upload and organize your models, and track the model versions and metadata. An endpoint is a resource that provides the service endpoint (URL) you use to request the prediction. An endpoint can have one or more deployed models, which are instances of model versions that are associated with physical resources. A deployed model can help you serve online predictions with low latency, and scale up or down based on the traffic. By creating a new model, setting the parentModel parameter to the model ID of the currently deployed model, uploading the model to Vertex AI Model Registry, d eploying the new model to the existing endpoint, and setting the new model to 100% of the traffic, you can deploy a new version of a model to a production Vertex AI endpoint that is serving traffic, direct all user traffic to the new model, and deploy the model with minimal disruption to your application 1 .
The other options are not as good as option C, for the following reasons:
* Option A: Creating a new endpoint, creating a new model, setting it as the default version, uploading the model to Vertex AI Model Registry, deploying the new model to the new endpoint, and updating Cloud DNS to point to the new endpoint would require more skills and steps than creating a new model, setting the parentModel parameter to the model ID of the currently deployed model, uploading the model to Vertex AI Model Registry, deploying the new model to the existing endpoint, and setting the new model to 100% of the traffic. Cloud DNS is a service that can provide reliable and scalable Domain Name System (DNS) services on Google Cloud. Cloud DNS can help you manage your DNS records, and resolve domain names to IP addresses. By updating Cloud DNS to point to the new endpoint, you can redirect the user traffic to the new endpoint, and avoid breaking the existing application. However, creating a new endpoint, creating a new model, setting it as the default version, uploading the model to Vertex AI Model Registry, deploying the new model to the new endpoint, and updating Cloud DNS to point to the new endpoint would require more skills and steps than creating a new model, setting the parentModel parameter to the model ID of the currently deployed model, uploading the model to Vertex AI Model Registry, deploying the new model to the existing endpoint, and setting the new model to 100% of the traffic. You would need to write code, create and configure the new endpoint, create and configure the new model, upload the model to Vertex AI Model Registry, deploy the model to the new endpoint, and update Cloud DNS to point to the new endpoint. Moreover, this option would create a new endpoint, which can increase the maintenance and management costs 2 .
* Option B: Creating a new endpoint, creating a new model, setting the parentModel parameter to the model ID of the currently deployed model and setting it as the default version, uploading the model to Vertex AI Model Registry, and deploying the new model to the new endpoint and setting the new model to 100% of the traffic would require more skills and steps than creating a new model, setting the parentModel parameter to the model ID of the currently deployed model, uploading the model to Vertex AI Model Registry, deploying the new model to the existing endpoint, and setting the new model to
100% of the traffic. A parentModel parameter is a parameter that specifies the model ID of the model that the new model version is based on. A parentModel parameter can help you inherit the settings and metadata of the existing model, and avoid duplicating the model configuration. A default version is a model version that is used for prediction when no other version is specified. A default version can help you simplify the prediction request, and avoid specifying the model version every time. By setting the parentModel parameter to the model ID of the currently deployed model and setting it as the default version, you can create a new model that is based on the existing model, and use it for prediction without specifying the model version. However, creating a new endpoint, creating a new model, setting the parentModel parameter to the model ID of the currently deployed model and setting it as the default version, uploading the model to Vertex AI Model Registry, and deploying the new model to the new endpoint and setting the new model to 100% of the traffic would require more skills and steps than creating a new model, setting the parentModel parameter to the model ID of the currently deployed model, uploading the model to Vertex AI Model Registry, deploying the new model to the existing endpoint, and setting the new model to 100% of the traffic. You would need to write code, create and configure the new endpoint, create and configure the new model, upload the model to Vertex AI Model Registry, and deploy the model to the new endpoint. Moreover, this option would create a new endpoint, which can increase the maintenance and management costs 2 .
* Option D: Creating a new model, setting it as the default version, uploading the model to Vertex AI Model Registry, and deploying the new model to the existing endpoint would not allow you to inherit the settings and metadata of the existing model, and could cause errors or poor performance. A default version is a model version that is used for prediction when no other version is specified. A default version can help you simplify the prediction request, and avoid specifying the model version every time. By setting the new model as the default version, you can use the new model for prediction without specifying the model version. However, creating a new model, setting it as the default version, uploading the model to Vertex AI Model Registry, and deploying the new model to the existing endpoint would not allow you to inherit the settings and metadata of the existing model, and could cause errors or poor performance. You would need to write code, create and configure the new model, upload the model to Vertex AI Model Registry, and deploy the model to the existing endpoint. Moreover, this option would not set the parentModel parameter to the model ID of the currently de ployed model, which could prevent you from inheriting the settings and metadata of the existing model, and cause inconsistencies or conflicts between the model versions 2 .
References:
Preparing for Google Cloud Certification: Machine Learning Engineer , Course 3: Production ML Systems, Week 2: Serving ML Predictions Google Cloud Professional Machine Learning Engineer Exam Guide , Section 3: Scaling ML models in production, 3.1 Deploying ML models to production Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6: Production ML Systems, Section 6.2: Serving ML Predictions Vertex AI Cloud DNS
NEW QUESTION # 188
This graph shows the training and validation loss against the epochs for a neural network.
The network being trained is as follows:
* Two dense layers, one output neuron
* 100 neurons in each layer
* 100 epochs
* Random initialization of weights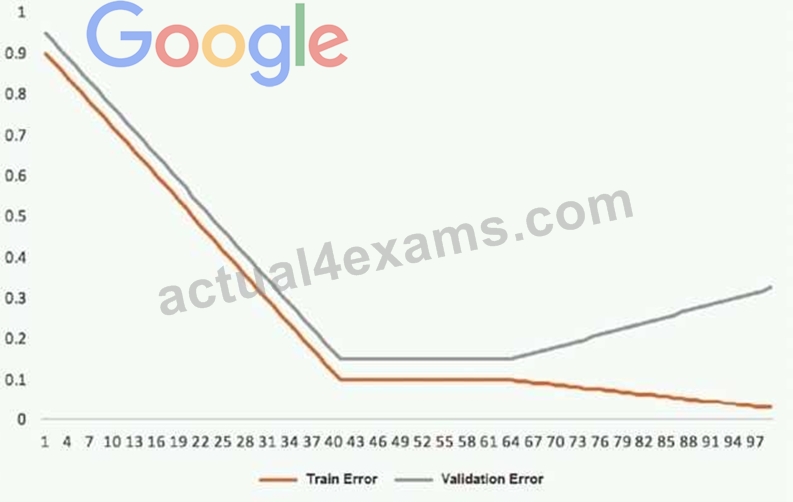
Which technique can be used to improve model performance in terms of accuracy in the validation set?
Answer: D
NEW QUESTION # 189
You are training a TensorFlow model on a structured data set with 100 billion records stored in several CSV files. You need to improve the input/output execution performance. What should you do?
Answer: C
Explanation:
The input/output execution performance of a TensorFlow model depends on how efficiently the model can read and process the data from the data source. Reading and processing data from CSV files can be slow and inefficient, especially if the data is large and distributed. Therefore, to improve the input/output execution performance, one should use a more suitable data format and storage system.
One of the best options for improving the input/output execution performance is to convert the CSV files into shards of TFRecords, and store the data in Cloud Storage. TFRecord is a binary data format that can store a sequence of serialized TensorFlow examples. TFRecord has several advantages over CSV, such as:
* Faster data loading: TFRecord can be read and processed faster than CSV, as it avoids the overhead of parsing and decoding the text data. TFRecord also supports compression and checksums, which can reduce the data size and ensure data integrity1
* Better performance: TFRecord can improve the performance of the model, as it allows the model to access the data in a sequential and streaming manner, and leverage the tf.data API to build efficient data pipelines. TFRecord also supports sharding and interleaving, which can increase the parallelism and throughput of the data processing2
* Easier integration: TFRecord can integrate seamlessly with TensorFlow, as it is the native data format for TensorFlow. TFRecord also supports various types of data, such as images, text, audio, and video, and can store the data schema and metadata along with the data3 Cloud Storage is a scalable and reliable object storage service that can store any amount of data. Cloud Storage has several advantages over other storage systems, such as:
* High availability: Cloud Storage can provide high availability and durability for the data, as it replicates the data across multiple regions and zones, and supports versioning and lifecycle management. Cloud Storage also offers various storage classes, such as Standard, Nearline, Coldline, and Archive, to meet different performance and cost requirements4
* Low latency: Cloud Storage can provide low latency and high bandwidth for the data, as it supports HTTP and HTTPS protocols, and integrates with other Google Cloud services, such as AI Platform, Dataflow, and BigQuery. Cloud Storage also supports resumable uploads and downloads, and parallel composite uploads, which can improve the data transfer speed and reliability5
* Easy access: Cloud Storage can provide easy access and management for the data, as it supports various tools and libraries, such as gsutil, Cloud Console, and Cloud Storage Client Libraries. Cloud Storage
* also supports fine-grained access control and encryption, which can ensure the data security and privacy.
The other options are not as effective or feasible. Loading the data into BigQuery and reading the data from BigQuery is not recommended, as BigQuery is mainly designed for analytical queries on large-scale data, and does not support streaming or real-time data processing. Loading the data into Cloud Bigtable and reading the data from Bigtable is not ideal, as Cloud Bigtable is mainly designed for low-latency and high-throughput key-value operations on sparse and wide tables, and does not support complex data types or schemas.
Converting the CSV files into shards of TFRecords and storing the data in the Hadoop Distributed File System (HDFS) is not optimal, as HDFS is not natively supported by TensorFlow, and requires additional configuration and dependencies, such as Hadoop, Spark, or Beam.
References: 1: TFRecord and tf.Example 2: Better performance with the tf.data API 3: TensorFlow Data Validation 4: Cloud Storage overview 5: Performance : [How-to guides]
NEW QUESTION # 190
You are training an LSTM-based model on Al Platform to summarize text using the following job submission script: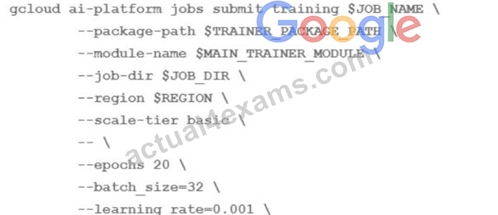
You want to ensure that training time is minimized without significantly compromising the accuracy of your model. What should you do?
Answer: D
NEW QUESTION # 191
You work for a delivery company. You need to design a system that stores and manages features such as parcels delivered and truck locations over time. The system must retrieve the features with low latency and feed those features into a model for online prediction. The data science team will retrieve historical data at a specific point in time for model training. You want to store the features with minimal effort. What should you do?
Answer: A
NEW QUESTION # 192
......
The Professional-Machine-Learning-Engineer certification exam is one of the top-rated career advancement certifications in the market. This Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam dumps have been inspiring beginners and experienced professionals since its beginning. There are several personal and professional benefits that you can gain after passing the Google Professional-Machine-Learning-Engineer Exam. The validation of expertise, more career opportunities, salary enhancement, instant promotion, and membership of Google certified professional community.
Associate Professional-Machine-Learning-Engineer Level Exam: https://www.actual4exams.com/Professional-Machine-Learning-Engineer-valid-dump.html
P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by Actual4Exams: https://drive.google.com/open?id=1pSSXhMxWdixtl6I4r6kgjk1EZ9CI6iht