Start Your Snowflake SPS-C01 Exam Preparation with SPS-C01 Actual Exam Questions

DOWNLOAD the newest TrainingDump SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=182JXFgH-ARgC9YkBQIKFxuoTIxBYJGtU
If you use our products, I believe it will be very easy for you to successfully pass your SPS-C01 exam. Of course, if you unluckily fail to pass your exam, don’t worry, because we have created a mechanism for economical compensation. You just need to give us your test documents and transcript, and then our Snowflake Certified SnowPro Specialty - Snowpark prep torrent will immediately provide you with a full refund, you will not lose money. More importantly, if you decide to buy our SPS-C01 Exam Torrent, we are willing to give you a discount, you will spend less money and time on preparing for your exam.
| Section | Weight | Objectives |
|---|
| Topic 1: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
- 1. Client-side vs server-side processing
- 2. Transformations vs actions
- 3. Lazy evaluation and DAG execution
- Session management and connection
- 1. Authentication and connection settings
- 2. Create and configure Snowpark sessions
|
| Topic 2: Performance and Best Practices | 10% | - Optimization techniques
- 1. Query pushdown and execution plans
- 2. Minimizing data movement
- 3. Caching and warehouse sizing
- Security and governance
- 1. Data protection and compliance
- 2. Access control and permissions
|
| Topic 3: Snowpark API and Development | 30% | - Multi-language support
- 1. Environment setup and dependencies
- 2. Java and Scala API basics
- Python API fundamentals
- 1. Data persistence and writing results
- 2. Column operations and functions
- 3. DataFrame creation from tables, views, SQL
|
| Topic 4: Data Transformations and Operations | 35% | - User-defined logic
- 1. Stored procedures with Snowpark
- 2. UDFs, UDAFs, UDTFs
- DataFrame manipulation
- 1. Selection, projection, renaming, casting
- 2. Joins, unions, set operations
- 3. Filtering, sorting, grouping, aggregation
- Advanced operations
- 1. Semi-structured data processing
- 2. Window functions and analytics
- 3. Pivot and unpivot transformations
|
>> SPS-C01 Reliable Test Testking <<
SPS-C01 Sample Test Online, SPS-C01 Dump Check
The SPS-C01 exam prep is produced by our expert, is very useful to help customers pass their SPS-C01 exams and get the certificates in a short time. If you want to know the quality of our SPS-C01 guide braindumps befor you buy it, you can just free download the demo of our SPS-C01 Exam Questions. We can sure that our SPS-C01 training guide will help you get the certificate easily. If you are wailing to believe us and try to learn our SPS-C01 exam torrent, you will get an unexpected result.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q145-Q150):
NEW QUESTION # 145
You have a Snowflake table named 'RAW EVENTS with a large number of events data, containing columns like 'EVENT ID', 'TIMESTAMP, 'USER ID, and 'EVENT_TYPE. The 'EVENT TYPE column contains string values representing different event categories. You want to create a Snowpark DataFrame, but due to the table's size, you only want to sample a small portion of the data for initial exploration and testing. Which of the following code snippets MOST accurately and efficiently creates a sampled Snowpark DataFrame named 'sampled_df containing approximately 1% of the rows from the 'RAW EVENTS table?
Answer: E
Explanation:
Explanation:Option A provides the MOST accurate and efficient way to sample 1% of the data using , seed-42)'. The 'frae parameter directly specifies the fraction of rows to sample. 'seed' ensures consistent sampling across multiple runs. Option B is inefficient because it calculates the total count of rows before limiting, which scans the entire table. Option C, uses 'randomSplit' , but it splits the data into two new dataframes. Option D, utilizes Snowflake's SQL sampling feature via 'session.sqr , is a valid alternative, but less idiomatic when using Snowpark API directly. Option E, the parameter 'n' is deprecated and has been removed. 'sample' requires 'frae parameter.
NEW QUESTION # 146
Consider the following Snowpark Python code snippet designed to calculate a custom metric on financial data, using a vectorized UDF for performance. Identify potential performance bottlenecks and recommend optimization strategies.
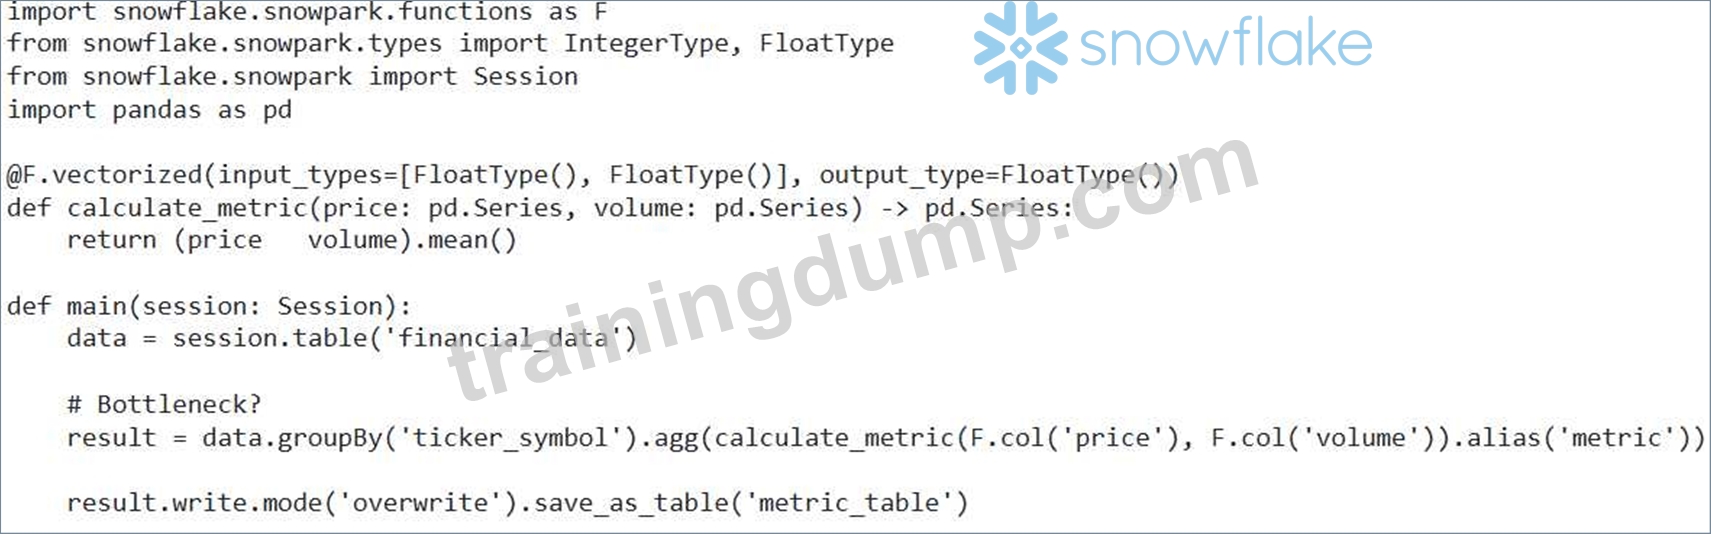
Which of the following actions (may be more than one) would MOST likely improve the performance of this Snowpark application?
- A. Change 'FloatType' to 'DoubleType' as it provides more precision.
- B. Use to explicitly declare the Pandas dependency.
- C. Repartition the 'data' DataFrame by 'ticker_symbol' before the 'groupBy' operation using to improve data locality.
- D. Ensure that the 'financial_data' table is clustered by 'ticker_symbor to optimize the 'groupBy' operation.
- E. Use before writing to the 'metric_table' , especially if the table is subsequently used downstream.
Answer: C,D,E
Explanation:
Clustering by 'ticker_symbol' significantly optimizes the 'groupBy' operation by organizing data physically for efficient retrieval. Caching the result before writing to a table is crucial if the intermediate result 'result' will be used multiple times, avoiding redundant computations. Repartitioning by 'ticker_symbol' before grouping helps distribute data evenly, improving parallelism and locality. While Pandas is generally available, explicitly declaring it might be necessary in certain isolated environments, so B can be considered a good practice, but not as impactful. Changing FloatType to DoubleType (C) will not lead to performnace improvement. It only changes precision level which is not required here.
NEW QUESTION # 147
Consider the following Snowpark Python code snippet intended to operationalize a stored procedure:

This code results in an error during registration. Which of the following actions would be MOST appropriate to fix the registration issue and ensure the stored procedure can be successfully operationalized?
- A. Add 'session.close()' at the end of the main function.
- B. Define 'session' as a global variable before calling 'session.sproc.register' .
- C. Remove the 'input_data' parameter from the 'main' function definition and access the input data directly using within the function.
- D. Add in sproc.register.
- E. Move the 'session.sproc.register' call outside of the 'main' function and execute it separately after the 'main' function definition.
Answer: E
Explanation:
Option C is the correct solution. The 'session.sproc.registefl method should be called outside of the 'main' function definition. The registration process is a separate step from the function definition itself. The 'sproc.register' will take the function definition and create an object in Snowflake. Since this must be outside of the function it needs to be outside the main function. All other options would not solve the error with the registration.
NEW QUESTION # 148
You are developing a Snowpark application to analyze website traffic data'. You have a DataFrame named 'website_logs' with columns 'user_id', 'page_url', and 'timestamp'. You need to create a new DataFrame that contains the count of distinct users who visited each page within a specific time window Consider the following (incomplete) Snowpark Python code:

Which of the following code lines, when inserted into the Complete the following line...' comment, will correctly calculate the approximate distinct user count for each page within the specified time window?
- A. _logs.with_column('distinct_users', F.countDistinct('user_id').over(window_spec)) website
- B. website_logs.with_column('distinct_users', F.count('user_id').over(window_spec))
- C. website_logs.with_column('distinct_users', F.approx_count_distinct('user_id').over(window_spec))
- D. website_logs.groupBy('page_url', F.window('timestamp', '1 hour')).agg(F.countDistinct('user_id').alias('distinct_users'))
- E. website_logs.groupBy('page_url').agg(F.countDistinct('user_id').alias('distinct_users'))
Answer: C
Explanation:
The correct code line is 'website_logs.with_column('distinct_users', F.approx_count_distinct('user_id').over(window_spec))'. This uses the function to calculate the approximate distinct count of user IDs within the window defined by 'window_spec' . Option B uses exact count which is less performant. Option A performs an aggregation, which will give a different type of result. Option D uses F.window' which is used for tumbling windows, not sliding windows as requested by the problem.
NEW QUESTION # 149
You are using Snowpark Python to process a DataFrame containing customer data,. One of the columns, 'phone_number' , contains phone numbers in various formats (e.g., '123-456-7890', '(123) 456-7890', '1234567890'). You need to standardize these phone numbers to the format 'XXX-XXX-XXXX' using a User-Defined Function (UDF). You want to create a UDF called 'standardize_phone_number' that takes a string as input and returns the standardized phone number. Which of the following code snippets correctly defines and registers this UDF in Snowpark, and applies it to the 'phone_number' column of the 'customer df DataFrame? Assume a Snowflake session object called 'session' is already available.
Answer: A
Explanation:
Option E is the most concise and correct way to define and use the UDF. It uses the '@F.udf decorator, which simplifies the UDF registration process. It also correctly imports 'snowflake.snowpark.functions as F to use the decorator. Options A and D are less efficient because they use 'call_udf instead of directly calling the UDF. Option B registers UDF but does not import required libraries. Option C doesn't import necessary library for the functions.
NEW QUESTION # 150
......
If you don't pass the Selling Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam, TrainingDump will refund the money. Some terms and conditions related to the refund are given on the guarantee page. You will not find such excellent offers anywhere else. Therefore, don't miss this golden opportunity and Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice test material today!
SPS-C01 Sample Test Online: https://www.trainingdump.com/Snowflake/SPS-C01-practice-exam-dumps.html
- SPS-C01 Reliable Study Questions 🔭 New SPS-C01 Test Sims 🧊 SPS-C01 Valid Test Online ⚛ Search for ( SPS-C01 ) and download exam materials for free through “ www.pdfdumps.com ” 🥤Test SPS-C01 King
- Free PDF Quiz Reliable SPS-C01 - Snowflake Certified SnowPro Specialty - Snowpark Reliable Test Testking 🧮 Search on ▷ www.pdfvce.com ◁ for 【 SPS-C01 】 to obtain exam materials for free download 🏈Latest SPS-C01 Test Online
- SPS-C01 Pass Test Guide 🏘 SPS-C01 Pass Test Guide 🥞 Exam SPS-C01 Tests 🥀 Copy URL ▛ www.prepawayexam.com ▟ open and search for “ SPS-C01 ” to download for free 🤦SPS-C01 Pass Test Guide
- Download SPS-C01 Pdf ☀ SPS-C01 Valid Test Online 📣 SPS-C01 Valid Test Online 🏀 Go to website ▛ www.pdfvce.com ▟ open and search for 《 SPS-C01 》 to download for free ⚪Exam SPS-C01 Tests
- SPS-C01 Reliable Test Testking: Snowflake Certified SnowPro Specialty - Snowpark - Trustable Snowflake SPS-C01 Sample Test Online 🎄 Open [ www.prepawayexam.com ] enter ⏩ SPS-C01 ⏪ and obtain a free download 🐱Pass SPS-C01 Test Guide
- Excellent SPS-C01 Reliable Test Testking, SPS-C01 Sample Test Online ☯ Go to website 《 www.pdfvce.com 》 open and search for ➽ SPS-C01 🢪 to download for free 🥚SPS-C01 Exam Success
- Trustable Snowflake Reliable Test Testking – Useful SPS-C01 Sample Test Online 💿 Open ▶ www.testkingpass.com ◀ and search for “ SPS-C01 ” to download exam materials for free 🔟Reliable SPS-C01 Exam Braindumps
- Pass Guaranteed SPS-C01 - Authoritative Snowflake Certified SnowPro Specialty - Snowpark Reliable Test Testking ☕ Download ➽ SPS-C01 🢪 for free by simply searching on “ www.pdfvce.com ” 🥼Latest Braindumps SPS-C01 Book
- Pass SPS-C01 Test Guide 🩲 SPS-C01 Reliable Study Questions 😰 SPS-C01 Exam Format 🥉 The page for free download of ( SPS-C01 ) on ➤ www.prepawayete.com ⮘ will open immediately 😗SPS-C01 Frequent Updates
- Three Snowflake SPS-C01 Exam Questions Formats - Make Your Exam Preparation Easy 🥼 Simply search for ☀ SPS-C01 ️☀️ for free download on ➠ www.pdfvce.com 🠰 🍍Latest Braindumps SPS-C01 Book
- New SPS-C01 Test Sims 🌮 SPS-C01 Frequent Updates 🍧 SPS-C01 Frequent Updates 🔚 Search for ➤ SPS-C01 ⮘ and download exam materials for free through ➤ www.vce4dumps.com ⮘ 🦧Reliable SPS-C01 Exam Braindumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, forum.lcshosting.eu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
DOWNLOAD the newest TrainingDump SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=182JXFgH-ARgC9YkBQIKFxuoTIxBYJGtU


