Die Microsoft AI-200 Zertifizierungsprüfung sind jedem IT-Fachmann sehr wichtig. Solange Sie das AI-200 Zertifikat bekommen, werden Sie im Beruf sicher nicht aussondert. Sie werden befördert und ein höheres Gehalt beziehen. Mit diesem Zertifikat können Sie alle bekommen, was Sie wünschen. Die Fragenpool zur Microsoft AI-200Zertifizierungsprüfung von ZertFragen sind die Ressourcen zum Erfolg. Mit diesen Schulungsmaterialien werden Sie den Schritt zum Erfolg beschleunigen. Sie werden sicher mehr selbstbewusster.
| Section | Weight | Objectives |
|---|---|---|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
>> AI-200 Deutsch Prüfungsfragen <<
Im 21. Jahrhundert ist die Technik hoch entwickelt und die Information weit verbreitet. Das Internet ist nicht nur eine Unterhaltungsplattform, sondern auch eine weltklassige elektronische Bibliothek. Bei ZertFragen können Sie Ihre eigene Schatzkammer für IT-Infoamationskenntnisse finden. Wählen Sie die Fragenkataloge zur Microsoft AI-200 Zertifizierungsprüfung von ZertFragen, armen Sie zugleich auch die schöne Zukunft um. Wenn Sie unsere Fragenkataloge zur Microsoft AI-200 Zertifizierungsprüfung kaufen, garantieren wir Ihenen, dass Sie die AI-200 Prüfung sicherlich bestehen können.
23. Frage
Drag and Drop Question
You are developing a solution for a hospital to support the following use cases:
- The most recent patient status details must be retrieved even if
multiple users in different locations have updated the patient record.
- Patient health monitoring data retrieved must be the current version
or the prior version.
- After a patient is discharged and all charges have been assessed, the patient billing record contains the final charges.
You provision an Azure Cosmos DB for NoSQL database and set the default consistency level for the database account to Strong.
You set the value for Indexing Mode to Consistent.
You need to minimize latency and any impact to the availability of the solution. You must override the default consistency level at the query level to meet the required consistency guarantees for the scenarios.
Which consistency levels should you implement? To answer, drag the appropriate consistency levels to the correct requirements. Each consistency level may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.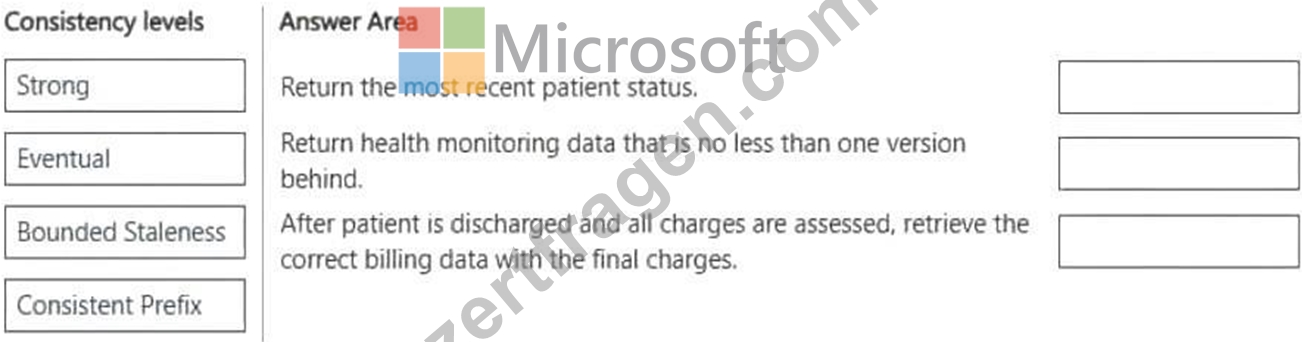
Antwort:
Begründung: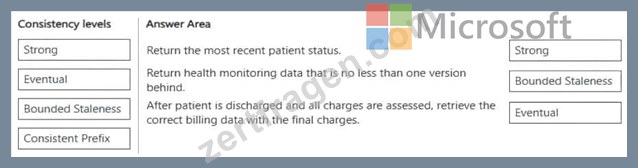
Explanation:
Box 1: Strong
Strong consistency must be used at the query level to meet this requirement.
Linearizability Guarantee: Strong consistency ensures that a read operation always returns the most recent committed version of an item.
Global Consensus: Because multiple users in different locations are updating the patient record, any reader across any region must wait for the updates to be fully committed globally before reading. This prevents any user from reading stale or out-of-order data, which is critical for patient status details.
Box 2: Bounded Staleness
To minimize latency and maximize availability while ensuring that retrieved patient health monitoring data is either the current version or the immediate prior version, you should override the consistency level at the query level to Bounded Staleness.
Version Guarantee: Bounded Staleness ensures that reads are not older than a specific time window or a configured number of versions K versions behind the latest write). Setting the version staleness to 1 (K=1 )guarantees that the data read is either the current version or the prior version.
Lower Latency: Bounded Staleness offers significantly lower latency than the account's default Strong consistency. Strong consistency requires a global majority acknowledgment before a read or write completes, increasing latency.
Higher Availability: By backing down from Strong consistency to Bounded Staleness for this query, you reduce the strict synchronization requirements, thereby minimizing impacts on availability during localized network disruptions.
Box 3: Eventual
Eventual consistency is the correct consistency level to use at the query level for this scenario.
Maximizes Performance: Eventual consistency offers the lowest latency and highest availability among all consistency levels.
Matches Scenario Needs: The billing record is final and no longer changing, so there is no risk of reading stale, in-progress updates.
Optimizes Costs: Eventual consistency queries consume half the Request Units (RUs) compared to Strong or Bounded Staleness queries.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/consistency-levels
24. Frage
You are building a RAG (retrieval-augmented generation) solution using Azure AI Foundry. The knowledge base consists of 50,000 PDF documents stored in Azure Blob Storage.
You need to make the document content searchable by the language model with minimal custom code.
What should you use?
Antwort: D
Begründung:
Use Azure AI Search integrated vectorization with a skillset . Integrated vectorization automates the main ingestion stages required for RAG: an Azure AI Search indexer can read documents directly from a supported data source such as Azure Blob Storage, extract and split document content into chunks, invoke an embedding model, and store both searchable text and vector representations in the search index. Microsoft specifically states that integrated vectorization reduces development and maintenance effort because developers do not need to implement the chunking and embedding pipeline manually.
A skillset can include a Text Split skill for chunking and an Azure OpenAI Embedding skill or another supported embedding skill for vector generation. At query time, a matching vectorizer can convert user questions into vectors so Azure AI Search can perform similarity or hybrid retrieval for grounding the language model.
Custom text classification solves a different NLP problem. Building Azure Functions to process all 50,000 PDFs manually would introduce unnecessary custom orchestration and maintenance. Azure Table Storage does not provide the native vector-search and RAG indexing capabilities required here.
Study Guide references: Azure AI Search # integrated vectorization; indexers; skillsets; Text Split skill; embedding skills; vector indexes; RAG retrieval.
25. Frage
Drag and Drop Question
A Python API running in ACA must send distributed traces to Azure Monitor.
The API creates spans. However, no traces appear in Azure Monitor.
You need to configure the OpenTelemetry SDK pipeline to export traces to Azure Monitor.
What should you do? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.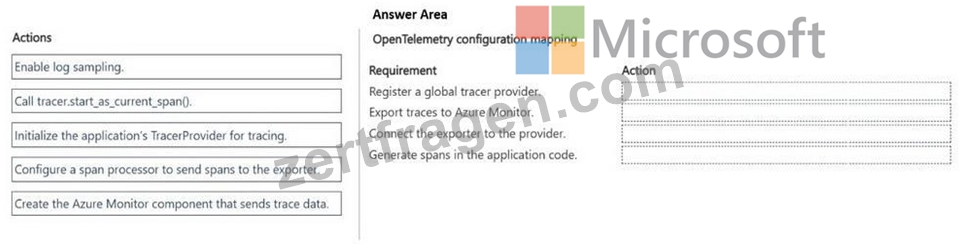
Antwort:
Begründung: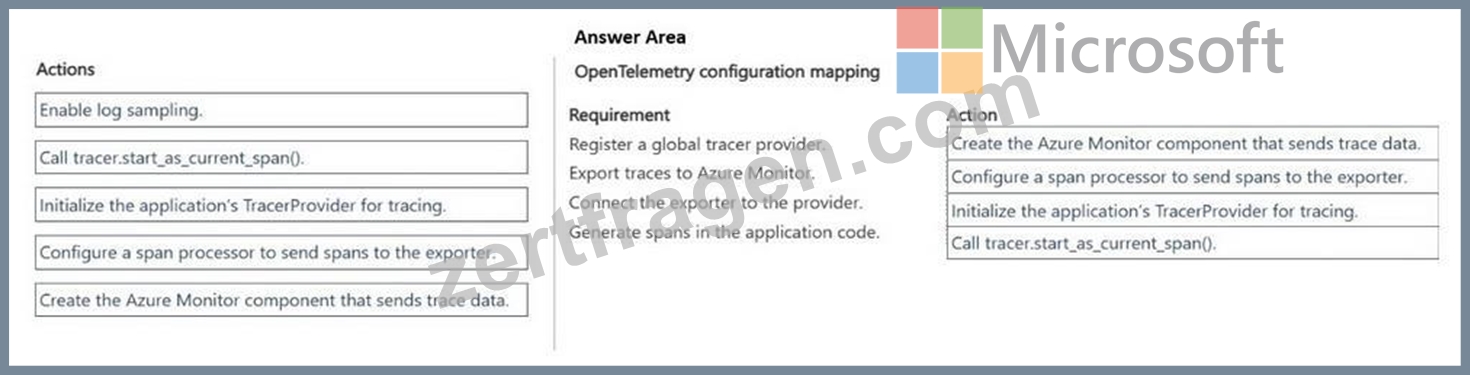
Explanation:
Box 1: Create the Azure Monitor component that sends trace data
To register a global TracerProvider in OpenTelemetry, you must call the SetTracerProvider method on the global tracer provider object, passing in your fully configured TracerProvider instance.
Box 2: Configure a span processor to send spans to the exporter
To export OpenTelemetry traces to Azure Monitor using the Python SDK, you must configure a span processor (such as BatchExportSpanProcessor), pass your initialized Azure Monitor trace exporter to it, and register that span processor with your global tracer provider.
Box 3: Initialize the application's TracerProvider for tracing
Box 4: Call tracer.start_as_current_span()
Acquire your tracer and create spans. Example code (continued from box 2 above):
tracer = trace.get_tracer(__name__)
with tracer.start_as_current_span("hello-aca-span")
Reference:
https://learn.microsoft.com/en-us/azure/durable-task/sdks/durable-task-scheduler-opentelemetry-tracing
https://learn.microsoft.com/en-us/python/api/overview/azure/monitor-opentelemetry-exporter-readme
26. Frage
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals.
You are preparing a production deployment for an Azure Function app. The app will run across multiple environments.
The solution must support environment-specific configuration and prevent secrets from being stored in source control.
You need to develop the solution.
Solution: Store connection strings in the Function app application settings configured in the Azure Portal.
Does the solution meet the goal?
Antwort: A
Begründung:
Azure Functions application settings are the correct mechanism for keeping environment-specific configuration outside the application source code. Microsoft documents that application settings, including connection strings and other configuration values, are defined separately for each function app . This allows development, test, staging, and production deployments to use different values without modifying the application code.
At runtime, Function app settings are exposed to the application as environment variables , so code can retrieve the required connection string or configuration value without embedding it in a configuration file committed to source control. This directly satisfies the requirement to prevent secrets from being stored in the Git repository.
For production-grade secret management, Azure Key Vault references are often preferable because they provide centralized secret lifecycle management and can be combined with managed identities. However, the question asks only whether the proposed solution meets the stated goals. Storing connection strings in Azure Function application settings does satisfy both: values can vary by deployed environment and remain outside source-controlled application files.
Study Guide references: Azure Functions configuration; application settings; environment variables; secure application configuration.
27. Frage
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to configure a connection string for the partner-facing service according to the technical requirements.
What should you use?
Antwort: D
Begründung:
Technical Requirements
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
To configure the connection string securely at runtime, you should use App Service environment variables combined with Azure Key Vault references.
Runtime Resolution: When you configure an App Service environment variable using the standard @Microsoft.KeyVault(...) syntax, Azure App Service resolves the secret value dynamically at runtime.
Managed Identity Integration: The App Service automatically uses its assigned system-assigned or user-assigned Managed Identity to authenticate against Azure Key Vault. No credentials are saved locally.
Separation of Concerns: The secret value remains centrally managed in Key Vault, fulfilling the constraint that secrets must not live inside code, configuration files, or image layers.
Reference:
https://learn.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
28. Frage
......
Die Konkurrenz in der IT-Branche im 21. Jahrhundert ist sehr hart. Natürlich ist die Microsoft AI-200 Zertifizierungsprüfung zu einer sehr beliebten Prüfung im IT-Bereich geworden. Immer mehr Menschen beteiligen sich an der AI-200 Prüfung. Die Prüfung zu bestehen, ist auch der Traum der ambitionierten IT-Fachleuten.
AI-200 Deutsch Prüfung: https://www.zertfragen.com/AI-200_prufung.html