Our Designing and Implementing Multi-Agent AI Solutions (AI-500) exam dumps comes in three formats: Microsoft AI-500 PDF dumps file, desktop-based practice test software, and a web-based practice exam. These versions are specially designed to make Designing and Implementing Multi-Agent AI Solutions (AI-500) preparation for users easier. AI-500 Questions in these formats of Dumpkiller's material are enough grasp every test topic in the shortest time possible.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop multi-agent solutions in Azure | 30-35% | - Design and implement advanced prompt engineering strategies
|
| Topic 2: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security for multi-agent solutions
|
| Topic 3: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Design and implement evaluation and validation strategies
|
| Topic 4: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
In order to provide the best AI-500 test training guide for all people, our company already established the integrate quality manage system, before sell serve and promise after sale. If you buy the AI-500 preparation materials from our company, we can make sure that you will have the right to enjoy the 24 hours full-time online service on our AI-500 Exam Questions. In order to help the customers solve the problem at any moment, our server staff will be online all the time give you the suggestions on AI-500 study guide.
NEW QUESTION # 49
You have a multi-agent customer support solution in a Microsoft Foundry project.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in evaluators that provide 1 to-5 scores with pass/fail labels for the following metrics:
* The quality of the retrieved context
* How directly a response answers a query
Which evaluator should you use for each metric? To answer, drag the appropriate evaluators to the correct metrics. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.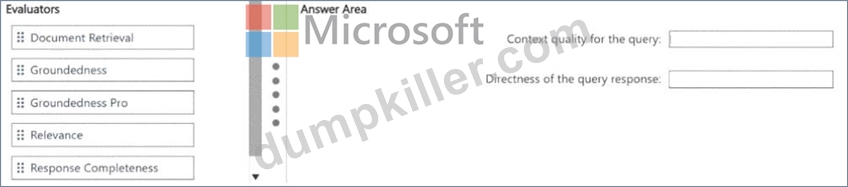
Answer:
Explanation: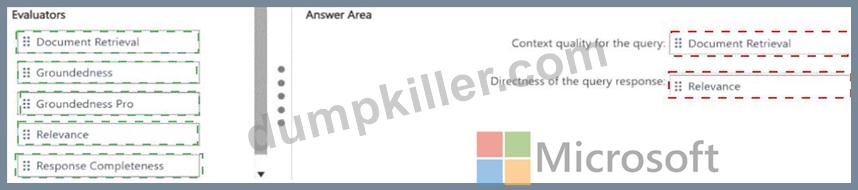
Explanation:
Quality of retrieved context: Retrieval evaluator; Directness of response to query: Relevance evaluator.
The dataset contains query, context, and response but does not contain document relevance labels. Microsoft ' s Retrieval evaluator is designed for exactly that situation: it uses an LLM judge to rate how relevant the retrieved context chunks are to the query and returns a 1-to-5 score with pass/fail behavior. The Relevance evaluator operates on the final response and measures whether the answer accurately, completely, and directly addresses the query. Document Retrieval is not appropriate because it requires retrieval ground truth such as known relevant documents or qrels. Groundedness answers a different question: whether response claims are supported by the provided context. Therefore the correct mapping is Retrieval for context quality and Relevance for response directness. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators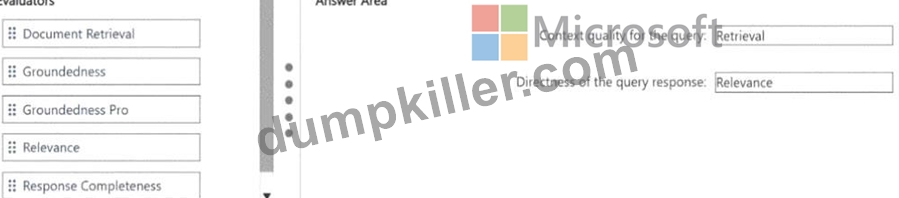
NEW QUESTION # 50
You have a Microsoft Foundry project that includes four independent analysis agents. Each agent invocation consumes 500 tokens per minute (TPM) from a Foundry deployment that has a TPM rate limit of 1,000.
After each agent completes, it writes 200 small records to Microsoft Dataverse. Running multiple agents simultaneously causes write bursts that result in HTTP 429 (Too Many Requests) responses.
You need to reduce the end-to-end task duration, while preventing provider and platform throttling. The solution must meet the following requirements:
* Keep as much agent parallelism as the TPM rate limit permits.
* Handle Dataverse throttling without sending premature retries.
How should you configure the orchestration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.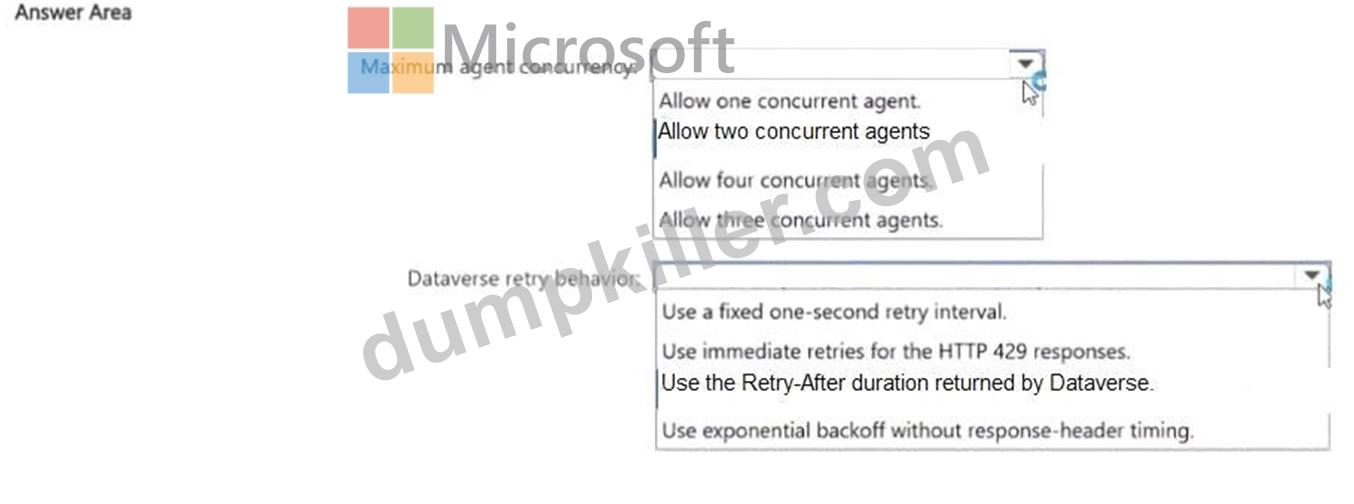
Answer:
Explanation: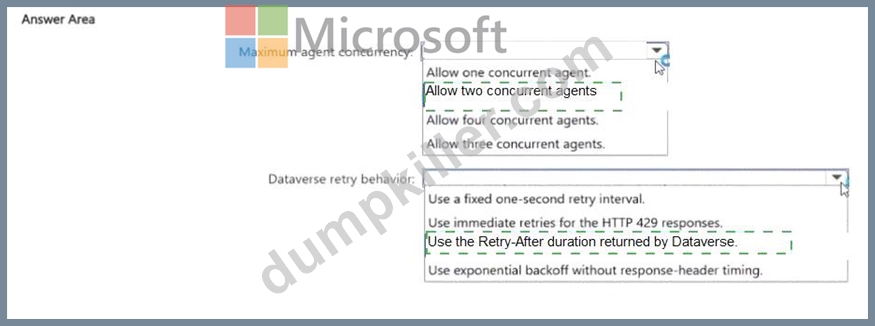
Explanation:
Maximum agent concurrency: Two agents; Dataverse retry behavior: Respect the Retry-After duration returned by Dataverse.
Each analysis agent consumes 500 TPM and the deployment permits 1,000 TPM, so at most two agents can run simultaneously without exceeding the stated model limit. Running only one wastes available parallelism; running three or four violates the limit. The separate Dataverse problem is HTTP 429 service-protection throttling. Microsoft Dataverse returns a `Retry-After` duration that tells clients how long to wait before retrying. Respecting that value prevents premature retries from worsening the overload condition. A fixed retry interval or immediate retry ignores the server ' s current capacity signal. The orchestration should therefore cap model-side concurrency at two and, after each agent finishes, pace Dataverse writes according to the returned retry guidance. This combination minimizes task duration while honoring both provider and platform throttling constraints. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Dataverse service protection API limits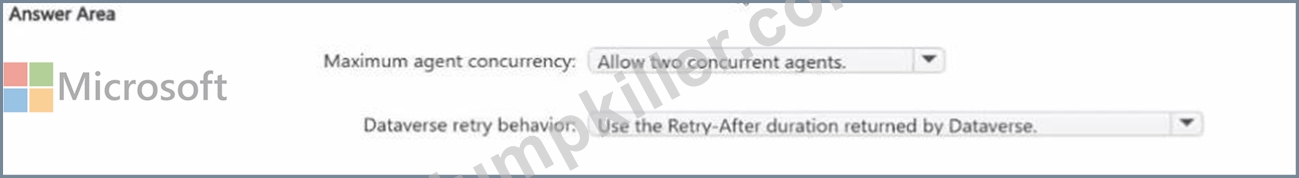
NEW QUESTION # 51
You have a Microsoft Foundry multi-agent customer support solution that retrieves grounding data from a shared vector index. The indexed corpus contains product runbooks in Markdown and support articles in HTML Both document types use a consistent hierarchical markup.
You discover that current fixed-size token chunking creates chunks that cross section boundaries.
You need to recommend a chunking approach for the ingestion pipeline. The solution must preserve existing document structure boundaries and minimize custom chunking code.
What should you recommend?
Answer: A
Explanation:
The corpus already contains reliable document hierarchy in Markdown and HTML, so the ingestion pipeline should preserve those author-defined boundaries rather than infer new ones from token counts or topic shifts.
Format-specific header splitters can divide Markdown by heading levels and HTML by structural headers, producing chunks that align with meaningful sections. This directly solves the current problem of fixed-size token chunks crossing section boundaries and requires less custom logic than building a semantic topic-shift chunker. Recursive character splitting can be configured with structure-aware separators, but it remains a more generic fallback when format-specific structure is already available. Microsoft Azure AI Search guidance recommends exploiting document structure such as headings when chunking. Therefore B is the most direct and maintainable approach. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure AI Search - structure-aware chunking and Markdown indexing
NEW QUESTION # 52
Solution: Use separate a managed identity for each agent and environment Assign Azure roles at the resource level. Does this meet the goal?
Answer: A
Explanation:
Separate managed identities for each agent and environment remove the need to store application secrets and create independent authorization boundaries. Assigning Azure roles at the resource level further limits each identity to only the Storage resource it requires. This sharply reduces lateral movement compared with a shared application principal or subscription-wide role. Microsoft Foundry and Azure identity guidance consistently recommend identity-based authentication, distinct identities when permissions differ, and the narrowest practical RBAC scope. In current Foundry deployments, the exact identity object may be represented through Microsoft Entra agent identity or a federated managed identity relationship, but the architectural principle in the option is correct. Therefore the solution meets both stated goals and the answer is A, Yes. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry agent identity
NEW QUESTION # 53
You have a Microsoft Foundry agent that completes benefits enrollment during a single user conversation The agent collects the required enrollment fields during 15 turns. Users can correct earlier values before final submission. The current implementation sends the complete transcript with every model request.
You need to change the context accumulation strategy for the active enrollment. The solution must meet the following requirements:
* Preserve the latest value for each required enrollment field until submission.
* Bound the maximum number of tokens sent with each model request
* Preserve user corrections until submission.
* Prevent durable cross-session memory.
What should you do?
Answer: C
Explanation:
The application must preserve the latest authoritative value of each enrollment field even when the user corrects an earlier value, while also placing a firm bound on prompt size. A session-scoped enrollment-state snapshot provides deterministic structured state: each correction overwrites the previous field value. A recent- turn sliding window then preserves enough conversational context for natural interaction without resending the full 15-turn transcript. Response chaining with a fixed number of prior turns can lose an important field once it falls outside the retained history. Summarization can omit or distort corrected values, and automatic truncation likewise offers no guarantee that the latest value of every required field survives. Because the state is scoped only to the active enrollment and is not written to long-term memory, the design also avoids durable cross-session memory. Therefore A is correct. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Agent Framework - workflow state and context management
NEW QUESTION # 54
......
There are three different versions provided by our company. Every version is very convenient and practical. The three different versions of our AI-500 study torrent have different function. Now I am willing to show you the special function of the PDF version of AI-500 test torrent. If you prefer to read paper materials rather than learning on computers, the PDF version of our AI-500 Guide Torrent must the best choice for you. Because the study materials on the PDF version are printable, you can download our AI-500 study torrent by the PDF version and print it on papers.
Latest AI-500 Dumps Ebook: https://www.dumpkiller.com/AI-500_braindumps.html