100% Pass Quiz Databricks - Databricks-Certified-Data-Engineer-Professional Perfect Exam Engine

As a worldwide leader in offering the best Databricks-Certified-Data-Engineer-Professional test torrent, we are committed to providing comprehensive service to the majority of consumers and strive for constructing an integrated service. What's more, we have achieved breakthroughs in Databricks-Certified-Data-Engineer-Professional certification training application as well as interactive sharing and after-sales service. As a matter of fact, our company takes account of every client's difficulties with fitting solutions. As long as you need help, we will offer instant support to deal with any of your problems about our Databricks-Certified-Data-Engineer-Professional Guide Torrent to help you pass the Databricks-Certified-Data-Engineer-Professional exam.
| Section | Objectives |
|---|
| Topic 1: Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader
- ETL pipeline design patterns
- Structured Streaming fundamentals
|
| Topic 2: Data Modeling and Transformation | - Performance optimization techniques
- Dimensional modeling concepts
- Spark SQL transformations
|
| Topic 3: Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics)
- Medallion architecture (Bronze, Silver, Gold)
- Workspace and cluster architecture
|
| Topic 4: Production Pipelines and Orchestration | - Error handling and recovery strategies
- Job scheduling and monitoring
- Databricks Workflows
|
| Topic 5: Delta Lake and Data Management | - Schema evolution and enforcement
- Time travel and versioning
- Delta Lake transactions and ACID properties
|
>> Databricks-Certified-Data-Engineer-Professional Exam Engine <<
Databricks-Certified-Data-Engineer-Professional Latest Exam Cram, Exam Databricks-Certified-Data-Engineer-Professional Tutorial
In accordance with the actual exam, we provide the latest Databricks-Certified-Data-Engineer-Professional exam dumps for your practices. With the latest Databricks-Certified-Data-Engineer-Professional test questions, you can have a good experience in practicing the test. Moreover, you have no need to worry about the price, we provide free updating for one year and half price for further partnerships, which is really a big sale in this field. After your payment, we will send the updated Databricks-Certified-Data-Engineer-Professional Exam to you immediately and if you have any question about updating, please leave us a message on our Databricks-Certified-Data-Engineer-Professional exam questions.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q219-Q224):
NEW QUESTION # 219
A new data engineer notices that a critical field was omitted from an application that writes its Kafka source to Delta Lake. This happened even though the critical field was in the Kafka source.
That field was further missing from data written to dependent, long-term storage. The retention threshold on the Kafka service is seven days. The pipeline has been in production for three months.
Which describes how Delta Lake can help to avoid data loss of this nature in the future?
- A. Ingestine all raw data and metadata from Kafka to a bronze Delta table creates a permanent, replayable history of the data state.
- B. Data can never be permanently dropped or deleted from Delta Lake, so data loss is not possible under any circumstance.
- C. The Delta log and Structured Streaming checkpoints record the full history of the Kafka producer.
- D. Delta Lake schema evolution can retroactively calculate the correct value for newly added fields, as long as the data was in the original source.
- E. Delta Lake automatically checks that all fields present in the source data are included in the ingestion layer.
Answer: A
Explanation:
This is the correct answer because it describes how Delta Lake can help to avoid data loss of this nature in the future. By ingesting all raw data and metadata from Kafka to a bronze Delta table, Delta Lake creates a permanent, replayable history of the data state that can be used for recovery or reprocessing in case of errors or omissions in downstream applications or pipelines.
Delta Lake also supports schema evolution, which allows adding new columns to existing tables without affecting existing queries or pipelines. Therefore, if a critical field was omitted from an application that writes its Kafka source to Delta Lake, it can be easily added later and the data can be reprocessed from the bronze table without losing any information.
NEW QUESTION # 220
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline. Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
- A. Use list pipelines to get the specs for all pipelines; get the pipeline spec from the return results parse and use this to create a pipeline
- B. Use the get command to capture the settings for the existing pipeline; remove the pipeline_id and rename the pipeline; use this in a create command
- C. Stop the existing pipeline; use the returned settings in a reset command
- D. Use the alone command to create a copy of an existing pipeline; use the get JSON command to get the pipeline definition; save this to git
Answer: B
Explanation:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use the databricks pipelines get --pipeline-id command to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing the pipeline_id to prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines create command to create a new pipeline with those settings.
NEW QUESTION # 221
Predictive Optimization is an automated Databricks service enabled by default for Unity Catalog Managed tables. It helps maintain Delta tables by continuously optimizing them to ensure optimal performance and costs. Which two operations does Predictive Optimization run to maintain the Delta tables? (Choose two.)
- A. PARTITION BY
- B. OPTIMIZE
- C. COMPACT
- D. ANALYZE
- E. BUCKETING
Answer: B,D
Explanation:
Predictive Optimization automatically runs OPTIMIZE to compact small files and improve data layout, and ANALYZE to collect and refresh table statistics. Together, these operations ensure efficient query planning, better data skipping, and optimized performance and cost for Unity Catalog managed Delta tables.
NEW QUESTION # 222
A data engineer is designing a pipeline in Databricks that processes records from a Kafka stream where late-arriving data is common. Which approach should the data engineer use?
- A. Use batch processing and overwrite the entire output table each time to ensure late data is incorporated correctly.
- B. Implement a custom solution using Databricks Jobs to periodically reprocess all historical data.
- C. Use an Auto CDC pipeline with batch tables to simplify late data handling.
- D. Use a watermark to specify the allowed lateness to accommodate records that arrive after their expected window, ensuring correct aggregation and state management.
Answer: D
Explanation:
In Structured Streaming, event-time watermarks control how long the engine waits for late- arriving data before finalizing aggregations. By setting an appropriate watermark, Databricks can handle late data gracefully -- incorporating records that arrive within the defined window while discarding excessively delayed events.
This approach ensures accurate aggregations, minimizes state size, and prevents memory leaks.
Manual reprocessing (A) or overwriting entire datasets (B) is inefficient and costly, while Auto CDC (C) is used for change tracking in Delta tables, not for streaming event lateness.
Thus, using watermarking is the recommended and official approach for managing late data in streaming pipelines.
NEW QUESTION # 223
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.
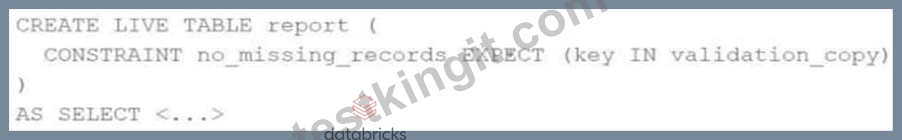
Which approach would allow using DLT expectations to validate all expected records are present in this table?
- A. Define a function that performs a left outer join on validation_copy and report and report, and check against the result in a DLT expectation for the report table
- B. Define a temporary table that perform a left outer join on validation_copy and report, and define an expectation that no report key values are null
- C. Define a view that performs a left outer join on validation_copy and report, and reference this view in DLT expectations for the report table
- D. Define a SQL UDF that performs a left outer join on two tables, and check if this returns null values for report key values in a DLT expectation for the report table.
Answer: C
Explanation:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
NEW QUESTION # 224
......
What is more, we have free demos are freebies for your information. In case you are tentative about their quality, we give these demos form which you could get the brief outline and questions closely related with the Databricks-Certified-Data-Engineer-Professional practice materials. Only by practising them on a regular base, you will see clear progress happened on you. Besides, rather than waiting for the gain of our Databricks-Certified-Data-Engineer-Professional practice materials, you can download them immediately after paying for it, so just begin your journey toward success now.
Databricks-Certified-Data-Engineer-Professional Latest Exam Cram: https://www.testkingit.com/Databricks/latest-Databricks-Certified-Data-Engineer-Professional-exam-dumps.html
- Databricks-Certified-Data-Engineer-Professional Dump with the Help of www.validtorrent.com Exam Questions ↖ The page for free download of 《 Databricks-Certified-Data-Engineer-Professional 》 on “ www.validtorrent.com ” will open immediately 🐹Databricks-Certified-Data-Engineer-Professional Passguide
- Databricks-Certified-Data-Engineer-Professional New Exam Materials 🌑 Valid Databricks-Certified-Data-Engineer-Professional Test Duration 🍗 Databricks-Certified-Data-Engineer-Professional Dump 🛺 Immediately open ➤ www.pdfvce.com ⮘ and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ to obtain a free download 📔Databricks-Certified-Data-Engineer-Professional Dumps Cost
- Exam Databricks-Certified-Data-Engineer-Professional Learning 🏃 Databricks-Certified-Data-Engineer-Professional Intereactive Testing Engine 🦱 Databricks-Certified-Data-Engineer-Professional Exam Brain Dumps 🏚 Search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 and download it for free immediately on ▶ www.practicevce.com ◀ 🚹Latest Test Databricks-Certified-Data-Engineer-Professional Simulations
- Valid Databricks-Certified-Data-Engineer-Professional Exam Simulator 🐎 Valid Databricks-Certified-Data-Engineer-Professional Test Duration 😙 Reliable Databricks-Certified-Data-Engineer-Professional Test Topics 🖐 Search for “ Databricks-Certified-Data-Engineer-Professional ” on 「 www.pdfvce.com 」 immediately to obtain a free download 🐑Exam Databricks-Certified-Data-Engineer-Professional Learning
- Quiz Databricks - Databricks-Certified-Data-Engineer-Professional –Professional Exam Engine 🅾 Simply search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ for free download on ➽ www.dumpsquestion.com 🢪 📷Databricks-Certified-Data-Engineer-Professional Exam Brain Dumps
- Databricks-Certified-Data-Engineer-Professional Original Questions - Databricks-Certified-Data-Engineer-Professional Training Online - Databricks-Certified-Data-Engineer-Professional Dumps Torrent 🌌 Download ▷ Databricks-Certified-Data-Engineer-Professional ◁ for free by simply entering ➥ www.pdfvce.com 🡄 website 🏜New Databricks-Certified-Data-Engineer-Professional Test Discount
- Databricks-Certified-Data-Engineer-Professional Exam Engine 100% Pass | Valid Databricks Databricks Certified Data Engineer Professional Exam Latest Exam Cram Pass for sure 💗 ▛ www.troytecdumps.com ▟ is best website to obtain ➠ Databricks-Certified-Data-Engineer-Professional 🠰 for free download 🌟Databricks-Certified-Data-Engineer-Professional Dump
- Valid Databricks-Certified-Data-Engineer-Professional Test Cost ⚗ Latest Test Databricks-Certified-Data-Engineer-Professional Simulations ⛺ Valid Databricks-Certified-Data-Engineer-Professional Test Cost 🧖 Search on “ www.pdfvce.com ” for ▶ Databricks-Certified-Data-Engineer-Professional ◀ to obtain exam materials for free download 🏥Databricks-Certified-Data-Engineer-Professional Test Dumps Demo
- Databricks-Certified-Data-Engineer-Professional New Study Questions 🍵 Valid Databricks-Certified-Data-Engineer-Professional Test Cost 🧕 Databricks-Certified-Data-Engineer-Professional Exam Brain Dumps ⌛ Search for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ and download it for free immediately on ➽ www.pass4test.com 🢪 ⛅Databricks-Certified-Data-Engineer-Professional Exam Syllabus
- Databricks Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam Marvelous Exam Engine 🐉 Open ➡ www.pdfvce.com ️⬅️ enter ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ and obtain a free download 🩸Valid Databricks-Certified-Data-Engineer-Professional Test Cost
- Databricks-Certified-Data-Engineer-Professional Exam Engine 100% Pass | Valid Databricks Databricks Certified Data Engineer Professional Exam Latest Exam Cram Pass for sure 🕧 [ www.prepawaypdf.com ] is best website to obtain ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ for free download 👄Databricks-Certified-Data-Engineer-Professional New Exam Materials
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, everlink.tools, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes