To be the best global supplier of electronic DP-750 study materials for our customers through innovation and enhancement of our customers' satisfaction has always been our common pursuit. The advantages of our DP-750 guide dumps are too many to count. And the most important point is that the pass rate of our DP-750 learning quiz is preety high as 98% to 99%. I guess this is also the candidates care most as well. You can totally trust in our DP-750 exam questions!
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
While making revisions and modifications to the Microsoft DP-750 practice exam, our team takes reports from over 90,000 professionals worldwide to make the Microsoft DP-750 Exam Questions foolproof. To make you capable of preparing for the DP-750 exam smoothly, we provide actual Microsoft DP-750 exam dumps.
NEW QUESTION # 41
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Payments.
Payments stores transaction data and contains a column named payment_amount of the Decimal data type.
You must enforce the following business rule:
payment_amount must be between 0 and 10,000, inclusive
You need to ensure that records that violate the rule are rejected when data is written to the Payments table.
What should you do?
Answer: B
Explanation:
A CHECK constraint enforces a Boolean condition whenever data is inserted or updated. The constraint can require payment_amount > = 0 AND payment_amount < = 10000, causing a transaction containing an invalid value to fail instead of allowing the record into Payments. This provides storage-level data-quality enforcement regardless of which pipeline, notebook, or SQL statement performs the write. Row-level security controls which existing records users can see; it does not reject invalid writes. SELECT statements filter results only when they are executed and therefore cannot protect the underlying table. Table update triggers are not the standard Delta Lake mechanism for this requirement. Azure Databricks classifies CHECK constraints as enforced constraints and rejects transactions when their conditions are violated. Microsoft Learn
NEW QUESTION # 42
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Tabid.
Table! is written by batch jobs every hour and is queried frequently by filtering two columns named Customerld and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.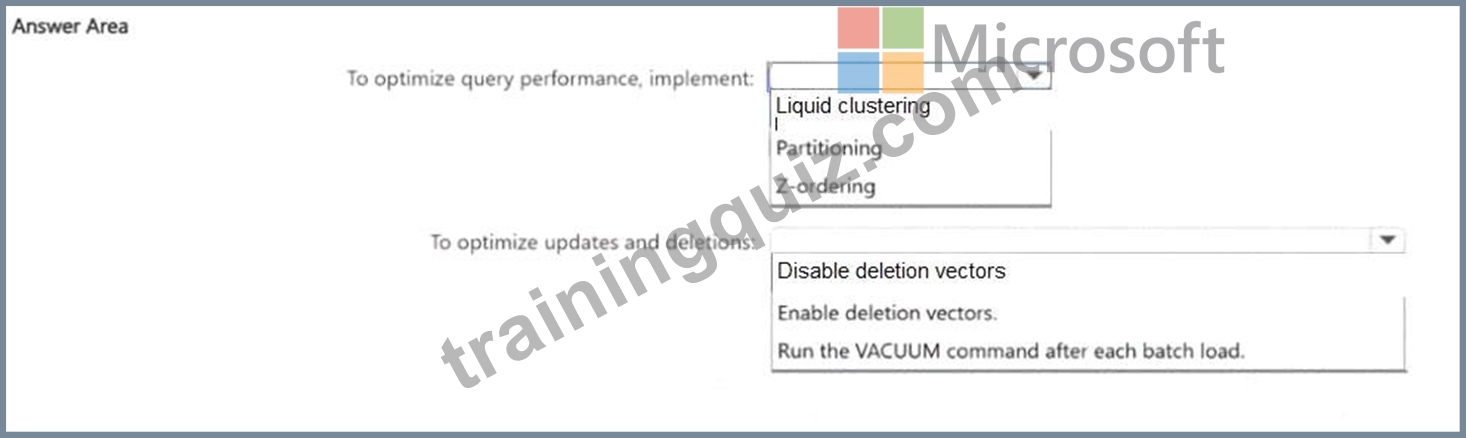
Answer:
Explanation: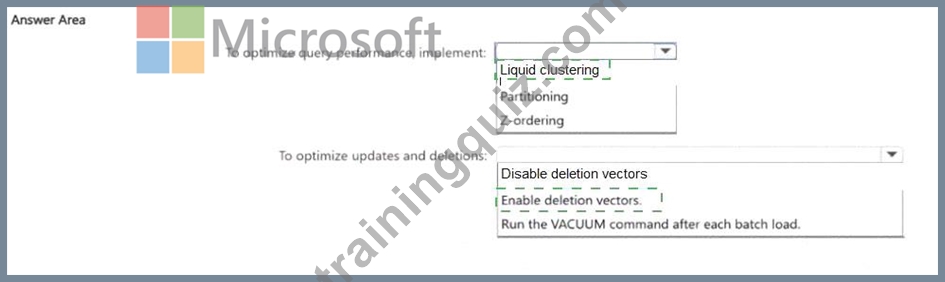
Explanation:
Two features work together to keep performance consistent and update costs low:
OPTIMIZE with ZORDER BY (CustomerId, EventDate). Z-Ordering co-locates rows with the same CustomerId and EventDate values in the same Parquet files. When a query filters on those columns, the Delta engine uses file statistics to skip files that can't possibly contain matching rows (data skipping). As the table grows, skipping scales proportionally - query time stays consistent.
Deletion Vectors (delta.enableDeletionVectors = true). When a row is updated or deleted, instead of rewriting the entire Parquet file, Delta marks the affected row in a small companion deletion vector file. This dramatically reduces write amplification for the frequent compliance-driven updates and deletions the question describes. Actual file rewrites are deferred to the next OPTIMIZE run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/data-skipping
NEW QUESTION # 43
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Sales_orders.
Sales_orders stores historical sales data.
You receive a daily CSV file daily that contains new sales records only. The file does NOT contain updates to existing rows.
You need to load the daily data into Sales_orders. The solution must meet the following requirements:
- Preserve the existing data.
- Add only the new records.
- Minimize processing effort.
Which command should include in the loading strategy?
Answer: A
Explanation:
The best command for this scenario is INSERT INTO.
The INSERT INTO command appends new rows directly to the end of an existing Delta table.
Because your daily CSV file contains only new records and zero updates to existing rows, simply appending the data completely satisfies your requirements. It leaves all historical data untouched and requires the absolute lowest processing power because Databricks does not need to scan, modify, or rewrite any existing files.
Incorrect:
The UPDATE command is used to modify values in rows that already exist in the table based on a matching condition. It cannot be used to add entirely new rows to a table, and it requires a heavy scan of the data to find matches, which violates the requirement to keep processing low.
The INSERT OVERWRITE command deletes all the existing historical data in the table (or a specific partition) and replaces it with the data from the new CSV file. Using this would erase your historical sales data.
Reference:
https://medium.com/@jithujosekokken/understanding-data-patterns-in-medallion-architecture-full- incremental-and-change-only-loads-e33db28e51f4
NEW QUESTION # 44
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a new native catalog in Unity Catalog.
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
NEW QUESTION # 45
You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
What should you do?
Answer: A
Explanation:
The correct answer is D. Breaking the pipeline into separate tasks for ingestion, cleansing, and curation is the foundation of well-designed Lakeflow Jobs pipelines. Each task should own one responsibility - when a task does too much, debugging a failure becomes a hunt through unrelated code, and retry logic becomes expensive because you re-execute work that already succeeded.
Contoso ' s planned changes explicitly call for ' a clear execution order and dependencies ' and ' orchestrate multi-step ingestion and transformation workflows. ' Separate tasks map directly to those goals: Lakeflow Jobs tracks each task ' s status independently, so if cleansing fails, ingestion doesn ' t re-run.
Option A bundles everything into one notebook, which means a curation bug forces a full re-ingestion. Option B copies logic three times - any future change must be applied in triplicate, which is a maintenance hazard.
Option C forces everything through SQL MERGE, which is the wrong tool for raw-event ingestion and doesn
' t address cleansing or schema drift.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/
NEW QUESTION # 46
......
It is inescapable choice to make why don't you choose our DP-750 study quiz with passing rate up to 98-100 percent. You can have a sweeping through of our DP-750 guide materials with intelligibly and under-stable contents. It is time to take the plunge and you will not feel depressed. All incomprehensible issues will be small problems and all contents of the DP-750 Exam Questions will be printed on your minds. And you will pass the exam easily.
DP-750 Review Guide: https://www.trainingquiz.com/DP-750-practice-quiz.html