Now it is wise choice for you to choose our Databricks-Certified-Data-Engineer-Professional actual test guide materials. Valid exam questions help you study and prepare double results with half works. You will get high-quality 100% pass rate Databricks-Certified-Data-Engineer-Professional learning prep so that you can master the key knowledge and clear exam easily. You can Pass Databricks-Certified-Data-Engineer-Professional Exam in the shortest time and obtain a certification soon. It will benefit you more. Instead of admiring others' redoubtable life, start your new life from choosing valid test dumps. Our Databricks-Certified-Data-Engineer-Professional actual test guide is the pass king in this field which will be the best option for you.
| Section | Weight | Objectives |
|---|---|---|
| Ensuring Data Security and Compliance | 10% | - Implement access control and permissions - Secure data at rest and in transit - Ensure data privacy and compliance |
| Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming - Handle incremental and batch data loads - Ingest data from diverse sources |
| Data Sharing and Federation | 5% | - Implement Lakehouse Federation - Manage cross-platform data access - Use Delta Sharing for secure data sharing |
| Data Modelling | 6% | - Implement dimensional and relational models - Design Medallion Architecture - Optimize table design and partitioning |
| Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code - Use Databricks-specific libraries and APIs - Implement complex data processing logic |
| Data Transformation, Cleansing, and Quality | 10% | - Apply data cleansing and validation rules - Implement schema evolution and management - Enforce data quality standards |
| Data Governance | 7% | - Enforce data policies and standards - Use Unity Catalog for governance - Manage data assets and metadata |
| Debugging and Deploying | 10% | - Troubleshoot and debug pipelines - Implement CI/CD and DevOps practices - Deploy using Asset Bundles, CLI, and APIs |
| Cost & Performance Optimisation | 13% | - Improve query and pipeline performance - Apply cost management best practices - Optimize compute and storage resources |
| Monitoring and Alerting | 10% | - Monitor pipeline performance and health - Track data lineage and metrics - Set up alerts and notifications |
>> Databricks-Certified-Data-Engineer-Professional Valid Exam Labs <<
If you buy online classes, you will need to sit in front of your computer on time at the required time; if you participate in offline counseling, you may need to take an hour or two on the commute to class. But if you buy Databricks-Certified-Data-Engineer-Professional exam material, things will become completely different. Databricks Certified Data Engineer Professional Exam study questions will provide you with very flexible learning time. Unlike other learning materials on the market, Databricks-Certified-Data-Engineer-Professional exam guide has an APP version. You can download our app on your mobile phone. And then, you can learn anytime, anywhere. Whatever where you are, whatever what time it is, just an electronic device, you can practice. With Databricks Certified Data Engineer Professional Exam study questions, you no longer have to put down the important tasks at hand in order to get to class; with Databricks-Certified-Data-Engineer-Professional Exam Guide, you don’t have to give up an appointment for study. Our study materials can help you to solve all the problems encountered in the learning process, so that you can easily pass the exam.
NEW QUESTION # 221
A streaming video analytics team ingests billions of events daily into a Unity Catalog-managed Delta table video_events. Analysts run ad-hoc point-lookup queries on columns like user_id, campaign_id, and region. The team manually runs OPTIMIZE video_events ZORDER BY (user_id, campaign_id, region), but still sees poor performance on recent data and dislikes the operational overhead. The team wants a hands-off way to keep hot columns co-located as query patterns evolve. Which Delta capability should the team leverage on video_events?
Answer: D
Explanation:
According to Databricks Delta Lake optimization documentation, Liquid Clustering is a next- generation file organization capability that automatically manages file co-location without requiring explicit partitioning or manual Z-ORDERing. When combined with Predictive Optimization, Databricks automatically maintains clustering across frequently filtered or queried columns, adapting dynamically as query workloads evolve.
This approach eliminates the need for manual maintenance (such as periodic OPTIMIZE or Z- ORDER commands) while improving query performance on large tables--particularly for high- ingest streaming workloads.
Delta caching (B) only improves performance for cached queries and does not address file layout issues, and (D) handles file size optimization but not clustering. Thus, C is the most efficient, modern, and low-maintenance solution recommended by Databricks.
NEW QUESTION # 222
A data engineer is developing a Lakeflow Declarative Pipeline (LDP) using a Databricks notebook directly connected to their pipeline. After adding new table definitions and transformation logic in their notebook, they want to check for any syntax errors in the pipeline code without actually processing data or running the pipeline. How should the data engineer perform this syntax check?
Answer: D
Explanation:
Databricks provides a "Validate" option within the Lakeflow Declarative Pipeline development interface that checks pipeline configurations, transformations, and syntax errors before actual execution.
This feature parses and validates the pipeline logic defined in notebooks or workspace files to ensure correctness and consistency of table dependencies, DLT (Delta Live Table) syntax, and schema references.
The validation process does not process or move any data, making it ideal for testing new configurations before deployment.
Using the shell terminal (B) or workspace files (D) does not perform integrated pipeline-level validation, while reconnecting to compute clusters (C) is unrelated to syntax checks. Therefore, the verified and correct approach is A.
NEW QUESTION # 223
A data engineer is troubleshooting a slow-running Delta Lake query on Databricks SQL involves complex joins and large datasets. They need to identify whether the root cause is related to poor data skipping, inefficient join strategies, or excessive data shuffling. Which approach should identify the specific bottlenecks using native Databricks tools?
Answer: A
Explanation:
The Query Profile's Top Operators panel surfaces the most expensive operators in the query execution, making it possible to directly identify bottlenecks such as inefficient join strategies, poor data skipping, or excessive shuffling. This native visualization highlights where time and resources are spent, enabling precise root-cause analysis for slow-running queries.
NEW QUESTION # 224
To reduce storage and compute costs, the data engineering team has been tasked with curating a series of aggregate tables leveraged by business intelligence dashboards, customer-facing applications, production machine learning models, and ad hoc analytical queries.
The data engineering team has been made aware of new requirements from a customer-facing application, which is the only downstream workload they manage entirely. As a result, an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added.
Which of the solutions addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed?
Answer: C
Explanation:
This is the correct answer because it addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed. The situation is that an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added, due to new requirements from a customer-facing application. By configuring a new table with all the requisite fields and new names and using this as the source for the customer-facing application, the data engineering team can meet the new requirements without affecting other teams that rely on the existing table schema and name. By creating a view that maintains the original data schema and Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from table name by aliasing select fields from the new table, the data engineering team can also avoid duplicating data or creating additional tables that need to be managed.
NEW QUESTION # 225
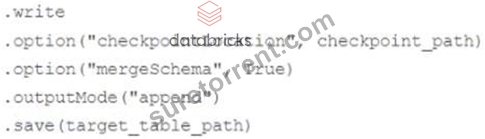
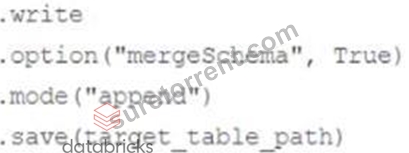
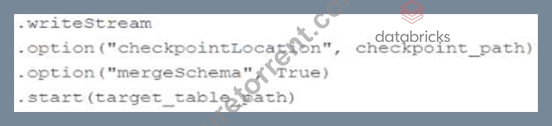
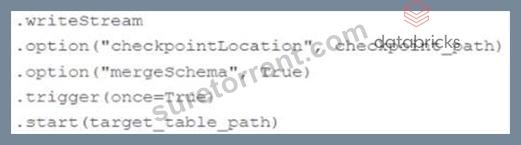
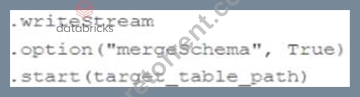
In order to facilitate near real-time workloads, a data engineer is creating a helper function to leverage the schema detection and evolution functionality of Databricks Auto Loader. The desired function will automatically detect the schema of the source directly, incrementally process JSON files as they arrive in a source directory, and automatically evolve the schema of the table when new fields are detected.
The function is displayed below with a blank: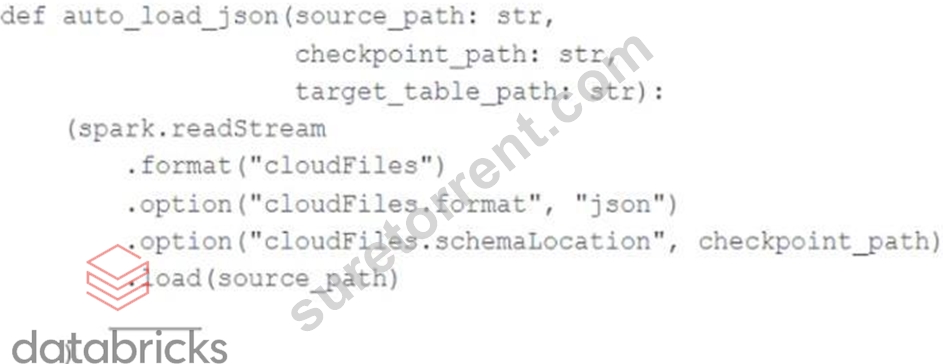
Which response correctly fills in the blank to meet the specified requirements?
Answer: C
Explanation:
https://docs.databricks.com/en/ingestion/auto-loader/schema.html
NEW QUESTION # 226
......
To help you prepare for Databricks-Certified-Data-Engineer-Professional examination certification, we provide you with a sound knowledge and experience. The questions designed by SureTorrent can help you easily pass the exam. The SureTorrent Databricks Databricks-Certified-Data-Engineer-Professional practice including Databricks-Certified-Data-Engineer-Professional exam questions and answers, Databricks-Certified-Data-Engineer-Professional test, Databricks-Certified-Data-Engineer-Professional books, Databricks-Certified-Data-Engineer-Professional study guide.
Valid Braindumps Databricks-Certified-Data-Engineer-Professional Ebook: https://www.suretorrent.com/Databricks-Certified-Data-Engineer-Professional-exam-guide-torrent.html