DOWNLOAD the newest ExamBoosts ACD-301 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1xdB2rFzurSSLE4QPJFFe9PEaa4f4uf7i
Appian Certified Lead Developer (ACD-301) exam dumps offers are categorized into several categories, so you can find the one that's right for you. ACD-301 practice exam software uses the same testing method as the real ACD-301 exam. With ACD-301 exam questions, you can prepare for your Appian Certified Lead Developer (ACD-301) certification exam. Job proficiency can be evaluated through ACD-301 Exam Dumps that include questions that relate to a company's ideal personnel. These Appian ACD-301 practice test feature questions similar to conventional scenarios, making scoring questions especially applicable for entry-level recruits and mid-level executives.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Scalability and Performance Design | 20% | - Troubleshoot application-level performance bottlenecks - Design and build high-performance components - Plan and execute load testing and monitoring |
| Topic 2: Platform & Solution Architecture | 15% | - Understand enterprise platform architecture - Manage deployments and environment configurations - Make architecture decisions for maintainability and scalability |
| Topic 3: Application Design and Development | 25% | - Apply best practices for multi-application development - Design applications with reusability and consistency - Evaluate how Appian meets user requirements |
| Topic 4: Data Management | 25% | - Design secure and efficient data models - Leverage Data Fabric, data types, and migration strategies - Troubleshoot complex data and database performance issues |
| Topic 5: Extending Appian & Integrations | 15% | - Troubleshoot integration and API errors - Implement authentication and secure integrations - Design advanced APIs and connected systems |
When it comes to the practice material, many writers did not think of the diversity of needs from exam candidates, and this was inconvenient for them. However, our ACD-301 torrent prep respects your inclination and preference of practice materials. PDF version being legible to read and remember, support customers’ printing request, and allow you to have a print and practice in papers. Software version of ACD-301 Exam Questions supports simulation test system. Remember this version support Windows system users only.
NEW QUESTION # 36
You need to generate a PDF document with specific formatting. Which approach would you recommend?
Answer: A
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, generating a PDF with specific formatting is a common requirement, and Appian provides several tools to achieve this. The question emphasizes "specific formatting," which implies precise control over layout, styling, and content structure. Let's evaluate each option based on Appian's official documentation and capabilities:
A . Create an embedded interface with the necessary content and ask the user to use the browser "Print" functionality to save it as a PDF:
This approach involves designing an interface (e.g., using SAIL components) and relying on the browser's native print-to-PDF feature. While this is feasible for simple content, it lacks precision for "specific formatting." Browser rendering varies across devices and browsers, and print styles (e.g., CSS) are limited in Appian's control. Appian Lead Developer best practices discourage relying on client-side functionality for critical document generation due to inconsistency and lack of automation. This is not a recommended solution for a production-grade requirement.
B . Use the PDF from XSL-FO Transformation smart service to generate the content with the specific format:
This is the correct choice. The "PDF from XSL-FO Transformation" smart service (available in Appian's process modeling toolkit) allows developers to generate PDFs programmatically with precise formatting using XSL-FO (Extensible Stylesheet Language Formatting Objects). XSL-FO provides fine-grained control over layout, fonts, margins, and styling-ideal for "specific formatting" requirements. In a process model, you can pass XML data and an XSL-FO stylesheet to this smart service, producing a downloadable PDF. Appian's documentation highlights this as the preferred method for complex PDF generation, making it a robust, scalable, and Appian-native solution.
C . Use the Word Doc from Template smart service in a process model to add the specific format:
This option uses the "Word Doc from Template" smart service to generate a Microsoft Word document from a template (e.g., a .docx file with placeholders). While it supports formatting defined in the template and can be converted to PDF post-generation (e.g., via a manual step or external tool), it's not a direct PDF solution. Appian doesn't natively convert Word to PDF within the platform, requiring additional steps outside the process model. For "specific formatting" in a PDF, this is less efficient and less precise than the XSL-FO approach, as Word templates are better suited for editable documents rather than final PDFs.
D . There is no way to fulfill the requirement using Appian. Suggest sending the content as a plain email instead:
This is incorrect. Appian provides multiple tools for document generation, including PDFs, as evidenced by options B and C. Suggesting a plain email fails to meet the requirement of generating a formatted PDF and contradicts Appian's capabilities. Appian Lead Developer training emphasizes leveraging platform features to meet business needs, ruling out this option entirely.
Conclusion: The PDF from XSL-FO Transformation smart service (B) is the recommended approach. It provides direct PDF generation with specific formatting control within Appian's process model, aligning with best practices for document automation and precision. This method is scalable, repeatable, and fully supported by Appian's architecture.
Appian Documentation: "PDF from XSL-FO Transformation Smart Service" (Process Modeling > Smart Services).
Appian Lead Developer Certification: Document Generation Module (PDF Generation Techniques).
Appian Best Practices: "Generating Documents in Appian" (XSL-FO vs. Template-Based Approaches).
NEW QUESTION # 37
Your team has deployed an application to Production with an underperforming view. Unexpectedly, the production data is ten times that of what was tested, and you must remediate the issue. What is the best option you can take to mitigate their performance concerns?
Answer: A
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, addressing performance issues in production requires balancing Appian's best practices, scalability, and maintainability. The scenario involves an underperforming view due to a significant increase in data volume (ten times the tested amount), necessitating a solution that optimizes performance while adhering to Appian's architecture. Let's evaluate each option:
A . Bypass Appian's query rule by calling the database directly with a SQL statement:
This approach involves circumventing Appian's query rules (e.g., a!queryEntity) and directly executing SQL against the database. While this might offer a quick performance boost by avoiding Appian's abstraction layer, it violates Appian's core design principles. Appian Lead Developer documentation explicitly discourages direct database calls, as they bypass security (e.g., Appian's row-level security), auditing, and portability features. This introduces maintenance risks, dependencies on database-specific logic, and potential production instability-making it an unsustainable and non-recommended solution.
B . Create a table which is loaded every hour with the latest data:
This suggests implementing a staging table updated hourly (e.g., via an Appian process model or ETL process). While this could reduce query load by pre-aggregating data, it introduces latency (data is only fresh hourly), which may not meet real-time requirements typical in Appian applications (e.g., a customer-facing view). Additionally, maintaining an hourly refresh process adds complexity and overhead (e.g., scheduling, monitoring). Appian's documentation favors more efficient, real-time solutions over periodic refreshes unless explicitly required, making this less optimal for immediate performance remediation.
C . Create a materialized view or table:
This is the best choice. A materialized view (or table, depending on the database) pre-computes and stores query results, significantly improving retrieval performance for large datasets. In Appian, you can integrate a materialized view with a Data Store Entity, allowing a!queryEntity to fetch data efficiently without changing application logic. Appian Lead Developer training emphasizes leveraging database optimizations like materialized views to handle large data volumes, as they reduce query execution time while keeping data consistent with the source (via periodic or triggered refreshes, depending on the database). This aligns with Appian's performance optimization guidelines and addresses the tenfold data increase effectively.
D . Introduce a data management policy to reduce the volume of data:
This involves archiving or purging data to shrink the dataset (e.g., moving old records to an archive table). While a long-term data management policy is a good practice (and supported by Appian's Data Fabric principles), it doesn't immediately remediate the performance issue. Reducing data volume requires business approval, policy design, and implementation-delaying resolution. Appian documentation recommends combining such strategies with technical fixes (like C), but as a standalone solution, it's insufficient for urgent production concerns.
Conclusion: Creating a materialized view or table (C) is the best option. It directly mitigates performance by optimizing data retrieval, integrates seamlessly with Appian's Data Store, and scales for large datasets-all while adhering to Appian's recommended practices. The view can be refreshed as needed (e.g., via database triggers or schedules), balancing performance and data freshness. This approach requires collaboration with a DBA to implement but ensures a robust, Appian-supported solution.
Appian Documentation: "Performance Best Practices" (Optimizing Data Queries with Materialized Views).
Appian Lead Developer Certification: Application Performance Module (Database Optimization Techniques).
Appian Best Practices: "Working with Large Data Volumes in Appian" (Data Store and Query Performance).
NEW QUESTION # 38
You are taking your package from the source environment and importing it into the target environment.
Review the errors encountered during inspection:
What is the first action you should take to Investigate the issue?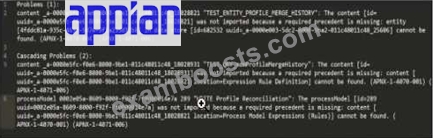
Answer: C
Explanation:
The error log provided indicates issues during the package import into the target environment, with multiple objects failing to import due to missing precedents. The key error messages highlight specific UUIDs associated with objects that cannot be resolved. The first error listed states:
"'TEST_ENTITY_PROFILE_MERGE_HISTORY': The content [id=uuid-a-0000m5fc-f0e6-8000-9b01-011c48011c48, 18028821] was not imported because a required precedent is missing: entity [uuid=a-0000m5fc-f0e6-8000-9b01-011c48011c48, 18028821] cannot be found..." According to Appian's Package Deployment Best Practices, when importing a package, the first step in troubleshooting is to identify the root cause of the failure. The initial error in the log points to an entity object with a UUID ending in 18028821, which failed to import due to a missing precedent. This suggests that the object itself or one of its dependencies (e.g., a data store or related entity) is either missing from the package or not present in the target environment.
Option A (Check whether the object (UUID ending in 18028821) is included in this package): This is the correct first action. Since the first error references this UUID, verifying its inclusion in the package is the logical starting point. If it's missing, the package export from the source environment was incomplete. If it's included but still fails, the precedent issue (e.g., a missing data store) needs further investigation.
Option B (Check whether the object (UUID ending in 7t00000i4e7a) is included in this package): This appears to be a typo or corrupted UUID (likely intended as something like "7t000014e7a" or similar), and it's not referenced in the primary error. It's mentioned later in the log but is not the first issue to address.
Option C (Check whether the object (UUID ending in 25606) is included in this package): This UUID is associated with a data store error later in the log, but it's not the first reported issue.
Option D (Check whether the object (UUID ending in 18028931) is included in this package): This UUID is mentioned in a subsequent error related to a process model or expression rule, but it's not the initial failure point.
Appian recommends addressing errors in the order they appear in the log to systematically resolve dependencies. Thus, starting with the object ending in 18028821 is the priority.
NEW QUESTION # 39
You are deciding the appropriate process model data management strategy.
For each requirement. match the appropriate strategies to implement. Each strategy will be used once.
Note: To change your responses, you may deselect your response by clicking the blank space at the top of the selection list.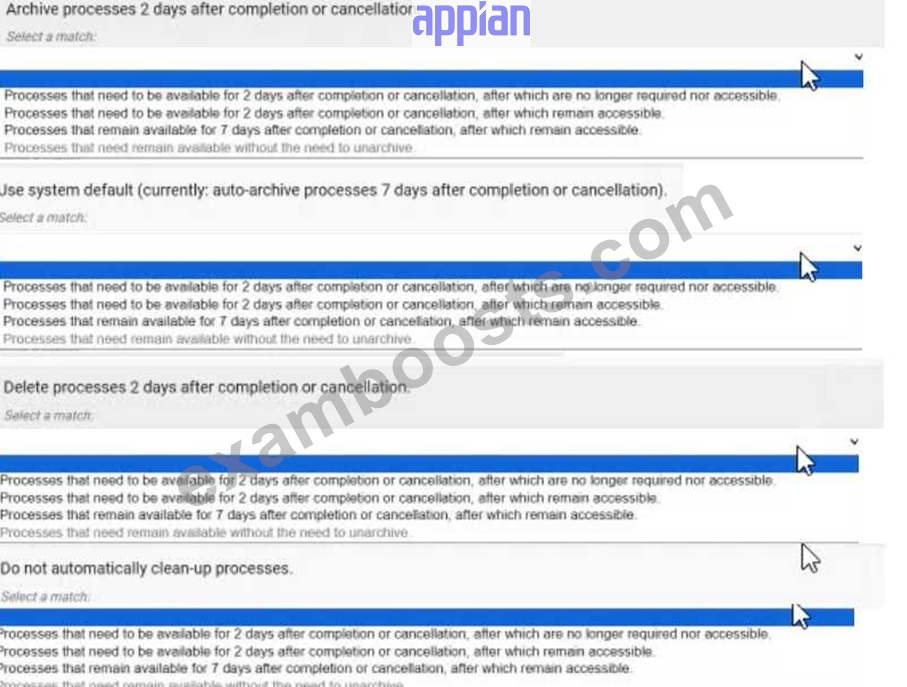
Answer:
Explanation: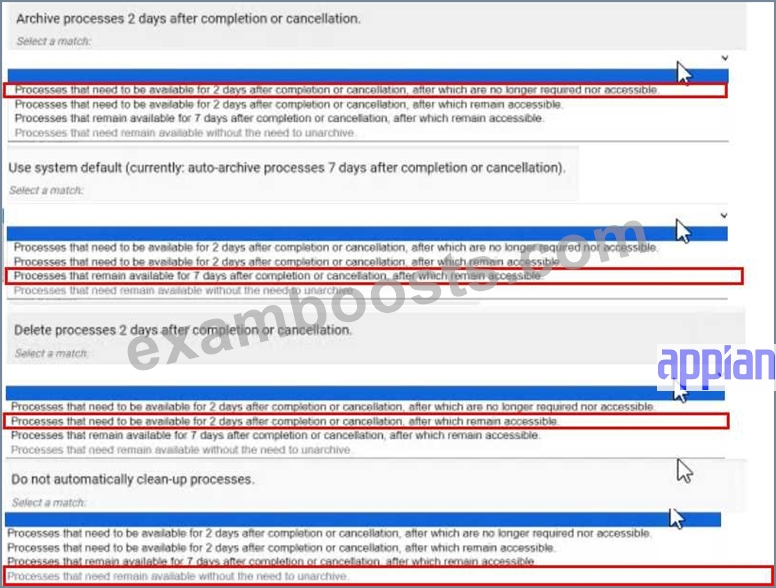
NEW QUESTION # 40
You are designing a process that is anticipated to be executed multiple times a day. This process retrieves data from an external system and then calls various utility processes as needed. The main process will not use the results of the utility processes, and there are no user forms anywhere.
Which design choice should be used to start the utility processes and minimize the load on the execution engines?
Answer: C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, designing a process that executes frequently (multiple times a day) and calls utility processes without using their results requires optimizing performance and minimizing load on Appian's execution engines. The absence of user forms indicates a backend process, so user experience isn't a concern-only engine efficiency matters. Let's evaluate each option:
A . Use the Start Process Smart Service to start the utility processes:
The Start Process Smart Service launches a new process instance independently, creating a separate process in the Work Queue. While functional, it increases engine load because each utility process runs as a distinct instance, consuming engine resources and potentially clogging the Java Work Queue, especially with frequent executions. Appian's performance guidelines discourage unnecessary separate process instances for utility tasks, favoring integrated subprocesses, making this less optimal.
B . Start the utility processes via a subprocess synchronously:
Synchronous subprocesses (e.g., a!startProcess with isAsync: false) execute within the main process flow, blocking until completion. For utility processes not used by the main process, this creates unnecessary delays, increasing execution time and engine load. With frequent daily executions, synchronous subprocesses could strain engines, especially if utility processes are slow or numerous. Appian's documentation recommends asynchronous execution for non-dependent, non-blocking tasks, ruling this out.
C . Use Process Messaging to start the utility process:
Process Messaging (e.g., sendMessage() in Appian) is used for inter-process communication, not for starting processes. It's designed to pass data between running processes, not initiate new ones. Attempting to use it for starting utility processes would require additional setup (e.g., a listening process) and isn't a standard or efficient method. Appian's messaging features are for coordination, not process initiation, making this inappropriate.
D . Start the utility processes via a subprocess asynchronously:
This is the best choice. Asynchronous subprocesses (e.g., a!startProcess with isAsync: true) execute independently of the main process, offloading work to the engine without blocking or delaying the parent process. Since the main process doesn't use the utility process results and there are no user forms, asynchronous execution minimizes engine load by distributing tasks across time, reducing Work Queue pressure during frequent executions. Appian's performance best practices recommend asynchronous subprocesses for non-dependent, utility tasks to optimize engine utilization, making this ideal for minimizing load.
Conclusion: Starting the utility processes via a subprocess asynchronously (D) minimizes engine load by allowing independent execution without blocking the main process, aligning with Appian's performance optimization strategies for frequent, backend processes.
Appian Documentation: "Process Model Performance" (Synchronous vs. Asynchronous Subprocesses).
Appian Lead Developer Certification: Process Design Module (Optimizing Engine Load).
Appian Best Practices: "Designing Efficient Utility Processes" (Asynchronous Execution).
NEW QUESTION # 41
......
If you have ExamBoosts's Appian ACD-301 exam training materials, we will provide you with one-year free update. This means that you can always get the latest exam information. As long as the Exam Objectives have changed, or our learning material changes, we will update for you in the first time. We know your needs, and we will help you gain confidence to pass the Appian ACD-301 Exam. You can be confident to take the exam and pass the exam.
Valid Dumps ACD-301 Sheet: https://www.examboosts.com/Appian/ACD-301-practice-exam-dumps.html
BTW, DOWNLOAD part of ExamBoosts ACD-301 dumps from Cloud Storage: https://drive.google.com/open?id=1xdB2rFzurSSLE4QPJFFe9PEaa4f4uf7i