BTW, DOWNLOAD part of Exam4Docs Mule-Arch-201 dumps from Cloud Storage: https://drive.google.com/open?id=1uX5tytye8dOWWk4-RvyMIS0QOGoQv2e0
The Mule-Arch-201 Exam is one of the best platforms that have been helping the Salesforce Mule-Arch-201 exam candidates in their preparation. Several Salesforce Mule-Arch-201 exam candidates have already passed their Salesforce Certified MuleSoft Platform Architect exam with good scores. They all used the Exams. Mule-Arch-201 Exam Questions and got success in the final Salesforce Mule-Arch-201 exam easily.
| Section | Objectives |
|---|---|
| Topic 1: Integration Architecture Strategy | - API-led connectivity principles - System, process, and experience APIs - Designing enterprise integration architecture |
| Topic 2: Security and Compliance | - Secure API exposure and threat protection - Authentication and authorization mechanisms |
| Topic 3: API Management and Governance | - Governance frameworks and best practices - API lifecycle management - API security policies and enforcement |
| Topic 4: Data Integration and Transformation | - Batch vs real-time integration patterns - Data mapping and transformation strategies |
| Topic 5: Anypoint Platform Architecture | - Runtime Fabric architecture overview - Anypoint Platform components and capabilities - Deployment models (CloudHub, hybrid, on-premises) |
| Topic 6: Performance and Scalability | - High availability design patterns - Scaling Mule applications |
>> Valid Mule-Arch-201 Test Questions <<
Never stop challenging your limitations. If you want to dig out your potentials, just keep trying. Repeated attempts will sharpen your minds. Maybe our Mule-Arch-201 study materials are suitable for you. We strongly advise you to have a brave attempt. You will own a wonderful experience after you learning our Mule-Arch-201 Study Materials. Our study materials are different from common study materials, which can motivate you to concentrate on study.
NEW QUESTION # 42
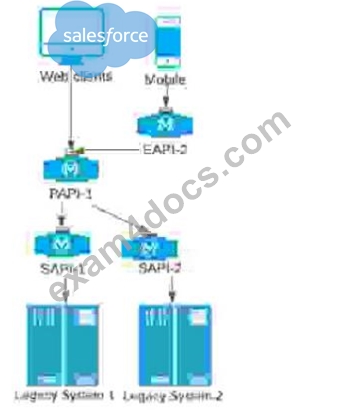
A company stores financial transaction data in two legacy systems. For each legacy system, a separate, dedicated System API (SAPI) exposes data for that legacy system. A Process API (PAPI) merges the data retrieved from ail of the System APIs into a common format. Several API clients call the PAPI through its public domain name.
The company now wants to expose a subset of financial data to a newly developed mobile application that uses a different Bounded Context Data Model. The company wants to follow MuleSoft's best practices for building out an effective application network.
Following MuleSoft's best practices, how can the company expose financial data needed by the mobile application in a way that minimizes the impact on the currently running API clients, API implementations, and support asset reuse?
Answer: D
Explanation:
To achieve the goal of exposing financial data to a new mobile application while following MuleSoft's best practices, the company should follow an API-led connectivity approach. This approach ensures minimal disruption to existing clients, maximizes reusability, and respects the separation of concerns across API layers.
of Solution:
Experience APIs for Client-Specific Requirements:
Create two new Experience APIs (EAPI-1 and EAPI-2) for the mobile application, tailored to meet the specific data and format requirements of the mobile application. These APIs encapsulate the client-specific needs and provide a custom interface without impacting other clients.
Process API Layer for Data Transformation:
By adding Mobile PAPI-2, we allow the mobile application to access the required subset of data, formatted according to the mobile application's requirements. This approach ensures that data transformation and aggregation are handled in the Process layer, maintaining consistency and reusability across different applications.
Reuse of System APIs:
Both the new Mobile PAPI-2 and existing PAPI-1 access data from System APIs (SAPI-1 and SAPI-2), which continue to expose data from each legacy system in a consistent, reusable manner. This avoids duplicating logic and ensures that data access remains centralized and manageable.
Why Option A is Correct:
Option A aligns with MuleSoft's best practices by isolating client-specific requirements in the Experience layer, utilizing Process APIs for data orchestration and transformation, and maintaining reusable System APIs for backend access.
This approach also ensures that the current API clients are not impacted, as new clients (e.g., the mobile app) interact with newly defined Experience APIs without modifying the existing API setup.
of Incorrect Options:
Option B: This option seems similar but lacks clarity on the separation of mobile-specific requirements and does not explicitly mention data transformation, which is essential in this scenario.
Option C: Creating a single mobile Experience API that exposes a subset of PAPI endpoints directly adds unnecessary complexity and may violate the separation of concerns, as transformation logic should not be in the Experience layer.
Option D: Deploying a new PAPI and using an API Proxy to redirect existing endpoints would add unnecessary complexity, disrupt the current API clients, and increase maintenance efforts.
Reference
For additional guidance, refer to MuleSoft documentation on API-led connectivity best practices and best practices for structuring Experience, Process, and System APIs.
NEW QUESTION # 43
What API policy would LEAST likely be applied to a Process API?
Answer: B
Explanation:
Correct Answe r: JSON threat protection
*****************************************
Fact: Technically, there are no restrictions on what policy can be applied in what layer. Any policy can be applied on any layer API. However, context should also be considered properly before blindly applying the policies on APIs.
That is why, this question asked for a policy that would LEAST likely be applied to a Process API.
From the given options:
>> All policies except "JSON threat protection" can be applied without hesitation to the APIs in Process tier.
>> JSON threat protection policy ideally fits for experience APIs to prevent suspicious JSON payload coming from external API clients. This covers more of a security aspect by trying to avoid possibly malicious and harmful JSON payloads from external clients calling experience APIs.
As external API clients are NEVER allowed to call Process APIs directly and also these kind of malicious and harmful JSON payloads are always stopped at experience API layer only using this policy, it is LEAST LIKELY that this same policy is again applied on Process Layer API.
NEW QUESTION # 44
What should be ensured before sharing an API through a public Anypoint Exchange portal?
Answer: B
Explanation:
Correct Answe r: The visibility level of the API instances of that API that need to be publicly accessible should be set to public visibility.
*****************************************
Reference:
https://docs.mulesoft.com/exchange/to-share-api-asset-to-portal
NEW QUESTION # 45
Refer to the exhibit.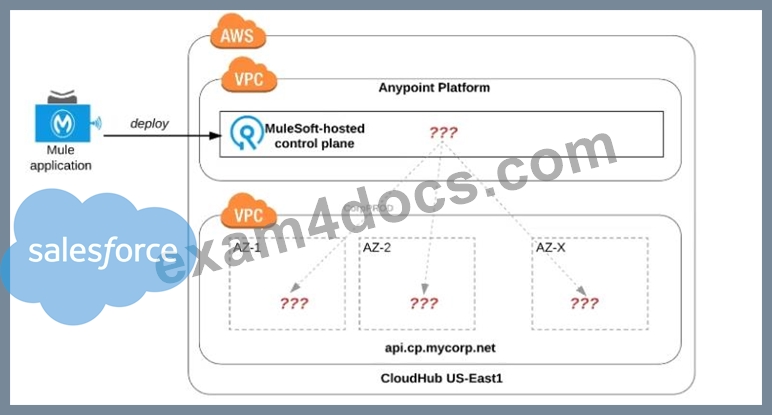
An organization uses one specific CloudHub (AWS) region for all CloudHub deployments.
How are CloudHub workers assigned to availability zones (AZs) when the organization's Mule applications are deployed to CloudHub in that region?
Answer: D
Explanation:
Correct Answe r: Workers are randomly distributed across available AZs within that region.
*****************************************
>> Currently, we only have control to choose which AWS Region to choose but there is no control at all using any configurations or deployment options to decide what Availability Zone (AZ) to assign to what worker.
>> There are NO fixed or implicit rules on platform too w.r.t assignment of AZ to workers based on environment or application.
>> They are completely assigned in random. However, cloudhub definitely ensures that HA is achieved by assigning the workers to more than on AZ so that all workers are not assigned to same AZ for same application.
Reference: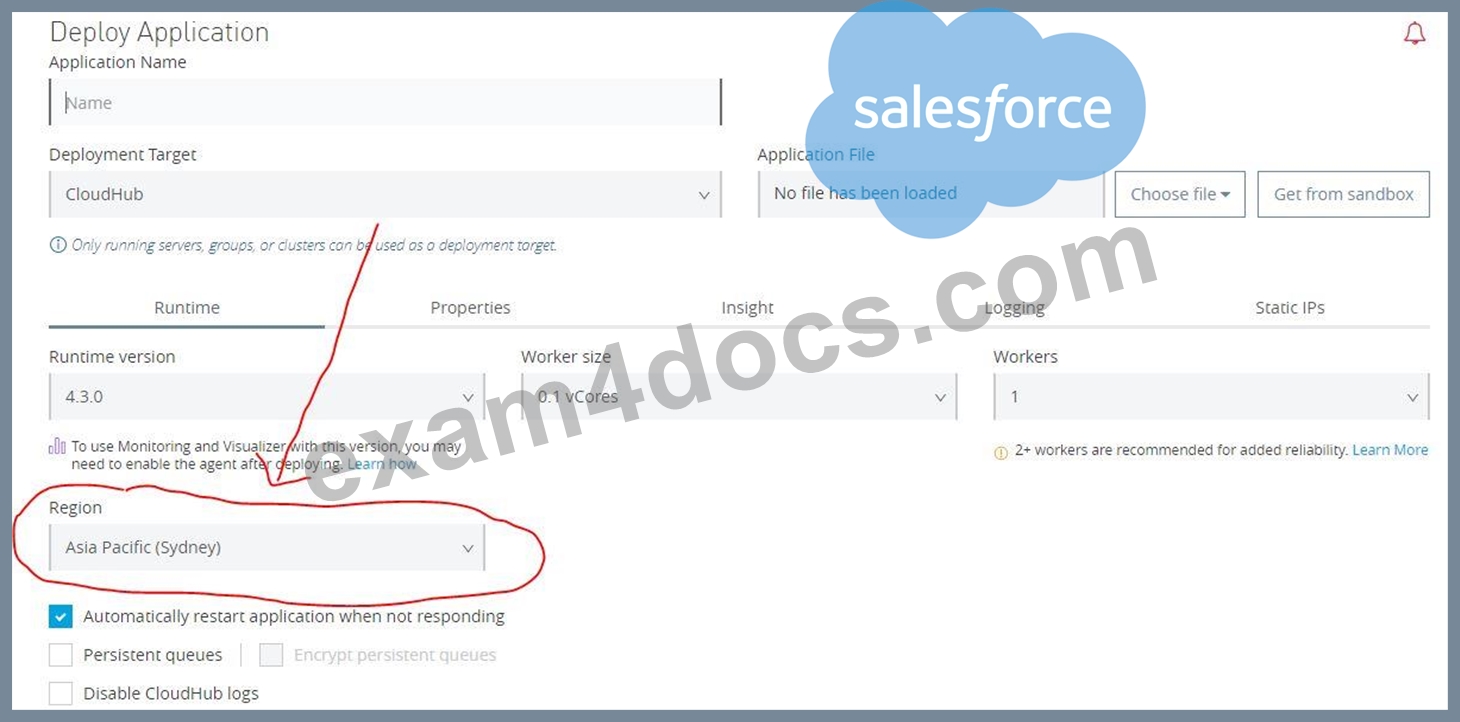
Bottom of Form
Top of Form
NEW QUESTION # 46
What best explains the use of auto-discovery in API implementations?
Answer: A
Explanation:
Correct Answe r: It makes API Manager aware of API implementations and hence enables it to enforce policies.
*****************************************
>> API Autodiscovery is a mechanism that manages an API from API Manager by pairing the deployed application to an API created on the platform.
>> API Management includes tracking, enforcing policies if you apply any, and reporting API analytics.
>> Critical to the Autodiscovery process is identifying the API by providing the API name and version.
Reference:
https://docs.mulesoft.com/api-manager/2.x/api-auto-discovery-new-concept
https://docs.mulesoft.com/api-manager/1.x/api-auto-discovery
https://docs.mulesoft.com/api-manager/2.x/api-auto-discovery-new-concept
NEW QUESTION # 47
......
Our study materials are choosing the key from past materials to finish our Mule-Arch-201 torrent prep. It only takes you 20 hours to 30 hours to do the practice. After your effective practice, you can master the examination point from the Mule-Arch-201 Exam Torrent. Then, you will have enough confidence to pass it. So start with our Mule-Arch-201 torrent prep from now on. We can succeed so long as we make efforts for one thing.
Mule-Arch-201 Valid Test Topics: https://www.exam4docs.com/Mule-Arch-201-study-questions.html
2026 Latest Exam4Docs Mule-Arch-201 PDF Dumps and Mule-Arch-201 Exam Engine Free Share: https://drive.google.com/open?id=1uX5tytye8dOWWk4-RvyMIS0QOGoQv2e0