TestkingPDF Databricks Databricks-Certified-Data-Engineer-Professional Dumps PDF Format
Candidates who become Databricks Databricks-Certified-Data-Engineer-Professional certified demonstrate their worth in the Databricks field. Databricks-Certified-Data-Engineer-Professional certification is proof of their competence and skills. This is a highly sought after credential and it makes career advancement easier for the candidate. To become Databricks Databricks-Certified-Data-Engineer-Professional Certified, you must pass the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) Exam. For this task, you need actual and updated Databricks-Certified-Data-Engineer-Professional Questions.
| Section | Weight | Objectives |
|---|
| Data Governance | 7% | - Enforce data policies and standards
- Manage data assets and metadata
- Use Unity Catalog for governance
|
| Monitoring and Alerting | 10% | - Monitor pipeline performance and health
- Track data lineage and metrics
- Set up alerts and notifications
|
| Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices
- Deploy using Asset Bundles, CLI, and APIs
- Troubleshoot and debug pipelines
|
| Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing
- Implement Lakehouse Federation
- Manage cross-platform data access
|
| Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming
- Ingest data from diverse sources
- Handle incremental and batch data loads
|
| Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management
- Enforce data quality standards
- Apply data cleansing and validation rules
|
| Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance
- Secure data at rest and in transit
- Implement access control and permissions
|
| Data Modelling | 6% | - Design Medallion Architecture
- Optimize table design and partitioning
- Implement dimensional and relational models
|
| Cost & Performance Optimisation | 13% | - Improve query and pipeline performance
- Apply cost management best practices
- Optimize compute and storage resources
|
| Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic
- Write efficient and maintainable code
- Use Databricks-specific libraries and APIs
|
>> Instant Databricks-Certified-Data-Engineer-Professional Download <<
2026 The Best Databricks-Certified-Data-Engineer-Professional – 100% Free Instant Download | Sample Databricks-Certified-Data-Engineer-Professional Test Online
Our experts update the Databricks-Certified-Data-Engineer-Professional training materials every day and provide the latest update timely to you. If you have the doubts or the questions about our product and the purchase procedures you can contact our online customer service personnel at any time. We provide the discounts to the old client and you can have a free download and tryout of our Databricks-Certified-Data-Engineer-Professional Test Question before your purchase. So there are many merits of our product. Read the introduction of the characteristics and the functions of our Databricks-Certified-Data-Engineer-Professional practice test as follow carefully before you purchase our product.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q158-Q163):
NEW QUESTION # 158
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impressions led to monetizable clicks.
In the code below, Impressions is a streaming DataFrame with a watermark ("event_time", "10 minutes")
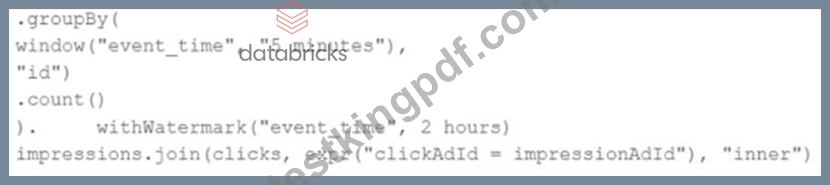
The data engineer notices the query slowing down significantly.
Which solution would improve the performance?
- A. Joining on event time constraint: clickTime >= impressionTime AND clickTime <= impressionTime interval 1 hour
- B. Joining on event time constraint: clickTime + 3 hours < impressionTime - 2 hours
- C. Joining on event time constraint: clickTime == impressionTime using a leftOuter join
- D. Joining on event time constraint: clickTime >= impressionTime - interval 3 hours and removing watermarks
Answer: A
NEW QUESTION # 159
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- B. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- C. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
- D. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- E. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
Answer: A
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
NEW QUESTION # 160
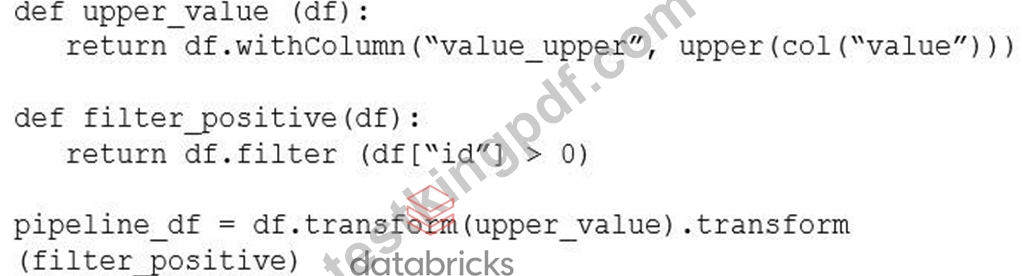
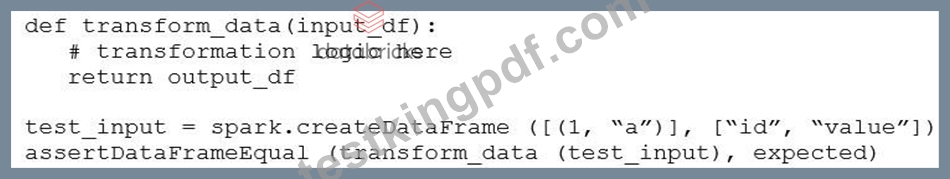
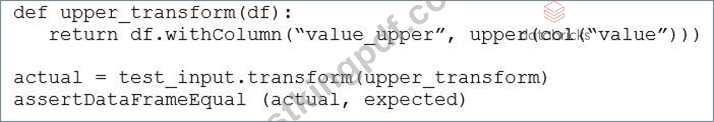
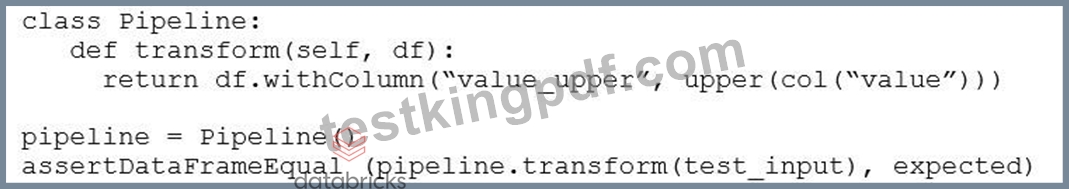
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
Answer: C
Explanation:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
NEW QUESTION # 161
A workspace admin has created a new catalog called finance_data and wants to delegate permission management to a finance team lead without giving them full admin rights. Which privilege should be granted to the finance team lead?
- A. Make the finance team lead a metastore admin.
- B. ALL PRIVILEGES on the finance_data catalog.
- C. MANAGE privilege on the finance_data catalog.
- D. GRANT OPTION privilege on the finance_data catalog.
Answer: C
Explanation:
The MANAGE privilege in Unity Catalog provides the ability to grant and revoke privileges on the specified object (in this case, a catalog) without giving full administrative access or ownership.
This is the Databricks-recommended approach for delegating governance responsibilities while preserving the principle of least privilege.
By contrast, the ALL PRIVILEGES option grants excessive access (including read and write permissions), and metastore admin status provides global control over all catalogs--far exceeding the requirement. The MANAGE privilege enables the finance team lead to control access to objects within finance_data responsibly while limiting overall administrative exposure.
NEW QUESTION # 162
What describes a primary technical challenge in ensuring consistent PII masking across all nodes in large-scale, distributed Databricks batch and streaming pipelines?
- A. Native masking in Databricks automatically synchronizes with all downstream external Databricks systems.
- B. Masking functions must be standardized and managed through Unity Catalog, with enforcement applied across all relevant datasets to avoid any data inconsistency.
- C. PII masking is only required for direct identifiers.
- D. Dynamic data masking is applied only at rest, so it does not affect query performance.
Answer: B
Explanation:
Consistent PII masking in distributed batch and streaming pipelines requires centrally defined and governed masking logic. Standardizing masking functions and enforcing them through Unity Catalog ensures that the same rules are applied uniformly across all datasets and execution paths, preventing inconsistencies across nodes and workloads.
NEW QUESTION # 163
......
There are rare products which can rival with our products and enjoy the high recognition and trust by the clients like our products. Our products provide the Databricks-Certified-Data-Engineer-Professional study materials to clients and help they pass the test Databricks-Certified-Data-Engineer-Professional certification which is highly authorized and valuable. Our company is a famous company which bears the world-wide influences and our Databricks-Certified-Data-Engineer-Professional Study Materials are recognized as the most representative and advanced study materials among the same kinds of products.
Sample Databricks-Certified-Data-Engineer-Professional Test Online: https://www.testkingpdf.com/Databricks-Certified-Data-Engineer-Professional-testking-pdf-torrent.html
- Latest Databricks-Certified-Data-Engineer-Professional Test Prep 👨 Databricks-Certified-Data-Engineer-Professional Reliable Dumps Book 🛄 Databricks-Certified-Data-Engineer-Professional Certification Book Torrent 🕡 The page for free download of ➠ Databricks-Certified-Data-Engineer-Professional 🠰 on [ www.torrentvce.com ] will open immediately ⛴Test Databricks-Certified-Data-Engineer-Professional Study Guide
- Exam Dumps Databricks-Certified-Data-Engineer-Professional Zip 🥵 Valid Databricks-Certified-Data-Engineer-Professional Exam Tutorial 🐚 Databricks-Certified-Data-Engineer-Professional Dumps Download 🔳 Search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 and obtain a free download on “ www.pdfvce.com ” 🔉Databricks-Certified-Data-Engineer-Professional Certified Questions
- Pass Guaranteed Quiz 2026 Databricks Databricks-Certified-Data-Engineer-Professional – The Best Instant Download 😂 Search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ and easily obtain a free download on ▶ www.easy4engine.com ◀ 🚀Test Databricks-Certified-Data-Engineer-Professional Testking
- Databricks Databricks-Certified-Data-Engineer-Professional Desktop-Based Practice Program 🏹 Search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 and download it for free on “ www.pdfvce.com ” website 🧘Databricks-Certified-Data-Engineer-Professional Reliable Dumps Book
- Free PDF Quiz 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Useful Instant Download 👸 《 www.prep4away.com 》 is best website to obtain ➤ Databricks-Certified-Data-Engineer-Professional ⮘ for free download 🐑Valid Databricks-Certified-Data-Engineer-Professional Study Plan
- Valid Test Databricks-Certified-Data-Engineer-Professional Tutorial 🍽 Valid Databricks-Certified-Data-Engineer-Professional Study Plan ↘ Exam Databricks-Certified-Data-Engineer-Professional Preview ⭐ Copy URL ▛ www.pdfvce.com ▟ open and search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ to download for free 🦅Exam Databricks-Certified-Data-Engineer-Professional Preview
- Updated Instant Databricks-Certified-Data-Engineer-Professional Download - Perfect Databricks-Certified-Data-Engineer-Professional Exam Tool Guarantee Purchasing Safety 🐝 Open website ( www.examcollectionpass.com ) and search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ for free download ❔Databricks-Certified-Data-Engineer-Professional Reliable Exam Pattern
- Databricks-Certified-Data-Engineer-Professional Certification Book Torrent ☕ Databricks-Certified-Data-Engineer-Professional Reliable Exam Pattern ↪ Databricks-Certified-Data-Engineer-Professional Free Dumps 🚋 Download 【 Databricks-Certified-Data-Engineer-Professional 】 for free by simply searching on ✔ www.pdfvce.com ️✔️ 👱Databricks-Certified-Data-Engineer-Professional Pdf Exam Dump
- Pass Guaranteed Quiz 2026 Databricks-Certified-Data-Engineer-Professional: Updated Instant Databricks Certified Data Engineer Professional Exam Download 🛑 Search on ☀ www.prep4sures.top ️☀️ for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ to obtain exam materials for free download 🅿Databricks-Certified-Data-Engineer-Professional Reliable Exam Pattern
- High Pass-Rate Instant Databricks-Certified-Data-Engineer-Professional Download - Accurate Sample Databricks-Certified-Data-Engineer-Professional Test Online: Databricks Certified Data Engineer Professional Exam ⛵ Search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ and download it for free on ➽ www.pdfvce.com 🢪 website 🎯Valid Databricks-Certified-Data-Engineer-Professional Exam Tutorial
- Free PDF Quiz 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Useful Instant Download 📌 Open ⏩ www.examdiscuss.com ⏪ and search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ to download exam materials for free 😅Databricks-Certified-Data-Engineer-Professional Free Dumps
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, youemerge.com, www.stes.tyc.edu.tw, Disposable vapes