P.S. Free & New Workday-Pro-Integrations dumps are available on Google Drive shared by Real4test: https://drive.google.com/open?id=1bp_h5yW7vE1qZShbCS8kycXgeCsfefHu
If you have tried on our Workday-Pro-Integrations exam questions, you may find that our Workday-Pro-Integrations study materials occupy little running memory. So it will never appear flash back. If you want to try our Workday-Pro-Integrations learning prep, just come to free download the demos which contain the different three versions of the Workday-Pro-Integrations training guide. And you will find every version is charming. Follow your heart and choose what you like best on our website.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Workday-Pro-Integrations Dump Check <<
To fit in this amazing and highly accepted exam, you must prepare for it with high-rank practice materials like our Workday-Pro-Integrations study materials. They are the Best choice in terms of time and money. All contents of Workday-Pro-Integrations training prep are made by elites in this area rather than being fudged by laymen. Let along the reasonable prices which attracted tens of thousands of exam candidates mesmerized by their efficiency by proficient helpers of our company. Any difficult posers will be solved by our Workday-Pro-Integrations Quiz guide.
NEW QUESTION # 94
Refer to the following XML to answer the question below.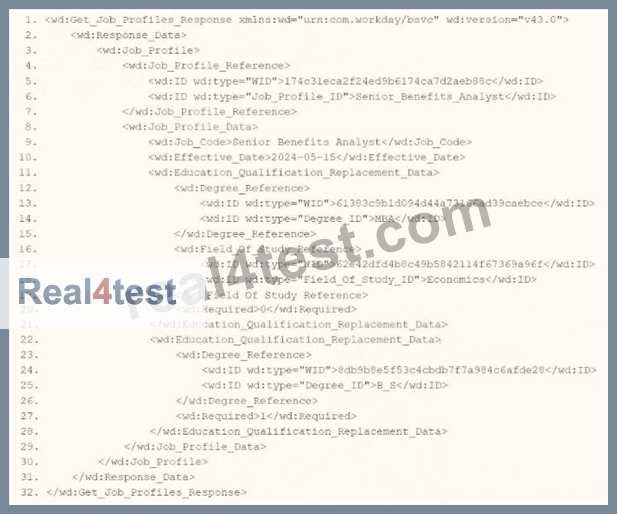
You are an integration developer and need to write XSLT to transform the output of an EIB which is making a request to the Get Job Profiles web service operation. The root template of your XSLT matches on the <wd:Get_Job_Profiles_Response> element. This root template then applies templates against <wd:Job_Profile>. What XPath syntax would be used to select the value of the ID element which has a wd:type attribute named Job_Profile_ID when the <xsl:value-of> element is placed within the template which matches on <wd:Job_Profile>?
Answer: A
Explanation:
As an integration developer working with Workday, you are tasked with transforming the output of an Enterprise Interface Builder (EIB) that calls the Get_Job_Profiles web service operation. The provided XML shows the response from this operation, and you need to write XSLT to select the value of the <wd:ID> element where the wd:type attribute equals "Job_Profile_ID." The root template of your XSLT matches on <wd:Get_Job_Profiles_Response> and applies templates to <wd:Job_Profile>. Within this template, you use the <xsl:value-of> element to extract the value. Let's analyze the XML structure, the requirement, and each option to determine the correct XPath syntax.
Understanding the XML and Requirement
The XML snippet provided is a SOAP response from the Get_Job_Profiles web service operation in Workday, using the namespace xmlns:wd="urn:com.workday/bsvc" and version wd:version="v43.0". Key elements relevant to the question include:
The root element is <wd:Get_Job_Profiles_Response>.
It contains <wd:Response_Data>, which includes <wd:Job_Profile> elements.
Within <wd:Job_Profile>, there is <wd:Job_Profile_Reference>, which contains multiple <wd:ID> elements, each with a wd:type attribute:
<wd:ID wd:type="WID">1740d3eca2f2ed9b6174ca7d2ae88c8c</wd:ID>
<wd:ID wd:type="Job_Profile_ID">Senior_Benefits_Analyst</wd:ID>
The task is to select the value of the <wd:ID> element where wd:type="Job_Profile_ID" (e.g., "Senior_Benefits_Analyst") using XPath within an XSLT template that matches <wd:Job_Profile>. The <xsl:value-of> element outputs the value of the selected node, so you need the correct XPath path from the <wd:Job_Profile> context to the specific <wd:ID> element with the wd:type attribute value "Job_Profile_ID." Analysis of Options Let's evaluate each option based on the XML structure and XPath syntax rules:
Option A: wd:Job_Profile_Reference/wd:ID/wd:type='Job_Profile_ID'
This XPath attempts to navigate from wd:Job_Profile_Reference to wd:ID, then to wd:type='Job_Profile_ID'. However, there are several issues:
wd:type='Job_Profile_ID' is not valid XPath syntax. In XPath, to filter based on an attribute value, you use the attribute selector [@attribute='value'], not a direct comparison like wd:type='Job_Profile_ID'.
wd:type is an attribute of <wd:ID>, not a child element or node. This syntax would not select the <wd:ID> element itself but would be interpreted as trying to match a nonexistent child node or property, resulting in an error or no match.
This option is incorrect because it misuses XPath syntax for attribute filtering.
Option B: wd:Job_Profile_Reference/wd:ID/@wd:type='Job_Profile_ID'
This XPath navigates to wd:Job_Profile_Reference/wd:ID and then selects the @wd:type attribute, comparing it to "Job_Profile_ID" with =@wd:type='Job_Profile_ID'. However:
The =@wd:type='Job_Profile_ID' syntax is invalid in XPath. To filter based on an attribute value, you use [@wd:type='Job_Profile_ID'] as a predicate, not an equality comparison in this form.
This XPath would select the wd:type attribute itself (e.g., the string "Job_Profile_ID"), not the value of the <wd:ID> element. Since <xsl:value-of> expects a node or element value, selecting an attribute directly would not yield the desired "Senior_Benefits_Analyst" value.
This option is incorrect due to the invalid syntax and inappropriate selection of the attribute instead of the element value.
Option C: wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']
This XPath navigates from wd:Job_Profile_Reference to wd:ID and uses the predicate [@wd:type='Job_Profile_ID'] to filter for <wd:ID> elements where the wd:type attribute equals "Job_Profile_ID." In the XML, <wd:Job_Profile_Reference> contains:
<wd:ID wd:type="WID">1740d3eca2f2ed9b6174ca7d2ae88c8c</wd:ID>
<wd:ID wd:type="Job_Profile_ID">Senior_Benefits_Analyst</wd:ID>
The predicate [@wd:type='Job_Profile_ID'] selects the second <wd:ID> element, whose value is "Senior_Benefits_Analyst." Since the template matches <wd:Job_Profile>, and <wd:Job_Profile_Reference> is a direct child of <wd:Job_Profile>, this path is correct:
<wd:Job_Profile> → <wd:Job_Profile_Reference> → <wd:ID[@wd:type='Job_Profile_ID']>.
When used with <xsl:value-of select="wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']"/>, it outputs "Senior_Benefits_Analyst," fulfilling the requirement.
This option is correct because it uses proper XPath syntax for attribute-based filtering and selects the desired <wd:ID> value.
Option D: wd:Job_Profile_Reference/wd:ID/[@wd:type='Job_Profile_ID']
This XPath is similar to Option C but includes an extra forward slash before the predicate: wd:ID/[@wd:type='Job_Profile_ID']. In XPath, predicates like [@attribute='value'] are used directly after the node name (e.g., wd:ID[@wd:type='Job_Profile_ID']), not separated by a slash. The extra slash is syntactically incorrect and would result in an error or no match, as it implies navigating to a child node that doesn't exist.
This option is incorrect due to the invalid syntax.
Why Option C is Correct
Option C, wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID'], is the correct XPath syntax because:
It starts from the context node <wd:Job_Profile> (as the template matches this element) and navigates to <wd:Job_Profile_Reference/wd:ID>, using the predicate [@wd:type='Job_Profile_ID'] to filter for the <wd:ID> element with wd:type="Job_Profile_ID".
It correctly selects the value "Senior_Benefits_Analyst," which is the content of the <wd:ID> element where wd:type="Job_Profile_ID".
It uses standard XPath syntax for attribute-based filtering, aligning with Workday's XSLT implementation for web service responses.
When used with <xsl:value-of>, it outputs the required value, fulfilling the question's requirement.
Practical Example in XSLT
Here's how this might look in your XSLT:
<xsl:template match="wd:Job_Profile">
<xsl:value-of select="wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']"/>
</xsl:template>
This would output "Senior_Benefits_Analyst" for the <wd:ID> element with wd:type="Job_Profile_ID" in the XML.
Verification with Workday Documentation
The Workday Pro Integrations Study Guide and SOAP API Reference (available via Workday Community) detail the structure of the Get_Job_Profiles response and how to use XPath in XSLT for transformations. The XML structure shows <wd:Job_Profile_Reference> containing <wd:ID> elements with wd:type attributes, and the guide emphasizes using predicates like [@wd:type='value'] to filter based on attributes. This is a standard practice for navigating Workday web service responses.
Workday Pro Integrations Study Guide Reference
Section: XSLT Transformations in EIBs - Describes using XSLT to transform web service responses, including selecting elements with XPath and attribute predicates.
Section: Workday Web Services - Details the Get_Job_Profiles operation and its XML output structure, including <wd:Job_Profile_Reference> and <wd:ID> with wd:type attributes.
Section: XPath Syntax - Explains how to use predicates like [@wd:type='Job_Profile_ID'] for attribute-based filtering in Workday XSLT.
Workday Community SOAP API Reference - Provides examples of XPath navigation for Workday web service responses, including attribute selection.
Option C is the verified answer, as it correctly selects the <wd:ID> value with wd:type="Job_Profile_ID" using the appropriate XPath syntax within the <wd:Job_Profile> template context.
NEW QUESTION # 95
What is the workflow to chain a Document Transformation system to a Connector integration for the purpose of transforming the output?
Answer: A
Explanation:
To chain a Document Transformation system to a Connector Integration, you must configure the Connector Integration System's Business Process (BP) to include a "Service step of Fire Integration", which triggers the Document Transformation after the connector completes.
From Workday documentation:
"To execute a Document Transformation after a connector integration, use the Fire Integration service step in the connector's business process to trigger the Document Transformation integration." This allows Workday to chain multiple integrations, such as taking the output of a Core Connector and sending it through a transformation step (e.g., XSLT) before delivering to an endpoint.
Why other options are incorrect:
* A. Fire Integration in the DT BP is not used to call itself.
* B. "Integration step" in BP is not a valid step type.
* C. Same issue - DT's own BP doesn't call itself or other integrations.
Reference:Workday Pro: Document Transformation - Integration Chaining via Fire Integration StepWorkday Integration Certification Guide - Document Transformation and BP Chaining
NEW QUESTION # 96
You need to create a report that includes data from multiple business objects. For a supervisory organization specified at run time, the report must output one row per worker, their active benefit plans, and the names and ages of all related dependents. The Worker business object contains the Employee, Benefit Plans, and Dependents fields. The Dependent business object contains the employee's dependent's Name and Age fields.
How would you select the primary business object (PBO) and related business objects (RBO) for the report?
Answer: C
Explanation:
In Workday reporting, selecting the appropriate Primary Business Object (PBO) and Related Business Objects (RBOs) is critical to ensure that the report retrieves and organizes data correctly based on the requirements.
The requirement here is to create a report that outputs one row per worker for a specified supervisory organization, including their active benefit plans and the names and ages of all related dependents. The Worker business object contains fields like Employee, Benefit Plans, and Dependents, while the Dependent business object provides the Name and Age fields for dependents.
* Why Worker as the PBO?The report needs to output "one row per worker," making the Worker business object the natural choice for the PBO. In Workday, the PBO defines the primary dataset and determines the granularity of the report (i.e., one row per instance of the PBO). Since the report revolves around workers and their associated data (benefit plans and dependents), Worker is the starting point. Additionally, the requirement specifies a supervisory organization at runtime, which is a filter applied to the Worker business object to limit the population.
* Why Dependent as an RBO?The Worker business object includes a "Dependents" field, which is a multi-instance field linking to the Dependent business object. To access detailed dependent data (Name and Age), the Dependent business object must be added as an RBO. This allows the report to pull in the related dependent information for each worker. Without the Dependent RBO, the report could only reference the existence of dependents, not their specific attributes like Name and Age.
* Analysis of Benefit Plans:The Worker business object already contains the "Benefit Plans" field, which provides access to active benefit plan data. Since this is a field directly available on the PBO (Worker), no additional RBO is needed to retrieve benefit plan information.
* Option Analysis:
* A. PBO: Dependent, RBO: Worker: Incorrect. If Dependent were the PBO, the report would output one row per dependent, not one row per worker, which contradicts the requirement.
Additionally, Worker as an RBO would unnecessarily complicate accessing worker-level data.
* B. PBO: Worker, RBO: Dependent: Correct. This aligns with the requirement: Worker as the PBO ensures one row per worker, and Dependent as the RBO provides access to dependent details (Name and Age). Benefit Plans are already accessible via the Worker PBO.
* C. PBO: Dependent, no RBOs: Incorrect. This would result in one row per dependent and would not allow easy access to worker or benefit plan data, failing to meet the "one row per worker" requirement.
* D. PBO: Worker, no RBOs: Incorrect. While Worker as the PBO is appropriate, omitting the Dependent RBO prevents the report from retrieving dependent Name and Age fields, which are stored in the Dependent business object, not directly on Worker.
* Implementation:
* Create a custom report with Worker as the PBO.
* Add a filter for the supervisory organization (specified at runtime) on the Worker PBO.
* Add Dependent as an RBO to access Name and Age fields.
* Include columns from Worker (e.g., Employee, Benefit Plans) and Dependent (e.g., Name, Age).
References from Workday Pro Integrations Study Guide:
* Workday Report Writer Fundamentals: Section on "Selecting Primary and Related Business Objects" explains how the PBO determines the report's row structure and RBOs extend data access to related objects.
* Integration System Fundamentals: Discusses how multi-instance fields (e.g., Dependents on Worker) require RBOs to retrieve detailed attributes.
NEW QUESTION # 97
After configuring domain security policies, what task must you run to ensure the most recent changes go into effect?
Answer: A
Explanation:
Whenever changes are made to domain security policies, they remain in a pending state until you explicitly activate them by running the:
Activate Pending Security Policy Changes task.
This ensures that all updates to permissions are applied across the tenant for real-time enforcement.
Why the others are incorrect:
A . Activate Previous Security Timestamp reverts to a prior configuration.
B . Activate All Pending Authentication Policy Changes is only for authentication rules.
D . Activate Metadata Schedule applies to metadata changes, not security.
NEW QUESTION # 98
Refer to the following scenario to answer the question below.
You are implementing a Core Connector: Worker integration to send employee data to a third-party active employee directory. The external vendor requires the following:
The Employee's Active Directory User Principal Name.
A mapping from Worker Type values to external worker type codes.
A specific filename format that includes a timestamp and sequence number.
You also need to ensure the document transformation occurs before the file is delivered to the endpoint. The connector's output must be transformed before the file is delivered to the vendor.
What step must be taken to ensure this occurs correctly?
Answer: D
Explanation:
The requirement states that the connector output must be transformed before the file is delivered to the endpoint. This means the Document Transformation step must run first, followed by the Document Delivery step.
In Workday, this is managed through the Business Process (BP) attached to the integration system.
From Workday documentation:
"To transform an integration file before delivery, configure the Business Process to run the Document Transformation step before the Document Delivery Service step." This ensures that:
The file is converted (via XSLT) to the correct format (e.g., CSV or flat XML) Only the final, transformed file is sent to the endpoint Why the others are incorrect:
A . Scheduling separately does not ensure correct sequence.
B . Delivery before transformation would send the wrong file.
D . A separate integration system is unnecessary and not best practice for chained transformations.
NEW QUESTION # 99
......
If you are the first time to prepare the Workday-Pro-Integrations exam, it is better to choose a type of good study materials. After all, you cannot understand the test syllabus of the Workday-Pro-Integrations exam in the whole round. It is important to predicate the tendency of the Workday-Pro-Integrations study materials if you want to easily pass the exam. And our Workday-Pro-Integrations Exam Questions are the one which can exactly cover the latest information of the exam in the first time for our professionals are good at this subject and you can totally rely on us.
Exam Workday-Pro-Integrations Questions Pdf: https://www.real4test.com/Workday-Pro-Integrations_real-exam.html
What's more, part of that Real4test Workday-Pro-Integrations dumps now are free: https://drive.google.com/open?id=1bp_h5yW7vE1qZShbCS8kycXgeCsfefHu