Now is not the time to be afraid to take any more difficult Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer certification exams. Our Databricks-Certified-Professional-Data-Engineer learning quiz can relieve you of the issue within limited time. Our website provides excellent Databricks-Certified-Professional-Data-Engineer learning guidance, practical questions and answers, and questions for your choice which are your real strength. You can take the Databricks Databricks-Certified-Professional-Data-Engineer Training Materials and pass it without any difficulty.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple Choice |
| Exam Price: | USD 200 |
| Exam Duration: | 120 minutes |
| Related Certifications: | Databricks Certified Associate Data Engineer |
| Passing Score: | 70% |
| Real Exam Qty: | 59 |
| Available Languages: | Korean, Japanese, English, Portuguese (Brazil) |
| Recommended Training: | Databricks Data Engineer Professional Training |
| Exam Registration: | Databricks Official Certification Registration |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored or onsite test center |
| Pre Condition: | No mandatory prerequisites; 1+ year hands-on experience and related training highly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-professional |
>> Databricks Databricks-Certified-Professional-Data-Engineer Guaranteed Questions Answers <<
Many don't find real Databricks-Certified-Professional-Data-Engineer exam questions and face loss of money and time. Actual4Exams made an absolute gem of study material which carries actual Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions for the students so that they don't get confused in order to prepare for Databricks Databricks-Certified-Professional-Data-Engineer Exam and pass it with a good score. The Databricks Databricks-Certified-Professional-Data-Engineer practice test questions are made by examination after consulting with a lot of professionals and receiving positive feedback from them.
Databricks Certified Professional Data Engineer certification exam is designed to test the knowledge and skills of data engineers who work with Databricks. Databricks is a cloud-based platform that provides a unified analytics engine for big data processing and machine learning. It is used by data engineers to manage data pipelines, extract insights from data, and build machine learning models. Databricks Certified Professional Data Engineer Exam certification exam is a comprehensive assessment of the candidate's ability to use Databricks effectively for data engineering tasks.
NEW QUESTION # 187
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table namedusers.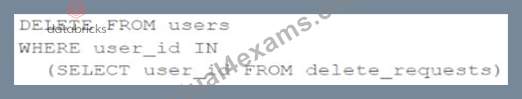
Assuming thatuser_idis a unique identifying key and thatdelete_requestscontains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Answer: E
Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion.
The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under "Remove files no longer referenced by a Delta table" section.
NEW QUESTION # 188
What steps need to be taken to set up a DELTA LIVE PIPELINE as a job using the workspace UI?
Answer: B
Explanation:
Explanation
The answer is,
Select Workflows UI and Delta live tables tab, under task type select Delta live tables pipeline and select the notebook.
Create a pipeline
To create a new pipeline using the Delta Live Tables notebook:
1.Click Workflows in the sidebar, click the Delta Live Tables tab, and click Create Pipeline.
2.Give the pipeline a name and click to select a notebook.
3.Optionally enter a storage location for output data from the pipeline. The system uses a de-fault location if you leave Storage Location empty.
4.Select Triggered for Pipeline Mode.
5.Click Create.
The system displays the Pipeline Details page after you click Create. You can also access your pipeline by clicking the pipeline name in the Delta Live Tables tab.
NEW QUESTION # 189
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is namedstore_saies_summaryand the schema is as follows:
The tabledaily_store_salescontains all the information needed to updatestore_sales_summary. The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
Ifdaily_store_salesis implemented as a Type 1 table and thetotal_salescolumn might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in thestore_sales_summarytable?
Answer: E
Explanation:
The daily_store_sales table contains all the information needed to update store_sales_summary. The schema of the table is:
store_id INT, sales_date DATE, total_sales FLOAT
The daily_store_sales table is implemented as a Type 1 table, which means that old values are overwritten by new values and no history is maintained. The total_sales column might be adjusted after manual data auditing, which means that the data in the table may change over time.
The safest approach to generate accurate reports in the store_sales_summary table is to use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update. Structured Streaming is a scalable and fault-tolerant stream processing engine built on Spark SQL. Structured Streaming allows processing data streams as if they were tables or DataFrames, using familiar operations such as select, filter, groupBy, or join. Structured Streaming also supports output modes that specify how to write the results of a streaming query to a sink, such as append, update, or complete. Structured Streaming can handle both streaming and batch data sources in a unified manner.
The change data feed is a feature of Delta Lake that provides structured streaming sources that can subscribe to changes made to a Delta Lake table. The change data feed captures both data changes and schema changes as ordered events that can be processed by downstream applications or services. The change data feed can be configured with different options, such as starting from a specific version or timestamp, filtering by operation type or partition values, or excluding no-op changes.
By using Structured Streaming to subscribe to the change data feed for daily_store_sales, one can capture and process any changes made to the total_sales column due to manual data auditing. By applying these changes to the aggregates in the store_sales_summary table with each update, one can ensure that the reports are always consistent and accurate with the latest data. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under "Structured Streaming" section; Databricks Documentation, under "Delta Change Data Feed" section.
NEW QUESTION # 190
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalidlatitudeandlongitudevalues in theactivity_detailstable have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to addCHECKconstraints to the Delta Lake table: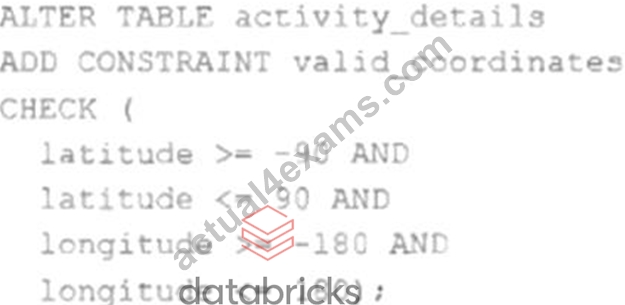
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
Answer: C
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and 180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Add a CHECK constraint to an existing table" section.
https://docs.databricks.com/en/sql/language-manual/sql-ref-syntax-ddl-alter-table.html#add-constraint
NEW QUESTION # 191
A Delta Lake table with Change Data Feed (CDF) enabled in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources. The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours. Which approach would simplify the identification of these changed records?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "Change data feed (CDF) provides row-level change information for Delta tables." Exact extract: "Use table_changes to query the set of rows that were inserted, updated, or deleted between two versions (or timestamps)." Exact extract: "MERGE INTO updates and inserts only the rows that changed."
NEW QUESTION # 192
......
Databricks-Certified-Professional-Data-Engineer New Exam Camp: https://www.actual4exams.com/Databricks-Certified-Professional-Data-Engineer-valid-dump.html