BONUS!!! Fast2test DA0-001ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=12-ZUvNwjCUVOCLwbKG_31gTctj221ExU
CompTIAのDA0-001試験に関する権威のある学習教材を見つけないで、悩んでいますか?世界中での各地の人々はほとんどCompTIAのDA0-001試験を受験しています。CompTIAのDA0-001の認証試験の高品質の資料を提供しているユニークなサイトはFast2testです。もし君はまだ心配することがあったら、私たちのCompTIAのDA0-001問題集を購入する前に、一部分のフリーな試験問題と解答をダンロードして、試用してみることができます。
Comptia Data+認定は、データ管理における候補者の知識とスキルを実証する国際的に認められた認定です。この認定は、トップIT企業によって認識されており、より良い雇用機会とより高い給与につながる可能性があります。認定は3年間有効であり、候補者は継続教育ユニット(CEU)を獲得するか、試験の最新バージョンに合格することで認定を更新できます。
CompTIA DA0-001、またはCompTIA Data+認定は、データ管理分野の個人のスキルと知識を測定するエントリーレベルの認定試験です。この試験は、データ管理のキャリアを追求し、データ分析、データベース設計、データ処理の知識を検証したい個人を対象としています。試験は、データストレージと管理、データセキュリティ、データ分析、およびデータベース設計を含むさまざまなトピックをカバーしています。
あなたが学生であるか、すでに仕事に参加した専門家であるかどうか、あなたは今競争の圧力を感じなければなりません。しかし、どんなに激しい競争であっても、あなたが力を持っている限り、あなたは確かに目立つことができます。良くなるのは簡単ではありません。 DA0-001試験の質問はあなたに助けを与えることができます。 DA0-001学習教材を使用した後、DA0-001試験にすばやく合格し、自分の強さを証明することもできます。もちろん、DA0-001学習教材はそれ以上のものをもたらします。 DA0-001試験問題の助けを借りて、より明るい未来を手に入れてください。
Comptia DA0-001またはComptia Data+認定試験は、データ管理の分野で個人のスキルと知識を検証するように設計された認定です。この認定は、IT業界でのキャリアを追求したい個人にIT認定とトレーニングを提供する非営利組織であるComputing Technology Industry Association(CompTIA)によって提供されます。
質問 # 390
A military commander would like to see the health scorecards of the troops daily and filter them based on gender and rank. Considering this data is PHI, which of the following would be the best way for the commander to view the information?
正解:A
解説:
Explanation
A password-protected dashboard is a type of web-based application that can display the health scorecards of the troops in a secure and interactive way. A password-protected dashboard can provide the following benefits for the commander:
It can protect the PHI data from unauthorized access or disclosure by requiring a valid username and password to log in. This can ensure that only the commander and other authorized personnel can view the information12 It can allow the commander to filter the data based on gender and rank by using drop-down menus, sliders, checkboxes, or other controls. This can enable the commander to customize the view and focus on the relevant data13 It can update the data daily by connecting to a data source that refreshes automatically or on demand. This can ensure that the commander always sees the latest and most accurate information14 It can present the data in a visual and intuitive way by using charts, graphs, tables, or other elements. This can help the commander to understand and analyze the data more easily and effectively1
質問 # 391
Which of the following data manipulation techniques is an example of a logical function?
正解:A
解説:
Explanation
This is because an IF function is a type of logical function that returns a value based on a condition or a set of conditions. An IF function can be used to manipulate data by applying different actions or calculations depending on whether the condition is true or false. For example, an IF function in Excel that can achieve this is:
=IF (condition, value_if_true, value_if_false)
The other data manipulation techniques are not examples of logical functions. Here is why:
WHERE is a type of clause that filters data based on a condition or a set of conditions. A WHERE clause can be used to manipulate data by selecting only the rows that satisfy the condition(s). For example, a WHERE clause in SQL that can achieve this is:
AGGREGATE is a type of function that performs a calculation on a group of values, such as sum, average, count, etc. An AGGREGATE function can be used to manipulate data by summarizing or aggregating the values in a column or a table. For example, an AGGREGATE function in SQL that can achieve this is:
BOOLEAN is a type of data type that represents two possible values: true or false. A BOOLEAN data type can be used to manipulate data by storing or returning logical values based on a condition or a set of conditions. For example, a BOOLEAN data type in Python that can achieve this is: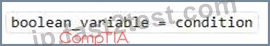
質問 # 392
Given the following data: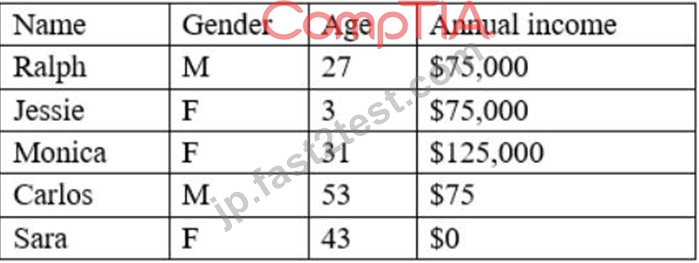
Which of the following BEST describes the data set?
正解:D
解説:
This is because inconsistency is a type of data quality issue that occurs when the data does not follow a common format, structure, or rule across different sources or systems, which can affect the efficiency and performance of the analysis or process. Inconsistency can be caused by having different spellings, punctuations, capitalizations, or abbreviations for the same or similar values in a data set, such as "M", "m", "Male", or "male" for gender in this case. Inconsistency can be eliminated or reduced by using data cleansing techniques, such as standardizing or normalizing the data values. The other options are not correct descriptions of the data set. Here is why:
Data bias is a type of data quality issue that occurs when the data is not representative or proportional of the population or the parameter, which can affect the validity and reliability of the analysis or process. Data bias can be caused by having a sample that is too small, too large, or too skewed for the population or the parameter, such as having only male customers for a product that targets both genders in this case. Data bias can be eliminated or reduced by using sampling techniques, such as stratified or cluster sampling.
The data is incomplete is a type of data quality issue that occurs when the data is absent or missing in a data set, which can affect the accuracy and reliability of the analysis or process. The data is incomplete can be caused by various factors, such as human error, system error, or non-response. The data is incomplete can be addressed by using various methods, such as replacing or imputing the missing values with some reasonable estimates, such as mean, median, mode, or regression.
The data is outliers is a type of data quality issue that occurs when the data has values that are unusually high or low compared to the rest of the data set, which can affect the quality and validity of the analysis or process. The data is outliers can be caused by various factors, such as measurement error, natural variation, or extreme events. The data is outliers can be addressed by using various methods, such as removing or filtering out the outliers, or using robust statistics that are less sensitive to outliers, such as median, interquartile range, or box plot.
質問 # 393
An analyst is reporting on the average income for a county and is reviewing the following data: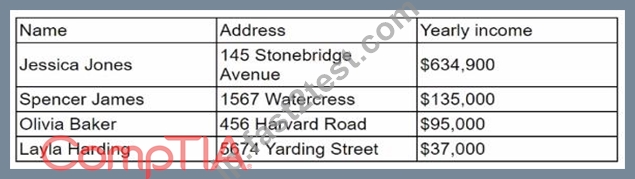
Which of the following is the reason the analyst would need to cleanse the data in this data set?
正解:A
質問 # 394
An analyst is working with the income data of suburban families in the United States. The data set has a lot of outliers, and the analyst needs to provide a measure that represents the typical income. Which of the following would BEST fulfill the analyst's goal?
正解:C
解説:
his is because median is a type of statistical measure that represents the typical value or central tendency of a data set, which means that it divides the data set into two equal halves, such that half of the values are above it and half are below it. Median can be used to provide a measure that represents the typical income of suburban families in the United States, especially when the data set has a lot of outliers, which means that it has values that are unusually high or low compared to the rest of the data set. Median can provide a measure that represents the typical income of suburban families in the United States, because it is not affected or skewed by the outliers, as it only depends on the middle value or the middle two values of the data set, regardless of how extreme or distant the outliers are. For example, median can provide a measure that represents the typical income of suburban families in the United States, by finding the income value that splits the data set into two equal groups of families, such that 50% of the families have higher incomes and 50% have lower incomes. The other statistical measures are not the best measures to represent the typical income of suburban families in the United States. Here is why:
Mean is a type of statistical measure that represents the average value or central tendency of a data set, which means that it is the sum of all the values divided by the number of values. Mean is not a good measure to represent the typical income of suburban families in the United States, especially when the data set has a lot of outliers, because it is affected or skewed by the outliers, as it takes into account all the values in the data set, regardless of how extreme or distant they are. For example, mean can provide a measure that does not represent the typical income of suburban families in the United States, by finding the income value that is influenced by a few very high or very low incomes, which could make it higher or lower than most of the incomes in the data set.
Mode is a type of statistical measure that represents the most frequent value or mode of a data set, which means that it is the value that occurs most often in the data set. Mode is not a good measure to represent the typical income of suburban families in the United States, especially when the data set has a lot of outliers, because it is not representative or indicative of the central tendency or distribution of the data set, as it only depends on the count or occurrence of a single value or a few values in the data set, regardless of how common or rare they are. For example, mode can provide a measure that does not represent the typical income of suburban families in the United States, by finding the income value that is repeated more often than others, which could be an outlier or an anomaly in the data set.
Standard deviation is a type of statistical measure that represents the amount of dispersion or variation of a data set, which means that it quantifies how much the values in a data set vary or deviate from the mean or average of the data set. Standard deviation is not a measure that represents the typical income of suburban families in the United States, but rather a measure that describes the spread or distribution of their incomes, as well as identifies any outliers or extreme values in their incomes. For example, standard deviation can provide a measure that describes how diverse or homogeneous their incomes are, as well as how far their incomes are from their average income.
質問 # 395
......
DA0-001資格取得講座: https://jp.fast2test.com/DA0-001-premium-file.html
さらに、Fast2test DA0-001ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=12-ZUvNwjCUVOCLwbKG_31gTctj221ExU