DP-800認定試験の準備を完了したのですか。試験を目前に控え、自信満々と受験することができますか。もしまだ試験に合格する自信を持っていないなら、ここで最高の試験参考書を推奨します。ただ短時間の勉強で試験に合格できる最新のDP-800問題集が登場しました。この素晴らしい問題集はJpexamによって提供されます。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Available Languages: | English, Japanese, Chinese (Simplified), Portuguese (Brazil), Spanish, French, German, Korean |
| Real Exam Qty: | 40-60 |
| Exam Duration: | 100 minutes |
| Passing Score: | 700 (on a scale of 1-1000) |
| Exam Format: | Multiple select, Drag and drop, Case studies, Active screen, Multiple choice |
| Exam Price: | $165 USD |
| Certificate Validity Period: | 1 year (renewable annually via free online assessment) |
| Recommended Training: | Microsoft Learn DP-800 Learning Path |
| Exam Registration: | Pearson VUE Registration |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE test centers |
| Pre Condition: | No mandatory prerequisites; recommended experience: T-SQL development, SQL Server/Azure SQL, CI/CD practices, basic AI concepts |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-800 |
現在、多くの事務員は自分自身の能力をアップすることに専念しています。 彼らは暇を利用して私たちのDP-800学習教材を勉強しています。DP-800学習教材は定期的に更新されます。また、私たちはいいサービスを提供します。私たちのDP-800学習教材はすごく人気があります。そして、利用した人は全部DP-800試験に合格しました。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
質問 # 41
You have an Azure SQL database that contains a table named stores, stores contains a column named description and a vector column named embedding.
You need to implement a hybrid search query that meets the following requirements:
* Uses full-text search on description for the keyword portion
* Returns the top 20 results based on a combined score that uses a weighted formula of 60% vector distance and 40% full-text rank How should you configure the query components? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.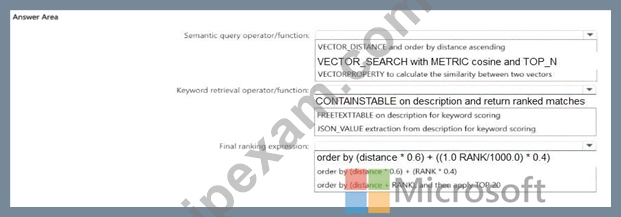
正解:
解説: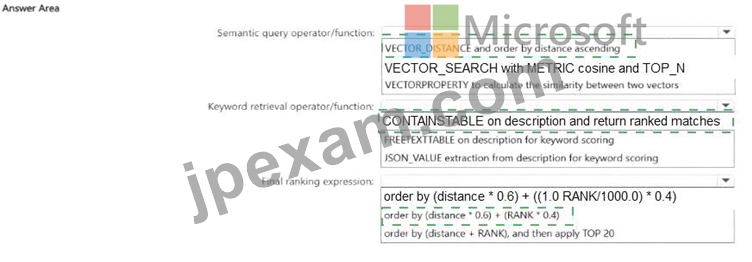
Explanation: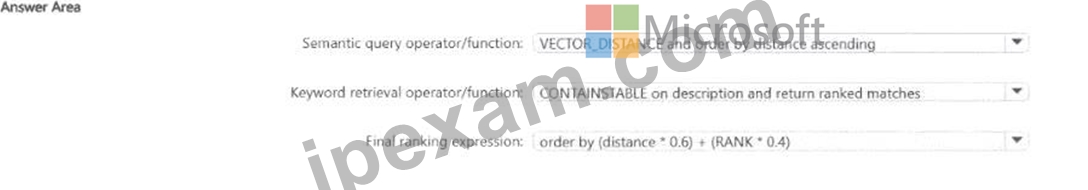
For the vector portion, the correct choice is VECTOR_DISTANCE and order by distance ascending . The requirement is to build a combined weighted formula using the actual vector distance. Microsoft documents that VECTOR_DISTANCE returns the exact distance between two vectors. Since lower distance means greater similarity, ascending distance is the right direction for ranking. VECTOR_SEARCH is for ANN retrieval, but this hotspot specifically asks for a weighted formula based on distance , so VECTOR_DISTANCE is the appropriate operator.
For the keyword portion, the correct choice is CONTAINSTABLE on description and return ranked matches . Microsoft documents that CONTAINSTABLE returns a RANK column from 0 through 1000 , which is exactly what is needed for weighted scoring in a hybrid formula.
For the final ranking expression, the best choice is order by (distance * 0.6) + ((1.0 - RANK/1000.0) * 0.4) .
This works because vector distance is a lower-is-better metric, while full-text RANK is a higher-is-better metric. Dividing RANK by 1000 normalizes it to the documented range, and subtracting from 1.0 converts it into a lower-is-better term so both components can be combined consistently in one ascending score. This final step is a sound inference based on Microsoft's documented distance semantics and full-text rank range.
質問 # 42
You have a database named DB1. The schema is stored in a GitHub repository as an SDK style SQL database project.
You use a feature branch workflow to deploy changes to DB1
You need to update the local feature branch with the latest changes to main, and then create a pull request to merge the feature branch into main for review.
How should you complete the GitHub CLI script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.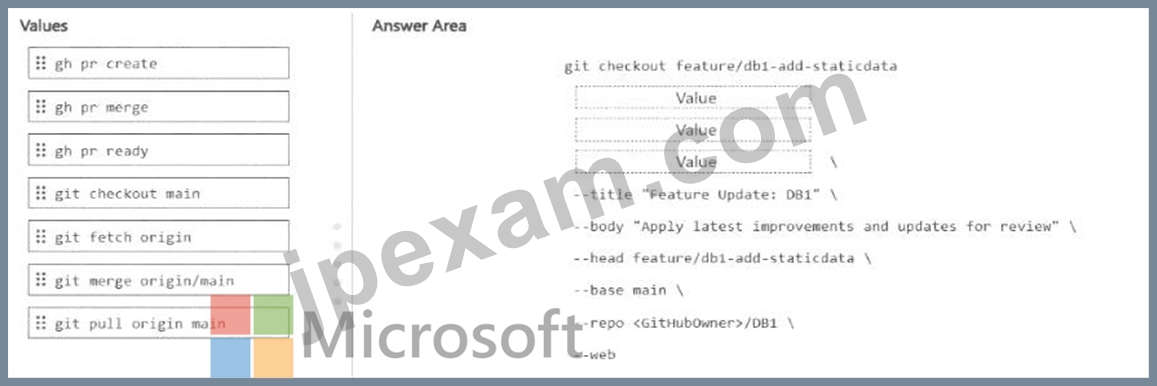
正解:
解説: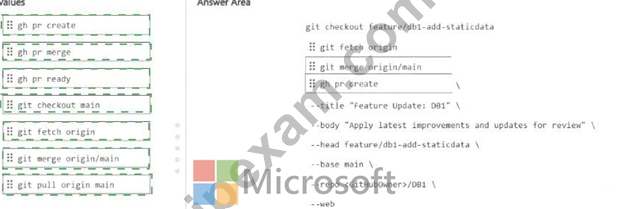
Explanation: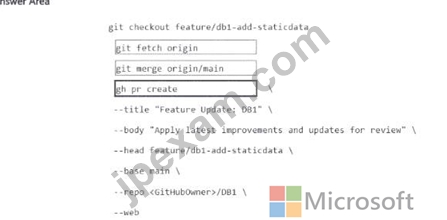
The correct sequence is:
* git fetch origin
* git merge origin/main
* gh pr create
This is the right workflow because the script starts on the local feature branch:
git checkout feature/db1-add-staticdata
To update that local feature branch with the latest changes from main, you first fetch the latest remote refs with git fetch origin , then merge the updated remote main branch into the current feature branch with git merge origin/main . After the feature branch is up to date, the correct GitHub CLI command to open the pull request is gh pr create . GitHub's CLI documentation shows that gh pr create is the command used to create a pull request, and supports flags such as --title, --body, --head, --base, --repo, and --web, which match the script shown in the question.
The other commands are not the best fit here:
* git checkout main would move you off the feature branch, which is not what you want before merging main into the feature branch.
* git pull origin main could update from remote main, but the script pattern here clearly separates fetching and then merging.
* gh pr merge merges an existing pull request, not create one.
* gh pr ready marks a draft PR as ready for review, but does not create the PR.
質問 # 43
You have an Azure SQL database that contains a column named Notes.
A security review discovers that Notes contains sensitive data.
You need to ensure that the data is protected so that neither the stored values nor the query inputs reveal information about the actual data. The solution must prevent a user from inferring relationships or repetitions in the data based on the encrypted output.
Which should you use?
正解:B
解説:
To protect sensitive Azure SQL database columns so that neither stored values nor query inputs reveal actual data--and to prevent inference of relationships/repetitions--Always Encrypted with Randomized Encryption is recommended. This approach ensures that data is encrypted on the client side, and the database engine never handles plaintext data or keys.
Key Recommendations:
Always Encrypted (Randomized): Use randomized encryption, which produces different encrypted values (ciphertext) for the same plaintext, preventing pattern analysis.
Azure Key Vault: Store column encryption keys in Azure Key Vault for secure, manageable key storage.
Client-side Encryption: Data is encrypted/decrypted within the application's memory using the SQL client driver, ensuring the database engine or high-privileged users cannot access the data.
Incorrect:
[Not D]
Deterministic Encryption: Allows matching queries (e.g., WHERE Column = 'Value'), but allows attackers to infer patterns and repetitions in data.
Transparent Data Encryption (TDE): Protects data at rest, but SQL users can still see plaintext data, violating the requirement.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-configure-always-encrypted-in-azure-sql- database/view
質問 # 44
Which tool helps orchestrate data pipelines for AI workflows?
正解:D
解説:
Azure Data Factory automates data movement and transformation pipelines.
質問 # 45
You have an Azure SQL database that contains a table named knowledgebase, knowledgebase stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_pnofiles and benefits_enrollnent that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.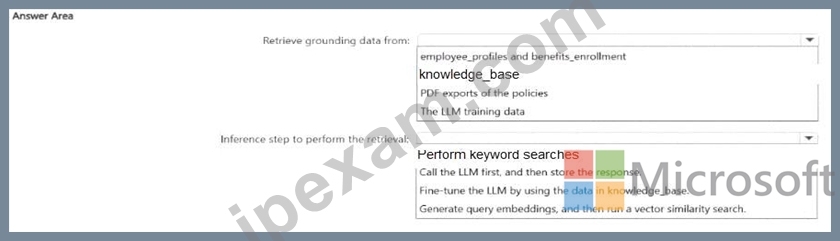
正解:
解説: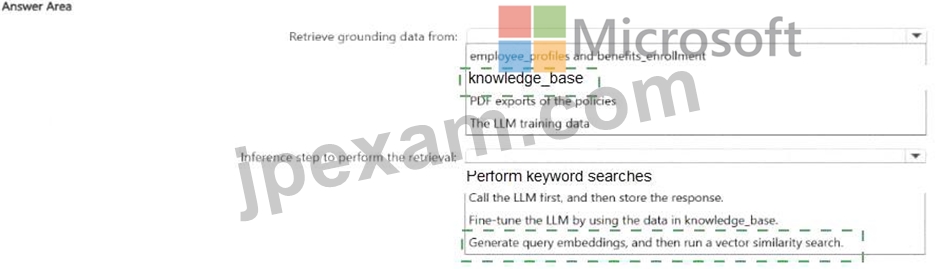
Explanation: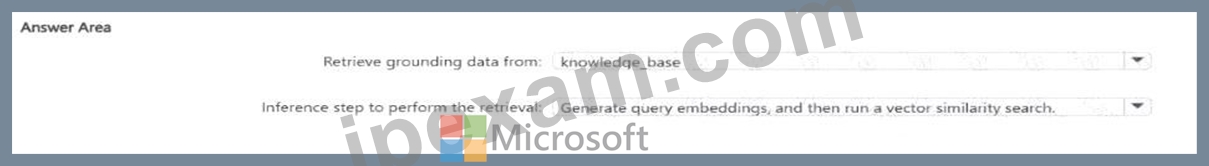
The correct recommendation is to retrieve grounding data from knowledge_base and, at inference time, generate query embeddings and run a vector similarity search .
The chatbot currently answers some general HR questions but fails when policies change and when users ask about internal policy documents by title or category . That is exactly the kind of problem RAG is meant to solve: ground the LLM in the organization's proprietary content instead of relying on the model's training data or unrelated transactional tables. Microsoft's RAG guidance states that RAG extends LLMs by grounding responses in your own content and that, for agentic retrieval, knowledge bases unify knowledge sources for retrieval.
So the grounding data should come from knowledge_base , because that table stores the HR policy documents and already includes fields like title, content, category, and embedding. Those are the fields directly tied to the missing and outdated policy answers. By contrast:
* employee_profiles and benefits_enrollment are operational HR tables, not the authoritative store for policy-document grounding.
* PDF exports of the policies would be inferior to querying the indexed/structured knowledge base already prepared for retrieval.
* The LLM training data is specifically the wrong source when the issue is outdated internal content.
For the retrieval step, Microsoft's guidance says to use embeddings for vector queries and notes that vector similarity search matches concepts, not exact terms . This is especially important because users ask about policy documents by title or category and also phrase questions in ways that might not exactly match document wording. Generating a query embedding and then running a vector similarity search is the appropriate retrieval step in a RAG pipeline.
質問 # 46
......
DP-800合格受験記: https://www.jpexam.com/DP-800_exam.html