If you have limited budget, and also need complete value package, why not try our Itcerttest's AI-200 exam training materials. It is easy to understand with reasonable price and high accuracy. It's suitable for all kinds of learners. If you choose Itcerttest' AI-200 Exam Training materials, you will get one year free renewable service.
| Section | Objectives |
|---|---|
| Topic 1: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 2: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 3: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 4: Connect to and consume Azure services | - Integrate Azure services
|
Our AI-200 test questions are available in three versions, including PDF versions, PC versions, and APP online versions. And AI-200 test material users can choose according to their own preferences. The most popular version is the PDF version of AI-200 exam prep. The PDF version of AI-200 test questions can be printed out to facilitate your learning anytime, anywhere, as well as your own priorities. The PC version of AI-200 Exam Prep is for Windows users. If you use the APP online version, just download the application program, you can enjoy our AI-200 test material service.
NEW QUESTION # 78
You are investigating high latency in an AI search application that processes millions of requests daily.
Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
* Include only data from the last 24 hours.
* Filter for failed requests only.
* Calculate the average duration of dependencies, grouped by operation.
The query must follow best practice to optimize the performance by minimizing the initial data scan.
You need to create the query.
In which order should perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.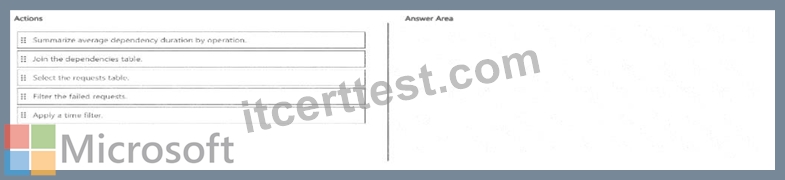
Answer:
Explanation: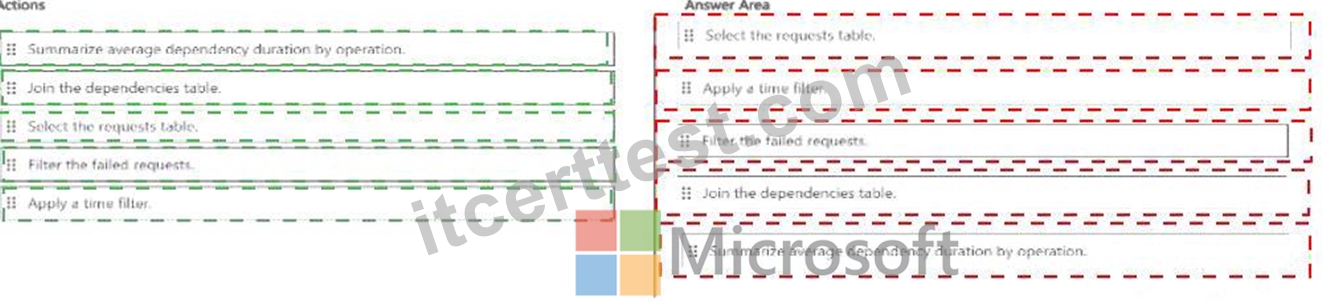
Explanation: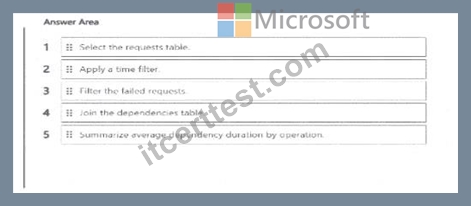
Verified Answer: 1) Select the requests table; 2) apply the 24-hour time filter; 3) filter failed requests; 4) join the dependencies table; 5) summarize average dependency duration by operation.
Detailed Explanation: KQL performs best when high-selectivity filters are applied as early as possible, especially the time predicate that limits the amount of data scanned. Starting from AppRequests, restricting to the last 24 hours, and then filtering failures reduces the left-side dataset before the join. The dependency table is then correlated with those requests, and aggregation is performed last to calculate average dependency duration by operation. Joining or summarizing before the time and failure filters would process more data than necessary.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Optimize log queries in Azure Monitor
NEW QUESTION # 79
You are deploying a model in Azure AI Foundry and must ensure the endpoint can handle unpredictable bursts of traffic while keeping cost low during idle periods. Which deployment type should you choose?
Answer: B
Explanation:
Standard pay-as-you-go deployments scale with token-based consumption and don't require reserving fixed throughput, making them cost-efficient for variable or bursty workloads. PTU is better suited for predictable, high-volume, latency-sensitive workloads where reserved capacity is justified.
NEW QUESTION # 80
You need to improve throughput for concurrent application requests to PostgreSQL.
What should you implement?
Answer: C
Explanation:
The correct solution is to implement connection pooling , ideally by using the built-in PgBouncer capability in Azure Database for PostgreSQL Flexible Server. Connection pooling allows many concurrent application requests to share and reuse a smaller set of established PostgreSQL server connections instead of repeatedly opening and closing database sessions. Microsoft notes that creating a new PostgreSQL connection for each operation consumes server resources because each connection involves its own backend process. Reusing pooled connections therefore reduces connection overhead, lowers CPU and memory consumption, and improves throughput for high-concurrency workloads.
This directly matches Fabrikam ' s stated requirement that database connections support high concurrency with minimal latency through connection optimization . PgBouncer can efficiently multiplex large numbers of client connections onto fewer PostgreSQL connections, particularly in transaction pooling mode.
Increasing max_connections is not the preferred solution because each additional PostgreSQL connection consumes memory and other resources; Microsoft explicitly recommends PgBouncer instead when more concurrent connections are required. Increasing shared_buffers addresses caching and memory allocation rather than connection-management overhead. Read replicas can scale read workloads, but they do not optimize the application ' s connection lifecycle.
Study Guide references: Azure Database for PostgreSQL Flexible Server # connection pooling; PgBouncer; connection management and high-concurrency performance.
NEW QUESTION # 81
You deploy an API to Azure Container Apps.
The solution must provide the following functionality:
* Support the concurrent activation of multiple application versions.
* Allocate a specific percentage of incoming requests to a secondary version You need to configure revision behavior.
Which configurations should you use? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.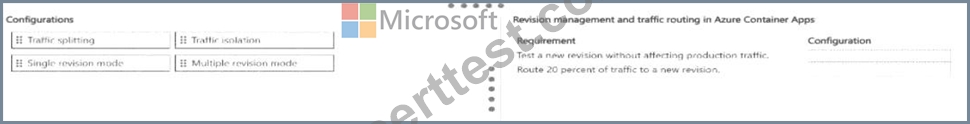
Answer:
Explanation: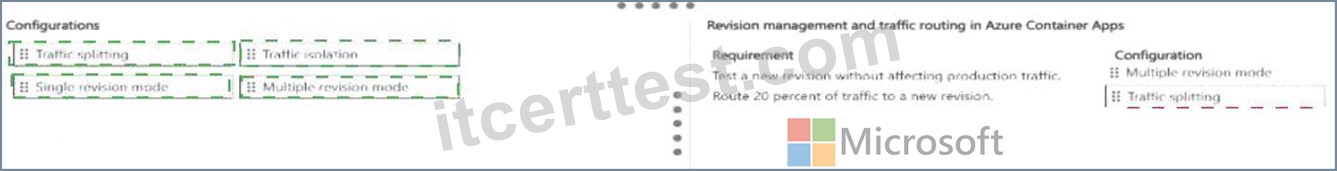
Explanation: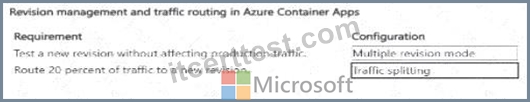
oncurrent active versions: Multiple revision mode. Route a percentage to the secondary version: Traffic splitting.
Detailed Explanation: Azure Container Apps supports side-by-side application versions through multiple revision mode. Once multiple revisions can be active, ingress traffic can be distributed by percentage across those revisions. This is the required combination for canary or controlled rollout scenarios. Single revision mode deactivates the previous revision as a new one becomes active, while traffic splitting is the specific feature that assigns a percentage of incoming requests to each active revision.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Azure Container Apps revisions
NEW QUESTION # 82
Drag and Drop Question
You are investigating high latency in an AI search application that processes millions of requests daily. Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
- Include only data from the last 24 hours.
- Filter for failed requests only.
- Calculate the average duration of dependencies, grouped by operation.
The query must be optimized for performance by minimizing the initial data scan.
You need to create the query.
Which five actions should you perform in sequence? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.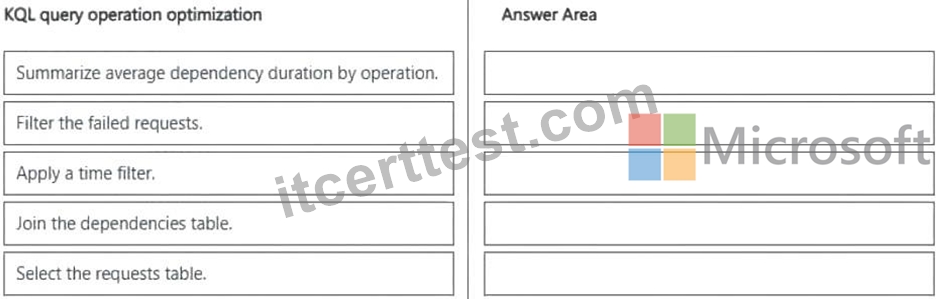
Answer:
Explanation: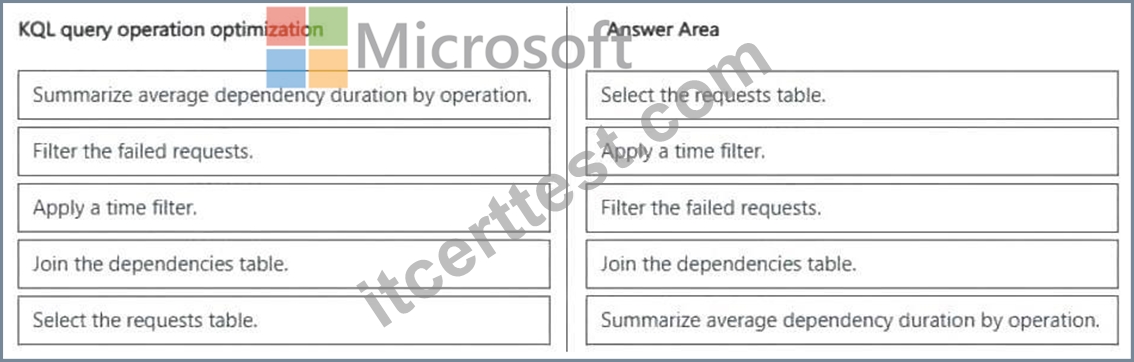
Explanation:
Step 1: Select the requests table
Starts the query stream with the primary base table.
Step 2: Apply a time filter
Such as (where timestamp >= ago(1d))
Restricts the dataset to the last 24 hours immediately to optimize performance by reducing the scan size.
Step 3: Filter the failed requests
where success == false or resultCode checks
Narrows down rows to only failures before performing resource-heavy operations.
Step 4: Join the dependencies table
(join AppDependencies): Correlates the filtered request subset with dependency data using common tracking identifiers.
Step 5: Summarize average dependency duration by operation (summarize avg(duration) by operation) Computes the final aggregated metrics grouped by the operation name.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/logs/get-started-queries
NEW QUESTION # 83
......
The experts in our company have been focusing on the AI-200 examination for a long time and they never overlook any new knowledge. The content of our AI-200 study materials has always been kept up to date. Don't worry if any new information comes out after your purchase of our AI-200 Study Guide. We will inform you by E-mail when we have a new version. We can ensure you a pass rate as high as 99%. If you don't pass the AI-200 exam, you will get a refund. Why not study and practice for just 20 to 30 hours and then pass the examination?
AI-200 Latest Dumps Questions: https://www.itcerttest.com/AI-200_braindumps.html