Comprehensive Databricks Certified-Data-Engineer-Professional Questions in PDF Format

It is universally acknowledged that Databricks certification can help present you as a good master of some knowledge in certain areas, and it also serves as an embodiment in showcasing one’s personal skills. However, it is easier to say so than to actually get the Databricks certification. We have to understand that not everyone is good at self-learning and self-discipline, and thus many people need outside help to cultivate good study habits, especially those who have trouble in following a timetable. To handle this, our Certified-Data-Engineer-Professional test training will provide you with a well-rounded service so that you will not lag behind and finish your daily task step by step. At the same time, our Certified-Data-Engineer-Professional study torrent will also save your time and energy in well-targeted learning as we are going to make everything done in order that you can stay focused in learning our Certified-Data-Engineer-Professional study materials without worries behind. We are so honored and pleased to be able to read our detailed introduction and we will try our best to enable you a better understanding of our Certified-Data-Engineer-Professional test training better.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Topic 2: Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data
- Apply advanced Spark transformations
|
| Topic 3: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs
- Implement row-level security, column masking, and compliance
|
| Topic 4: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines
- Apply AUTO CDC APIs and exactly-once semantics
|
| Topic 5: Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
- Manage dependencies, libraries, and UDFs
- Implement scalable Python/SQL code and project structures
|
| Topic 6: Data Modeling | ~10% | - Apply dimensional modeling techniques
- Design scalable Delta Lake schemas and clustering
|
| Topic 7: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables
- Diagnose common pipeline and job failures
|
| Topic 8: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines
- Deploy with Declarative Automation Bundles, CLI, and REST API
|
| Topic 9: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools
- Optimize queries, clusters, and storage
|
>> Certified-Data-Engineer-Professional Latest Dumps Book <<
Valid Dumps Certified-Data-Engineer-Professional Book, New Certified-Data-Engineer-Professional Braindumps Questions
As we all know that the higher position always ask for the more capable man. So your strength and efficiency will really bring you more job opportunities. You must complete your goals in the shortest possible time. How to make it? Our Certified-Data-Engineer-Professional exam materials can give you a lot of help. Our Certified-Data-Engineer-Professional Study Guide is famous for its high-effective and high-efficiency advantages. If you study with our Certified-Data-Engineer-Professional practice engine, you can get the latest and specialized information in the subject and you will be rewarded with the certification.
Databricks Certified Data Engineer Professional Sample Questions (Q208-Q213):
NEW QUESTION # 208
The data engineering team has configured a job to process customer requests to be forgotten (have their data deleted). All user data that needs to be deleted is stored in Delta Lake tables using default table settings.
The team has decided to process all deletions from the previous week as a batch job at 1am each Sunday. The total duration of this job is less than one hour. Every Monday at 3am, a batch job executes a series of VACUUM commands on all Delta Lake tables throughout the organization.
The compliance officer has recently learned about Delta Lake's time travel functionality. They are concerned that this might allow continued access to deleted data.
Assuming all delete logic is correctly implemented, which statement correctly addresses this concern?
- A. Because the default data retention threshold is 7 days, data files containing deleted records will be retained until the vacuum job is run 8 days later.
- B. Because Delta Lake's delete statements have ACID guarantees, deleted records will be permanently purged from all storage systems as soon as a delete job completes.
- C. Because the default data retention threshold is 24 hours, data files containing deleted records will be retained until the vacuum job is run the following day.
- D. Because Delta Lake time travel provides full access to the entire history of a table, deleted records can always be recreated by users with full admin privileges.
- E. Because the vacuum command permanently deletes all files containing deleted records, deleted records may be accessible with time travel for around 24 hours.
Answer: A
Explanation:
https://learn.microsoft.com/en-us/azure/databricks/delta/vacuum
NEW QUESTION # 209
What statement is true regarding the retention of job run history?
- A. It is retained until you export or delete job run logs
- B. It is retained for 90 days or until the run-id is re-used through custom run configuration
- C. It is retained for 60 days, during which you can export notebook run results to HTML
- D. It is retained for 60 days, after which logs are archived
- E. It is retained for 30 days, during which time you can deliver job run logs to DBFS or S3
Answer: C
Explanation:
https://docs.databricks.com/en/workflows/jobs/monitor-job-runs.html
NEW QUESTION # 210
A Data Engineer is building a simple data pipeline using Lakeflow Declarative Pipelines (LDP) in Databricks to ingest customer data. The raw customer data is stored in a cloud storage location in JSON format. The task is to create Lakeflow Declarative Pipelines that read the raw JSON data and write it into a Delta table for further processing. Which code snippet will correctly ingest the raw JSON data and create a Delta table using LDP?
- A. import dlt
@dlt.table
def raw_customers():
return spark.read.json("s3://my-bucket/raw-customers/") - B. import dlt
@dlt.table
def raw_customers():
return spark.read.format("csv").load("s3://my-bucket/raw-customers/") - C. import dlt
@dlt.view
def raw_customers():
return spark.format.json("s3://my-bucket/raw-customers/") - D. import dlt
@dlt.table
def raw_customers():
return spark.read.format("parquet").load("s3://my-bucket/raw-customers/")
Answer: A
Explanation:
The correct method to define a table using Lakeflow Declarative Pipelines (LDP) is with the
@dlt.table decorator, which persists the output as a managed Delta table. When ingesting raw JSON data, spark.read.json() or spark.read.format("json").load() is the standard approach. This reads JSON- formatted files from the source and stores them in Delta format automatically managed by Databricks.
NEW QUESTION # 211
The following table consists of items found in user carts within an e-commerce website.
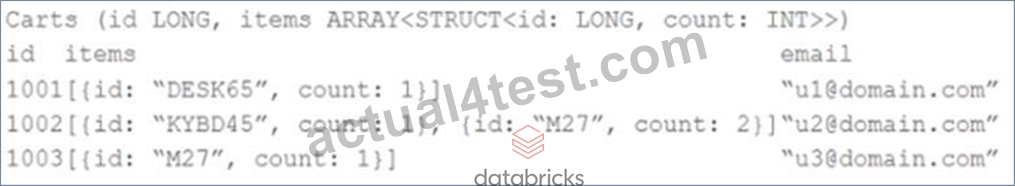
The following MERGE statement is used to update this table using an updates view, with schema evolution enabled on this table.
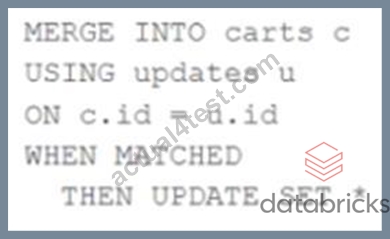
How would the following update be handled?

- A. The update is moved to separate ''restored'' column because it is missing a column expected in the target schema.
- B. The new restored field is added to the target schema, and dynamically read as NULL for existing unmatched records.
- C. The new nested field is added to the target schema, and files underlying existing records are updated to include NULL values for the new field.
- D. The update throws an error because changes to existing columns in the target schema are not supported.
Answer: C
Explanation:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGE operation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
NEW QUESTION # 212
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
- A. Use dropDuplicates() to remove out-of-order and duplicate records in LDP.
- B. Set track_history_column_list to [event_timestamp, event_id] in AUTO CDC APIs.
- C. Use SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) in AUTO CDC APIs.
- D. Use a window function to sort update_sequence_id within the same partition, i.e., update_timestamp in the LDP pipeline.
Answer: C
Explanation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration.
Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
NEW QUESTION # 213
......
Sometimes hesitating will lead to missing a lot of opportunities. If you think a lot of our Certified-Data-Engineer-Professional exam dumps PDF, you should not hesitate again. Too much hesitating will just waste a lot of time. Our Certified-Data-Engineer-Professional exam dumps PDF can help you prepare casually and pass exam easily. If you make the best use of your time and obtain a useful certification you may get a senior position ahead of others. Chance favors the prepared mind. Actual4test provide the best Certified-Data-Engineer-Professional Exam Dumps Pdf materials in this field which is helpful for you.
Valid Dumps Certified-Data-Engineer-Professional Book: https://www.actual4test.com/Certified-Data-Engineer-Professional_examcollection.html
- HOT Certified-Data-Engineer-Professional Latest Dumps Book - The Best Databricks Valid Dumps Certified-Data-Engineer-Professional Book: Databricks Certified Data Engineer Professional 🕗 Immediately open ➽ www.prep4sures.top 🢪 and search for ➥ Certified-Data-Engineer-Professional 🡄 to obtain a free download 💹Certified-Data-Engineer-Professional New Dumps Ebook
- Test Certified-Data-Engineer-Professional Voucher 🖼 Certified-Data-Engineer-Professional Valid Dumps 🆒 Certified-Data-Engineer-Professional Exam Duration 🔎 Open ➠ www.pdfvce.com 🠰 and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download exam materials for free 🈵Trustworthy Certified-Data-Engineer-Professional Dumps
- HOT Certified-Data-Engineer-Professional Latest Dumps Book - The Best Databricks Valid Dumps Certified-Data-Engineer-Professional Book: Databricks Certified Data Engineer Professional 👴 Easily obtain free download of ( Certified-Data-Engineer-Professional ) by searching on ( www.torrentvce.com ) 📕Reliable Exam Certified-Data-Engineer-Professional Pass4sure
- Trustworthy Certified-Data-Engineer-Professional Dumps ❎ Valid Test Certified-Data-Engineer-Professional Tips 🏍 Certified-Data-Engineer-Professional New Dumps Ebook 🤶 Enter “ www.pdfvce.com ” and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download for free 👎Certified-Data-Engineer-Professional Exam Questions Vce
- Certified-Data-Engineer-Professional Exam Duration 🍠 Trustworthy Certified-Data-Engineer-Professional Dumps 💸 Certified-Data-Engineer-Professional Exam Duration 💿 Search for ( Certified-Data-Engineer-Professional ) and download it for free immediately on ⇛ www.prepawaypdf.com ⇚ 🤓Certified-Data-Engineer-Professional Valid Dumps
- Trustworthy Certified-Data-Engineer-Professional Dumps 🙊 New Certified-Data-Engineer-Professional Exam Labs ⛵ Valid Test Certified-Data-Engineer-Professional Tips ‼ Download ➠ Certified-Data-Engineer-Professional 🠰 for free by simply searching on 【 www.pdfvce.com 】 😺Latest Certified-Data-Engineer-Professional Exam Testking
- Reliable Exam Certified-Data-Engineer-Professional Pass4sure 🕒 Dump Certified-Data-Engineer-Professional Collection 🦺 Certified-Data-Engineer-Professional Top Exam Dumps 🍬 Download ➽ Certified-Data-Engineer-Professional 🢪 for free by simply searching on ➡ www.troytecdumps.com ️⬅️ ✉Latest Certified-Data-Engineer-Professional Exam Testking
- Certified-Data-Engineer-Professional Dumps PDF 😬 Certified-Data-Engineer-Professional Exam Questions Vce 🍨 Certified-Data-Engineer-Professional Dumps Questions 🌶 Download ⮆ Certified-Data-Engineer-Professional ⮄ for free by simply searching on 《 www.pdfvce.com 》 🍧Certified-Data-Engineer-Professional Latest Test Online
- HOT Certified-Data-Engineer-Professional Latest Dumps Book - The Best Databricks Valid Dumps Certified-Data-Engineer-Professional Book: Databricks Certified Data Engineer Professional 🛀 Open ➡ www.testkingpass.com ️⬅️ and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download exam materials for free 🐭Dump Certified-Data-Engineer-Professional Collection
- Latest Certified-Data-Engineer-Professional Latest Dumps Book – 100% Valid Valid Dumps Databricks Certified Data Engineer Professional Book 📡 The page for free download of ☀ Certified-Data-Engineer-Professional ️☀️ on 《 www.pdfvce.com 》 will open immediately 🆘Certified-Data-Engineer-Professional Latest Test Online
- Certified-Data-Engineer-Professional Exam Duration 🗳 Trustworthy Certified-Data-Engineer-Professional Dumps 🥎 Certified-Data-Engineer-Professional Valid Exam Question 📒 Download “ Certified-Data-Engineer-Professional ” for free by simply searching on ☀ www.troytecdumps.com ️☀️ 🛩Top Certified-Data-Engineer-Professional Exam Dumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, faithlife.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, tooter.in, zenwriting.net, Disposable vapes