Best Databricks-Certified-Data-Engineer-Professional Vce, Databricks-Certified-Data-Engineer-Professional Passleader Review

SurePassExams has designed Databricks Certified Data Engineer Professional Exam which has actual exam Dumps questions, especially for the students who are willing to pass the Databricks Databricks-Certified-Data-Engineer-Professional exam for the betterment of their future. The study material is available in three different formats. Databricks Practice Exam are also available so the students can test their preparation with unlimited tries and pass Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) certification exam on the first try.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Processing | 28% | - Structured Streaming
- ETL Pipelines
- Data Transformation
- Spark SQL
|
| Topic 2: Data Modeling and Storage | 20% | - Storage Optimization
- File Formats
- Data Modeling
|
| Topic 3: Databricks Lakehouse Platform | 24% | - Lakehouse Architecture
- Delta Lake
- Unity Catalog
- Data Management
|
| Topic 4: Data Quality and Governance | 12% | - Governance
- Data Quality
- Data Lineage
|
| Topic 5: Monitoring and Troubleshooting | 16% | - Monitoring
- Troubleshooting
- Performance Optimization
|
>> Best Databricks-Certified-Data-Engineer-Professional Vce <<
Newest Best Databricks-Certified-Data-Engineer-Professional Vce & Latest Databricks Certification Training - High Pass-Rate Databricks Databricks Certified Data Engineer Professional Exam
Computer brings more convenience, online access to information, published an article, watch movies, online remote virtual learning and other benefits. IT workers are becoming high-salary field in all over the world. SurePassExams releases latest and valid Databricks-Certified-Data-Engineer-Professional Exam preparations to help candidates clear exams certainly as Databricks certifications are outstanding and attractive. If you determine to take part in exams, our Databricks-Certified-Data-Engineer-Professional exam preparations will be a good helper.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q138-Q143):
NEW QUESTION # 138
The data architect has mandated that all tables in the Lakehouse should be configured as external (also known as "unmanaged") Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When data is saved to a table, make sure that a full file path is specified alongside the Delta format.
- B. When configuring an external data warehouse for all table storage, leverage Databricks for all ELT.
- C. When a database is being created, make sure that the LOCATION keyword is used.
- D. When tables are created, make sure that the EXTERNAL keyword is used in the CREATE TABLE statement.
- E. When the workspace is being configured, make sure that external cloud object storage has been mounted.
Answer: D
Explanation:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from To create an external or unmanaged Delta Lake table, you need to use the EXTERNAL keyword in the CREATE TABLE statement. This indicates that the table is not managed by the catalog and the data files are not deleted when the table is dropped. You also need to provide a LOCATION clause to specify the path where the data files are stored.
For example:
CREATE EXTERNAL TABLE events ( date DATE, eventId STRING, eventType STRING, data STRING) USING DELTA LOCATION `/mnt/delta/events'; This creates an external Delta Lake table named events that references the data files in the
`/mnt/delta/events' path. If you drop this table, the data files will remain intact and you can recreate the table with the same statement.
NEW QUESTION # 139
A production workload incrementally applies updates from an external Change Data Capture feed to a Delta Lake table as an always-on Structured Stream job. When data was initially migrated for this table, OPTIMIZE was executed and most data files were resized to 1 GB. Auto Optimize and Auto Compaction were both turned on for the streaming production job. Recent review of data files shows that most data files are under 64 MB, although each partition in the table contains at least 1 GB of data and the total table size is over 10 TB.
Which of the following likely explains these smaller file sizes?
- A. Databricks has autotuned to a smaller target file size based on the overall size of data in the table
- B. Databricks has autotuned to a smaller target file size based on the amount of data in each partition
- C. Z-order indices calculated on the table are preventing file compaction C Bloom filler indices calculated on the table are preventing file compaction
- D. Databricks has autotuned to a smaller target file size to reduce duration of MERGE operations
Answer: D
Explanation:
This is the correct answer because Databricks has a feature called Auto Optimize, which automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones and sorting data within each file by a specified column. However, Auto Optimize also considers the trade- off between file size and merge performance, and may choose a smaller target file size to reduce the duration of merge operations, especially for streaming workloads that frequently update existing records. Therefore, it is possible that Auto Optimize has autotuned to a smaller target file size based on the characteristics of the streaming production job.
NEW QUESTION # 140
A security analytics pipeline must enrich billions of raw connection logs with geolocation data.
The join hinges on finding which IPv4 range each event's address falls into.
Table 1: network_events ( 5 billion rows)
event_id ip_int
42 3232235777
Table 2: ip_ranges ( 2 million rows)
start_ip_int end_ip_int country
3232235520 3232236031 US
The query is currently very slow:
SELECT n.event_id, n.ip_int, r.country
FROM network_events n
JOIN ip_ranges r
ON n.ip_int BETWEEN r.start_ip_int AND r.end_ip_int;
Which change will most dramatically accelerate the query while preserving its logic?
- A. Add a broadcast hint: /*+ BROADCAST(r) */ for ip_ranges.
- B. Force a sort-merge join with /*+ MERGE(r) */.
- C. Increase spark.sql.shuffle.partitions from 200 to 10000.
- D. Add a range-join hint /*+ RANGE_JOIN(r, 65536) */.
Answer: D
Explanation:
The query joins billions of rows (network_events) with millions of rows (ip_ranges) using a range predicate (BETWEEN). Unlike equality joins (=), range joins are not efficiently handled by broadcast or sort-merge joins because:
Broadcast Join (D): Effective for small tables but only for equality joins. Since this query uses a range condition, broadcast will not reduce the complexity of scanning billions of records across non-equality conditions.
Sort-Merge Join (C): Works for ordered joins but is inefficient on range conditions. Sorting billions of records adds excessive overhead and will not resolve the bottleneck.
Increasing Shuffle Partitions (A): Only spreads out shuffle work but does not address the fundamental inefficiency of range-based lookups at scale.
Range Joins in Spark (RANGE_JOIN hint):
Databricks provides range join optimizations specifically for conditions such as BETWEEN. By applying a RANGE_JOIN hint, Spark can build optimized data structures (such as interval indexes or partition pruning strategies) that map billions of input rows to ranges much faster. This avoids brute- force scans and unnecessary shuffle costs.
Thus, Option B is the correct solution because:
It leverages range-join optimization, which is purpose-built for queries joining massive event logs to smaller lookup tables with IP ranges.
This ensures Spark can evaluate billions of rows against millions of ranges with optimized matching logic, drastically improving query performance while preserving correctness.
NEW QUESTION # 141
A view is registered with the following code:
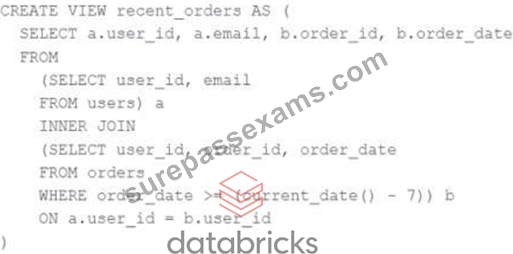
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- B. The versions of each source table will be stored in the table transaction log; query results will be saved to DBFS with each query.
- C. All logic will execute when the table is defined and store the result of joining tables to the DBFS; this stored data will be returned when the table is queried.
- D. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
Answer: D
NEW QUESTION # 142
The business intelligence team has a dashboard configured to track various summary metrics for retail stories. This includes total sales for the previous day alongside totals and averages for a variety of time periods. The fields required to populate this dashboard have the following schema:

For Demand forecasting, the Lakehouse contains a validated table of all itemized sales updated incrementally in near real-time. This table named products_per_order, includes the following fields:

Because reporting on long-term sales trends is less volatile, analysts using the new dashboard only require data to be refreshed once daily. Because the dashboard will be queried interactively by many users throughout a normal business day, it should return results quickly and reduce total compute associated with each materialization.
Which solution meets the expectations of the end users while controlling and limiting possible costs?
- A. Use the Delta Cache to persists the products_per_order table in memory to quickly the dashboard with each query.
- B. Define a view against the products_per_order table and define the dashboard against this view.
- C. Populate the dashboard by configuring a nightly batch job to save the required values as a table overwritten with each update.
- D. Use Structure Streaming to configure a live dashboard against the products_per_order table within a Databricks notebook.
- E. Configure a webhook to execute an incremental read against products_per_order each time the dashboard is refreshed.
Answer: C
NEW QUESTION # 143
......
For candidates who are going to buy Databricks-Certified-Data-Engineer-Professional learning materials online, they may pay more attention to that money safety. We apply international recognition third party for the payment, and therefore your account and money safety can be guaranteed if you choose Databricks-Certified-Data-Engineer-Professional exam materials from us. In attrition, in order to build up your confidence for Databricks-Certified-Data-Engineer-Professional Exam Dumps, we are pass guarantee and money back guarantee. If you fail to pass the exam in your first attempt, we will give you full refund and no other questions will be asked. You give us trust, and we help you pass the exam successfully.
Databricks-Certified-Data-Engineer-Professional Passleader Review: https://www.surepassexams.com/Databricks-Certified-Data-Engineer-Professional-exam-bootcamp.html
- Databricks-Certified-Data-Engineer-Professional Valid Braindumps Book 🥉 Practice Databricks-Certified-Data-Engineer-Professional Tests 🎭 Exam Databricks-Certified-Data-Engineer-Professional Vce 🕊 Open website ( www.examcollectionpass.com ) and search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ for free download ✌Study Databricks-Certified-Data-Engineer-Professional Plan
- Effective Databricks Databricks-Certified-Data-Engineer-Professional Exam Preparation In a Short Time 🔷 【 www.pdfvce.com 】 is best website to obtain ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ for free download 😃Databricks-Certified-Data-Engineer-Professional Reliable Test Simulator
- Databricks-Certified-Data-Engineer-Professional Mock Test 🚘 Databricks-Certified-Data-Engineer-Professional Download Demo 🥑 Practice Databricks-Certified-Data-Engineer-Professional Tests 🔊 Enter “ www.examcollectionpass.com ” and search for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ to download for free ⭐Databricks-Certified-Data-Engineer-Professional Download Demo
- Free Databricks-Certified-Data-Engineer-Professional Sample 🍛 Databricks-Certified-Data-Engineer-Professional Test Certification Cost 🧟 Databricks-Certified-Data-Engineer-Professional Test Certification Cost 🍼 Easily obtain free download of ▷ Databricks-Certified-Data-Engineer-Professional ◁ by searching on ➠ www.pdfvce.com 🠰 🥣Exam Databricks-Certified-Data-Engineer-Professional Vce
- New Databricks-Certified-Data-Engineer-Professional Test Materials 🐈 Databricks-Certified-Data-Engineer-Professional Mock Test ⛪ Exam Databricks-Certified-Data-Engineer-Professional Vce 👰 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ and download exam materials for free through ☀ www.testkingpass.com ️☀️ 🧣Reliable Databricks-Certified-Data-Engineer-Professional Exam Simulations
- Databricks - Databricks-Certified-Data-Engineer-Professional - Best Databricks Certified Data Engineer Professional Exam Vce ⏏ Search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 on ( www.pdfvce.com ) immediately to obtain a free download ↙Databricks-Certified-Data-Engineer-Professional Reliable Test Simulator
- Best Databricks-Certified-Data-Engineer-Professional Vce - 100% Pass Quiz 2026 Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam First-grade Passleader Review ❤️ ⮆ www.exam4labs.com ⮄ is best website to obtain [ Databricks-Certified-Data-Engineer-Professional ] for free download 🍱Practice Databricks-Certified-Data-Engineer-Professional Tests
- Effective Databricks Databricks-Certified-Data-Engineer-Professional Exam Preparation In a Short Time 🔳 The page for free download of ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ on ✔ www.pdfvce.com ️✔️ will open immediately 🏳Databricks-Certified-Data-Engineer-Professional Valid Exam Questions
- Databricks-Certified-Data-Engineer-Professional Valid Braindumps Book 🦔 Study Databricks-Certified-Data-Engineer-Professional Plan ⏏ New Databricks-Certified-Data-Engineer-Professional Exam Answers 😩 Easily obtain free download of ▛ Databricks-Certified-Data-Engineer-Professional ▟ by searching on ➠ www.testkingpass.com 🠰 🩳Databricks-Certified-Data-Engineer-Professional Test Certification Cost
- Databricks-Certified-Data-Engineer-Professional Download Demo 🍻 Databricks-Certified-Data-Engineer-Professional Frenquent Update 📈 Databricks-Certified-Data-Engineer-Professional Download Demo 🧙 ⇛ www.pdfvce.com ⇚ is best website to obtain ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ for free download 🚏Databricks-Certified-Data-Engineer-Professional Frenquent Update
- Pass Guaranteed Quiz 2026 Valid Databricks Databricks-Certified-Data-Engineer-Professional: Best Databricks Certified Data Engineer Professional Exam Vce 🥯 Search on ▛ www.pdfdumps.com ▟ for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ to obtain exam materials for free download ☁Databricks-Certified-Data-Engineer-Professional Reliable Test Simulator
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes