MogiExamのMicrosoftのDP-750試験トレーニング資料の知名度が非常に高いことを皆はよく知っています。MogiExam は世界的によく知られているサイトです。どうしてこのような大きな連鎖反応になりましたか。それはMogiExamのMicrosoftのDP-750試験トレーニング資料は適用性が高いもので、本当にみなさんが良い成績を取ることを助けられるからです。
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
多くの大学生、多くの労働者、さらに多くの主婦など、DP-750試験に合格するために最善を尽くす人が増えています。 DP-750試験に合格したいこれらの人々は、試験を自分自身を向上させ、大きな進歩を遂げる唯一の機会と考えています。そのため、彼らはDP-750試験の準備に全力を尽くすことを望んでいますが、多くの人が重要なDP-750試験の準備に十分な時間がないことは明らかです。 DP-750試験の質問は、最小限の時間と労力でDP-750試験に合格するのに役立ちます。
質問 # 92
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.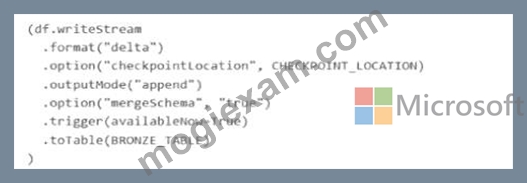
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.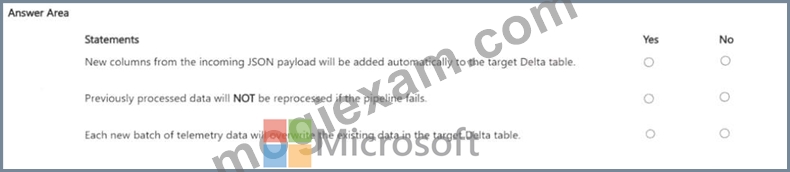
正解:
解説: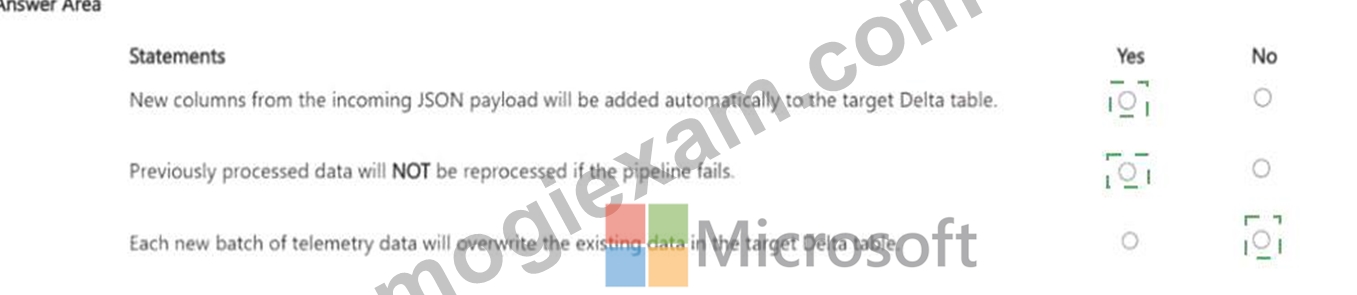
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: ' overwrite ' replaces existing data; ' append ' adds to it.
Always check whether the code uses the correct Delta format (.format( ' delta ' )), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
質問 # 93
You need to complete the PySpark code for the Spark Structured Streaming pipelines. The solution must meet the data ingestion and processing requirements.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.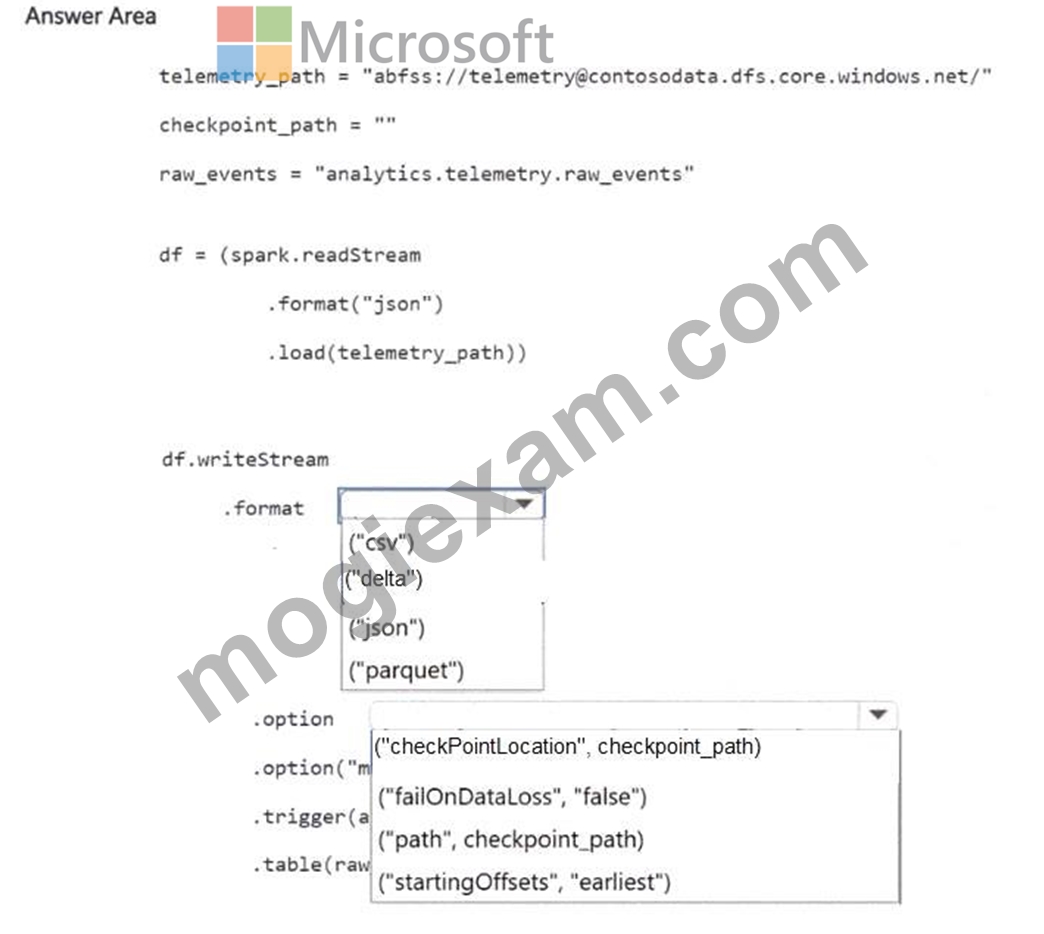
正解:
解説: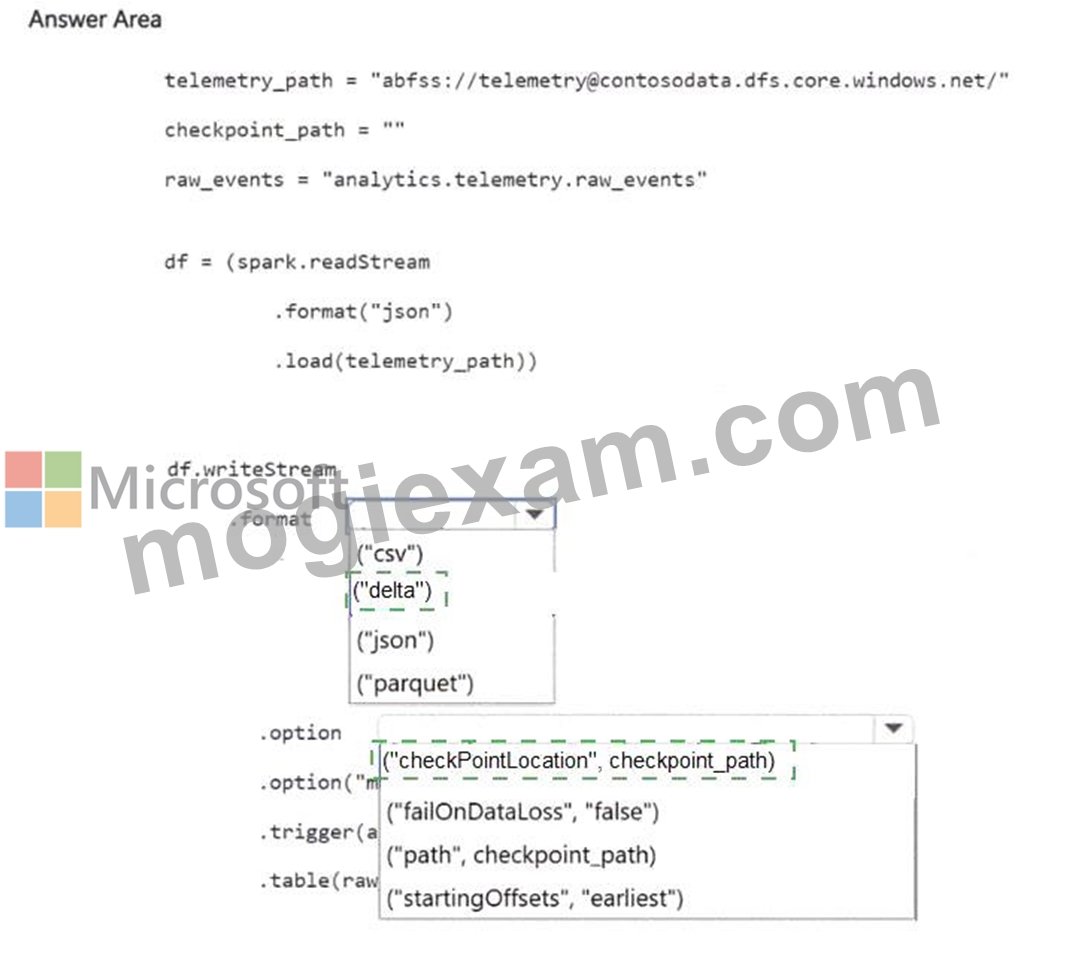
Explanation:
The solution requires spark.readStream with format('cloudFiles') for Auto Loader, paired with .writeStream using mergeSchema=true and a checkpointLocation.
Auto Loader's cloudFiles source incrementally processes new JSON files without rescanning the entire directory. The mergeSchema option handles schema drift - when sensors add new fields, the target Delta table schema expands automatically instead of throwing a parse error. This directly addresses Contoso's requirement to 'support schema drift.' The checkpointLocation is what gives the pipeline its resilience. Databricks writes the stream's committed offset and schema state to that path. If the cluster restarts, the engine reads the checkpoint and picks up exactly where it left off - no events are reprocessed, satisfying 'exactly-once semantics' and 'resume processing after failures without reprocessing the data.' Without a checkpoint, the stream would restart from the beginning on every cluster bounce, which is precisely the problem Contoso is trying to eliminate.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/schema
質問 # 94
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1.
Table1 stores customer profile data.
Business users must analyze how customer profile records change over time. They must also be able to query earlier versions of the table.
You need to implement a solution that:
* Maintains persistent historical versions of customer profile records for long-term analysis.
* Allows users to query earlier versions of the Delta table.
* Minimizes maintenance effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.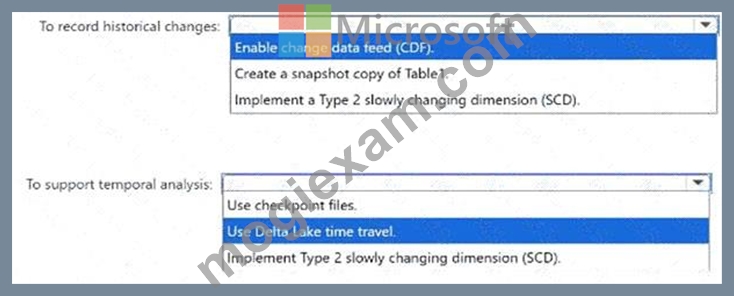
正解:
解説: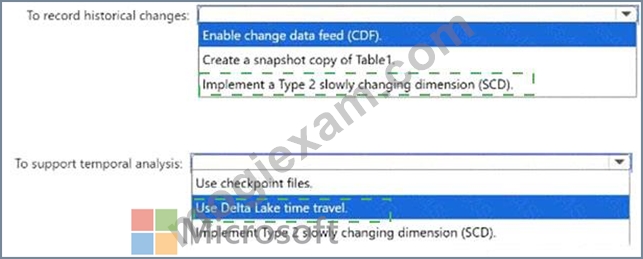
Explanation:
To record historical changes: Implement a Type 2 slowly changing dimension (SCD).
To support temporal analysis: Use Delta Lake time travel.
A Type 2 slowly changing dimension preserves customer-profile history by inserting a new record whenever a tracked attribute changes instead of overwriting the existing record. Effective dates, expiration dates, version values, or current-record indicators can identify which version applied during a particular period. This provides persistent business history for long-term analysis. Delta Lake time travel supports temporal analysis of the physical table by allowing users to query an earlier version with VERSION AS OF or TIMESTAMP AS OF. Time travel is useful for auditing and reproducing previous results, but its availability depends on retained Delta log entries and data files. Therefore, it should not replace a Type 2 SCD for permanent customer history. Together, the two features satisfy the historical-record and earlier-version requirements.
質問 # 95
You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
What should you do?
正解:B
解説:
The correct answer is D. Breaking the pipeline into separate tasks for ingestion, cleansing, and curation is the foundation of well-designed Lakeflow Jobs pipelines. Each task should own one responsibility - when a task does too much, debugging a failure becomes a hunt through unrelated code, and retry logic becomes expensive because you re-execute work that already succeeded.
Contoso ' s planned changes explicitly call for ' a clear execution order and dependencies ' and ' orchestrate multi-step ingestion and transformation workflows. ' Separate tasks map directly to those goals: Lakeflow Jobs tracks each task ' s status independently, so if cleansing fails, ingestion doesn ' t re-run.
Option A bundles everything into one notebook, which means a curation bug forces a full re-ingestion. Option B copies logic three times - any future change must be applied in triplicate, which is a maintenance hazard.
Option C forces everything through SQL MERGE, which is the wrong tool for raw-event ingestion and doesn
' t address cleansing or schema drift.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/
質問 # 96
Which operation guarantees ACID compliance in Delta Lake?
正解:C
解説:
Delta Lake ensures ACID compliance through its transaction log (Delta log). It tracks all changes, enabling consistency, isolation, and rollback capabilities. File append operations alone are not transactional. RDD transformations are low-level and not ACID-aware.
質問 # 97
......
Microsoft持ってきた製品があなたにふさわしくないと感じることはよくありますか? Microsoftラーニングガイドを使用することに決めた場合、問題に遭遇することは決してないことをお伝えしたいと思います。 私たちの教材は、あなたが期待できないDP-750高品質を持っています。 学習教材のガイダンスで経験を積むと、以前よりもDP-750時間を費やさず、明らかにImplementing Data Engineering Solutions Using Azure Databricks進歩を感じることができます。また、Microsoftテストクイズは進歩に役立つことがわかります。
DP-750難易度: https://www.mogiexam.com/DP-750-exam.html