私たちのウェブサイトから見ると、AI-300学習教材は3つのバージョンがあります。PDF、ソフトウェアとオンライン版です。PDF版は印刷できます。ソフトウェアとオンライン版はコンピュータで使用できます。コンピュータで学ぶことが難しい場合は、AI-300学習教材の印刷資料で勉強できます。また、AI-300学習教材の価格は合理的に設定されています。
| Section | Weight | Objectives |
|---|---|---|
| Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Implement machine learning model lifecycle and operations | 25–30% | - Orchestrate model training and experimentation
|
| Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
MicrosoftのAI-300試験の認定はIT業種で欠くことができない認証です。では、どうやって、最も早い時間でMicrosoftのAI-300認定試験に合格するのですか。It-Passportsは君にとって最高な選択になっています。It-PassportsのMicrosoftのAI-300試験トレーニング資料はIt-PassportsのIT専門家たちが研究して、実践して開発されたものです。その高い正確性は言うまでもありません。もし君はいささかな心配することがあるなら、あなたはうちの商品を購入する前に、It-Passportsは無料でサンプルを提供することができます。
質問 # 180
You manage an Azure Machine Learning workspace. You have a folder that contains a CSV file. The folder is registered as a folder data asset.
You plan to use the folder data asset for data wrangling during interactive development.
You need to access and load the folder data asset into a Pandas data frame.
Which method should you use to achieve this goal?
正解:C
解説:
Azure Machine Learning distinguishes between uri_folder, uri_file, and mltable data assets. Because the registered asset in this scenario is a folder data asset containing CSV data , the appropriate MLTable API is mltable.from_delimited_files(). Microsoft documents that a registered uri_folder containing CSV files can be retrieved through MLClient, its storage path supplied as a folder path, and then passed to mltable.
from_delimited_files(). The resulting MLTable object can subsequently be materialized into a Pandas DataFrame by calling to_pandas_dataframe().
A representative workflow is conceptually:
tbl = mltable.from_delimited_files(paths=[{ " folder " : data_asset.path}]) followed by:
df = tbl.to_pandas_dataframe()
mltable.load() is primarily appropriate when loading an existing MLTable definition , such as a registered table data asset containing an MLTable file. from_parquet_files() is intended for Parquet-formatted data, while from_delta_lake() targets Delta Lake data sources. Neither matches the CSV-based folder described here. Microsoft also identifies uri_folder as the appropriate asset type for folders containing CSV or Parquet files used with Pandas or Spark.
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning data assets, MLTable APIs, interactive data access, and Pandas-based data wrangling.
Continue with Azure ML data access
質問 # 181
Drag and Drop Question
You have an existing GitHub repository containing Azure Machine Learning project files.
You need to clone the repository to your Azure Machine Learning shared workspace file system.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.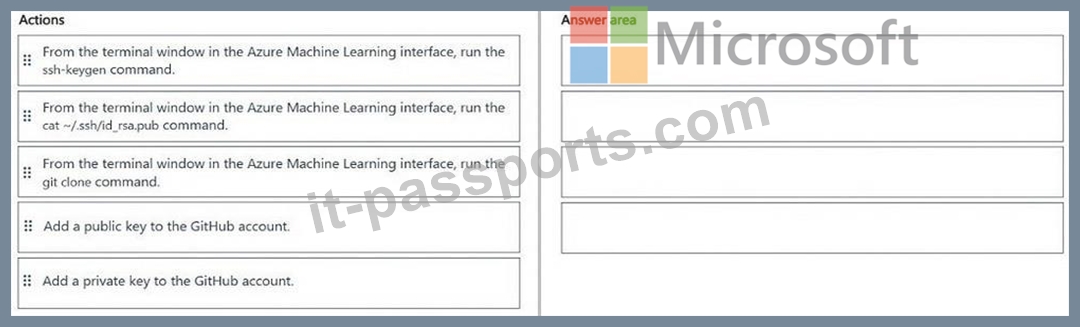
正解:
解説: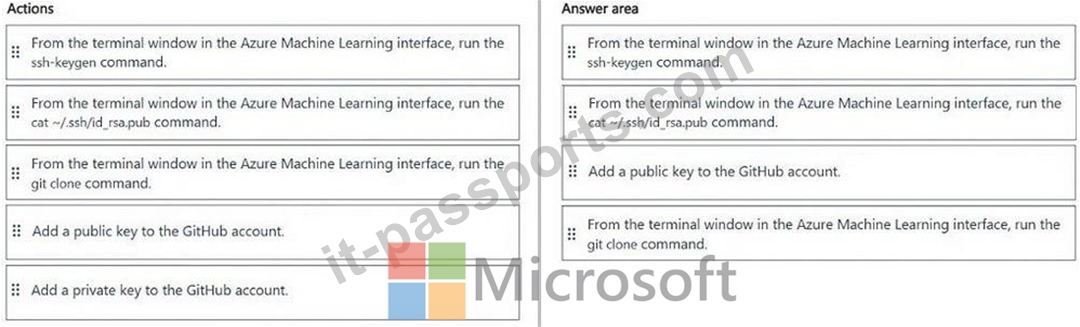
質問 # 182
A machine learning model is deployed to production in Azure Machine Learning and is actively serving predictions for a business application. The model was trained by using a historical dataset that represented expected input patterns at the time of deployment.
The team working on the model must ensure the following:
Changes in input data distribution are detected.
Appropriate actions are triggered when predefined thresholds are exceeded.
You need to configure monitoring to meet the requirements.
Which configuration should you use for each requirement? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.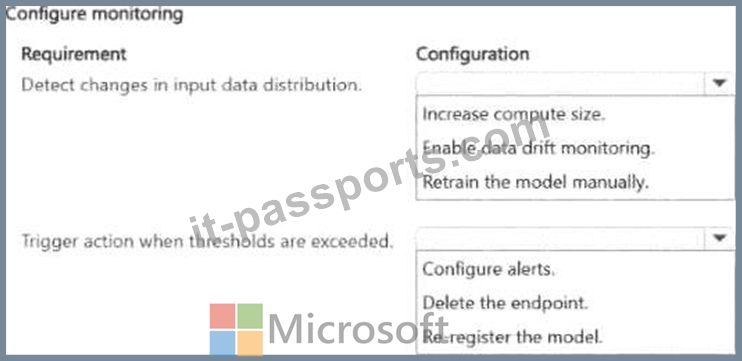
正解:
解説: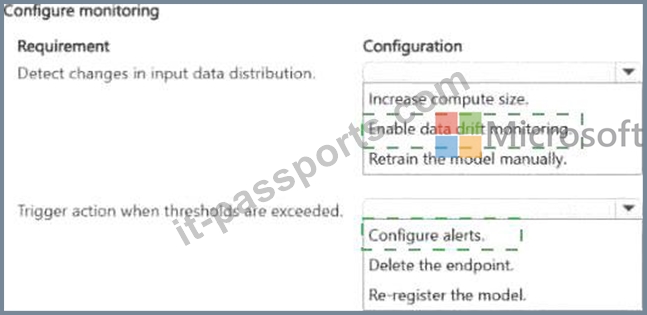
Explanation:
Azure Machine Learning ' s data drift monitor solves the first requirement: it continuously compares the statistical distribution of live inference input features against the baseline training data distribution, flagging when significant drift occurs. For the second requirement of triggering appropriate actions when thresholds are exceeded, Azure Monitor alert rules are configured on the drift metrics. When the drift coefficient exceeds a defined threshold, Azure Monitor fires an alert that can invoke Logic Apps, send emails, trigger an Azure ML retraining pipeline, or post to Teams. This two-layer approach - ML-specific drift detection backed by Azure Monitor alerting - is the Microsoft-recommended pattern for production model monitoring. The data drift monitor handles detection, while Azure Monitor handles the operational response, keeping the two concerns cleanly separated.
Microsoft Learn Reference Topic: Monitor model data drift - Azure Machine Learning model monitoring and Azure Monitor integration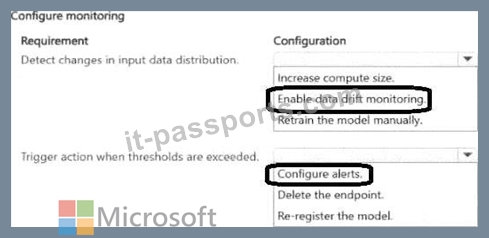
質問 # 183
A team deploys a classification model to production and monitors performance and data changes.
The team wants to ensure that significant drops in prediction accuracy automatically trigger the following:
Stakeholders must be notified of the drops.
Retraining must be initiated when thresholds are exceeded
You need to configure monitoring to meet the requirements.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.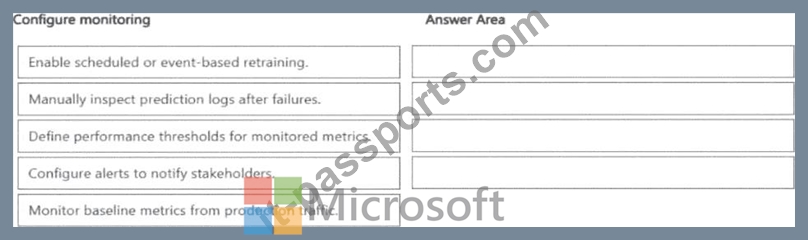
正解:
解説: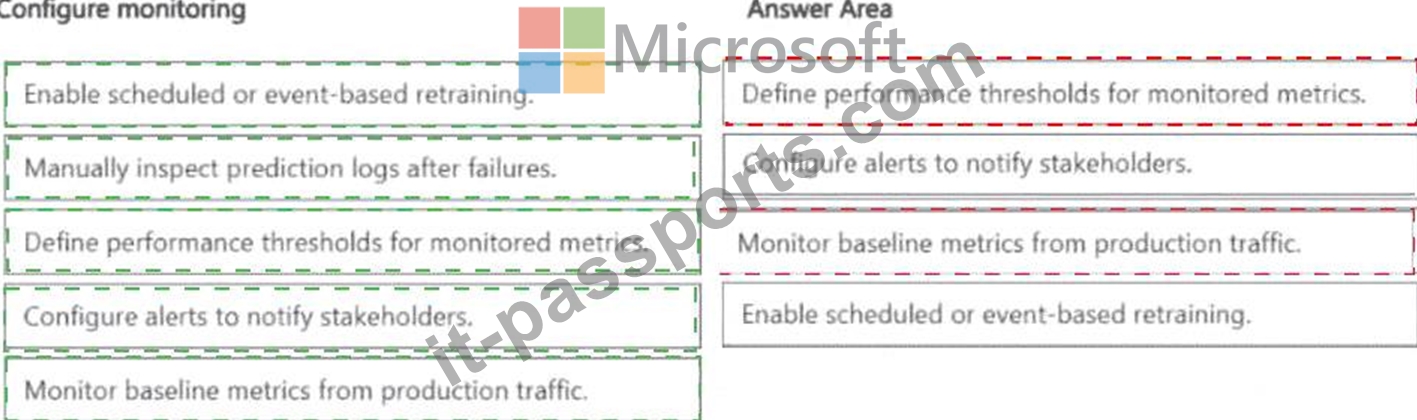
Explanation:
Microsoft ' s guidance on production model monitoring prescribes a four-stage sequence. First, configure an Azure ML model monitor on the deployed endpoint, specifying which metrics to track and on what schedule.
Second, define the threshold value below which model performance is considered unacceptable - this becomes the trigger condition. Third, create an Azure Monitor alert rule that evaluates the monitored metric against the threshold and fires when it is breached; the alert rule is associated with an action group that sends notifications to stakeholders via email, SMS, or Teams webhook. Fourth, the action group includes a webhook action pointing to an Azure Machine Learning pipeline ' s published REST endpoint, which starts the retraining job automatically. This sequence cleanly separates detection, notification, and remediation, matching Microsoft ' s recommended MLOps automation pattern.
Microsoft Learn Reference Topic: Automate model retraining based on monitoring alerts - Azure Machine Learning MLOps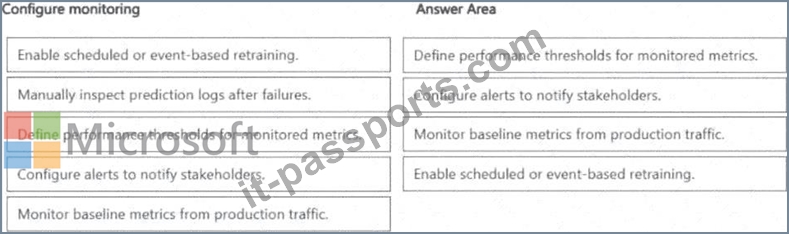
質問 # 184
You need to run large-scale inference jobs on millions of records periodically. Jobs are not latency-sensitive but must be cost-efficient and scalable. Which deployment option is MOST appropriate?
正解:D
解説:
Batch endpoints are optimized for large-scale, asynchronous inference workloads. They efficiently process large datasets and scale based on demand, making them cost-effective for non-real-time scenarios. Online endpoints are designed for low-latency use cases and are more expensive for batch processing.
質問 # 185
......
It-Passports弊社が提供する製品は、専門家によって精巧にコンパイルされており、Microsoftお客様に便利な方法でAI-300学習教材の学習を支援することを目的としたさまざまなバージョンを強化しています。 AI-300彼らは毎日アップデートをチェックしており、Operationalizing Machine Learning and Generative AI Solutions購入日から無料のアップデートサービスが受けられることを保証できます。AI-300 販売前または販売後にカスタマーサービスを提供するMicrosoft試験問題について質問や疑問がある場合は、試験資料について質問や疑問がある場合は連絡してください。Operationalizing Machine Learning and Generative AI Solutions専門の担当者が解決に役立ちます。 AI-300学習資料の使用に関する問題。
AI-300英語版: https://www.it-passports.com/AI-300.html