BONUS!!! Download part of Easy4Engine ACD-301 dumps for free: https://drive.google.com/open?id=1sRKbcolgLkc1HIj6HwWykoXtOUDmY2QP
Easy4Engine offers a free demo of the ACD-301 exam dumps for customers to try out before purchasing. This allows individuals to examine the ACD-301 exam prep material and make decisions. Customers will receive free updates to the ACD-301 exam questions for three months if any changes are made to the Appian Certified Lead Developer (ACD-301) exam content after the purchase of the ACD-301 Practice Questions. Easy4Engine has helped thousands of individuals worldwide in obtaining their ACD-301 certification through their real ACD-301 pdf dumps and practice tests. Passing the Appian Certified Lead Developer (ACD-301) exam on the first attempt can save individuals both time and money.
| Section | Objectives |
|---|---|
| Topic 1: Application Design and Architecture | - Reusable components and design patterns - Solution structuring and application layering |
| Topic 2: Data Management | - Data types and CDT structures - Record types and data stores |
| Topic 3: Security and Deployment | - Deployment pipelines and environment management - Security roles and group management |
| Topic 4: Process Modeling | - Exception handling and optimization - Advanced process model design |
| Topic 5: Expression Language and Logic | - Rule design and optimization - Advanced Appian expression functions |
| Topic 6: User Interface Design | - User experience best practices - Interface design and dynamic layouts |
>> New ACD-301 Test Practice <<
The web-based ACD-301 practice test is accessible via any browser. This ACD-301 mock exam simulates the actual Appian Certified Lead Developer (ACD-301) exam and does not require any software or plugins. Compatible with iOS, Mac, Android, and Windows operating systems, it provides all the features of the desktop-based ACD-301 Practice Exam software.
NEW QUESTION # 31
You are deciding the appropriate process model data management strategy.
For each requirement. match the appropriate strategies to implement. Each strategy will be used once.
Note: To change your responses, you may deselect your response by clicking the blank space at the top of the selection list.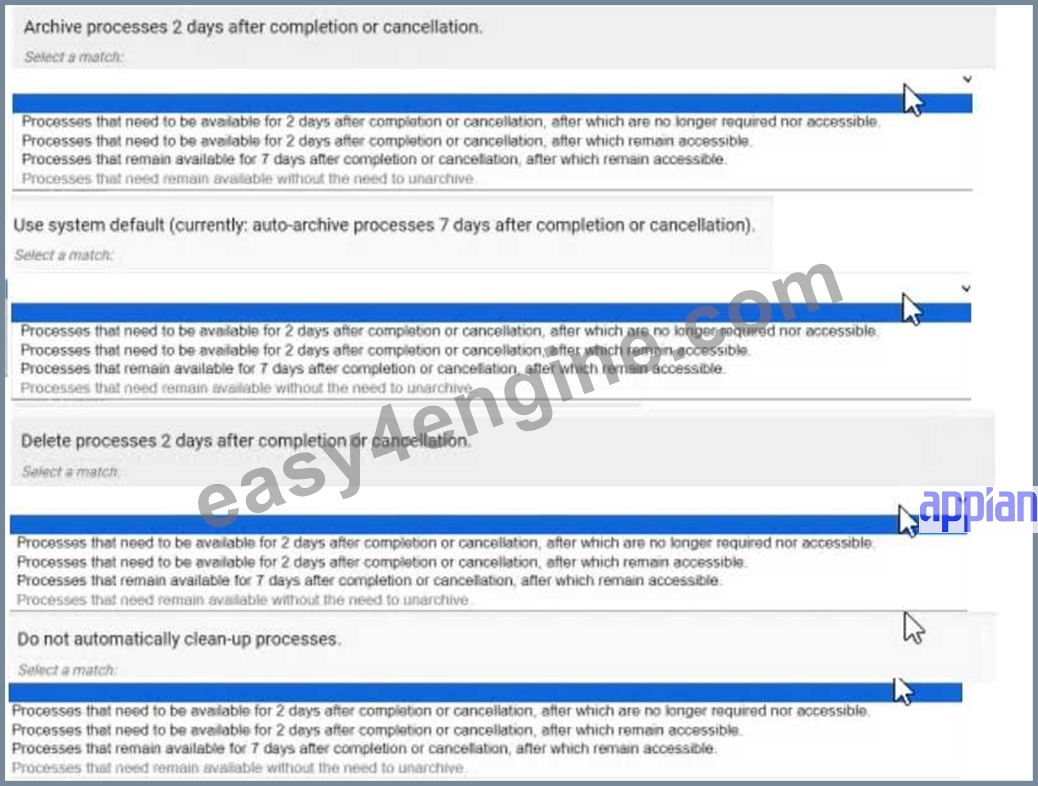
Answer:
Explanation: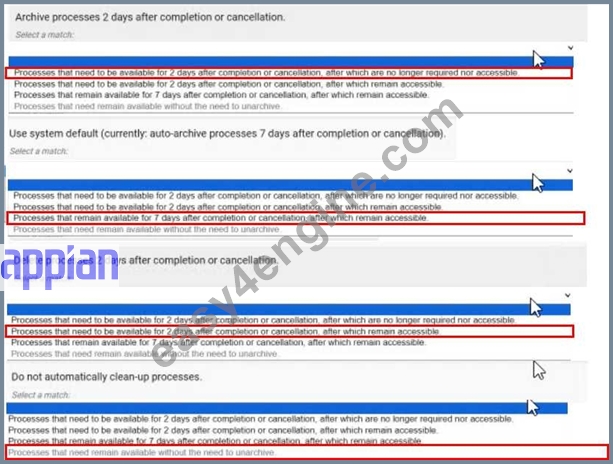
NEW QUESTION # 32
You are tasked to build a large-scale acquisition application for a prominent customer. The acquisition process tracks the time it takes to fulfill a purchase request with an award.
The customer has structured the contract so that there are multiple application development teams.
How should you design for multiple processes and forms, while minimizing repeated code?
Answer: A
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, designing a large-scale acquisition application with multiple development teams requires a strategy to manage processes, forms, and code reuse effectively. The goal is to minimize repeated code (e.g., duplicate interfaces, process models) while ensuring scalability and maintainability across teams. Let's evaluate each option:
A . Create a Center of Excellence (CoE):
A Center of Excellence is an organizational structure or team focused on standardizing practices, training, and governance across projects. While beneficial for long-term consistency, it doesn't directly address the technical design of minimizing repeated code for processes and forms. It's a strategic initiative, not a design solution, and doesn't solve the immediate need for code reuse. Appian's documentation mentions CoEs for governance but not as a primary design approach, making this less relevant here.
B . Create a common objects application:
This is the best recommendation. In Appian, a "common objects application" (or shared application) is used to store reusable components like expression rules, interfaces, process models, constants, and data types (e.g., CDTs). For a large-scale acquisition application with multiple teams, centralizing shared objects (e.g., rule!CommonForm, pm!CommonProcess) ensures consistency, reduces duplication, and simplifies maintenance. Teams can reference these objects in their applications, adhering to Appian's design best practices for scalability. This approach minimizes repeated code while allowing team-specific customizations, aligning with Lead Developer standards for large projects.
C . Create a Scrum of Scrums sprint meeting for the team leads:
A Scrum of Scrums meeting is a coordination mechanism for Agile teams, focusing on aligning sprint goals and resolving cross-team dependencies. While useful for collaboration, it doesn't address the technical design of minimizing repeated code-it's a process, not a solution for code reuse. Appian's Agile methodologies support such meetings, but they don't directly reduce duplication in processes and forms, making this less applicable.
D . Create duplicate processes and forms as needed:
Duplicating processes and forms (e.g., copying interface!PurchaseForm for each team) leads to redundancy, increased maintenance effort, and potential inconsistencies (e.g., divergent logic). This contradicts the goal of minimizing repeated code and violates Appian's design principles for reusability and efficiency. Appian's documentation strongly discourages duplication, favoring shared objects instead, making this the least effective option.
Conclusion: Creating a common objects application (B) is the recommended design. It centralizes reusable processes, forms, and other components, minimizing code duplication across teams while ensuring consistency and scalability for the large-scale acquisition application. This leverages Appian's application architecture for shared resources, aligning with Lead Developer best practices for multi-team projects.
Appian Documentation: "Designing Large-Scale Applications" (Common Application for Reusable Objects).
Appian Lead Developer Certification: Application Design Module (Minimizing Code Duplication).
Appian Best Practices: "Managing Multi-Team Development" (Shared Objects Strategy).
To build a large scale acquisition application for a prominent customer, you should design for multiple processes and forms, while minimizing repeated code. One way to do this is to create a common objects application, which is a shared application that contains reusable components, such as rules, constants, interfaces, integrations, or data types, that can be used by multiple applications. This way, you can avoid duplication and inconsistency of code, and make it easier to maintain and update your applications. You can also use the common objects application to define common standards and best practices for your application development teams, such as naming conventions, coding styles, or documentation guidelines. Verified [Appian Best Practices], [Appian Design Guidance]
NEW QUESTION # 33
You are on a call with a new client, and their program lead is concerned about how their legacy systems will integrate with Appian. The lead wants to know what authentication methods are supported by Appian. Which three authentication methods are supported?
Answer: A,D,F
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, addressing a client's concerns about integrating legacy systems with Appian requires accurately identifying supported authentication methods for system-to-system communication or user access. The question focuses on Appian's integration capabilities, likely for both user authentication (e.g., SSO) and API authentication, as legacy system integration often involves both. Appian's documentation outlines supported methods in its Connected Systems and security configurations. Let's evaluate each option:
A . API Keys:
API Key authentication involves a static key sent in requests (e.g., via headers). Appian supports this for outbound integrations in Connected Systems (e.g., HTTP Authentication with an API key), allowing legacy systems to authenticate Appian calls. However, it's not a user authentication method for Appian's platform login-it's for system-to-system integration. While supported, it's less common for legacy system SSO or enterprise use cases compared to other options, making it a lower-priority choice here.
B . Biometrics:
Biometrics (e.g., fingerprint, facial recognition) isn't natively supported by Appian for platform authentication or integration. Appian relies on standard enterprise methods (e.g., username/password, SSO), and biometric authentication would require external identity providers or custom clients, not Appian itself. Documentation confirms no direct biometric support, ruling this out as an Appian-supported method.
C . SAML:
Security Assertion Markup Language (SAML) is fully supported by Appian for user authentication via Single Sign-On (SSO). Appian integrates with SAML 2.0 identity providers (e.g., Okta, PingFederate), allowing users to log in using credentials from legacy systems that support SAML-based SSO. This is a key enterprise method, widely used for integrating with existing identity management systems, and explicitly listed in Appian's security configuration options-making it a top choice.
D . CAC:
Common Access Card (CAC) authentication, often used in government contexts with smart cards, isn't natively supported by Appian as a standalone method. While Appian can integrate with CAC via SAML or PKI (Public Key Infrastructure) through an identity provider, it's not a direct Appian authentication option. Documentation mentions smart card support indirectly via SSO configurations, but CAC itself isn't explicitly listed, making it less definitive than other methods.
E . OAuth:
OAuth (specifically OAuth 2.0) is supported by Appian for both outbound integrations (e.g., Authorization Code Grant, Client Credentials) and inbound API authentication (e.g., securing Appian Web APIs). For legacy system integration, Appian can use OAuth to authenticate with APIs (e.g., Google, Salesforce) or allow legacy systems to call Appian services securely. Appian's Connected System framework includes OAuth configuration, making it a versatile, standards-based method highly relevant to the client's needs.
F . Active Directory:
Active Directory (AD) integration via LDAP (Lightweight Directory Access Protocol) is supported for user authentication in Appian. It allows synchronization of users and groups from AD, enabling SSO or direct login with AD credentials. For legacy systems using AD as an identity store, this is a seamless integration method. Appian's documentation confirms LDAP/AD as a core authentication option, widely adopted in enterprise environments-making it a strong fit.
Conclusion: The three supported authentication methods are C (SAML), E (OAuth), and F (Active Directory). These align with Appian's enterprise-grade capabilities for legacy system integration: SAML for SSO, OAuth for API security, and AD for user management. API Keys (A) are supported but less prominent for user authentication, CAC (D) is indirect, and Biometrics (B) isn't supported natively. This selection reassures the client of Appian's flexibility with common legacy authentication standards.
Appian Documentation: "Authentication for Connected Systems" (OAuth, API Keys).
Appian Documentation: "Configuring Authentication" (SAML, LDAP/Active Directory).
Appian Lead Developer Certification: Integration Module (Authentication Methods).
NEW QUESTION # 34
What are two advantages of having High Availability (HA) for Appian Cloud applications?
Answer: A,D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
High Availability (HA) in Appian Cloud is designed to ensure that applications remain operational and data integrity is maintained even in the face of hardware failures, network issues, or other disruptions. Appian's Cloud Architecture and HA documentation outline the benefits, focusing on redundancy, minimal downtime, and data protection. The question asks for two advantages, and the options must align with these core principles.
Option B (Data and transactions are continuously replicated across the active nodes to achieve redundancy and avoid single points of failure):
This is a key advantage of HA. Appian Cloud HA instances use multiple active nodes to replicate data and transactions in real-time across the cluster. This redundancy ensures that if one node fails, others can take over without data loss, eliminating single points of failure. This is a fundamental feature of Appian's HA setup, leveraging distributed architecture to enhance reliability, as detailed in the Appian Cloud High Availability Guide.
Option D (In the event of a system failure, your Appian instance will be restored and available to your users in less than 15 minutes, having lost no more than the last 1 minute worth of data):
This is another significant advantage. Appian Cloud HA is engineered to provide rapid recovery and minimal data loss. The Service Level Agreement (SLA) and HA documentation specify that in the case of a failure, the system failover is designed to complete within a short timeframe (typically under 15 minutes), with data loss limited to the last minute due to synchronous replication. This ensures business continuity and meets stringent uptime and data integrity requirements.
Option A (An Appian Cloud HA instance is composed of multiple active nodes running in different availability zones in different regions):
This is a description of the HA architecture rather than an advantage. While running nodes across different availability zones and regions enhances fault tolerance, the benefit is the resulting redundancy and availability, which are captured in Options B and D. This option is more about implementation than a direct user or operational advantage.
Option C (A typical Appian Cloud HA instance is composed of two active nodes):
This is a factual statement about the architecture but not an advantage. The number of nodes (typically two or more, depending on configuration) is a design detail, not a benefit. The advantage lies in what this setup enables (e.g., redundancy and quick recovery), as covered by B and D.
The two advantages-continuous replication for redundancy (B) and fast recovery with minimal data loss (D)-reflect the primary value propositions of Appian Cloud HA, ensuring both operational resilience and data integrity for users.
The two advantages of having High Availability (HA) for Appian Cloud applications are:
B . Data and transactions are continuously replicated across the active nodes to achieve redundancy and avoid single points of failure. This is an advantage of having HA, as it ensures that there is always a backup copy of data and transactions in case one of the nodes fails or becomes unavailable. This also improves data integrity and consistency across the nodes, as any changes made to one node are automatically propagated to the other node.
D). In the event of a system failure, your Appian instance will be restored and available to your users in less than 15 minutes, having lost no more than the last 1 minute worth of data. This is an advantage of having HA, as it guarantees a high level of service availability and reliability for your Appian instance. If one of the nodes fails or becomes unavailable, the other node will take over and continue to serve requests without any noticeable downtime or data loss for your users.
NEW QUESTION # 35
As part of an upcoming release of an application, a new nullable field is added to a table that contains customer dat a. The new field is used by a report in the upcoming release and is calculated using data from another table.
Which two actions should you consider when creating the script to add the new field?
Answer: C,D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, adding a new nullable field to a database table for an upcoming release requires careful planning to ensure data integrity, report functionality, and rollback capability. The field is used in a report and calculated from another table, so the script must handle both deployment and potential reversibility. Let's evaluate each option:
A . Create a script that adds the field and leaves it null:
Adding a nullable field and leaving it null is technically feasible (e.g., using ALTER TABLE ADD COLUMN in SQL), but it doesn't address the report's need for calculated data. Since the field is used in a report and calculated from another table, leaving it null risks incomplete or incorrect reporting until populated, delaying functionality. Appian's data management best practices recommend populating data during deployment for immediate usability, making this insufficient as a standalone action.
B . Create a rollback script that removes the field:
This is a critical action. In Appian, database changes (e.g., adding a field) must be reversible in case of deployment failure or rollback needs (e.g., during testing or PROD issues). A rollback script that removes the field (e.g., ALTER TABLE DROP COLUMN) ensures the database can return to its original state, minimizing risk. Appian's deployment guidelines emphasize rollback scripts for schema changes, making this essential for safe releases.
C . Create a script that adds the field and then populates it:
This is also essential. Since the field is nullable, calculated from another table, and used in a report, populating it during deployment ensures immediate functionality. The script can use SQL (e.g., UPDATE table SET new_field = (SELECT calculated_value FROM other_table WHERE condition)) to populate data, aligning with Appian's data fabric principles for maintaining data consistency. Appian's documentation recommends populating new fields during deployment for reporting accuracy, making this a key action.
D . Create a rollback script that clears the data from the field:
Clearing data (e.g., UPDATE table SET new_field = NULL) is less effective than removing the field entirely. If the deployment fails, the field's existence with null values could confuse reports or processes, requiring additional cleanup. Appian's rollback strategies favor reverting schema changes completely (removing the field) rather than leaving it with nulls, making this less reliable and unnecessary compared to B.
E . Add a view that joins the customer data to the data used in calculation:
Creating a view (e.g., CREATE VIEW customer_report AS SELECT ... FROM customer_table JOIN other_table ON ...) is useful for reporting but isn't a prerequisite for adding the field. The scenario focuses on the field addition and population, not reporting structure. While a view could optimize queries, it's a secondary step, not a primary action for the script itself. Appian's data modeling best practices suggest views as post-deployment optimizations, not script requirements.
Conclusion: The two actions to consider are B (create a rollback script that removes the field) and C (create a script that adds the field and then populates it). These ensure the field is added with data for immediate report usability and provide a safe rollback option, aligning with Appian's deployment and data management standards for schema changes.
Appian Documentation: "Database Schema Changes" (Adding Fields and Rollback Scripts).
Appian Lead Developer Certification: Data Management Module (Schema Deployment Strategies).
Appian Best Practices: "Managing Data Changes in Production" (Populating and Rolling Back Fields).
NEW QUESTION # 36
......
This format of Easy4Engine Appian ACD-301 practice material is compatible with these smart devices: Laptops, Tablets, and Smartphones. This compatibility makes ACD-301 PDF Dumps easily usable from any place. It contains real and latest ACD-301 exam questions with correct answers. Easy4Engine examines it regularly for new updates so that you always get new Appian Certified Lead Developer (ACD-301) practice questions. Since it is a printable format, you can do a paper study. The Appian Certified Lead Developer (ACD-301) PDF Dumps document is accessible from every location at any time.
Pass ACD-301 Guarantee: https://www.easy4engine.com/ACD-301-test-engine.html
2026 Latest Easy4Engine ACD-301 PDF Dumps and ACD-301 Exam Engine Free Share: https://drive.google.com/open?id=1sRKbcolgLkc1HIj6HwWykoXtOUDmY2QP