Excellent 100% Free NCP-AIO–100% Free Associate Level Exam | New NCP-AIO Test Notes

DOWNLOAD the newest PDFVCE NCP-AIO PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1Q5irEyEAsK5G9G62cF6BEKuFg_k8Z4U1
One of the most important functions of our NCP-AIO preparation questions are that can support almost all electronic equipment, including the computer, mobile phone and so on. If you want to prepare for your exam by the computer, you can buy the Software and APP online versions of our NCP-AIO training quiz, because these two versions can work well by the computer. Moreover, the APP online version of our NCP-AIO learning materials can also apply the IPAD, phone, laptop and so on.
NVIDIA NCP-AIO Exam Overview:
| Certification Vendor: | NVIDIA |
|---|
| Exam Name: | NVIDIA-Certified Professional: AI Operations Exam |
|---|
| Exam Number: | NCP-AIO |
|---|
| Passing Score: | Pass/Fail (not officially disclosed) |
|---|
| Exam Duration: | 120 minutes |
|---|
| Available Languages: | English |
|---|
| Exam Format: | Scenario-based, Multiple choice, Hands-on lab exercises |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Exam Price: | $500 USD |
|---|
| Related Certifications: | NVIDIA-Certified Associate: AI Infrastructure and Operations (NCA-AIIO)
NVIDIA-Certified Professional: AI Networking (NCP-AIN)
NVIDIA-Certified Professional: AI Infrastructure (NCP-AII) |
|---|
| Real Exam Qty: | 30–75 |
|---|
| Recommended Training: | NVIDIA AI Operations Training |
|---|
| Exam Registration: | Certiverse Exam Platform
NVIDIA Certification Portal |
|---|
| Sample Questions: | NVIDIA NCP-AIO Sample Questions |
|---|
| Exam Way: | Online remote proctored exam |
|---|
| Pre Condition: | Recommended: 2–3 years of experience managing AI infrastructure, GPU systems, or data center operations; familiarity with Kubernetes, containers, and NVIDIA software stack |
|---|
| Official Syllabus URL: | https://www.nvidia.com/en-us/learn/certification/ai-operations-professional/ |
|---|
>> NCP-AIO Associate Level Exam <<
New NCP-AIO Test Notes & NCP-AIO PDF Questions
You can try the NVIDIA AI Operations (NCP-AIO) exam dumps demo before purchasing. If you like our NVIDIA AI Operations (NCP-AIO) exam questions features, you can get the full version after payment. PDFVCE NVIDIA NCP-AIO Dumps give surety to confidently pass the NVIDIA AI Operations (NCP-AIO) exam on the first attempt.
| Topic | Details |
|---|
| Topic 1 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
| Topic 2 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
| Topic 3 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
| Topic 4 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
NVIDIA AI Operations Sample Questions (Q76-Q81):
NEW QUESTION # 76
An instance of NVIDIA Fabric Manager service is running on an HGX system with KVM. A System Administrator is troubleshooting NVLink partitioning.
By default, what is the GPU polling subsystem set to?
- A. Every 1 second
- B. Every 60 seconds
- C. Every 30 seconds
- D. Every 10 seconds
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In NVIDIA AI infrastructure, theNVIDIA Fabric Managerservice is responsible for managing GPU fabric features such as NVLink partitioning on HGX systems. This service periodically polls the GPUs to monitor and manage NVLink states. By default, the GPU polling subsystem is set toevery 30 secondsto balance timely updates with system resource usage.
This polling interval allows the Fabric Manager to efficiently detect and respond to changes or issues in the NVLink fabric without excessive overhead or latency. It is a standard default setting unless specifically configured otherwise by system administrators.
This default behavior aligns with NVIDIA's system management guidelines for HGX platforms and is referenced in NVIDIA AI Operations materials concerning fabric management and troubleshooting of NVLink partitions.
NEW QUESTION # 77
You are troubleshooting an issue where BCM is failing to connect to the database after a recent network change. Which of the following steps is the MOST appropriate first step to diagnose the problem?
- A. Restart the BCM service.
- B. Update the NVIDIA drivers on all GPU nodes.
- C. Examine the BCM logs for database connection errors.
- D. Reinstall BCM.
- E. Check the database connection string in 'bcm_config.yaml' to ensure it reflects the new network configuration.
Answer: C
Explanation:
Examining the BCM logs for database connection errors is the most appropriate first step. The logs will provide specific details about the connection failure, such as the error code, hostname, or authentication issue, which will help pinpoint the root cause. Checking the 'bcm_config.yaml' and verifying the connection string is the next logical step if the logs indicate an incorrect configuration.
NEW QUESTION # 78
Which practice ensures that changes to machine learning models, datasets, and configuration files are tracked, reproducible, and auditable across development, testing, and production environments in an AI operations lifecycle?
- A. Containerization
- B. Data labeling
- C. Load balancing
- D. Version control
Answer: D
Explanation:
Version control systems manage changes in code, datasets, and model artifacts. They provide traceability, reproducibility, and rollback capabilities. This is essential for maintaining consistency and compliance in AI operations across multiple environments and teams.
NEW QUESTION # 79
Given the following Slurm configuration snippet in slurm.conf:
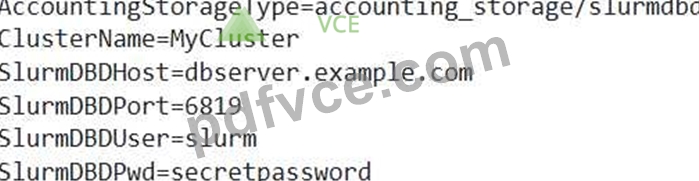
What steps are necessary to ensure that the Slurm cluster is properly connected to the SlurmDBD and that accounting data is being collected correctly?
- A. Restart the Slurmctld and Slurmd daemons after making the changes to slurm.conf.
- B. All of the above
- C. Ensure that the SlurmDBD service is running on dbserver.example.com and accessible on port 6819.
- D. Test the connection to the database using 'sacctmgr' to create/modify account or user data.
- E. Verify that the 'slurm' user has the necessary privileges on the SlurmDBD database.
Answer: B
NEW QUESTION # 80
You are designing a data center that must support both interactive AI development and large-scale batch training jobs. You want to maximize GPU utilization while ensuring that interactive users have a responsive experience. Which of the following strategies is MOST effective?
- A. Oversubscribe all GPUs to maximize utilization, even if it degrades interactive performance.
- B. Use NVIDIA MPS (Multi-Process Service) to allow interactive users and batch jobs to share GPUs concurrently, and implement QOS to prioritize interactive workloads.
- C. Run all workloads on a single large GPU server to simplify management.
- D. Schedule batch jobs to run only during off-peak hours when interactive users are not active.
- E. Allocate dedicated GPUs to interactive users and run batch jobs on idle CPUs.
Answer: B
Explanation:
NVIDIA MPS allows multiple processes to share a GPU concurrently, which maximizes utilization. QOS ensures that interactive workloads receive priority, maintaining a responsive experience. Dedicated GPUs for interactive users wastes resources when they are idle. Scheduling batch jobs for off-peak hours is limiting and inefficient. Oversubscribing without QOS can severely impact interactive performance. Running all workloads on a single server creates a single point of failure and limits scalability.
NEW QUESTION # 81
......
New NCP-AIO Test Notes: https://www.pdfvce.com/NVIDIA/NCP-AIO-exam-pdf-dumps.html
- New NCP-AIO Learning Materials 💽 Certification NCP-AIO Exam Infor 🏵 NCP-AIO Valid Braindumps Ebook 🚺 Immediately open ➤ www.examcollectionpass.com ⮘ and search for “ NCP-AIO ” to obtain a free download 🍇Valid Exam NCP-AIO Braindumps
- Valid Exam NCP-AIO Braindumps 🧃 Reliable NCP-AIO Dumps Files 🔴 New NCP-AIO Learning Materials 🏋 Search for [ NCP-AIO ] and download it for free immediately on ➥ www.pdfvce.com 🡄 ☝Latest NCP-AIO Test Preparation
- Upgrade NCP-AIO Dumps 🥚 Latest NCP-AIO Dumps Ppt 🚢 NCP-AIO Excellect Pass Rate 👷 The page for free download of ➤ NCP-AIO ⮘ on ▶ www.practicevce.com ◀ will open immediately ☣Latest NCP-AIO Test Preparation
- NVIDIA NCP-AIO Exam Questions - Failure Will Result In A Refund 🤑 Open website ⏩ www.pdfvce.com ⏪ and search for “ NCP-AIO ” for free download 🙈NCP-AIO Reliable Braindumps Files
- Latest NCP-AIO Dumps Ppt 😘 NCP-AIO Reliable Braindumps Files 😆 NCP-AIO Pass Leader Dumps 🦲 Enter ⏩ www.exam4labs.com ⏪ and search for ⏩ NCP-AIO ⏪ to download for free 🦎Latest NCP-AIO Dumps Ppt
- Pass Guaranteed Fantastic NVIDIA - NCP-AIO Associate Level Exam 🧮 Easily obtain ▛ NCP-AIO ▟ for free download through “ www.pdfvce.com ” 🤮Latest NCP-AIO Test Preparation
- How NVIDIA is so Confident in its NVIDIA NCP-AIO Exam Questions? 🐚 Simply search for ⏩ NCP-AIO ⏪ for free download on ➡ www.vceengine.com ️⬅️ 🍌NCP-AIO Valid Braindumps Ebook
- New NCP-AIO Real Test 🤣 NCP-AIO Reliable Braindumps Files 🧀 Accurate NCP-AIO Test 🕞 Easily obtain ✔ NCP-AIO ️✔️ for free download through 《 www.pdfvce.com 》 ⏳New NCP-AIO Real Test
- NCP-AIO Reliable Braindumps Files 😉 Valid Dumps NCP-AIO Book 🕝 NCP-AIO Valid Exam Practice 🕓 The page for free download of ( NCP-AIO ) on ➥ www.dumpsquestion.com 🡄 will open immediately 🚎Latest NCP-AIO Dumps Ppt
- NCP-AIO Valid Exam Practice 🕯 NCP-AIO Reliable Braindumps Files 🩲 Latest NCP-AIO Test Preparation 🐼 Search for 「 NCP-AIO 」 on 《 www.pdfvce.com 》 immediately to obtain a free download 🏐Latest NCP-AIO Test Preparation
- NCP-AIO Reliable Braindumps Files 🚚 Certification NCP-AIO Exam Infor 👭 Exam NCP-AIO Pass4sure 🏉 The page for free download of ▷ NCP-AIO ◁ on ➤ www.troytecdumps.com ⮘ will open immediately 🐠Exam NCP-AIO Pass4sure
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BTW, DOWNLOAD part of PDFVCE NCP-AIO dumps from Cloud Storage: https://drive.google.com/open?id=1Q5irEyEAsK5G9G62cF6BEKuFg_k8Z4U1