P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by PrepAwayTest: https://drive.google.com/open?id=1pn_oQ4w2TkyB7Dw8yv551HXH58q6Eg87
Our Snowflake learning materials contain latest test questions, valid answers and professional explanations, which ensure you hold SPS-C01 actual test with great confidence. And we will provide you with the most comprehensive service when you prepare SPS-C01 Practice Exam with our valid dumps collection.
| Section | Weight | Objectives |
|---|---|---|
| Snowpark API for Python | 30% | - Reading and writing data - DataFrame creation and manipulation - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data - Establishing connections and session management |
| Snowpark Concepts | 15% | - Snowpark DataFrames and query plans - Client-side vs. Server-side execution - Transformations vs. Actions - Snowpark Sessions and connection management - Stored procedures and conditional logic - Snowpark architecture and core concepts |
| Performance Optimization and Best Practices | 20% | - Warehouse sizing for Snowpark - Query pushdown and optimization - Caching strategies - Minimizing data transfer - Debugging and explain plans - Vectorized UDFs |
| Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Window functions - Persisting transformed data - Using built-in functions - Filtering, Aggregating, and Joining DataFrames |
In recent years, our SPS-C01 Test Torrent has been well received and have reached 99% pass rate with all our dedication. As a powerful tool for a lot of workers to walk forward a higher self-improvement, our SPS-C01 certification training continue to pursue our passion for advanced performance and human-centric technology. As a matter of fact, our company takes account of every client’s difficulties with fitting solutions. As long as you need help, we will offer instant support to deal with any of your problems about our Snowflake Certified SnowPro Specialty - Snowpark guide torrent. Any time is available; our responsible staff will be pleased to answer your questions.
NEW QUESTION # 101
You need to perform a set difference operation between two DataFrames in Snowpark Python. 'dfl' contains customer IDs from a marketing campaign, and 'df2 contains customer IDs from a recent purchase event. You want to identify customers who were targeted in the campaign but did not make a recent purchase. Both DataFrames have a column named 'customer id'. Which of the following approaches provides the most efficient way to accomplish this task in Snowpark?





Answer: E
Explanation:
Option C, using a 'left_anti' join, is the most efficient way to perform a set difference operation between two DataFrames in Snowpark. A join returns only the rows from the left DataFrame Cdfl s) where the join condition is not met in the right DataFrame Cdf2). This leverages Snowflake's query optimizer for optimal performance. Option A, 'subtract(df2)' , is equivalent to 'exceptAll(df2)' (Option B) and removes duplicate rows. While functionally correct, join is often more performant, especially for larger datasets. Option D is highly inefficient as it collects the 'customer_id' from 'df2 to the driver, it should be avoided. Option E calculates intersection, not difference.
NEW QUESTION # 102
You are tasked with optimizing a Snowpark Python application that performs complex data transformations using a large DataFrame. The application is running slower than expected. You suspect that data skew is causing uneven distribution of work across the Snowflake warehouse nodes. Which of the following techniques could be used to mitigate data skew and improve the performance of your Snowpark application? (Select TWO)
Answer: A,B
Explanation:
Options B and E are effective techniques for mitigating data skew. Option B, allows you to explicitly redistribute the data based on a specific column or set of columns, ensuring a more even distribution across the warehouse nodes. Option E, using the 'BROADCAST' hint, is useful when joining a smaller DataFrame with a large DataFrame, as it broadcasts the smaller DataFrame to all nodes, preventing skew during the join operation. Option A, increasing the warehouse size, might provide more resources but doesn't address the underlying data skew issue directly. Option C, sorting the data, doesn't necessarily address data skew and might even worsen it in some cases. Option D, Snowflake's automatic clustering, helps with data locality for queries but doesn't directly address data skew within the Snowpark application during transformations.
NEW QUESTION # 103
You have a Snowpark application that utilizes a vectorized Python UDF to perform complex calculations on a large dataset. You notice that the performance is still not optimal. You suspect that the bottleneck might be related to how the data is being partitioned and processed by Snowflake. Which of the following actions, when performed in conjunction with vectorization, would MOST likely improve performance?
Answer: B
Explanation:
Repartitioning the DataFrame using allows you to control how the data is distributed across compute nodes. This can improve performance by ensuring that related data is processed together, reducing data shuffling and improving data locality. Pre- sorting data (A) might help in some cases, but it doesn't guarantee optimal data distribution for parallel processing. Broadcasting the DataFrame (C) is suitable for smaller datasets, not large ones where it can lead to memory issues. Converting the DataFrame to a Pandas DataFrame (D) defeats the purpose of using Snowpark for distributed processing and introduces a single-node bottleneck. There's no direct control over the number of UDF worker threads in Snowflake.
NEW QUESTION # 104
Consider the following Snowpark code snippet that defines and registers a UDF: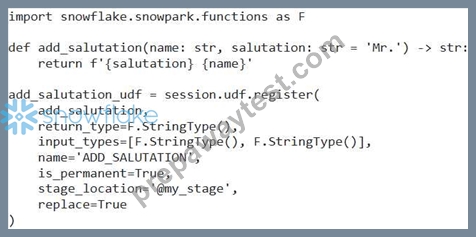
Which of the following statements about this code are TRUE?
Answer: B,C,E
Explanation:
The correct answers are C, D, and E. makes the UDF permanent. 'replace=True' overwrites any existing UDF with the same name. Python's default parameter value IS used in the SQL call if the salutation is omitted. 'input_typeS are not redundant, they are required and Python's type hints are not automatically used. Option A is incorrect because 'is_permanent' is set to true.
NEW QUESTION # 105
You have a Snowpark DataFrame containing product information, and you want to persist it into a Snowflake table named PRODUCTS. You need to handle the following scenarios: 1. If the table 'PRODUCTS does not exist, create it. 2. If the table PRODUCTS' exists, append the data from 'df_products' to it. Which of the following methods can achieve this?





Answer: A
Explanation:
Option B is the correct solution. The 'mode('append')' ensures that the data from 'df_products' is appended to the 'PRODUCTS' table if it exists. If the table does not exist, Snowflake will create it automatically. Option A will create the table if it doesn't exist, but will throw an error if it does. Option C will overwrite the table. Option D is unnecessarily complex and inefficient, first collecting the data to the driver then creating a new DataFrame. Option E doesn't exist in Snowpark API.
NEW QUESTION # 106
......
Our Snowflake Certified SnowPro Specialty - Snowpark exam questions are curated and crafted by experts. We have put in a lot of efforts to create amazing guides for our customers. Passing SPS-C01 can be hard, and you won’t find such exam SPS-C01 Brain Dumps anywhere. With SPS-C01 sample questions exam dumps, you can secure high marks in the SPS-C01. We provide 100% money back guarantee on exam SPS-C01 practice exam products.
SPS-C01 Lead2pass Review: https://www.prepawaytest.com/Snowflake/SPS-C01-practice-exam-dumps.html
DOWNLOAD the newest PrepAwayTest SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1pn_oQ4w2TkyB7Dw8yv551HXH58q6Eg87