P.S. Free & New AI-300 dumps are available on Google Drive shared by Braindumpsqa: https://drive.google.com/open?id=1C4gffnRf0gQIItwoq2fFON5u0y4GlQdr
Before you place orders, you can download the free demos of AI-300 practice test as experimental acquaintance. Once you decide to buy, you will have many benefits like free update lasting one-year and convenient payment mode. We will inform you immediately once there are latest versions of AI-300 Test Question released. And if you get any questions, please get contact with us, our staff will be online 24/7 to solve your problems all the way.
| Section | Objectives |
|---|---|
| Topic 1: Optimize generative AI systems and model performance | - Optimize inference performance, caching, and throughput - Implement cost management and scaling strategies for GenAI workloads - Tune prompts, system messages, and grounding strategies - Fine-tune and distill models for specific use cases |
| Topic 2: Implement generative AI quality assurance and observability | - Evaluate generative AI outputs for quality, safety, and grounding - Conduct red teaming, adversarial testing, and content filtering - Implement logging, tracing, and telemetry for GenAI applications - Monitor latency, token usage, cost, and error rates |
| Topic 3: Design and implement an MLOps infrastructure | - Implement security, governance, and compliance for MLOps - Manage environments, data stores, and model registries - Set up Azure Machine Learning workspace and compute targets - Configure source control, CI/CD pipelines, and automation for ML workflows |
| Topic 4: Implement machine learning model lifecycle and operations | - Deploy models to real-time and batch endpoints - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production - Monitor model performance, data drift, and operational health |
| Topic 5: Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Configure prompt orchestration, prompt flows, and agent frameworks - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search |
Our Braindumpsqa website try our best for the majority of examinees to provide the best and most convenient service. Under the joint efforts of everyone for many years, the passing rate of Braindumpsqa Microsoft's AI-300 Certification Exam has reached as high as100%. If you buy our AI-300 exam certification training materials, we will also provide one year free renewal service. Hurry up!
NEW QUESTION # 178
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You work in Microsoft Foundry with a prompt flow.
You must manually evaluate prompts and compare results across prompt variants.
You need to capture the inputs, outputs, token usage, and latencies for each flow run for the evaluation.
Solution: In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Incorrect:
* Create prompt variants and compare their outputs in the Evaluation experience.
* Use the prompt flow SDK to enable tracing for the flow before executing runs. Then run the flow to generate traceable results.
Note:
In Azure AI Foundry, you can capture and compare these metrics by enabling Tracing and using the Bulk Test feature. This allows you to systematically evaluate different prompt variants against a common dataset.
Steps to Evaluate and Compare Prompt Variants
*-> 1. Enable Tracing
Navigate to your Prompt Flow project.
Locate the Tracing toggle at the top of the flow authoring page.
Switch it to On.
This ensures every execution captures latency, token counts, and node-level inputs/outputs.
2. Create Prompt Variants
Within your flow, identify the LLM node you want to test.
Click Variants to create multiple versions of your prompt (e.g., Variant_0, Variant_1).
This allows you to test different instructions or few-shot examples side-by-side.
3. Run a Bulk Test (Evaluation)
4. Analyze the Results
Reference:
https://www.linkedin.com/pulse/streamlining-generative-ai-development-azure-foundry-tracing- taneja-mbwze
NEW QUESTION # 179
A team plans to deploy a large foundation model in Microsoft Foundry as part of a new enterprise AI capability.
Different business units across the team ' s organization will access the model from various internal applications.
You need to deploy a foundation model by minimizing latency.
Which deployment type should you use?
Answer: B
Explanation:
Data Zone Standard deployment routes requests to multiple datacenters within a defined geographic zone such as the US data zone, providing lower latency by using zone-level load balancing while maintaining data within a broad compliance boundary. This makes it suitable for enterprise internal applications where multiple business units need low-latency access without strict single-region data residency requirements. Developer deployment (option A) is a low-quota, unguaranteed tier designed for prototype testing, not production workloads serving multiple business units. Data Zone Batch (option B) is designed for high-volume asynchronous batch processing, not interactive low-latency real-time requests. Global Batch (option D) is optimized for scheduled bulk inference across all global regions but adds latency and is inappropriate for synchronous interactive use cases.
Microsoft Learn Reference Topic: Foundation model deployment types in Microsoft Foundry - Data Zone Standard for low-latency internal use
NEW QUESTION # 180
A Retrieval-Augmented Generation (RAG) solution returns incomplete answers because relevant content is inconsistently retrieved from the knowledge source.
You need to improve RAG accuracy without changing the embedding model currently in use. You need to achieve this goal while minimizing operational costs.
Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point. Choose two .
Answer: A,D
Explanation:
Microsoft ' s RAG optimization guidance identifies two high-impact, low-cost improvements for retrieval quality that do not require changing the embedding model. First, tuning chunk size and overlap (option A):
chunk size determines how much context each retrieved piece contains - too large and irrelevant content dilutes the signal; too small and answers may be split across chunks. Adjusting these parameters requires only re-indexing the documents with zero additional compute cost. Second, implementing a re-ranker (option B): a re-ranker is a cross-encoder model that takes the top-N retrieved chunks and re-scores them based on their specific relevance to the query, significantly improving precision by filtering out contextually irrelevant chunks. Re-rankers add modest compute cost but are far cheaper than changing the embedding model, which would require re-embedding the entire knowledge base. Increasing token limits (option C) and optimizing embedding vector length (option D) do not address retrieval accuracy without an embedding model change.
Microsoft Learn Reference Topic: Optimize RAG pipelines - Chunk size tuning and re-ranking in Azure AI Search and Azure Machine Learning
NEW QUESTION # 181
Your ML pipeline contains independent feature engineering steps that currently execute sequentially, increasing overall runtime. You want to optimize execution without modifying logic.
What is the BEST solution?
Answer: B
Explanation:
Parallel execution allows independent pipeline steps to run simultaneously, reducing total execution time without altering logic. This is more efficient than increasing compute resources, which may raise costs without guaranteeing proportional performance improvements.
NEW QUESTION # 182
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
Hotspot Question
You need to configure an optimization method to meet Fabrikam Inc.'s technical requirements.
Which strategy should you apply first? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.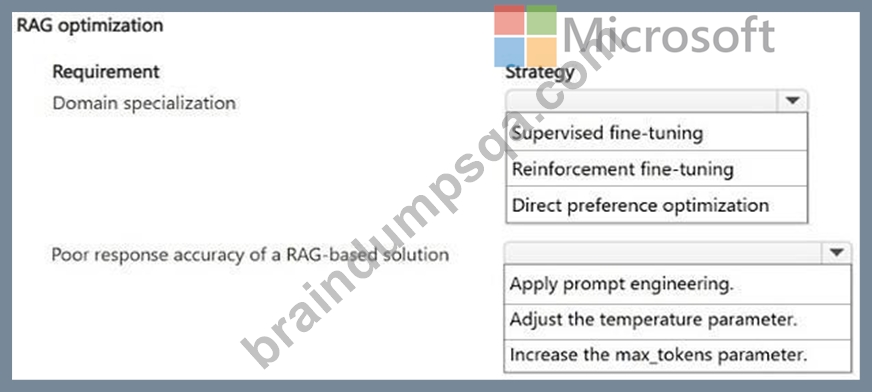
Answer:
Explanation: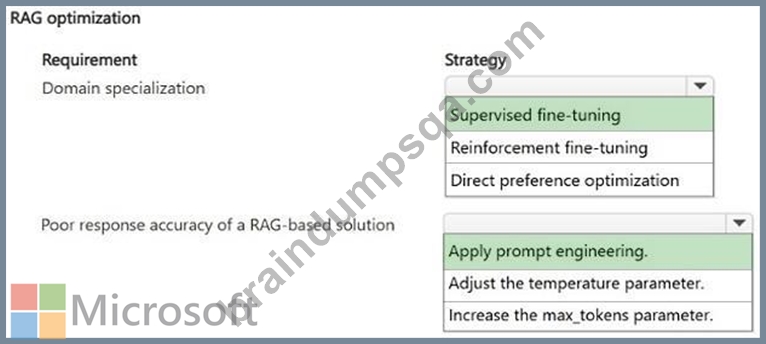
NEW QUESTION # 183
......
We will have a dedicated specialist to check if our AI-300 learning materials are updated daily. We can guarantee that our AI-300 exam question will keep up with the changes by updating the system, and we will do our best to help our customers obtain the latest information on learning materials to meet their needs. If you choose to purchase our AI-300 quiz torrent, you will have the right to get the update system and the update system is free of charge. We do not charge any additional fees. Once our AI-300 Learning Materials are updated, we will automatically send you the latest information about our AI-300 exam question. We assure you that our company will provide customers with a sustainable update system.
Valid AI-300 Exam Format: https://www.braindumpsqa.com/AI-300_braindumps.html
P.S. Free & New AI-300 dumps are available on Google Drive shared by Braindumpsqa: https://drive.google.com/open?id=1C4gffnRf0gQIItwoq2fFON5u0y4GlQdr