DP-100試験3回目にして合格した僕がおすすめする参考書はこれJPTestKing

2026年JPTestKingの最新DP-100 PDFダンプおよびDP-100試験エンジンの無料共有:https://drive.google.com/open?id=1ewnzOCmlTwIQ4r63TOeNuA5ctv9pSU6q
DP-100 Designing and Implementing a Data Science Solution on Azureは、技術的な精度の最高水準を高め、認定された主題と専門家のみを使用します。最新の正確なDP-100試験トレントをクライアントに提供し、提供する質問と回答は実際の試験に基づいています。合格率が高く、約98%-100%であることをお約束します。また、DP-100テストブレインダンプは高いヒット率を高め、試験を刺激してDP-100試験の準備を整えることができます。あなたの成功は、DP-100試験問題に縛られています。
Microsoft DP-100 Exam Overview:
| Certification Vendor: | Microsoft |
|---|
| Exam Name: | Designing and Implementing a Data Science Solution on Azure |
|---|
| Exam Number: | DP-100 |
|---|
| Available Languages: | Japanese, Chinese (Simplified), French, Portuguese, English, Spanish, German, Korean |
|---|
| Passing Score: | 700/1000 |
|---|
| Certificate Validity Period: | 1 year |
|---|
| Real Exam Qty: | 40-60 |
|---|
| Exam Format: | Interactive Tasks, Drag and Drop, Case Study, Multiple Choice, Lab |
|---|
| Exam Duration: | 100 minutes |
|---|
| Exam Price: | $165 USD |
|---|
| Related Certifications: | Microsoft Certified: Azure Data Scientist Associate |
|---|
| Sample Questions: | Microsoft DP-100 Sample Questions |
|---|
| Exam Way: | Online proctored exam or test center delivery through Pearson VUE. |
|---|
| Pre Condition: | Candidates should have experience with Azure services, Python programming, and machine learning frameworks such as Scikit-Learn, PyTorch, or TensorFlow. |
|---|
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-100/ |
|---|
>> DP-100試験勉強過去問 <<
一番いいDP-100試験勉強過去問 & 資格試験におけるリーダーオファー & 正確的なMicrosoft Designing and Implementing a Data Science Solution on Azure
DP-100トレーニング資料を用意しました。 これらは、保証対象の専門的な練習資料です。 参考のために許容できる価格に加えて、3つのバージョンのすべての資料は、10年以上にわたってこの分野の専門家によって編集されています。 さらに、一連の利点があります。 したがって、DP-100の実際のテストの重要性は言うまでもありません。 今すぐご注文いただいた場合、1年間無料の更新をお送りします。 これらのサプリメントはすべて、DP-100模擬試験にも役立ちます。
Microsoft DP-100認定試験の準備をするには、候補者はデータサイエンスの概念を確実に理解し、Azureツールとサービスを使用した経験が必要です。 Microsoftは、オンライントレーニングコース、練習試験、学習ガイドなど、候補者が試験の準備を支援するためのさまざまなリソースを提供しています。候補者は、ブログ、フォーラム、チュートリアルなど、オンラインで豊富な情報やリソースを見つけることもできます。
Microsoft Designing and Implementing a Data Science Solution on Azure 認定 DP-100 試験問題 (Q334-Q339):
質問 # 334
You manage an Azure Machine Learning workspace named workspace1 with a compute instance named compute1. You connect to compute! by using a terminal window from wofkspace1. You create a file named
"requirements.txt" containing Python dependencies to include Jupyler.
You need to add a new Jupyter kernel to compute1.
Which four commands should you use? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.

正解:
解説:
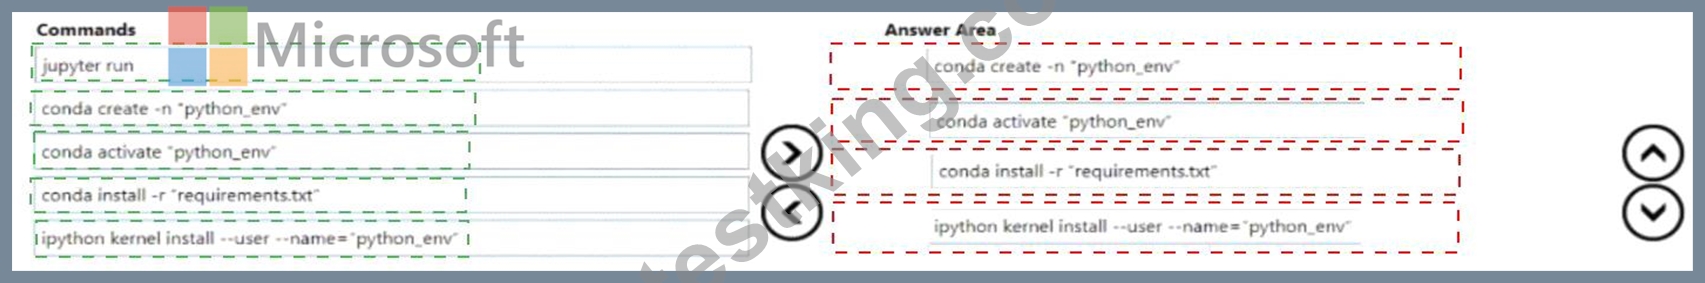
Explanation

質問 # 335

You need to obtain the output from the pipeline execution. Where will you find the output?
- A. the digitjdentification.py script
- B. the Inference Clusters tab in Machine Learning studio
- C. a file named parallel_run_step.txt located in the output folder
- D. the debug log
- E. the Activity Log in the Azure portal for the Machine Learning workspace
正解:C
解説:
output_action (str): How the output is to be organized. Currently supported values are 'append_row' and
'summary_only'.
* 'append_row' - All values output by run() method invocations will be aggregated into one unique file named parallel_run_step.txt that is created in the output location.
* 'summary_only'
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-contrib-pipeline-steps/azureml.contrib.pipeline.steps.parall
質問 # 336
You have a dataset that contains over 150 features. You use the dataset to train a Support Vector Machine (SVM) binary classifier.
You need to use the Permutation Feature Importance module in Azure Machine Learning Studio to compute a set of feature importance scores for the dataset.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.

正解:
解説:

Explanation:

Step 1: Add a Two-Class Support Vector Machine module to initialize the SVM classifier.
Step 2: Add a dataset to the experiment
Step 3: Add a Split Data module to create training and test dataset.
To generate a set of feature scores requires that you have an already trained model, as well as a test dataset.
Step 4: Add a Permutation Feature Importance module and connect to the trained model and test dataset.
Step 5: Set the Metric for measuring performance property to Classification - Accuracy and then run the experiment.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/two-class-support-vector- machine
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature- importance
質問 # 337
You manage an Azure Machine Learning workspace named workspace1 with a compute instance named compute1. You connect to compute! by using a terminal window from wofkspace1. You create a file named
"requirements.txt" containing Python dependencies to include Jupyler.
You need to add a new Jupyter kernel to compute1.
Which four commands should you use? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.

正解:
解説:

Explanation:

質問 # 338
You need to define an evaluation strategy for the crowd sentiment models.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.

正解:
解説:

1 - Define a cross-entropy function activation
2 - Add cost functions for each target state.
3 - Evaluated the distance error metric.
Reference:
https://www.analyticsvidhya.com/blog/2018/04/fundamentals-deep-learning-regularization-techniques/
質問 # 339
......
DP-100日本語受験教科書: https://www.jptestking.com/DP-100-exam.html
- 100%合格率のDP-100試験勉強過去問 - 合格スムーズDP-100日本語受験教科書 | 便利なDP-100認証資格 🔨 ( www.mogiexam.com )を開いて“ DP-100 ”を検索し、試験資料を無料でダウンロードしてくださいDP-100受験対策書
- DP-100 有効練習問題集、DP-100学習準備資料、Designing and Implementing a Data Science Solution on Azure 試験練習pdf 🧔 ☀ DP-100 ️☀️を無料でダウンロード▷ www.goshiken.com ◁で検索するだけDP-100受験対策書
- 100%合格率のDP-100試験勉強過去問 - 合格スムーズDP-100日本語受験教科書 | ハイパスレートのDP-100認証資格 🦇 ( www.passtest.jp )は、✔ DP-100 ️✔️を無料でダウンロードするのに最適なサイトですDP-100関連受験参考書
- DP-100日本語試験情報 🍟 DP-100最新資料 📁 DP-100問題トレーリング ▶ ▷ www.goshiken.com ◁サイトにて最新▶ DP-100 ◀問題集をダウンロードDP-100資格トレーリング
- DP-100試験の準備方法|最新のDP-100試験勉強過去問試験|検証するDesigning and Implementing a Data Science Solution on Azure日本語受験教科書 🌅 ➠ www.passtest.jp 🠰を開き、▛ DP-100 ▟を入力して、無料でダウンロードしてくださいDP-100問題トレーリング
- DP-100試験概要 🐵 DP-100問題と解答 📠 DP-100関連受験参考書 🦞 ⮆ www.goshiken.com ⮄サイトにて《 DP-100 》問題集を無料で使おうDP-100試験概要
- DP-100問題トレーリング 🤍 DP-100テストトレーニング 💖 DP-100模擬練習 🔒 ➤ www.goshiken.com ⮘には無料の《 DP-100 》問題集がありますDP-100学習資料
- DP-100日本語試験情報 👪 DP-100資格トレーリング ↖ DP-100認定テキスト 🎿 URL ▶ www.goshiken.com ◀をコピーして開き、➡ DP-100 ️⬅️を検索して無料でダウンロードしてくださいDP-100試験概要
- DP-100無料模擬試験 👦 DP-100トレーニング費用 📙 DP-100無料模擬試験 ⏩ ▛ www.topexam.jp ▟サイトにて最新《 DP-100 》問題集をダウンロードDP-100関連資格知識
- DP-100最新試験 🍟 DP-100日本語試験情報 👸 DP-100関連受験参考書 🛸 ▛ www.goshiken.com ▟で➠ DP-100 🠰を検索して、無料で簡単にダウンロードできますDP-100試験概要
- 一生懸命にDP-100試験勉強過去問 - 合格スムーズDP-100日本語受験教科書 | 更新するDP-100認証資格 🕛 ウェブサイト⮆ www.jpshiken.com ⮄を開き、[ DP-100 ]を検索して無料でダウンロードしてくださいDP-100テストトレーニング
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, zenwriting.net, Disposable vapes
2026年JPTestKingの最新DP-100 PDFダンプおよびDP-100試験エンジンの無料共有:https://drive.google.com/open?id=1ewnzOCmlTwIQ4r63TOeNuA5ctv9pSU6q