What's more, part of that BraindumpsVCE AI-300 dumps now are free: https://drive.google.com/open?id=1flSYTgDjpaEDqM5kKWZQjeQiORa3Z1PM
The BraindumpsVCE is one of the top-rated and reliable platforms that has been helping the Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam candidates for many years. Over this long time period, these AI-300 questions have helped countless AI-300 exam candidates. They all got help from the top-rated AI-300 Practice Test questions and easily passed their dream Microsoft AI-300 certification exam and now they have become certified AI-300 professionals and doing jobs in top world brands.
| Section | Objectives |
|---|---|
| Design and implement generative AI solutions | - Large language model integration
|
| Implement secure and scalable AI systems | - Security and governance
|
| Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
| Operationalizing machine learning solutions | - ML lifecycle management
|
Now passing Microsoft certification AI-300 exam is not easy, so choosing a good training tool is a guarantee of success. BraindumpsVCE will be the first time to provide you with exam information and exam practice questions and answers to let you be fully prepared to ensure 100% to pass Microsoft Certification AI-300 Exam. BraindumpsVCE can not only allow you for the first time to participate in the Microsoft certification AI-300 exam to pass it successfully, but also help you save a lot of valuable time.
NEW QUESTION # 116
You manage an Azure Machine Learning workspace.
An MLflow model is already registered. You plan to customize how the deployment does inference. You need to deploy the MLflow model to a batch endpoint for batch inferencing. What should you create first?
Answer: A
NEW QUESTION # 117
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to refine a GPT-5 model so that its performance and behavior align with the technical and business requirements of Fabrikam Inc.
Which two Foundry strategies should you apply? Each correct answer presents a complete solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: B,D
Explanation:
Scenario, Technical Requirements:
Improve RAG-based solution output quality.
Apply advanced fine-tuning techniques only when prompt engineering is insufficient Business Requirements:
Provide a conversational interface that answers analytics questions by using internal documents and datasets.
The two Foundry strategies that would be most useful in this scenario are Evaluations and Supervised fine-tuning.
Evaluations: This strategy is critical for improving RAG-based solution output quality. It provides systemic measurement to test how changes to your data, prompts, or retrieval chunks impact the accuracy, relevance, and groundedness of the model's answers before moving to more complex methods.
Supervised fine-tuning: This strategy directly satisfies the requirement to apply advanced fine- tuning techniques only when prompt engineering is insufficient. It allows you to deeply customize the model's behavior and conversational tone to fit your specific analytics interface requirements.
Incorrect:
Guardrails: While valuable for safety and compliance, guardrails focus on enforcing hard operational boundaries (e.g., blocking toxic content or preventing data leaks). They do not optimize RAG output quality or provide advanced behavioral updates when prompt engineering fails.
Synthetic data generation: While helpful for bootstrapping training datasets when real-world data is scarce, it is an data-preparation step rather than a core model refinement strategy designed to iteratively solve prompt engineering limitations or build conversational systems.
Reference:
https://medium.com/@hugoparreao/context-engineering-what-really-improves-the-performance-of-llms-0c0e3ed45c98
NEW QUESTION # 118
You are training machine learning models in Azure Machine Learning. You use Hyperdrive to tune the hyperparameters.
In previous model training and tuning runs, many models showed similar performance.
You need to select an early termination policy that meets the following requirements:
* Accounts for the performance of all previous runs when evaluating the current run.
* Avoids comparing the current run with only the best performing run to date.
Which two early termination policies should you use? Each correct answer presents part of the solution.
Answer: A,D
Explanation:
Median stopping and Truncation selection both evaluate a run relative to the broader population of training runs rather than comparing it only against the single best run.
The Median Stopping Policy calculates running averages of the primary metric across all runs . At an evaluation interval, a run can be terminated when its best primary-metric performance is worse than the median of the running averages across the population. Microsoft explicitly defines this policy as being based on running averages of the primary metric of all runs.
The Truncation Selection Policy periodically ranks runs by their primary metric and terminates a configured percentage of the lowest-performing runs . For example, a 20-percent truncation policy terminates runs falling within the lowest 20 percent at the applicable evaluation interval. It therefore compares each candidate with the population of comparable runs rather than only the current leader.
Bandit is specifically unsuitable because it uses an allowable slack relative to the best-performing run , which directly violates the requirement. The Default behavior applies no early termination policy and allows runs to execute to completion.
Study Guide Reference: Implement machine learning model lifecycle and operations - automated hyperparameter tuning, early termination policies, Median Stopping Policy, Truncation Selection Policy, and efficient experiment execution.
NEW QUESTION # 119
Drag and Drop Question
You have an existing GitHub repository containing Azure Machine Learning project files.
You need to clone the repository to your Azure Machine Learning shared workspace file system.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.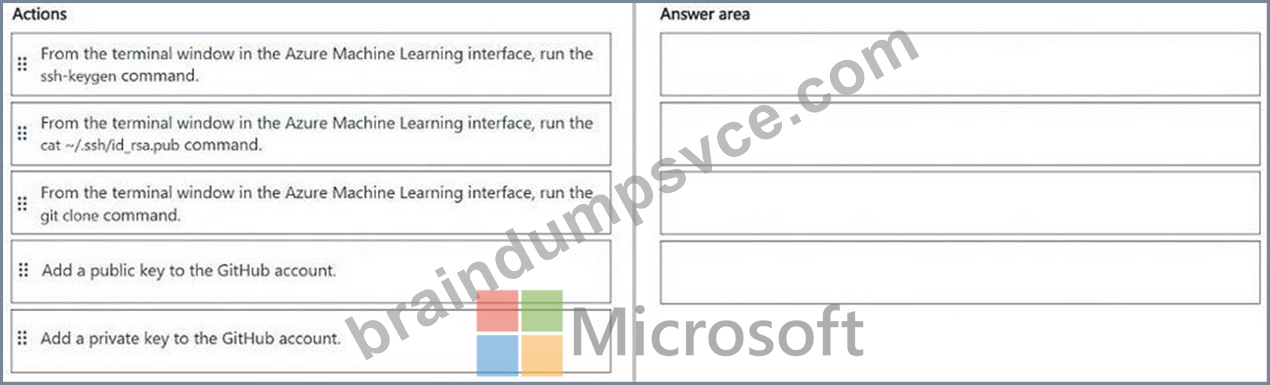
Answer:
Explanation: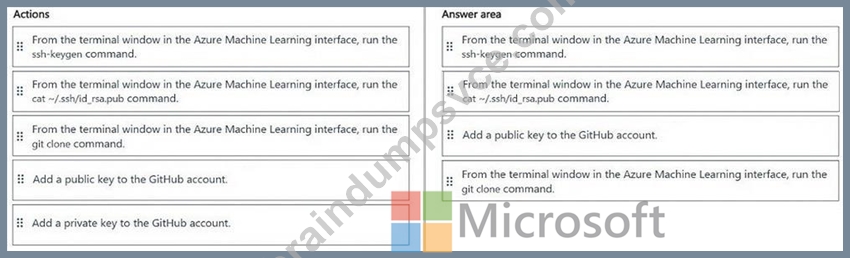
NEW QUESTION # 120
Hotspot Question
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_data. The folder structure contains the following content: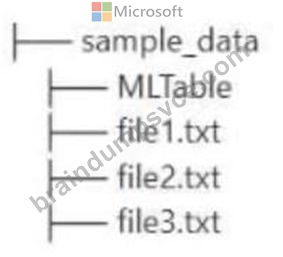
You write Python SDK v2 code to materialize the data from the files in the sample_data folder into a Pandas data frame.
You need to complete the Python SDK v2 code to use the MLTable folder as the materialization blueprint.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point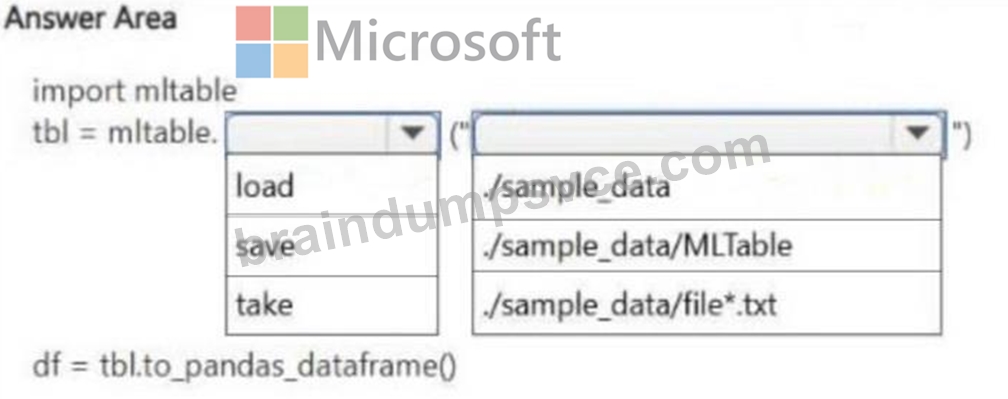
Answer:
Explanation: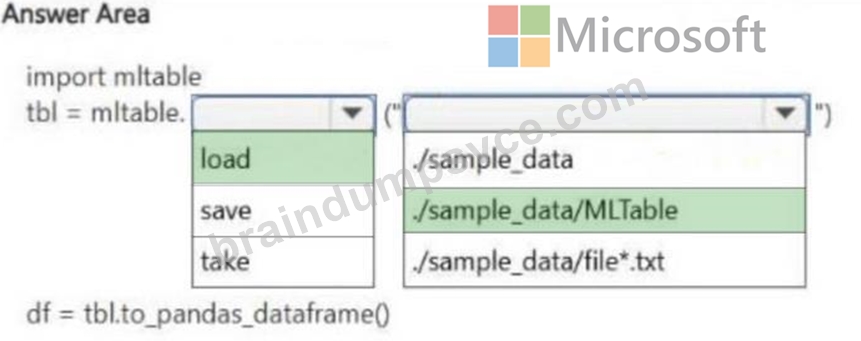
NEW QUESTION # 121
......
Download AI-300 Actual Questions and Start Your Preparation Now! Get these amazing offers from Operationalizing Machine Learning and Generative AI Solutions real dumps and begin AI-300 test preparation without wasting further time. The Microsoft Exam Operationalizing Machine Learning and Generative AI Solutions certification is indeed beneficial to advancing your Microsoft career. Enroll in the AI-300 examination and start preparation. We have a 24/7 customer support.
Test AI-300 Objectives Pdf: https://www.braindumpsvce.com/AI-300_exam-dumps-torrent.html
BTW, DOWNLOAD part of BraindumpsVCE AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1flSYTgDjpaEDqM5kKWZQjeQiORa3Z1PM