
DOWNLOAD the newest TorrentExam MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1u4EHPVby-s8mq3HbuhCde0i1xAU_VcLl
We are pleased to inform you that we have engaged in this business for over ten years with our MLA-C01 exam questions. Because of our past years’ experience, we are well qualified to take care of your worried about the MLA-C01 Preparation exam and smooth your process with successful passing results. Our pass rate of the MLA-C01 study materials is high as 98% to 100% which is unique in the market.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Model Deployment and Inference | 20% | - Model versioning and rollback - A/B testing and shadow mode deployment - Inference optimization (latency, throughput) - SageMaker endpoints configuration - Model deployment strategies (real-time, batch) |
| Topic 2: Model Development | 30% | - Algorithm selection and model architecture - ML frameworks (SageMaker, built-in algorithms) - Distributed training - Training and validation strategies - Transfer learning and fine-tuning - Hyperparameter optimization |
| Topic 3: MLOps and Monitoring | 28% | - Security and access management for ML - Model lineage and reproducibility - Cost optimization for ML workloads - Incident response and remediation - Model monitoring and drift detection - CI/CD pipelines for ML |
| Topic 4: Data Processing | 22% | - Data preprocessing and feature engineering - Data ingestion and transformation - Data validation and quality assessment - Handling imbalanced data - Data pipelining with AWS services ( Glue, Data Brew, etc.) |
>> Exam Vce Amazon MLA-C01 Free <<
Because they are immensely useful and help you gain success in a MLA-C01 certification exam. More than ever, the professionals are now facing a highly competitive world to get their talent recognized enhancing their positions in their work environment. Such a milieu demands them to enrich their candidature more seriously. So the professionals work hard to maintain their quality and never fail in doing so. TorrentExam MLA-C01 Certification exams are the best option for any ambitious and ardent professional to make his continuation in his area of work intact.
NEW QUESTION # 26
A company is developing an ML model for a customer. The training data is stored in an Amazon S3 bucket in the customer's AWS account (Account A). The company runs Amazon SageMaker AI training jobs in a separate AWS account (Account B).
The company defines an S3 bucket policy and an IAM policy to allow reads to the S3 bucket.
Which additional steps will meet the cross-account access requirement?
Answer: B
Explanation:
For cross-account Amazon S3 access, AWS requires two components:
* An S3 bucket policy in the owning account (Account A) that grants access to a principal in another account
* An IAM role policy in the consuming account (Account B) that allows the service to access the bucket Amazon SageMaker training jobs assume an IAM role in the account where the job runs-in this case, Account B. Therefore, the IAM policy must be attached to the SageMaker execution role in Account B.
The S3 bucket policy must reside in Account A because bucket policies are owned and enforced by the bucket owner. This policy explicitly allows the IAM role from Account B to read the training data.
Any other combination fails either because the policy is in the wrong account or because the role is not the one used by SageMaker.
AWS documentation clearly describes this pattern as the correct way to grant cross-account access for SageMaker training jobs.
Therefore, Option B is the correct and AWS-aligned solution.
NEW QUESTION # 27
A company is planning to use Amazon Redshift ML in its primary AWS account. The source data is in an Amazon S3 bucket in a secondary account.
An ML engineer needs to set up an ML pipeline in the primary account to access the S3 bucket in the secondary account. The solution must not require public IPv4 addresses.
Which solution will meet these requirements?
Answer: B
Explanation:
S3 Gateway Endpoint: Allows private access to S3 from within a VPC without requiring a public IPv4 address, ensuring that data transfer between the primary and secondary accounts is secure and private.
Bucket Policy Update: The S3 bucket policy in the secondary account must explicitly allow access from the primary account's IAM principals to provide the necessary permissions.
Interface VPC Endpoints: Required for private communication between the VPC and Amazon SageMaker and Amazon Redshift services, ensuring the solution operates without public internet access.
This configuration meets the requirement to avoid public IPv4 addresses and allows secure and private communication between the accounts.
NEW QUESTION # 28
A company uses Amazon SageMakerAI to support ML workflows such as model training and deployment.
Select the correct registry from the following list to meet the requirements for each use case with the LEAST operational overhead. Each registry should be selected one or more times. (Select FOUR.)
* Amazon Elastic Container Registry (Amazon ECR)
* SageMaker Model Registry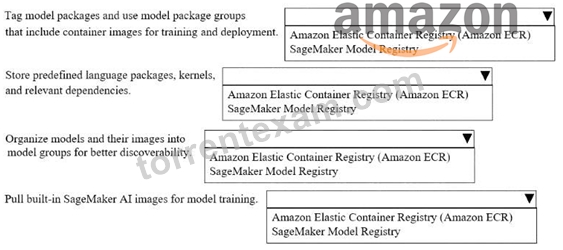
Answer:
Explanation: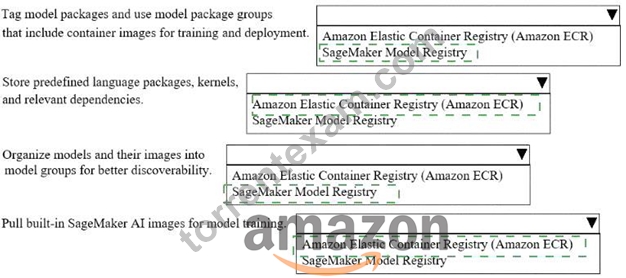
Explanation:
* Tag model packages and use model package groups that include container images for training and deployment # SageMaker Model Registry
* Store predefined language packages, kernels, and relevant dependencies # Amazon Elastic Container Registry (Amazon ECR)
* Organize models and their images into model groups for better discoverability # SageMaker Model Registry
* Pull built-in SageMaker AI images for model training # Amazon Elastic Container Registry (Amazon ECR) The correct hotspot mapping is based on the different purposes of SageMaker Model Registry and Amazon ECR .
For model packages , model package groups , and model discoverability, the correct choice is SageMaker Model Registry . AWS documentation states that a model package group is a collection of versioned model packages, and each version can contain the model artifacts, metadata, and container information used for deployment. AWS also documents that registered models can be organized into groups to support governance, discoverability, and lifecycle management. That is why both " tag model packages and use model package groups " and " organize models and their images into model groups " map to SageMaker Model Registry
.
For storing software environments and pulling training images, the correct choice is Amazon ECR . AWS documentation says SageMaker uses Docker container images , and these images contain the software stack such as frameworks, language packages, kernels, and dependencies. AWS also states that SageMaker provides prebuilt Docker images for training and inference, and these are referenced through Amazon ECR image URIs . Therefore, both " store predefined language packages, kernels, and relevant dependencies " and " pull built-in SageMaker AI images for model training " map to Amazon ECR .
NEW QUESTION # 29
A company wants to host an ML model on Amazon SageMaker. An ML engineer is configuring a continuous integration and continuous delivery (Cl/CD) pipeline in AWS CodePipeline to deploy the model. The pipeline must run automatically when new training data for the model is uploaded to an Amazon S3 bucket.
Select and order the pipeline's correct steps from the following list. Each step should be selected one time or not at all. (Select and order three.)
* An S3 event notification invokes the pipeline when new data is uploaded.
* S3 Lifecycle rule invokes the pipeline when new data is uploaded.
* SageMaker retrains the model by using the data in the S3 bucket.
* The pipeline deploys the model to a SageMaker endpoint.
* The pipeline deploys the model to SageMaker Model Registry.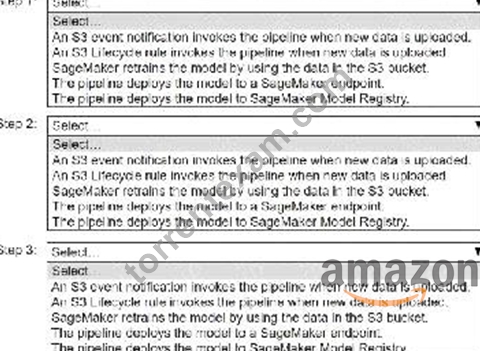
Answer:
Explanation: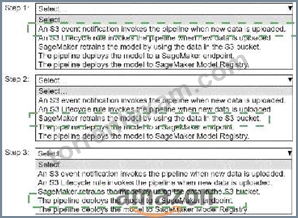
Explanation:
Step 1: An S3 event notification invokes the pipeline when new data is uploaded.Step 2: SageMaker retrains the model by using the data in the S3 bucket.Step 3: The pipeline deploys the model to a SageMaker endpoint.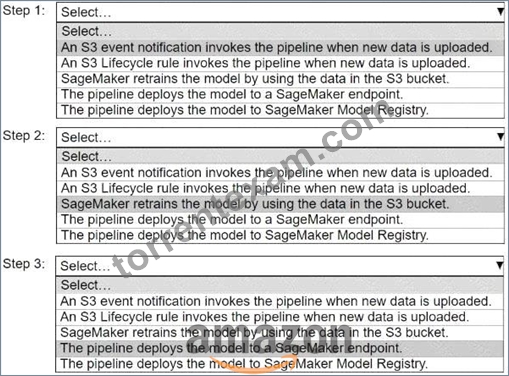
* Step 1: An S3 Event Notification Invokes the Pipeline When New Data is Uploaded
* Why?The CI/CD pipeline should be triggered automatically whenever new training data is uploaded to Amazon S3. S3 event notifications can be configured to send events to AWS services like Lambda, which can then invoke AWS CodePipeline.
* How?Configure the S3 bucket to send event notifications (e.g., s3:ObjectCreated:*) to AWS Lambda, which in turn triggers the CodePipeline.
* Step 2: SageMaker Retrains the Model by Using the Data in the S3 Bucket
* Why?The uploaded data is used to retrain the ML model to incorporate new information and maintain performance. This step is critical to updating the model with fresh data.
* How?Define a SageMaker training step in the CI/CD pipeline, which reads the training data from the S3 bucket and retrains the model.
* Step 3: The Pipeline Deploys the Model to a SageMaker Endpoint
* Why?Once retrained, the updated model must be deployed to a SageMaker endpoint to make it available for real-time inference.
* How?Add a deployment step in the CI/CD pipeline, which automates the creation or update of the SageMaker endpoint with the retrained model.
Order Summary:
* An S3 event notification invokes the pipeline when new data is uploaded.
* SageMaker retrains the model by using the data in the S3 bucket.
* The pipeline deploys the model to a SageMaker endpoint.
This configuration ensures an automated, efficient, and scalable CI/CD pipeline for continuous retraining and deployment of the ML model in Amazon SageMaker.
NEW QUESTION # 30
A financial company receives a high volume of real-time market data streams from an external provider. The streams consist of thousands of JSON records per second.
The company needs a scalable AWS solution to identify anomalous data points with the LEAST operational overhead.
Which solution will meet these requirements?
Answer: B
Explanation:
For real-time anomaly detection on streaming data, AWS recommends using Amazon Managed Service for Apache Flink, which provides serverless, scalable stream processing with built-in ML functions.
Apache Flink includes a native RANDOM_CUT_FOREST (RCF) function for unsupervised anomaly detection. This eliminates the need to deploy, manage, or scale custom ML endpoints. When combined with Amazon Kinesis Data Streams, the solution can process thousands of records per second with very low latency.
Option B introduces multiple services and custom logic, increasing operational overhead. Option C requires managing EC2 infrastructure and Kafka clusters. Option D is batch-oriented and does not meet real-time requirements.
AWS documentation explicitly highlights Kinesis + Managed Flink + RCF as the lowest-overhead solution for real-time anomaly detection.
Therefore, Option A is the correct and AWS-aligned choice.
NEW QUESTION # 31
......
A certification is not only an affirmation to your ability but also can help you enter a better company and improve your salary. MLA-C01 exam cram can help you get your certification successfully. We have a professional team to collect and research the latest information for the exam, and we offer you free update for 365 days after payment, so that you can obtain the latest information. In order to build up your confidence for MLA-C01 Exam Braindumps, we are pass guarantee and money back guarantee if you fail to pass the exam.
Download MLA-C01 Fee: https://www.torrentexam.com/MLA-C01-exam-latest-torrent.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by TorrentExam: https://drive.google.com/open?id=1u4EHPVby-s8mq3HbuhCde0i1xAU_VcLl