Außerdem sind jetzt einige Teile dieser EchteFrage AIF-C01 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1jPySbCC_2myeM4qpvInqEnXLyK2OKdfH
Amazon AIF-C01 dumps von EchteFrage sind die unentbehrliche Prüfungsunterlagen, mit denen Sie sich auf Amazon AIF-C01 Zertifizierung vorbereiten. Der Wert dieser Unterlagen ist gleich wie die anderen Nachschlagsbücher. Diese Meinung ist nicht übertrieben. Wenn Sie diese Schulungsunterlagen zur Amazon AIF-C01 Zertifizierung benutzen, finden Sie es wirklich.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified AI Practitioner |
| Exam Number: | AIF-C01 |
| Related Certifications: | AWS Certified Machine Learning Engineer - Associate AWS Certified Cloud Practitioner AWS Certified Data Engineer - Associate |
| Available Languages: | Japanese, Simplified Chinese, English, Portuguese (Brazil), Korean |
| Passing Score: | 700 / 1000 |
| Certificate Validity Period: | 3 years |
| Exam Price: | USD 100 |
| Exam Format: | Multiple response, Multiple choice |
| Real Exam Qty: | 80 |
| Exam Duration: | 90 minutes |
| Sample Questions: | Amazon AIF-C01 Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) or in-person testing center |
| Pre Condition: | None required. Recommended: General IT cloud knowledge and basic understanding of AI/ML concepts. AWS Cloud Practitioner certification is a recommended prerequisite but not mandatory. |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-ai-practitioner/ |
Die Amazon AIF-C01 Zertifizierungsprüfung gehört zu den beliebtesten IT-Zertifizierungen. Viele ambitionierte IT-Fachleute wollen auch Amazon AIF-C01 Prüfung bestehen. Viele Kandidaten sollen genügende Vorbereitungen treffen, um eine hohe Note zu bekommen und sich den Bedürfnissen des Marktes anzupassen.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
| Thema 4 |
|
| Thema 5 |
|
293. Frage
A customer service team uses Amazon Bedrock to summarize conversation transcripts. The team needs to redact personally identifiable information (PII) from the summaries.
Which Amazon Bedrock Guardrails filter should the team configure?
Antwort: C
Begründung:
Amazon Bedrock Guardrails provides sensitive information filters that identify and protect personally identifiable information within user inputs and model-generated responses.
These filters support built-in PII categories, including names, email addresses, telephone numbers, physical addresses, and other sensitive identifiers.
Organizations can configure the filters to block content or anonymize detected PII by replacing it with descriptive placeholders.
For example, a customer service summary containing an email address can have that information replaced with an appropriate PII category marker.
Word filters block specified terms or expressions rather than performing contextual PII detection.
Contextual grounding checks evaluate whether generated responses are supported by reference information.
Automated reasoning checks validate statements against formal policy rules.
Therefore, sensitive information filters are the correct solution for redacting customer PII from conversation summaries.
294. Frage
A company wants to build an ML application.
Select and order the correct steps from the following list to develop a well-architected ML workload. Each step should be selected one time. (Select and order FOUR.)
* Deploy model
* Develop model
* Monitor model
* Define business goal and frame ML problem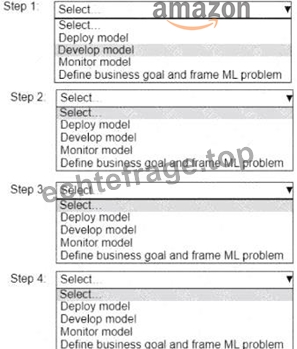
Antwort:
Begründung: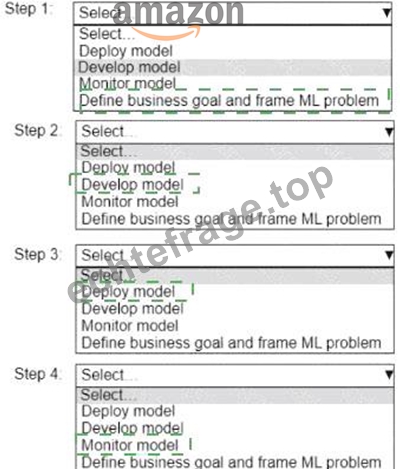
Explanation: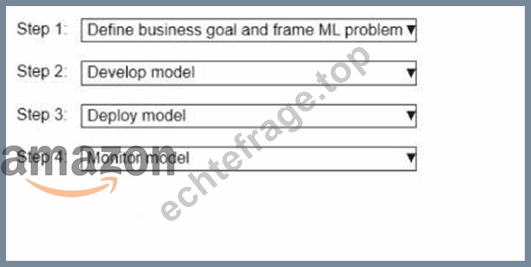
Building a well-architected ML workload follows a structured lifecycle as outlined in AWS best practices.
The process begins with defining the business goal and framing the ML problem to ensure the project aligns with organizational objectives. Next, the model is developed, which includes data preparation, training, and evaluation. Once the model is ready, it is deployed tomake predictions in a production environment. Finally, the model is monitored to ensure it performs as expected and to address any issues like drift or degradation over time. This order ensures a systematic approach to ML development.
Exact Extract from AWS AI Documents:
From the AWS AI Practitioner Learning Path:
"The machine learning lifecycle typically follows these stages: 1) Define the business goal and frame the ML problem, 2) Develop the model (including data preparation, training, and evaluation), 3) Deploy the model to production, and 4) Monitor the model for performance and drift to ensure it continues to meet business needs." (Source: AWS AI Practitioner Learning Path, Module on Machine Learning Lifecycle) Detailed Explanation:
* Step 1: Define business goal and frame ML problemThis is the first step in any ML project. It involves understanding the business objective (e.g., reducing churn) and framing the ML problem (e.g., classification or regression). Without this step, the project lacks direction. The hotspot lists this option as "Define business goal and frame ML problem," which matches this stage.
* Step 2: Develop modelAfter defining the problem, the next step is to develop the model. This includes collecting and preparing data, selecting an algorithm, training the model, and evaluating its performance. The hotspot lists "Develop model" as an option, aligning with this stage.
* Step 3: Deploy modelOnce the model is developed and meets performance requirements, it is deployed to a production environment to make predictions or automate decisions. The hotspot includes "Deploy model" as an option, which fits this stage.
* Step 4: Monitor modelAfter deployment, the model must be monitored to ensure it performs well over time, addressing issues like data drift or performance degradation. The hotspot lists "Monitor model" as an option, completing the lifecycle.
Hotspot Selection Analysis:
The hotspot provides four steps, each with the same dropdown options: "Select...," "Deploy model," "Develop model," "Monitor model," and "Define business goal and frame ML problem." The correct selections are:
* Step 1: Define business goal and frame ML problem
* Step 2: Develop model
* Step 3: Deploy model
* Step 4: Monitor model
Each option is used exactly once, as required, and follows the logical order of the ML lifecycle.
References:
AWS AI Practitioner Learning Path: Module on Machine Learning Lifecycle Amazon SageMaker Developer Guide: Machine Learning Workflow (https://docs.aws.amazon.com/sagemaker
/latest/dg/how-it-works-mlconcepts.html)
AWS Well-Architected Framework: Machine Learning Lens (https://docs.aws.amazon.com/wellarchitected
/latest/machine-learning-lens/)
295. Frage
A financial company uses a generative AI model to assign credit limits to new customers. The company wants to make the decision-making process of the model more transparent to its customers.
Antwort: C
Begründung:
According to the AWS Certified AI Practitioner documentation, explainable AI (XAI) refers to methods and techniques that make the behavior and predictions of machine learning models more understandable and transparent to users and stakeholders. In financial use cases, especially when decisions such as credit limits are made, regulatory and ethical concerns demand transparency about how such decisions are reached.
Option B is correct because applying explainable AI techniques (such as SHAP, LIME, or Amazon SageMaker Clarify) allows organizations to provide customers with clear insights into which data points or factors contributed to the model's decision. This aligns with best practices for responsible AI as defined in the AWS documentation, which states:
"Explainable AI increases transparency and trust in machine learning applications by helping users and regulators understand the decision process behind model predictions." (Reference: AWS AI/ML Best Practices - Explainable AI, AWS AI Practitioner Exam Guide)
"Explainable AI increases transparency and trust in machine learning applications by helping users and regulators understand the decision process behind model predictions." (Reference: AWS AI/ML Best Practices - Explainable AI, AWS AI Practitioner Exam Guide) Option A suggests switching to a rule-based system, which is not practical for complex problems addressed by generative AI and may reduce model performance.
Option C (just a UI) does not inherently provide transparency into the model's reasoning, unless paired with explainability techniques.
Option D (accuracy over transparency) does not address the company's requirement for transparency.
Reference:
AWS Certified AI Practitioner Exam Guide
Amazon SageMaker Clarify Documentation
296. Frage
A retail company wants to build an ML model to recommend products to customers. The company wants to build the model based on responsible practices. Which practice should the company apply when collecting data to decrease model bias?
Antwort: C
Begründung:
The retail company wants to build an ML model for product recommendations using responsible practices to decrease model bias. Collecting balanced and diverse data ensures the model does not favor specific groups, reducing bias and promoting fairness, a key responsible AI practice.
Exact Extract from AWS AI Documents:
From the AWS AI Practitioner Learning Path:
"To reduce model bias, it is critical to collect balanced and diverse data that represents various demographics and user groups. This practice ensures fairness and prevents the model from disproportionately favoring certain populations." (Source: AWS AI Practitioner Learning Path, Module on Responsible AI) Detailed Explanation:
* Option A: Use data from only customers who match the demography of the company's overall customer base.Limiting data to a specific demographic may reinforce existing biases, failing to address underrepresented groups and increasing bias.
* Option B: Collect data from customers who have a past purchase history.Focusing only on customers with purchase history may exclude new users, potentially introducing bias, and does not address diversity.
* Option C: Ensure that the data is balanced and collected from a diverse group.This is the correct answer. A balanced and diverse dataset reduces bias by ensuring the model learns from a representative sample, aligning with responsible AI practices.
* Option D: Ensure that the data is from a publicly available dataset.Public datasets may not be diverse or representative of the company's customer base and could introduce unrelated biases, failing to address fairness.
References:
AWS AI Practitioner Learning Path: Module on Responsible AI
Amazon SageMaker Developer Guide: Bias and Fairness in ML (https://docs.aws.amazon.com/sagemaker
/latest/dg/clarify-bias.html)
AWS Documentation: Responsible AI Practices (https://aws.amazon.com/machine-learning/responsible-ai/)
297. Frage
A company wants more customized responses to its generative AI models' prompts.
Select the correct customization methodology from the following list for each use case. Each use case should be selected one time. (Select THREE.)
* Continued pre-training
* Data augmentation
* Model fine-tuning
Antwort:
Begründung: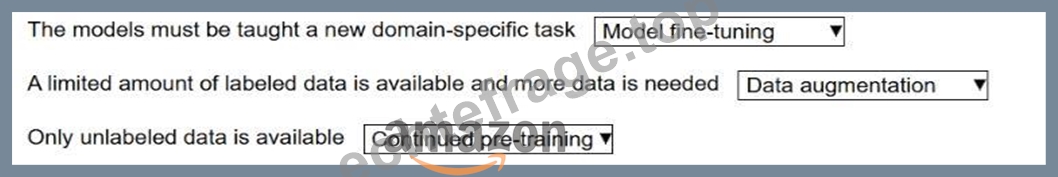
Model fine-tuning adapts a pre-trained model to a specific domain or task using labeled data. This is the preferred approach when you want highly customized behavior for a particular application or subject area.
(Reference: Amazon Bedrock Fine-Tuning)
Data augmentation is used to artificially increase the size of a labeled dataset, usually by transforming or generating variations of the original data. This helps improve model generalization when labeled data is limited.
(Reference: AWS Data Preparation Techniques, AWS AI Practitioner Guide) Continued pre-training (also called domain-adaptive pre-training) further trains a foundation model on large amounts of unlabeled data from a specific domain, improving the model's language understanding or generation for that domain.
(Reference: Amazon Bedrock Customization Options)
298. Frage
......
AIF-C01 Ausbildungsressourcen: https://www.echtefrage.top/AIF-C01-deutsch-pruefungen.html
Übrigens, Sie können die vollständige Version der EchteFrage AIF-C01 Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1jPySbCC_2myeM4qpvInqEnXLyK2OKdfH