SPS-C01認定資格試験 & SPS-C01ソフトウエア

現状に自己満足して、自分の小さな持ち場を守って少ない給料をもらって解雇されるのを待っている人がいないです。こんな生活はとてもつまらないですから。あなたの人生をよりカラフルにしたいのですか。ここで成功へのショートカットを教えてあげます。即ちSnowflakeのSPS-C01認定試験に受かることです。この認証を持っていたら、あなたは、高レベルのホワイトカラーの生活を送ることができます。実力を持っている人になって、他の人に尊敬されることもできます。It-PassportsはSnowflakeのSPS-C01試験トレーニング資料を提供できます。It-Passportsを利用したら、あなたは美しい夢を実現することができます。さあ、ためらわずにIt-PassportsのSnowflakeのSPS-C01試験トレーニング資料をショッピングカートに入れましょう。
Snowflake SPS-C01 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Snowpark Concepts | 15% | - Stored procedures and conditional logic
- Client-side vs. Server-side execution
- Snowpark DataFrames and query plans
- Snowpark Sessions and connection management
- Transformations vs. Actions
- Snowpark architecture and core concepts
|
| Topic 2: Performance Optimization and Best Practices | 20% | - Caching strategies
- Minimizing data transfer
- Vectorized UDFs
- Warehouse sizing for Snowpark
- Query pushdown and optimization
- Debugging and explain plans
|
| Topic 3: Snowpark API for Python | 30% | - Establishing connections and session management
- DataFrame creation and manipulation
- Working with Semi-structured data
- User-Defined Functions (UDFs) and Stored Procedures
- Reading and writing data
|
| Topic 4: Data Transformations and DataFrame Operations | 35% | - Persisting transformed data
- Filtering, Aggregating, and Joining DataFrames
- Using built-in functions
- Window functions
- Complex data pipelines
|
>> SPS-C01認定資格試験 <<
SPS-C01試験の準備方法|100%合格率のSPS-C01認定資格試験試験|信頼的なSnowflake Certified SnowPro Specialty - Snowparkソフトウエア
私たちが提供するSnowflake Certified SnowPro Specialty - Snowpark準備トレントは、精巧にコンパイルされ、非常に効率的です。 SPS-C01試験トレントを練習するのに20〜30時間しかかからず、試験に参加できます。仕事などで忙しいほとんどのお客様。ただし、SPS-C01テスト準備を使用する場合、短時間で試験を準備して試験内容をマスターするのにそれほど時間は必要ありません。彼らがする必要があるのは、毎日学習して練習するのに1〜2時間を費やし、SPS-C01テスト準備で簡単に試験に合格することです。試験に合格するための時間と労力はほとんどかかりません。
Snowflake Certified SnowPro Specialty - Snowpark 認定 SPS-C01 試験問題 (Q290-Q295):
質問 # 290
You are developing a Snowpark application that utilizes a UDF. You need to ensure that the UDF runs with the privileges of the caller (the user executing the query). Which of the following steps are necessary to accomplish this while creating the Snowpark session?
- A. When defining the UDF using Snowpark, ensure the argument is passed in the decorator. Create the Snowpark session as usual.
- B. When creating the Snowpark session, explicitly set the 'privilege' parameter to 'CALLER.
- C. No special steps are required when creating the Snowpark session; the UDF automatically inherits the caller's privileges.
- D. After creating the Snowpark session, execute the SQL command 'ALTER SESSION SET
- E. The account administrator needs to explicitly grant the 'CREATE FUNCTION' privilege to the user.
正解:A
解説:
To ensure a UDF runs with the privileges of the caller, you need to explicitly specify the 'api_caller_identity=sf.Caller.CALLER when defining the UDF using Snowpark. This instructs Snowflake to execute the UDF with the caller's permissions. No special session configurations are needed. Option A is irrelevant for caller's identity. Option B is incorrect as it's not automatic. Option D does not exist. Option E is a valid SQL command but needs to be implemented in Python using 'session.sqr function
質問 # 291
You are tasked with creating a secure UDF in Snowflake using Snowpark Python API that encrypts sensitive customer data before storing it. The UDF should be accessible only to users with specific roles. You have the following code snippet. What needs to be done to make it secure and operationalize for multiple users?
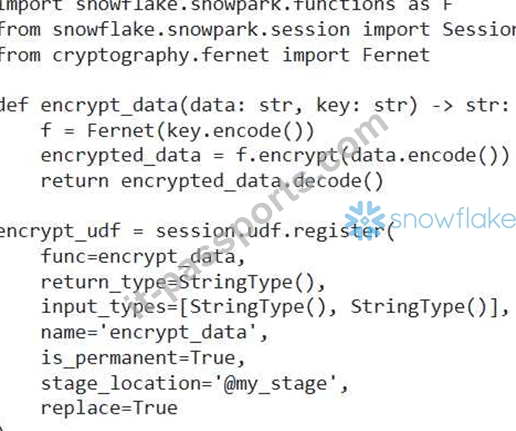
Considering Security best practices, what steps are critical for securing the UDF and granting appropriate permissions to other users?
- A. Use Snowflake's Secret object to securely store the encryption key and retrieve it within the UDF. Grant USAGE privilege on the secret to specific roles.
- B. Grant EXECUTE privilege on the UDF and USAGE privilege on the database and schema containing the UDF to the roles needing access.
- C. Grant global USAGE privilege on the function's stage location to all users.
- D. Bypass role-based access control and use shared credentials for UDF execution.
- E. Store the encryption key directly in the UDF code for simplicity.
正解:A、B
解説:
Storing the encryption key directly in the UDF code is a major security vulnerability. Snowflake's Secret object provides a secure way to store and manage sensitive information like encryption keys. Granting EXECUTE privilege on the UDF and USAGE privilege on the database and schema is essential for allowing authorized users to execute the UDF. USAGE privilege on the database and schema allows users to 'see' the UDF. Option C is incorrect because granting global USAGE privilege on the stage location is overly permissive. Option E is incorrect as bypassing role-based access control is insecure.
質問 # 292
You are tasked with deploying a Snowpark Python application that utilizes a third-party library, 'scikit-learn' , for machine learning tasks. The application will be executed as a Snowflake Stored Procedure. What are the necessary steps to ensure the 'scikit-learn' library is available within the Snowpark environment?
- A. Create a Snowflake Anaconda channel integration, add the 'scikit-learn' package to the channel, and then reference the channel in the Snowpark session configuration.
- B. Install scikit-learn on your local machine, package your snowpark code into a zip file and upload it to a stage, no extra steps are required.
- C. Include the 'scikit-learn' library directly in the Snowpark session using 'session.add_import(sklearny.
- D. Upload the 'scikit-learrf library as a ZIP file to a Snowflake stage, create a Python UDF that unzips the library, and then import the library within the Snowpark Stored Procedure.
- E. Create a Snowflake Anaconda environment using conda, include the 'scikit-learns package in the environment, and then create a Snowpark Stored Procedure that utilizes the environment via the 'packages' parameter in the CREATE PROCEDURE statement.
正解:E
解説:
The correct approach is to create a Snowflake Anaconda environment with the required packages and then specify that environment when creating the Snowpark Stored Procedure. This ensures that the environment is available during execution. A is incorrect as session.add_import() is for local file imports. B is not the recommended and reliable approach. C is overly complex. E is incorrect as the environment in Snowflake must contain the dependency.
質問 # 293
You have a Snowpark DataFrame with columns 'department' , and 'salary'. You want to identify employees in each department whose salary is within the top 20% of salaries for that department. Which of the following approaches, using window functions, is the MOST efficient way to achieve this?
- A. Use window function to rank employees within each department by salary, then calculate the 80th percentile salary using a separate aggregation and join back to the original DataFrame to filter.
- B. Use the 'ntile(5)' window function to divide each department's employees into 5 buckets based on salary, then select employees in the top bucket.
- C. Calculate the average salary per department, then filter employees whose salary is greater than 80% of the average salary.
- D. Use the window function to calculate the percentile rank of each employee's salary within their department, then filter for ranks greater than or equal to 0.8.
- E. Calculate the maximum salary per department, then filter employees whose salary is greater than or equal to 80% of the maximum salary.
正解:D
解説:
Option B is the most efficient. directly calculates the percentile rank, allowing for a simple and efficient filter. Options A and C only consider the average or maximum salary and don't provide a percentile rank. Option D divides into 5 buckets (quintiles), which isn't precise enough for identifying the top 20%. Option E is less efficient as it involves multiple steps: ranking, aggregation, and joining.
質問 # 294
You are tasked with optimizing a Snowpark application that performs complex data transformations on a large dataset (1 TB) stored in Snowflake. The application currently uses Snowpark DataFrames and is experiencing slow performance. You suspect the issue might be related to data transfer overhead between the Snowflake engine and the Python environment. Which of the following strategies would be MOST effective in minimizing this overhead and improving performance?
- A. Increase the virtual warehouse size to the largest available option (e.g., X-Large) to improve processing power within Snowflake, regardless of data transfer costs.
- B. Implement vectorization techniques within the Snowpark DataFrame operations using built-in functions and optimized expressions where applicable.
- C. Convert the Snowpark DataFrame to a Pandas DataFrame and perform the transformations locally within the Python environment.
- D. Utilize User-Defined Functions (UDFs) written in Python to encapsulate the transformations and execute them within the Snowflake engine.
- E. Reduce the data volume by applying aggressive filtering and aggregation using Snowpark DataFrame operations before any other transformations, minimizing the amount of data transferred.
正解:B、D、E
解説:
UDFs written in Python allow you to push the computation to the Snowflake engine, avoiding the need to transfer large amounts of data to the Python environment, improving performance by reducing data transfer overhead. Pre-filtering and aggregating reduces data before more complex transformations, also reducing data transfer. Vectorization through optimized Snowpark DataFrame methods also reduces data transfer and speeds computation in the Snowflake engine. Converting to Pandas DataFrames negates the benefit of Snowpark for large datasets. Increasing the virtual warehouse size only addresses processing power but does not minimize data transfer.
質問 # 295
......
SnowflakeのSPS-C01認定試験は実は技術専門家を認証する試験です。 SnowflakeのSPS-C01認定試験はIT人員が優れたキャリアを持つことを助けられます。優れたキャリアを持ったら、社会と国のために色々な利益を作ることができて、国の経済が継続的に発展していることを進められるようになります。全てのIT人員がそんなにられるとしたら、国はぜひ強くなります。It-PassportsのSnowflakeのSPS-C01試験トレーニング資料はIT人員の皆さんがそんな目標を達成できるようにヘルプを提供して差し上げます。It-PassportsのSnowflakeのSPS-C01試験トレーニング資料は100パーセントの合格率を保証しますから、ためらわずに決断してIt-Passportsを選びましょう。
SPS-C01ソフトウエア: https://www.it-passports.com/SPS-C01.html
- ハイパスレートのSPS-C01認定資格試験一回合格-信頼的なSPS-C01ソフトウエア 🅰 最新【 SPS-C01 】問題集ファイルは➽ www.it-passports.com 🢪にて検索SPS-C01模擬試験
- ハイパスレートのSPS-C01認定資格試験 - 合格スムーズSPS-C01ソフトウエア | 認定するSPS-C01学習教材 🍅 「 www.goshiken.com 」を入力して「 SPS-C01 」を検索し、無料でダウンロードしてくださいSPS-C01トレーリング学習
- SPS-C01資格関連題 😥 SPS-C01模擬試験 ⛺ SPS-C01入門知識 😩 「 jp.fast2test.com 」サイトにて「 SPS-C01 」問題集を無料で使おうSPS-C01合格内容
- 認定するSnowflake SPS-C01認定資格試験 - 合格スムーズSPS-C01ソフトウエア | ユニークなSPS-C01学習教材 🏭 ⇛ www.goshiken.com ⇚を開き、▛ SPS-C01 ▟を入力して、無料でダウンロードしてくださいSPS-C01資格関連題
- SPS-C01模擬試験 🚃 SPS-C01テキスト 🧑 SPS-C01再テスト 🚧 ✔ www.passtest.jp ️✔️から簡単に{ SPS-C01 }を無料でダウンロードできますSPS-C01受験準備
- 認定するSnowflake SPS-C01認定資格試験 - 合格スムーズSPS-C01ソフトウエア | ユニークなSPS-C01学習教材 🖊 URL ☀ www.goshiken.com ️☀️をコピーして開き、[ SPS-C01 ]を検索して無料でダウンロードしてくださいSPS-C01難易度受験料
- 優秀なSPS-C01認定資格試験 - 認定試験のリーダー - 実用的なSPS-C01ソフトウエア 🎀 ▛ SPS-C01 ▟の試験問題は( jp.fast2test.com )で無料配信中SPS-C01専門試験
- ハイパスレートのSPS-C01認定資格試験 - 合格スムーズSPS-C01ソフトウエア | 認定するSPS-C01学習教材 🍅 ウェブサイト【 www.goshiken.com 】を開き、{ SPS-C01 }を検索して無料でダウンロードしてくださいSPS-C01コンポーネント
- 優秀なSPS-C01認定資格試験 - 認定試験のリーダー - 実用的なSPS-C01ソフトウエア 🏞 《 www.mogiexam.com 》を開き、☀ SPS-C01 ️☀️を入力して、無料でダウンロードしてくださいSPS-C01日本語解説集
- ハイパスレートのSPS-C01認定資格試験一回合格-信頼的なSPS-C01ソフトウエア 🥤 ( www.goshiken.com )サイトで➡ SPS-C01 ️⬅️の最新問題が使えるSPS-C01資格関連題
- SPS-C01模擬試験 🧴 SPS-C01入門知識 🍲 SPS-C01専門試験 🍃 ✔ www.passtest.jp ️✔️は、➥ SPS-C01 🡄を無料でダウンロードするのに最適なサイトですSPS-C01トレーリング学習
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes