TestPassKing is a very good website to provide a convenient service for the Microsoft certification AI-200 exam. TestPassKing's products can help people whose IT knowledge is not comprehensive pass the difficulty Microsoft certification AI-200 exam. If you add the Microsoft Certification AI-200 Exam product of TestPassKing to your cart, you will save a lot of time and effort. TestPassKing's product is developed by TestPassKing's experts' study of Microsoft certification AI-200 exam, and it is a high quality product.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Topic 2: Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Topic 3: Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Topic 4: Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
>> Microsoft AI-200 Exam Training <<
Will you feel that the product you have brought is not suitable for you? One trait of our AI-200 exam prepare is that you can freely download a demo to have a try. Because there are excellent free trial services provided by our AI-200 exam guides, our products will provide three demos that specially designed to help you pick the one you are satisfied. On the one hand, by the free trial services you can get close contact with our products, learn about the detailed information of our AI-200 Study Materials, and know how to choose the right version of our AI-200 exam questions.
NEW QUESTION # 32
You need to address the known issue resulting from vector similarity queries.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
Detailed Explanation: The objective is to reduce RU consumption from vector similarity queries. Microsoft guidance identifies vector numeric precision and vector-index selection as major cost and performance levers.
Using a lower supported vector precision can reduce storage and processing cost, while quantizedFlat and DiskANN are designed to reduce latency and RU consumption compared with flat search for appropriate data sizes. Strong consistency would increase resource cost rather than solve vector-search efficiency. A regular composite index is not a substitute for the vector index. Option B should be read as reducing vector numeric precision, not changing a generic "indexing precision" setting.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector search in Azure Cosmos DB | Optimize Cosmos DB vector search performance
Topic 1 : Proseware Inc. Case Study 7
Topic 2 : Fabrikam Inc 8
Topic 3 : Standalone Questions Set 127
TOTAL 142
Topic 1, Proseware Inc. Case Study
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers. The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring:
* Telemetry generated by Azure resources is sent to Azure Monitor.
* A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
* Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version- controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known issues
RU consumption spikes during vector similarity queries.
NEW QUESTION # 33
You are developing a Retrieval-Augmented Generation (RAG) solution for a company. AI responses and embedding vectors are cached in Redis. The solution must meet the following requirements.
* AI responses must expire exactly 24 hours after they are cached
* Cached embeddings must always reflect the current source data.
You need to configure Redis to meet the requirements.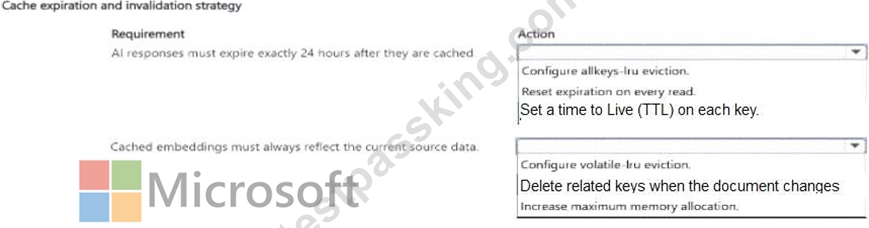
Answer:
Explanation:
Explanation:
I response expiry: set a 24-hour TTL on each key. Embedding freshness: delete related cache keys when the source document changes.
Detailed Explanation: A fixed TTL encodes the requirement that an AI response must expire after a defined period rather than survive indefinitely or have its lifetime extended on every read. Embedding freshness is a separate consistency requirement: when the authoritative document changes, any cached representation derived from the old document must be invalidated immediately. Memory eviction policies are capacity- management mechanisms and cannot guarantee a precise 24-hour lifetime or source-data consistency.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Azure Managed Redis documentation
NEW QUESTION # 34
You store embeddings in Redis by using keys formatted as doc:(id). Some embeddings are accessed frequently. Others are rarely used.
You need to implement a caching strategy that keeps only frequently accessed embeddings in memory.
What should you use?
Answer: B
Explanation:
To implement this strategy, you should use allkeys-lru combined with the EXPIRE command as a secondary fallback.
Primary Mechanism: Configure your Redis maxmemory-policy to allkeys-lru.
Secondary Mechanism: Apply the EXPIRE command to your keys as a safety net.
Why allkeys-lru is the Best Choice
Memory Management: It automatically evicts the Least Recently Used (LRU) keys across your entire dataset when Redis hits its memory limit.
Frequent Access: It guarantees that frequently accessed embeddings stay in memory, regardless of when they were created.Prefix Independent: It scans all keys, making it perfect for your doc:(id) format Reference:
https://rahulchowdhury.in/blog/redis-caching-patterns-every-mern-dev
NEW QUESTION # 35
You need to secure an Azure OpenAI resource so that it is only reachable from your virtual network and not from the public internet. What should you configure?
Answer: A
Explanation:
Private Link/private endpoints assign the Azure OpenAI resource a private IP within your VNet and allow disabling public network access, ensuring traffic stays on the Microsoft backbone network and isn't reachable from the public internet.
NEW QUESTION # 36
You are developing an application that must extract structured field data (invoice number, total, vendor name) from scanned invoices in multiple layouts.
You need a solution that requires no custom model training.
What should you use?
Answer: A
Explanation:
Use the Azure AI Document Intelligence prebuilt invoice model . The prebuilt invoice model is specifically designed to analyze invoices and extract structured fields and line items without requiring an organization to train a custom model. Microsoft documents support for fields including InvoiceId , VendorName , InvoiceTotal , InvoiceDate, CustomerName, AmountDue, tax information, addresses, and invoice line items.
Because the model is pretrained to recognize common invoice structures, it can process invoices that use different layouts and formats while returning normalized structured output. This directly satisfies the requirement to extract invoice number, total, and vendor information from scanned documents while minimizing development and training effort.
The Azure AI Vision Read API performs OCR and can extract printed or handwritten text, but it does not provide invoice-specific semantic field extraction. Custom named entity recognition would require training and is designed for text entity extraction rather than document-layout understanding. A Document Intelligence custom neural model can handle organization-specific forms and layouts, but it requires custom model training, directly violating the requirement.
Therefore, the prebuilt invoice model provides the required combination of OCR, document understanding, structured extraction, and zero custom training.
Study Guide references: Azure AI Document Intelligence # prebuilt invoice model; structured field extraction; OCR; invoice fields and line items.
NEW QUESTION # 37
......
TestPassKing offers the AI-200 exam questions in a convenient PDF format, allowing you to easily download them on your PC, laptop, Mac, tablet, or smartphone. With this accessibility, you can access the Microsoft AI-200 PDF questions anytime and from anywhere. Having all the information about the Developing AI Cloud Solutions on Azure (AI-200) Exam at your fingertips enhances your studying experience, making it easier and more effective, whether you're at home or on the go.
Questions AI-200 Exam: https://www.testpassking.com/AI-200-exam-testking-pass.html